What's more, part of that TestkingPDF AIF-C01 dumps now are free: https://drive.google.com/open?id=1yLgrM0hdVgxEEAOGcClGRncvRvPsi5Fa
Our company employs experts in many fields to write AIF-C01 study guide, so you can rest assured of the quality of our AIF-C01 learning materials. What’s more, preparing for the exam under the guidance of our AIF-C01 Exam Questions, you will give you more opportunities to be promoted and raise your salary in the near future. So when you are ready to take the exam, you can rely on our AIF-C01learning materials!
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
| Topic 4 |
|
| Topic 5 |
|
You should keep in mind to pass the AIF-C01 certification exam is not an easy task. It is a challenging job. If you want to pass the AIF-C01 exam then you have to put in some extra effort, time, and investment then you will be confident to pass the AWS Certified AI Practitioner (AIF-C01) exam. With the complete and comprehensive AIF-C01 exam dumps preparation you can pass the AWS Certified AI Practitioner (AIF-C01) exam with good scores. The TestkingPDF AIF-C01 Questions can be helpful in this regard. You must try this.
NEW QUESTION # 53
A company is building a large language model (LLM) question answering chatbot. The company wants to decrease the number of actions call center employees need to take to respond to customer questions.
Which business objective should the company use to evaluate the effect of the LLM chatbot?
Answer: A
Explanation:
The business objective to evaluate the effect of an LLM chatbot aimed at reducing the actions required by call center employees should be average call duration.
* Average Call Duration:
* This metric measures the time taken to handle a customer call or query. A successful LLM chatbot should reduce the call duration by efficiently providing answers, minimizing the need for human intervention.
* By decreasing the average call duration, the company can improve call center efficiency, reduce costs, and enhance the user experience.
* Why Option B is Correct:
* Direct Impact: The objective aligns directly with the goal of reducing the number of actions call center employees must take.
* Operational Efficiency: Reducing call duration is a clear indicator of the chatbot's effectiveness in assisting customers without human help.
* Why Other Options are Incorrect:
* A. Website engagement rate: Is unrelated to call center operations.
* C. Corporate social responsibility: Does not relate to call center efficiency.
* D. Regulatory compliance: Is important but does not measure the effectiveness of a chatbot in reducing employee actions.
NEW QUESTION # 54
A company needs to build its own large language model (LLM) based on only the company's private dat a. The company is concerned about the environmental effect of the training process.
Which Amazon EC2 instance type has the LEAST environmental effect when training LLMs?
Answer: C
Explanation:
The Amazon EC2 Trn series (Trainium) instances are designed for high-performance, cost-effective machine learning training while being energy-efficient. AWS Trainium-powered instances are optimized for deep learning models and have been developed to minimize environmental impact by maximizing energy efficiency.
Option D (Correct): "Amazon EC2 Trn series": This is the correct answer because the Trn series is purpose-built for training deep learning models with lower energy consumption, which aligns with the company's concern about environmental effects.
Option A: "Amazon EC2 C series" is incorrect because it is intended for compute-intensive tasks but not specifically optimized for ML training with environmental considerations.
Option B: "Amazon EC2 G series" (Graphics Processing Unit instances) is optimized for graphics-intensive applications but does not focus on minimizing environmental impact for training.
Option C: "Amazon EC2 P series" is designed for ML training but does not offer the same level of energy efficiency as the Trn series.
AWS AI Practitioner Reference:
AWS Trainium Overview: AWS promotes Trainium instances as their most energy-efficient and cost-effective solution for ML model training.
NEW QUESTION # 55
A company wants to build an ML application.
Select and order the correct steps from the following list to develop a well-architected ML workload. Each step should be selected one time. (Select and order FOUR.)
* Deploy model
* Develop model
* Monitor model
* Define business goal and frame ML problem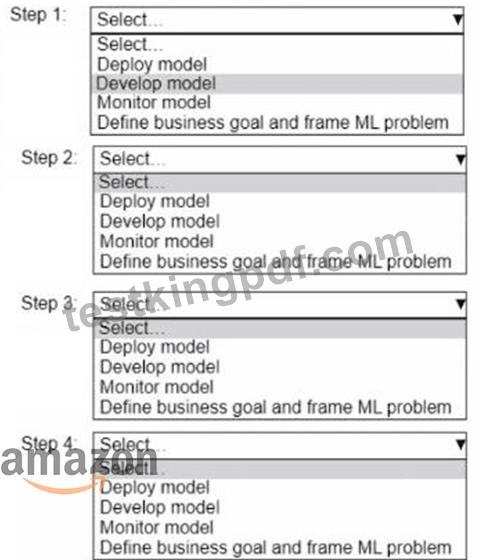
Answer:
Explanation:
Reference:
AWS AI Practitioner Learning Path: Module on Machine Learning Lifecycle Amazon SageMaker Developer Guide: Machine Learning Workflow (https://docs.aws.amazon.com/sagemaker/latest/dg/how-it-works-mlconcepts.html) AWS Well-Architected Framework: Machine Learning Lens (https://docs.aws.amazon.com/wellarchitected/latest/machine-learning-lens/)
NEW QUESTION # 56
A company deployed a Retrieval Augmented Generation (RAG) application on Amazon Bedrock that gathers financial news to distribute in daily newsletters. Users have recently reported politically influenced ideas in the newsletters.
Which Amazon Bedrock Guardrails feature can identify and filter this content?
Answer: D
Explanation:
Denied topics are the appropriate Amazon Bedrock Guardrails feature because the company wants to identify and prevent responses relating to a specific subject area-in this case, unwanted political content.
AWS explains: "You can specify a set of denied topics in a guardrail that are undesirable" for a generative AI application. When a prompt or response is identified as belonging to a configured denied topic, the guardrail can block that content and return the configured blocked-response message.
The company could therefore define a denied topic describing political advocacy, political commentary, politically influenced recommendations, or whatever political-content boundary its newsletter policy prohibits. Amazon Bedrock Guardrails evaluates content contextually against the topic definition rather than relying solely on individual keywords.
This distinction is important because political ideas can be expressed without using predictable keywords. A contextual denied-topic policy is consequently better suited than maintaining a static list of political terms.
Word filters, option A, block configured words or phrases through direct matching. They are useful for profanity, competitor names, or other exact terms but are less suitable for broad conceptual topics.
Sensitive information filters, option C, detect personally identifiable information and configured sensitive patterns. They address privacy rather than political subject matter.
Content filters, option D, detect predefined harmful-content categories. Current Amazon Bedrock Guardrails categories include Hate, Insults, Sexual, Violence, Misconduct, and Prompt Attack. Politics is not one of those predefined content-filter categories.
Denied topics are specifically intended for application-specific subjects that the organization chooses to prohibit. AWS gives examples such as a banking assistant being configured to avoid investment-advice or cryptocurrency discussions.
Consequently, the RAG architecture does not change the appropriate control. Guardrails can evaluate generated output after retrieval and generation, and the company can define politics-related content as an undesirable subject.
Therefore, the correct answer is B. Denied topics.
NEW QUESTION # 57
A company needs a scalable method to compare two foundation models (FMs) for chat summarization based on correctness and completeness.
Which solution will meet these requirements?
Answer: A
Explanation:
The verified answer is C. Use the LLM-as-a-judge approach with a rubric across prompts to compare model outputs. The question asks for a scalable way to compare two foundation models for chat summarization based on correctness and completeness. AWS documentation for Amazon Bedrock model evaluation states that an evaluation job using a judge model uses an LLM to score another model's responses and provide an explanation of how it scored each prompt and response pair. This is specifically designed to compare model outputs across prompt datasets at scale, without requiring every output to be manually scored by humans.
AWS Bedrock documentation also lists built-in metrics for model evaluation jobs that use an LLM as a judge. The valid built-in metrics include Correctness and Completeness, which directly match the evaluation criteria in the question. Therefore, using LLM-as-a-judge with a rubric across prompts is the best fit because it evaluates the actual summaries produced by each model against the desired quality dimensions.
Option A is partially valid as an evaluation method, but it is not the most scalable approach. Human reviewers can provide high-quality judgments, but manual review becomes expensive and slow when comparing many prompts, outputs, and models. Option B is incorrect because latency and throughput measure operational performance, not whether a summary is correct or complete. A fast model can still produce incomplete or inaccurate summaries. Option D is incorrect because external benchmark rankings are generic. They do not prove that a model performs best on the company's specific chat summarization workload.
The decisive terms are "scalable," "correctness," and "completeness." Amazon Bedrock LLM-as-a-judge evaluation directly supports those dimensions, so option C is correct.
NEW QUESTION # 58
......
Amazon AIF-C01 valid test cram will help you to get your AIF-C01 certification. It will be a breeze to get your AIF-C01 certification with the help of the TestkingPDF AIF-C01 pdf vce. We will help whenever you need: 24*7 dedicated email and chat support are available. Besides, we ensure you a flawless shopping experience by Paypal. You can get passed by our latest & updated AIF-C01 Preparation material.
AIF-C01 Reliable Test Labs: https://www.testkingpdf.com/AIF-C01-testking-pdf-torrent.html
What's more, part of that TestkingPDF AIF-C01 dumps now are free: https://drive.google.com/open?id=1yLgrM0hdVgxEEAOGcClGRncvRvPsi5Fa