Itcertkr의 Microsoft AI-300덤프는 Microsoft AI-300시험문제변경에 따라 주기적으로 업데이트를 진행하여 덤프가 항상 가장 최신버전이도록 업데이트를 진행하고 있습니다.구매한 Microsoft AI-300덤프가 업데이트되면 저희측에서 자동으로 구매시 사용한 메일주소에 업데이트된 최신버전을 발송해드리는데 해당 덤프의 구매시간이 1년미만인 분들은 업데이트서비스를 받을수 있습니다.
| Section | Weight | Objectives |
|---|---|---|
| Design and implement a GenAIOps infrastructure | 20–25% | - Implement infrastructure for generative AI workloads
|
| Implement machine learning model lifecycle and operations | 25–30% | - Register, version, and package models
|
| Design and implement an MLOps infrastructure | 15–20% | - Implement infrastructure as code for Machine Learning
|
| Implement generative AI quality assurance and observability | 10–15% | - Evaluate and test generative AI applications
|
| Optimize generative AI systems and model performance | 15–20% | - Optimize model selection and configuration
|
많은 사이트에서Microsoft 인증AI-300 인증시험대비자료를 제공하고 있습니다. 그중에서 Itcertkr를 선택한 분들은Microsoft 인증AI-300시험통과의 지름길에 오른것과 같습니다. Itcertkr는 시험에서 불합격성적표를 받으시면 덤프비용을 환불하는 서비스를 제공해드려 아무런 걱정없이 시험에 도전하도록 힘이 되어드립니다. Itcertkr덤프를 사용하여 시험에서 통과하신 분이 전해주신 희소식이 Itcertkr 덤프품질을 증명해드립니다.
질문 # 106
A data science team trains a classification model that predicts loan approval outcomes.
Before registering the model, the team must ensure the following:
- Predictions must not disproportionately impact protected groups.
- Prediction errors can be evaluated across different data segments.
You need to assess whether the model meets Responsible AI expectations.
Which two approaches should you use? Each correct answer presents part of the solution.
Choose two.
NOTE: Each correct selection is worth one point.
정답:B,C
설명:
[D]
To evaluate a trained loan classification model for Responsible AI expectations--ensuring no disproportionate impact on protected groups, evaluating error across segments, and verifying prediction transparency--you can employ SHAP (SHapley Additive exPlanations) values to assess feature importance.
This approach allows you to identify which variables (e.g., credit history, debt levels) drive the model's predictions, fostering trust and fairness.
Feature Importance for Transparency: Use SHAP (model-agnostic) or LIME (local approximations) to explain why the model approved or denied a loan. These techniques identify how each feature contributes to individual predictions.
[E]
To ensure a trained loan approval classification model meets responsible AI expectations-- specifically, that it does not disproportionately impact protected groups and that errors can be evaluated across segments--you should analyze error rates across defined demographic cohorts using Fairness-Aware Machine Learning metrics.
Reference:
https://urfpublishers.com/journal/artificial-intelligence/article/view/explainable-aiml-testing- ensuring-transparency-accountability-and-compliance
https://timvero.com/blog/ethics-in-automated-lending-can-ai-make-fair-credit-decisions
질문 # 107
A team manages prompts used by a generative AI application built on Microsoft Foundry. Prompt updates are frequent, and prior changes have caused unexpected behavior in production.
The team requires that new prompt versions can be tested and reviewed without affecting production behavior.
You need to implement a source control practice that allows safe prompt experimentation.
What should you do?
정답:B
설명:
Creating a feature Git branch for each prompt change is an excellent and highly recommended action.
Prompts are code. Managing them through a standard software development lifecycle prevents production failures and allows for safe experimentation.
Isolation: Changes stay completely separate from the working production version.
Collaboration: Teams can review prompt tweaks together via Pull Requests (PRs).
Traceability: You can easily see who changed a prompt, when, and why.
Rollbacks: If a prompt performs poorly, you can instantly revert to a prior Git commit.
Reference:
https://mirascope.com/blog/prompt-management-system
질문 # 108
You are monitoring a fine-tuned large language model deployed in Microsoft Foundry.
You evaluate the model before and after fine-tuning by using the same evaluation dataset.
You review the following evaluation results: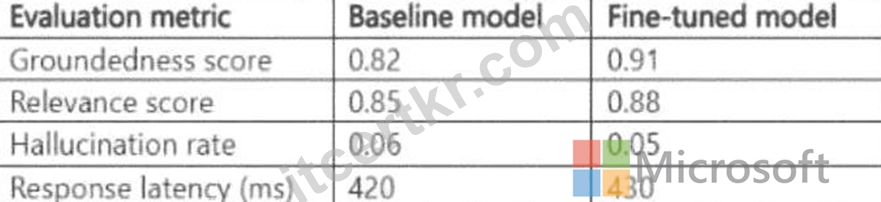
You need to determine whether the fine-tuned model shows improved performance without introducing regression.
For each of the following statements, select Yes if the statement is true. Otherwise, select No. NOTE: Each correct selection is worth one point.
정답:
설명:
Explanation:
When evaluating a fine-tuned model against the base model using the same evaluation dataset, the interpretation of each metric requires careful analysis. A statement that the fine-tuned model improves on the target task is True if and only if the target metric such as task-specific accuracy, F1 score, or ROUGE score shows a statistically meaningful improvement. A statement about regression on a complementary metric is True if the fine-tuned model ' s score on that metric is meaningfully lower than the base model ' s. In Microsoft Foundry ' s evaluation framework, both pre-fine-tuning and post-fine-tuning results are stored against the same experiment, enabling direct side-by-side comparison. The core principle is that improvement on the primary task is not sufficient if fine-tuning causes degradation on safety or coherence - this is called catastrophic forgetting, and the evaluation dataset is designed to detect it.
Microsoft Learn Reference Topic: Evaluate fine-tuned models in Microsoft Foundry - Compare base and fine- tuned model metrics
질문 # 109
You manage an Azure Machine Learning workspace.
You must define the execution environments for your jobs and encapsulate the dependencies for your code.
You need to configure the environment from a Docker build context.
How should you complete the rode segment? To answer, select the appropriate option in the answer area.
NOTE: Each correct selection is worth one point.
정답:
설명:
Explanation:
질문 # 110
A team manages an Azure Machine Learning workspace where they deploy models to online endpoints.
The team needs to introduce a new version of a model to production without disrupting existing users.
The team must validate the new version before full rollout.
You need to reduce risk during deployment.
What should you do?
정답:C
설명:
According to Microsoft ' s Azure Machine Learning documentation on managed online endpoints, a single endpoint can host multiple named deployments simultaneously, and you can control what percentage of incoming traffic each deployment receives. This traffic-splitting capability is the foundation of blue/green and canary deployment strategies. When you route 10% of traffic to a new deployment and 90% to the existing one, you can monitor error rates, latency, and output quality of the new version under real production load without risking the majority of users. Microsoft explicitly recommends this pattern for safe rollouts. Option A (batch endpoint) is inappropriate for real-time serving. Option C (replacing the endpoint) is high-risk with no validation window. Option D (routing all traffic to the new deployment) provides zero protection if the new version has issues.
Microsoft Learn Reference Topic: Safe rollout of machine learning models - Traffic splitting on managed online endpoints
질문 # 111
......
Itcertkr는 다른 회사들이 이루지 못한 Itcertkr만의 매우 특별한 이점을 가지고 있습니다.Itcertkr의Microsoft AI-300덤프는 전문적인 엔지니어들의Microsoft AI-300시험을 분석이후에 선택이 된 문제들이고 적지만 매우 가치 있는 질문과 답변들로 되어있는 학습가이드입니다.고객들은 단지 Itcertkr에서 제공해드리는Microsoft AI-300덤프의 질문과 답변들을 이해하고 마스터하면 첫 시험에서 고득점으로 합격을 할 것입니다.
AI-300시험문제모음: https://www.itcertkr.com/AI-300_exam.html