Boost Your Confidence with Online Snowflake DEA-C01 Practice Test Engine

P.S. Free & New DEA-C01 dumps are available on Google Drive shared by Prep4SureReview: https://drive.google.com/open?id=1hoCggUQ6pu1Bjmwziz8Xkro2voGsx5SL
For the candidates of the exam, you pay much attention to the pass rate. If you can’t pass the exam, all efforts you have done will be invalid. The pass rate of us is more than 98.95%, if you choose us, we will assure you that you can pass the exam, and all your efforts will be rewarded. Our service stuff will reply all your confusions about the DEA-C01 Exam Braindumps, and they will give you the professional suggestions and advice.
Snowflake DEA-C01 Exam Overview:
| Certification Vendor: | Snowflake |
|---|
| Exam Name: | SnowPro Advanced: Data Engineer Certification Exam |
|---|
| Exam Number: | DEA-C01 |
|---|
| Exam Format: | Multiple Choice, Multiple Select |
|---|
| Certificate Validity Period: | 2 years (recertification required) |
|---|
| Available Languages: | English |
|---|
| Exam Duration: | 90 minutes |
|---|
| Real Exam Qty: | approximately 50 questions |
|---|
| Related Certifications: | SnowPro Core Certification (Recommended Prerequisite) |
|---|
| Passing Score: | ~70% (exact passing score not publicly disclosed by Snowflake) |
|---|
| Exam Price: | $375 USD |
|---|
| Sample Questions: | Snowflake DEA-C01 Sample Questions |
|---|
| Exam Way: | Online proctored exam (via Pearson VUE) or in-person testing center |
|---|
| Pre Condition: | SnowPro Core Certification is strongly recommended before attempting this advanced-level exam. Practical experience with Snowflake data engineering projects is essential. |
|---|
| Official Syllabus URL: | https://www.snowflake.com/certification/ |
|---|
>> DEA-C01 Pdf Pass Leader <<
Reliable DEA-C01 Test Testking, DEA-C01 Reliable Mock Test
Society will never welcome lazy people, and luck will never come to those who do not. We must continue to pursue own life value, such as get the test Snowflake certification, not only to meet what we have now, but also to constantly challenge and try something new and meaningful. For example, our DEA-C01 prepare questions are the learning product that best meets the needs of all users. There are three version of our DEA-C01 training prep: PDF, Soft and APP versions. And you can free download the demo of our DEA-C01 learning guide before your payment. Just rush to buy our DEA-C01 exam braindump!
| Topic | Details |
|---|
| Topic 1 | - Data Movement: Snowflake Data Engineers and Software Engineers are assessed on their proficiency to load, ingest, and troubleshoot data in Snowflake. It evaluates skills in building continuous data pipelines, configuring connectors, and designing data sharing solutions.
|
| Topic 2 | - Security: The Security topic of the DEA-C01 test covers the principles of Snowflake security, including the management of system roles and data governance. It measures the ability to secure data and ensure compliance with policies, crucial for maintaining secure data environments for Snowflake Data Engineers and Software Engineers.
|
| Topic 3 | - Storage and Data Protection: The topic tests the implementation of data recovery features and the understanding of Snowflake's Time Travel and micro-partitions. Engineers are evaluated on their ability to create new environments through cloning and ensure data protection, highlighting essential skills for maintaining Snowflake data integrity and accessibility.
|
| Topic 4 | - Data Transformation: The SnowPro Advanced: Data Engineer exam evaluates skills in using User-Defined Functions (UDFs), external functions, and stored procedures. It assesses the ability to handle semi-structured data and utilize Snowpark for transformations. This section ensures Snowflake engineers can effectively transform data within Snowflake environments, critical for data manipulation tasks.
|
| Topic 5 | - Performance Optimization: This topic assesses the ability to optimize and troubleshoot underperforming queries in Snowflake. Candidates must demonstrate knowledge in configuring optimal solutions, utilizing caching, and monitoring data pipelines. It focuses on ensuring engineers can enhance performance based on specific scenarios, crucial for Snowflake Data Engineers and Software Engineers.
|
Snowflake SnowPro Advanced: Data Engineer Certification Exam Sample Questions (Q359-Q364):
NEW QUESTION # 359
A company stores raw clickstream data in an Amazon S3 bucket. The company needs a solution to process the data every day by using complex PySpark transformations that rely on custom internal libraries. After the data is transformed, the company must store the data in Amazon Redshift for analytics. The solution must be highly scalable to handle large data workloads. Which solution will meet these requirements with the LEAST operational overhead?
- A. Use Amazon EMR to run PySpark jobs. Use bootstrap actions to install the custom libraries
- B. Use AWS Glue Studio to build and schedule PySpark jobs. Configure an AWS Glue data connection that includes the custom libraries.
- C. Use Amazon SageMaker Processing jobs to run PySpark code that uses native SageMaker libraries.
- D. Use Amazon EC2 Auto Scaling groups with a custom AMI that contains the custom libraries to run a PySpark application.
Answer: B
Explanation:
AWS Glue is a fully managed, highly scalable serverless service for running PySpark ETL jobs, and it supports adding custom Python libraries to Glue jobs from Amazon S3 by using job parameters such as --additional-python-modules and --extra-py-files. AWS Glue can also write to Amazon Redshift, making it the best fit for daily large-scale PySpark transformations with the least operational overhead compared with managing EC2 instances or EMR clusters.
Reference:
https://docs.aws.amazon.com/glue/latest/dg/aws-glue-programming-python-libraries.html
https://docs.aws.amazon.com/glue/latest/dg/aws-glue-programming-etl-connect-redshift- home.html
NEW QUESTION # 360
A data engineer maintains custom Python scripts that perform a data formatting process that many AWS Lambda functions use. When the data engineer needs to modify the Python scripts, the data engineer must manually update all the Lambda functions.
The data engineer requires a less manual way to update the Lambda functions.
Which solution will meet this requirement?
- A. Package the custom Python scripts into Lambda layers. Apply the Lambda layers to the Lambda functions.
- B. Store the custom Python scripts in a shared Amazon S3 bucket. Store a pointer to the customer scripts in environment variables.
- C. Store the custom Python scripts in a shared Amazon S3 bucket. Store a pointer to the custom scripts in the execution context object.
- D. Assign the same alias to each Lambda function. Call each Lambda function by specifying the function's alias.
Answer: A
Explanation:
Lambda layers allow you to package external libraries, custom scripts, or dependencies (like Python scripts) separately from the Lambda function code. By using Lambda layers, you can update the custom Python scripts in one central place (the layer) without manually updating each Lambda function. When the layer is updated, all Lambda functions that use the layer automatically get the latest version of the scripts.
NEW QUESTION # 361
A company uses an Amazon Redshift cluster to manage data, including vendor sales data. The company wants to store a copy of the vendor data in an Amazon S3 bucket.
A data engineer sets up an AWS Glue job to upload the data to the S3 bucket data on a schedule. The data engineer set up a network connection to allow private traffic between Amazon Redshift and Amazon S3.
What is the next step required to meet this requirement?
- A. Create an IAM role that has permission to write to the S3 bucket. Associate the IAM role with the Amazon Redshift cluster.
- B. Enable the Amazon Redshift data sharing feature. Set the S3 bucket as a target bucket for data sharing.
- C. Store login credentials for Amazon Redshift in AWS Secrets Manager. Add a reference to the secret to the Glue job configuration.
- D. Add the S3 bucket to an AWS Glue Data Catalog. Configure Amazon Redshift Spectrum to access the Data Catalog.
Answer: A
Explanation:
Amazon Redshift needs an IAM role that grants permission to write to the target Amazon S3 bucket. After the private network path is in place, associating that role with the Redshift cluster enables the export operation to store the vendor data in S3.
NEW QUESTION # 362
The following chart represents the performance of a virtual warehouse over time:
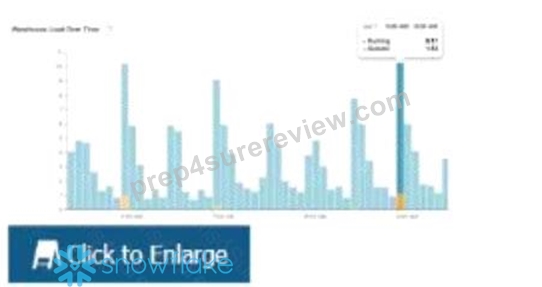
A DataEngineer notices that the warehouse is queueing queries The warehouse is size X-Smallthe minimum and maximum cluster counts are set to 1 the scaling policy is set to i and auto-suspend is set to 10 minutes.
How canthe performance be improved?
- A. Increase the size of the warehouse
- B. Change the scaling policy to economy
- C. Change the cluster settings
- D. Change auto-suspend to a longer time frame
Answer: A
Explanation:
Explanation
The performance can be improved by increasing the size of the warehouse. The chart shows that the warehouse is queueing queries, which means that there are more queries than the warehouse can handle at its current size. Increasing the size of the warehouse will increase its processing power and concurrency limit, which could reduce the queueing time and improve the performance. The other options are not likely to improve the performance significantly. Option A, changing the cluster settings, will not help unless the minimum and maximum cluster countsare increased to allow for multi-cluster scaling. Option C, changing the scaling policy to economy, will not help because it will reduce the responsiveness of the warehouse to scale up or down based on demand. Option D, changing auto-suspend to a longer time frame, will not help because it will only affect how long the warehouse stays idle before suspending itself.
NEW QUESTION # 363
In efforts to recover the dropped child tables within schema named SCV_SCHEMA by Data Engi-neer, She found that DATA_RETENTION_TIME_IN_DAYS parameter set with value 45 days at Schema level &the data retention period for child tables explicitly set at 85 days. What will happen when she will try to run undrop table command on Child tables to recover them on the 50th day as-suming SCV_SCHEMA is already dropped on 45th day?
- A. To honor the data retention period for child tables, She will ab able to recover the child tables on 50th day as DATA_RETENTION_TIME_IN_DAYS is explicitly set with higher retention value.
- B. When a schema is already dropped, the data retention period for child tables, if explicit-ly set to be different from the retention of the schema, is not honoured. So UNDROP command will fail to run on
50th day for Child tables recovery. - C. Child tables can be recovered using Fail-Safe SQL commands.
- D. Data Engineer needs to first recover the Schema & then Child tables will automatically be recovered irrespective of Retention Inheritance.
Answer: B
Explanation:
Explanation
Dropped Containers and Object Retention Inheritance
Currently, when a database is dropped, the data retention period for child schemas or tables, if ex-plicitly set to be different from the retention of the database, is not honored. The child schemas or tables are retained for the same period of time as the database.
Similarly, when a schema is dropped, the data retention period for child tables, if explicitly set to be different from the retention of the schema, is not honored. The child tables are retained for the same period of time as the schema.
To honor the data retention period for these child objects (schemas or tables), drop them explicitly before you drop the database or schema.
NEW QUESTION # 364
......
Reliable DEA-C01 Test Testking: https://www.prep4surereview.com/DEA-C01-latest-braindumps.html
- Updated And Free Snowflake DEA-C01 PDF Dumps Are Hassle-Free Preparation With www.validtorrent.com 💻 Search for ⏩ DEA-C01 ⏪ and obtain a free download on ⏩ www.validtorrent.com ⏪ 🛌Free DEA-C01 Study Material
- Updated And Free Snowflake DEA-C01 PDF Dumps Are Hassle-Free Preparation With Pdfvce 🔯 Open website ⇛ www.pdfvce.com ⇚ and search for ➠ DEA-C01 🠰 for free download 🔯DEA-C01 Vce Files
- Desktop-Based Snowflake DEA-C01 Practice Exam Software 🏸 Search for ➽ DEA-C01 🢪 on ⇛ www.pass4test.com ⇚ immediately to obtain a free download ➰DEA-C01 Passing Score Feedback
- Accurate DEA-C01 Pdf Pass Leader - Leading Provider in Qualification Exams - Trusted Reliable DEA-C01 Test Testking 😺 Open ➡ www.pdfvce.com ️⬅️ enter ➤ DEA-C01 ⮘ and obtain a free download 🦧Detailed DEA-C01 Study Plan
- Reliable DEA-C01 Dumps Free 🥧 DEA-C01 Vce Files 🐛 Detailed DEA-C01 Study Plan 🍣 Open website ▶ www.examcollectionpass.com ◀ and search for 【 DEA-C01 】 for free download ⛷Test DEA-C01 Question
- Dumps DEA-C01 PDF 💕 Updated DEA-C01 Dumps ✌ Test DEA-C01 Simulator Online ♻ Enter ▶ www.pdfvce.com ◀ and search for ➠ DEA-C01 🠰 to download for free ♥DEA-C01 VCE Exam Simulator
- Test DEA-C01 Question ♻ Valid DEA-C01 Exam Pdf 🌟 Test DEA-C01 Simulator Online 🚟 Search for ▶ DEA-C01 ◀ and easily obtain a free download on ( www.pdfdumps.com ) 🤢Free DEA-C01 Study Material
- DEA-C01 Dumps 🤐 DEA-C01 VCE Exam Simulator 🗓 DEA-C01 Passing Score Feedback 📍 Enter 「 www.pdfvce.com 」 and search for [ DEA-C01 ] to download for free 🍼Test DEA-C01 Simulator Online
- DEA-C01 New Test Camp 🏫 Exam DEA-C01 Guide Materials 🚒 Reliable DEA-C01 Dumps Free ☀ Simply search for { DEA-C01 } for free download on ⏩ www.examdiscuss.com ⏪ 🤼Detailed DEA-C01 Study Plan
- Dumps DEA-C01 PDF 📙 DEA-C01 Valid Cram Materials 🍷 Reliable DEA-C01 Test Forum 👟 Open ⇛ www.pdfvce.com ⇚ enter ▷ DEA-C01 ◁ and obtain a free download 🧓Exam DEA-C01 Guide Materials
- DEA-C01 VCE Exam Simulator 🏉 Study DEA-C01 Material 🦚 Dumps DEA-C01 PDF 🔢 Open 《 www.pdfdumps.com 》 enter ➠ DEA-C01 🠰 and obtain a free download 🔵New DEA-C01 Test Fee
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes
BTW, DOWNLOAD part of Prep4SureReview DEA-C01 dumps from Cloud Storage: https://drive.google.com/open?id=1hoCggUQ6pu1Bjmwziz8Xkro2voGsx5SL