P.S. Free & New DP-800 dumps are available on Google Drive shared by DumpsKing: https://drive.google.com/open?id=1V05oQH0FzA8LJVyVClLzgot74ysPSdp5
DumpsKing provide you with 100% free up-dated DP-800 study material for 356 days after complete purchase. The DP-800 updated dumps reflects any changes related to the actual test. With our DP-800 torrent dumps, you can be confident to face any challenge in the actual test. Besides, we make your investment secure with the full refund policy. You do not need to run the risk of losing money in case of failure of DP-800 test. You can require for money back according to our policy.
| Certification Vendor: | Microsoft |
|---|---|
| Exam Name: | Developing AI-Enabled Database Solutions |
| Exam Number: | DP-800 |
| Exam Format: | Multiple select, Drag and drop, Multiple choice, Build list, Case studies |
| Related Certifications: | Microsoft Certified: SQL AI Developer Associate |
| Exam Price: | $165 USD |
| Available Languages: | Spanish, Korean, Italian, English, Japanese, German, Arabic (Saudi Arabia), Chinese (Simplified), Indonesian (Indonesia), French, Portuguese (Brazil), Chinese (Traditional) |
| Certificate Validity Period: | 1 year |
| Passing Score: | 700 |
| Real Exam Qty: | 40-60 |
| Exam Duration: | 100 minutes |
| Sample Questions: | Microsoft DP-800 Sample Questions |
| Exam Way: | Online proctored or in-person at a testing center |
| Pre Condition: | No specific prerequisites, but candidates should have experience with SQL and a basic understanding of Azure services. Familiarity with AI or machine learning concepts is recommended. |
| Official Syllabus URL: | https://learn.microsoft.com/en-us/credentials/certifications/exams/dp-800/ |
Our company has authoritative experts and experienced team in related industry. To give the customer the best service, all of our company's DP-800 learning materials are designed by experienced experts from various field, so our DP-800 Learning materials will help to better absorb the test sites. One of the great advantages of buying our product is that can help you master the core knowledge in the shortest time. At the same time, our DP-800 learning materials discard the most traditional rote memorization methods and impart the key points of the qualifying exam in a way that best suits the user's learning interests, this is the highest level of experience that our most authoritative think tank brings to our DP-800 Learning Materials users. Believe that there is such a powerful expert help, our users will be able to successfully pass the qualification test to obtain the qualification certificate.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
NEW QUESTION # 78
You have an Azure SQL database that contains a table named knowledgebase, knowledgebase stores human resources (HR) policy documents and contains columns named title, content, category, and embedding.
You have an application named App1. App1 queries two relational tables named employee_pnofiles and benefits_enrollnent that contain HR data. App1 hosts a chatbot that calls a large language model (LLM) directly.
Users report that the chatbot answers general HR questions correctly but provides outdated or incorrect answers when policies change. The chatbot also fails to answer questions that reference internal policy documents by title or category.
You need to recommend a Retrieval Augmented Generation (RAG) solution to resolve the chatbot issues.
What should you recommend? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.
Answer:
Explanation:
Explanation:
The correct recommendation is to retrieve grounding data from knowledge_base and, at inference time, generate query embeddings and run a vector similarity search .
The chatbot currently answers some general HR questions but fails when policies change and when users ask about internal policy documents by title or category . That is exactly the kind of problem RAG is meant to solve: ground the LLM in the organization's proprietary content instead of relying on the model's training data or unrelated transactional tables. Microsoft's RAG guidance states that RAG extends LLMs by grounding responses in your own content and that, for agentic retrieval, knowledge bases unify knowledge sources for retrieval.
So the grounding data should come from knowledge_base , because that table stores the HR policy documents and already includes fields like title, content, category, and embedding. Those are the fields directly tied to the missing and outdated policy answers. By contrast:
* employee_profiles and benefits_enrollment are operational HR tables, not the authoritative store for policy-document grounding.
* PDF exports of the policies would be inferior to querying the indexed/structured knowledge base already prepared for retrieval.
* The LLM training data is specifically the wrong source when the issue is outdated internal content.
For the retrieval step, Microsoft's guidance says to use embeddings for vector queries and notes that vector similarity search matches concepts, not exact terms . This is especially important because users ask about policy documents by title or category and also phrase questions in ways that might not exactly match document wording. Generating a query embedding and then running a vector similarity search is the appropriate retrieval step in a RAG pipeline.
NEW QUESTION # 79
You have an Azure SQL database that supports an AI-driven product search API.
You need to identify the top CPU-consuming queries from the last two hours by using Query Store data. The solution must aggregate CPU consumption across executions and return only the top 15 query hashes.
How should you complete the Transact-SQL code? To answer, drag the appropriate values to the correct targets. Each value may be used once, more than once, or not at all.
NOTE: Each correct selection is worth one point.
Answer:
Explanation:
Explanation:
Verified Answer : =
* CPU aggregation expression # rs.avg_cpu_time
* Runtime interval source # sys.query_store_runtime_stats_interval
* Last two hours filter # DATEADD(HOUR, -2, GETUTCDATE())
Comprehensive and Detailed Explanation with all Developing AI-Enabled Database Solutions documents : = The first correct selection is rs.avg_cpu_time . Query Store stores CPU statistics per aggregation interval, and Microsoft documents avg_cpu_time as the average CPU time per execution, in microseconds . To calculate total CPU consumption across all executions, multiply count_executions by avg_cpu_time , then divide by
1000.0 to convert microseconds to milliseconds:
SUM(count_executions * rs.avg_cpu_time / 1000.0)
This is the exact pattern Microsoft uses in its documented query for identifying the top 15 CPU-consuming queries by query hash .
The second selection is sys.query_store_runtime_stats_interval because sys.query_store_runtime_stats.
runtime_stats_interval_id is a foreign key to this view. The interval view provides start_time and end_time , allowing Query Store data to be limited to the required time window.
The third selection is DATEADD(HOUR, -2, GETUTCDATE()) . Microsoft's own Azure SQL performance- monitoring example for the last two hours uses exactly:
rsi.start_time > = DATEADD(HOUR, -2, GETUTCDATE())
and then ranks by total CPU descending to return the top 15 query hashes.
Final drag-and-drop selections:
* First target: rs.avg_cpu_time
* Second target: sys.query_store_runtime_stats_interval
* Third target: DATEADD(HOUR, -2, GETUTCDATE())
NEW QUESTION # 80
Case Study 1 - Contoso
Existing Environment
Azure Environment
Contoso has an Azure subscription in North Europe that contains the corporate infrastructure.
The current infrastructure contains a Microsoft SQL Server 2017 database. The database contains the following tables.
The FeedbackJsoncolumn has a full-text index and stores JSON documents in the following format.
The support staff at Contoso never has the UNMASKpermission.
Problem Statements
Contoso is deploying a new Azure SQL database that will become the authoritative data store for the following:
* AI workloads
* Vector search
* Modernized API access
* Retrieval Augmented Generation (RAG) pipelines
Sometimes the ingestion pipeline fails due to malformed JSON and duplicate payloads.
The engineers at Contoso report that the following dashboard query runs slowly.
You review the execution plan and discover that the plan shows a clustered index scan.
VehicleIncidentReportsoften contains details about the weather, traffic conditions, and location. Analysts report that it is difficult to find similar incidents based on these details.
Requirements
Planned Changes
Contoso wants to modernize Fleet Intelligence Platform to support AI-powered semantic search over incident reports.
Security Requirements
Contoso identifies the following security requirements:
* Restrict the support staff from viewing Personally Identifiable Information (PII) data, which is full email addresses and phone numbers.
* Enforce row-level filtering so that analysts see only incidents for the fleets to which they are assigned. The analysts can be assigned to multiple fleets.
Database Performance and Requirements
Contoso identifies the following telemetry requirements:
* Telemetry data must be stored in a partitioned table.
* Telemetry data must provide predictable performance for ingestion and retention operations.
* latitude, longitude, and accuracyJSON properties must be filtered by using an index seek.
Contoso identifies the following maintenance data requirements:
* Ensure that any changes to a row in the MaintenanceEventstable updates the corresponding value in the LastModifiedUtccolumn to the time of the change.
* Avoid recursive updates.
AI Search, Embeddings, and Vector Indexing
Contoso plans to implement semantic search over incident data to meet the following requirements:
* Embeddings must be stored in dedicated Azure SQL Database tables.
* Embeddings must be generated from rich natural language fields.
* Chunking must preserve semantic coherence.
* Hybrid search must combine the following:
- Vector similarity
- Keyword filtering or boosting
Development Requirements
The development team at Contoso will use Microsoft Visual Studio Code and GitHub Copilot and will retrieve live metadata from the databases.
Contoso identifies the following requirements for querying data in the FeedbackJsoncolumn of the CustomerFeedbacktable:
* Extract the customer feedback text from the JSON document.
* Filter rows where the JSON text contains a keyword.
* Calculate a fuzzy similarity score between the feedback text and a known issue description.
* Order the results by similarity score, with the highest score first.
You need to recommend a solution for the development team to retrieve the live metadata. The solution must meet the development requirements. What should you include in the recommendation?
Answer: B
Explanation:
Scenario: Development Requirements
The development team at Contoso will use Microsoft Visual Studio Code and GitHub Copilot and will retrieve live metadata from the databases.
To retrieve live metadata from Azure SQL databases and use it with GitHub Copilot in Visual Studio Code (VS Code), you must use the SQL Server (mssql) extension. This extension provides the native capability to extract a database schema as a .dacpac file directly within the editor.
1. Export the Schema as a .dacpac File
You can extract the schema of your live Azure SQL database using the SQL Server (mssql) extension.
2. Load the .dacpac into GitHub Copilot Context
Once the .dacpac file is saved in your VS Code workspace, you can provide it as context to GitHub Copilot Chat using #-mentions or Drag & Drop.
Reference:
https://learn.microsoft.com/en-us/sql/tools/sql-database-projects/concepts/data-tier- applications/extract-dacpac-from-database
NEW QUESTION # 81
You have a Microsoft SQL Server 2025 instance that has a managed identity enabled.
You have a database that contains a table named dbo.ManualChunks. dbo.ManualChunks contains product manuals.
A retrieval query already returns the top five matching chunks as nvarchar(max)text.
You need to call an Azure OpenAI REST endpoint for chat completions. The solution must provide the highest level of security.
You write the following Transact-SQL code.
What should you insert at line 02?


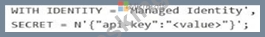

Answer: B
Explanation:
To use a Managed Identity with sys.sp_invoke_external_rest_endpoint in SQL Server, you need to configure your database-scoped credential with the following specific values:
Required Settings
WITH IDENTITY: Must be set to Managed Identity.
SECRET: Must be set to SECRET = N'{"resourceid":"<value>"}'.
Example Statement
CREATE DATABASE SCOPED CREDENTIAL [MyManagedIdentityCredential]
WITH IDENTITY = 'Managed Identity',
SECRET = N'{"resourceid": "https://azure.com"}'; -- Or your specific resource URI Quick Breakdown Identity: Managed Identity tells SQL Server to use the instance's assigned Azure identity rather than a static key or token.
Secret: The resourceid inside the JSON string specifies the Audience (resource) for which the Managed Identity is requesting an access token (e.g., Azure Storage, Key Vault, or a custom API).
Reference:
https://learn.microsoft.com/en-us/azure/azure-sql/managed-instance/authentication-azure-ad- user-assigned-managed-identity-create-managed-instance
NEW QUESTION # 82
You need to meet the development requirements for the FeedbackJson column.
How should you complete the Transact SQL query? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.
Answer:
Explanation:
Explanation:
JSON_VALUE(f.FeedbackJson, ' $.text ' ) AS FeedbackText
CONTAINS(FeedbackJson, @Keyword)
SimilarityScore
These three selections are the correct way to complete the query because they align exactly with the stated requirements for the FeedbackJson column.
First, to extract the customer feedback text from the JSON document, the correct expression is JSON_VALUE (f.FeedbackJson, ' $.text ' ) AS FeedbackText. Microsoft documents that JSON_VALUE is used to extract a scalar value from JSON, while JSON_QUERY is used for returning an object or array. Since $.text is the textual feedback string, JSON_VALUE is the correct function.
Second, to filter rows where the JSON text contains a keyword, the best choice is CONTAINS(FeedbackJson,
@Keyword). The scenario explicitly states that FeedbackJson already has a full-text index, and Microsoft documents that CONTAINS is the full-text predicate used in the WHERE clause to search full-text indexed character data. That makes it more appropriate than using EDIT_DISTANCE for keyword filtering.
Third, to order the results by similarity score, highest first, the correct item is SimilarityScore in the ORDER BY clause, which would be paired with DESC in the query. This matches the requirement to sort by the computed fuzzy similarity value. The DP-800 study guide specifically includes writing queries that use fuzzy string matching functions such as EDIT_DISTANCE, which supports the earlier computed SimilarityScore expression in the query.
NEW QUESTION # 83
......
Dump DP-800 File: https://www.dumpsking.com/DP-800-testking-dumps.html
BONUS!!! Download part of DumpsKing DP-800 dumps for free: https://drive.google.com/open?id=1V05oQH0FzA8LJVyVClLzgot74ysPSdp5