Valid Databricks-Certified-Data-Engineer-Associate exam materials offer you accurate preparation dumps

Laden Sie die neuesten ExamFragen Databricks-Certified-Data-Engineer-Associate PDF-Versionen von Prüfungsfragen kostenlos von Google Drive herunter: https://drive.google.com/open?id=1xgq6HFEX4oUsqq6xiEQ354miceUSS8Id
Über die Prüfungsfragen und Antworten zur Databricks Databricks-Certified-Data-Engineer-Associate Zertifizierung hat ExamFragen eine gute Qualität. ExamFragen wird die zuverlässigsten Informationsressourcen sein. Durch die Feedbacks und tiefintensive Analyse sind wir in einer Stelle. Wir müssen darüber entscheiden, welche Anbieter Ihnen die neuesten Übungen von guter Qualität zur Databricks Databricks-Certified-Data-Engineer-Associate Zertifizierungsprüfung bieten und aktualisieren zu können. Unsere Schulungsunterlagen zur Databricks Databricks-Certified-Data-Engineer-Associate Zertifizierungsprüfung werden ständig bearbeitet und modifiziert. Wir haben die umfassendesten Ausbildungserfahrugnen. Wenn Sie Zertifikate erhalten wollen, benutzen Sie doch unsere Schulungsunterlagen zur Databricks Databricks-Certified-Data-Engineer-Associate Zertifizierungsprüfung. Schicken ExamFragen doch schnell in Ihren Warenkorb. Unzählige Überraschungen warten schon auf Sie.
Databricks Databricks-Certified-Data-Engineer-Associate Exam Syllabus Topics:
| Section | Weight | Objectives |
|---|
| Lakehouse Platform Concepts | 10-15% | - Understand the Lakehouse architecture and its benefits
- Describe key Databricks Lakehouse platform components
- Explain data governance and security concepts
|
| Delta Lake Fundamentals | 20-25% | - Explain Delta Lake features and benefits
- Understand ACID transactions and time travel
- Write to and read from Delta tables
- Create and manage Delta tables
|
| Spark SQL and DataFrames | 15-20% | - Aggregate and group data
- Write and execute Spark SQL queries
- Join and union DataFrames
- Handle null values and data quality
|
| Python for Data Engineering | 10-15% | - Work with Spark APIs in Python
- Implement user-defined functions (UDFs)
- Use PySpark for data processing
|
| Data Pipeline Architecture | 15-20% | - Design data pipelines for batch and streaming
- Monitor and optimize pipeline performance
- Understand ELT vs ETL patterns
- Implement incremental data processing
|
| Apache Spark Data Processing Fundamentals | 20-25% | - Apply transformations and actions on DataFrames
- Create and use Spark DataFrames
- Work with structured data types (arrays, maps, structs)
- Use Spark SQL for data processing
|
>> Databricks-Certified-Data-Engineer-Associate Deutsch Prüfung <<
Databricks-Certified-Data-Engineer-Associate PDF & Databricks-Certified-Data-Engineer-Associate Deutsch Prüfungsfragen
ExamFragen kann Ihnen Ihren Stress zur Databricks Databricks-Certified-Data-Engineer-Associate Zertifizierungsprüfung im Internet überwinden. Die Lernmaterialien zur Databricks Databricks-Certified-Data-Engineer-Associate Zertifizierungsprüfung enthalten Kurse, Online-Prüfung, Lerntipps im Internet. Unser ExamFragen hat Simulationsprüfungen, das Ihnen helfen, die Databricks Databricks-Certified-Data-Engineer-Associate Prüfung ganz einfach ohne viel Zeit und Geld zu bestehen. Wenn Sie unsere Lernmaterialien haben und sich um die Prüfungsfragen kümmern, können Sie ganz leicht das Zertifikat bekommen.
Databricks Certified Data Engineer Associate Exam Databricks-Certified-Data-Engineer-Associate Prüfungsfragen mit Lösungen (Q29-Q34):
29. Frage
A data engineer has configured a Structured Streaming job to read from a table, manipulate the data, and then perform a streaming write into a new table.
The code block used by the data engineer is below:
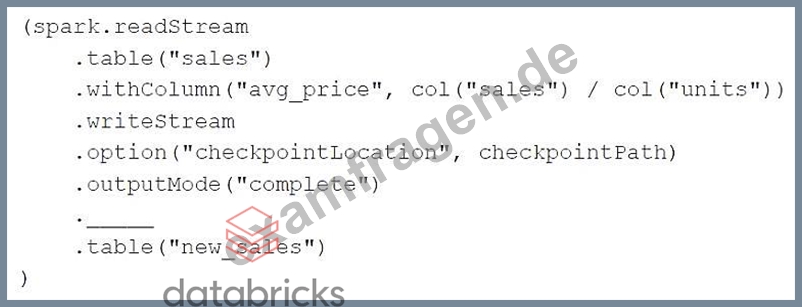
If the data engineer only wants the query to process all of the available data in as many batches as required, which of the following lines of code should the data engineer use to fill in the blank?
- A. trigger(continuous= " once " )
- B. trigger(parallelBatch=True)
- C. trigger(processingTime= " once " )
- D. processingTime(1)
- E. trigger(availableNow=True)
Antwort: E
Begründung:
https://spark.apache.org/docs/latest/api/python/reference/pyspark.ss/api/pyspark.sql.streaming.
DataStreamWriter.trigger.html
30. Frage
Which of the following must be specified when creating a new Delta Live Tables pipeline?
- A. A location of a target database for the written data
- B. A path to cloud storage location for the written data
- C. At least one notebook library to be executed
- D. The preferred DBU/hour cost
- E. A key-value pair configuration
Antwort: C
Begründung:
Option E is the correct answer because it is the only mandatory requirement when creating a new Delta Live Tables pipeline. A pipeline is a data processing workflow that contains materialized views and streaming tables declared in Python or SQL source files. Delta Live Tables infers the dependencies between these tables and ensures updates occur in the correct order. To create a pipeline, you need to specify at least one notebook library to be executed, which contains the Delta Live Tables syntax. You can also specify multiple libraries of different languages within your pipeline. The other options are optional or not applicable for creating a pipeline. Option A is not required, but you can optionally provide a key-value pair configuration to customize the pipeline settings, such as the storage location, the target schema, the notifications, and the pipeline mode. Option B is not applicable, as the DBU/hour cost is determined by the cluster configuration, not the pipeline creation. Option C is not required, but you can optionally specify a storage location for the output data from the pipeline. If you leave it empty, the system uses a default location. Option D is not required, but you can optionally specify a location of a target database for the written data, either in the Hive metastore or the Unity Catalog.
Tutorial: Run your first Delta Live Tables pipeline, What is Delta Live Tables?, Create a pipeline, Pipeline configuration.
31. Frage
A data engineer needs to apply custom logic to string column city in table stores for a specific use case. In order to apply this custom logic at scale, the data engineer wants to create a SQL user-defined function (UDF).
Which of the following code blocks creates this SQL UDF?
- A. sql
CREATE FUNCTION city_custom_logic(city STRING)
AS
IF city = 'London' THEN 'LND' ELSE city END; - B. sql
CREATE UDF city_custom_logic(city STRING)
RETURNS STRING
AS
SELECT CASE WHEN city = 'London' THEN 'LND' ELSE city END; - C. sql
DEFINE FUNCTION city_custom_logic(city STRING)
AS STRING
RETURN CASE WHEN city = 'London' THEN 'LND' ELSE city END; - D. sql
CREATE FUNCTION city_custom_logic(city STRING)
RETURNS STRING
RETURN CASE
WHEN city = 'London' THEN 'LND'
ELSE city
END;
Antwort: D
Begründung:
https://www.databricks.com/blog/2021/10/20/introducing-sql-user-defined-functions.html
32. Frage
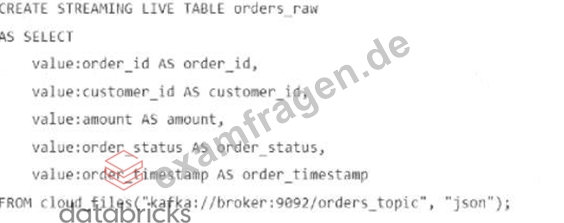
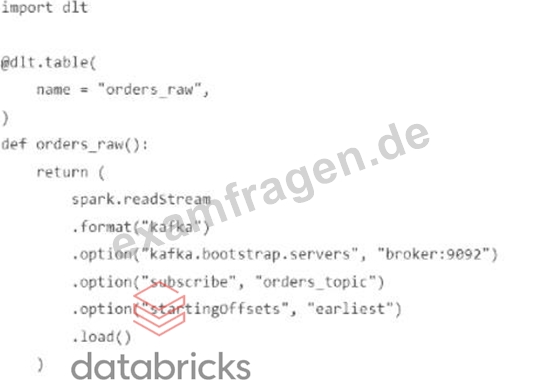
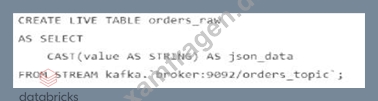
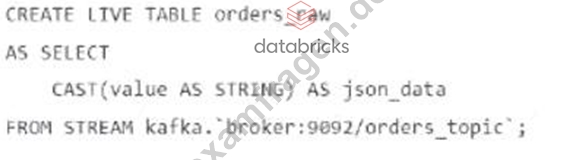
A data engineer streams customer orders into a Kafka topic (orders_topic) and is currently writing the ingestion script of a DLT pipeline. The data engineer needs to ingest the data from Kafka brokers to DLT using Databricks What is the correct code for ingesting the data?
Antwort: B
33. Frage
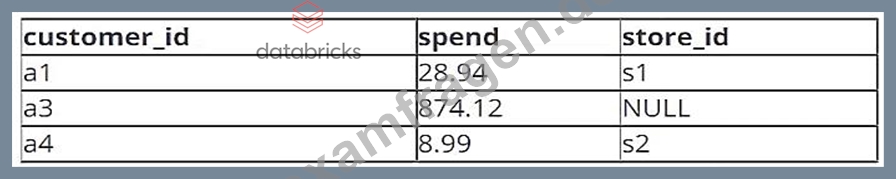
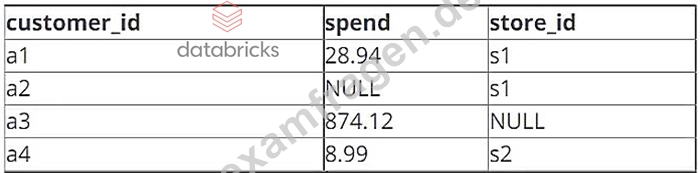
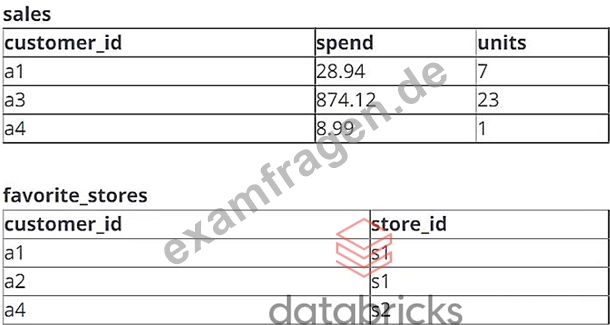
A data engineer is working with two tables. Each of these tables is displayed below in its entirety.
The data engineer runs the following query to join these tables together:
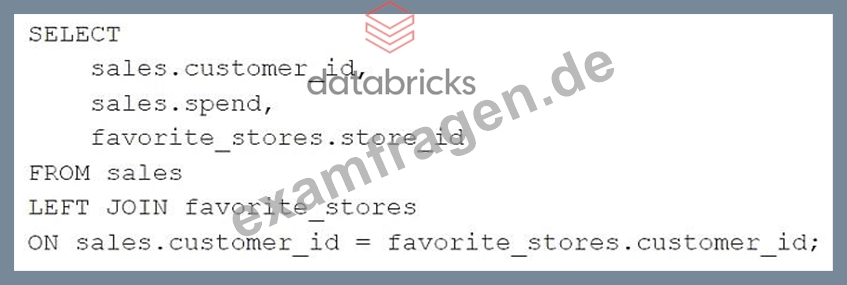
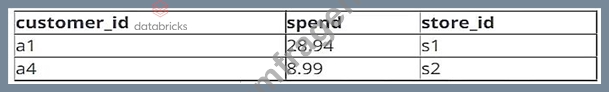
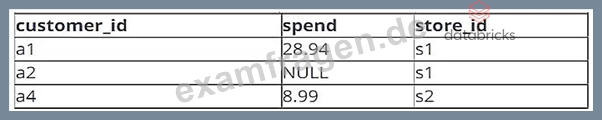
Which of the following will be returned by the above query?
Antwort: A
34. Frage
......
Die Databricks Databricks-Certified-Data-Engineer-Associate Zertifizierungsunterlagen von ExamFragen sind unbedingt die Unterlagen für Databricks Databricks-Certified-Data-Engineer-Associate Zertifizierungsprüfung, an der Sie glauben können. Falls Sie nicht glauben, probieren Sie bitte persönlich, dann können Sie diese Tatsachen wissen. Klicken Sie bitte die Demo von ExamFragen Website. PDF-Versionen und Software-Versionen sind beide vorhanden. Probieren Sie bitte zuerst. Sie können persönlich die Qualität der Databricks Databricks-Certified-Data-Engineer-Associate Dumps überprüfen.
Databricks-Certified-Data-Engineer-Associate PDF: https://www.examfragen.de/Databricks-Certified-Data-Engineer-Associate-pruefung-fragen.html
- Wir machen Databricks-Certified-Data-Engineer-Associate leichter zu bestehen! 👝 Öffnen Sie die Webseite ➥ www.zertsoft.com 🡄 und suchen Sie nach kostenloser Download von { Databricks-Certified-Data-Engineer-Associate } 🦜Databricks-Certified-Data-Engineer-Associate Zertifizierungsantworten
- Databricks-Certified-Data-Engineer-Associate Deutsch Prüfung 🌇 Databricks-Certified-Data-Engineer-Associate Fragen Und Antworten ⏹ Databricks-Certified-Data-Engineer-Associate Zertifizierungsantworten 🛳 Suchen Sie einfach auf ▷ www.itzert.com ◁ nach kostenloser Download von ▷ Databricks-Certified-Data-Engineer-Associate ◁ 👎Databricks-Certified-Data-Engineer-Associate Fragen Antworten
- Databricks-Certified-Data-Engineer-Associate Echte Fragen ⚾ Databricks-Certified-Data-Engineer-Associate Unterlage 👽 Databricks-Certified-Data-Engineer-Associate Prüfungen 🤓 URL kopieren ⮆ www.zertsoft.com ⮄ Öffnen und suchen Sie ☀ Databricks-Certified-Data-Engineer-Associate ️☀️ Kostenloser Download 🥴Databricks-Certified-Data-Engineer-Associate Fragen Beantworten
- Databricks-Certified-Data-Engineer-Associate Fragen&Antworten 🐺 Databricks-Certified-Data-Engineer-Associate PDF Testsoftware 🐮 Databricks-Certified-Data-Engineer-Associate Fragen Beantworten 🔫 Suchen Sie einfach auf ⇛ www.itzert.com ⇚ nach kostenloser Download von ➤ Databricks-Certified-Data-Engineer-Associate ⮘ 👺Databricks-Certified-Data-Engineer-Associate Deutsch Prüfung
- Databricks-Certified-Data-Engineer-Associate Studienmaterialien: Databricks Certified Data Engineer Associate Exam - Databricks-Certified-Data-Engineer-Associate Torrent Prüfung - Databricks-Certified-Data-Engineer-Associate wirkliche Prüfung 🤰 Geben Sie 《 de.fast2test.com 》 ein und suchen Sie nach kostenloser Download von ➡ Databricks-Certified-Data-Engineer-Associate ️⬅️ 💞Databricks-Certified-Data-Engineer-Associate Prüfungsfrage
- Databricks-Certified-Data-Engineer-Associate Fragen Und Antworten 🛸 Databricks-Certified-Data-Engineer-Associate Testking 🏃 Databricks-Certified-Data-Engineer-Associate Fragen Beantworten ✡ Suchen Sie jetzt auf 「 www.itzert.com 」 nach 「 Databricks-Certified-Data-Engineer-Associate 」 und laden Sie es kostenlos herunter ⤵Databricks-Certified-Data-Engineer-Associate Prüfungsfrage
- Databricks-Certified-Data-Engineer-Associate Fragen Und Antworten 🏢 Databricks-Certified-Data-Engineer-Associate Zertifizierung 🥽 Databricks-Certified-Data-Engineer-Associate Deutsch Prüfungsfragen 🏫 Suchen Sie auf ⏩ de.fast2test.com ⏪ nach kostenlosem Download von { Databricks-Certified-Data-Engineer-Associate } 🕣Databricks-Certified-Data-Engineer-Associate Zertifizierungsantworten
- Databricks-Certified-Data-Engineer-Associate Kostenlos Downloden 🧀 Databricks-Certified-Data-Engineer-Associate Prüfungsfrage 🃏 Databricks-Certified-Data-Engineer-Associate Dumps ⛽ Erhalten Sie den kostenlosen Download von “ Databricks-Certified-Data-Engineer-Associate ” mühelos über 【 www.itzert.com 】 🐀Databricks-Certified-Data-Engineer-Associate Fragen Beantworten
- Kostenlos Databricks-Certified-Data-Engineer-Associate Dumps Torrent - Databricks-Certified-Data-Engineer-Associate exams4sure pdf - Databricks Databricks-Certified-Data-Engineer-Associate pdf vce 🔹 Öffnen Sie die Webseite 「 www.deutschpruefung.com 」 und suchen Sie nach kostenloser Download von 《 Databricks-Certified-Data-Engineer-Associate 》 👐Databricks-Certified-Data-Engineer-Associate Fragen Beantworten
- Databricks-Certified-Data-Engineer-Associate Zertifizierung 🤘 Databricks-Certified-Data-Engineer-Associate Kostenlos Downloden ⏲ Databricks-Certified-Data-Engineer-Associate Fragen Und Antworten 📒 Suchen Sie jetzt auf 《 www.itzert.com 》 nach ➥ Databricks-Certified-Data-Engineer-Associate 🡄 um den kostenlosen Download zu erhalten 👱Databricks-Certified-Data-Engineer-Associate Dumps
- Databricks-Certified-Data-Engineer-Associate Prüfungs-Guide 🧵 Databricks-Certified-Data-Engineer-Associate Testking 😟 Databricks-Certified-Data-Engineer-Associate PDF Testsoftware 🧼 Öffnen Sie die Website ▛ www.examfragen.de ▟ Suchen Sie ➡ Databricks-Certified-Data-Engineer-Associate ️⬅️ Kostenloser Download 🏮Databricks-Certified-Data-Engineer-Associate Deutsch Prüfung
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, Disposable vapes
P.S. Kostenlose 2026 Databricks Databricks-Certified-Data-Engineer-Associate Prüfungsfragen sind auf Google Drive freigegeben von ExamFragen verfügbar: https://drive.google.com/open?id=1xgq6HFEX4oUsqq6xiEQ354miceUSS8Id