Reliable Databricks-Certified-Data-Analyst-Associate Braindumps Free - Pdf Databricks-Certified-Data-Analyst-Associate Torrent
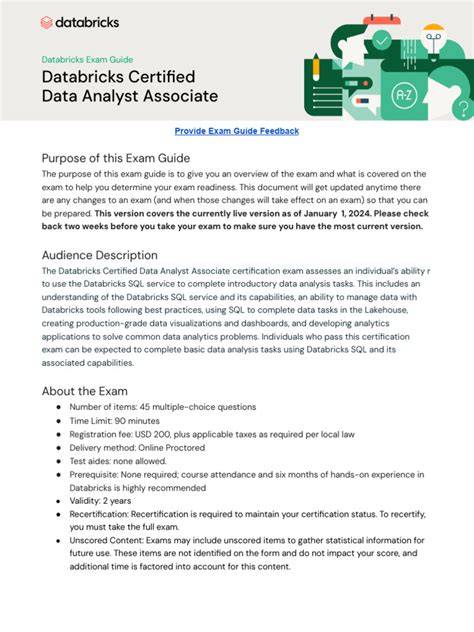
BONUS!!! Download part of itPass4sure Databricks-Certified-Data-Analyst-Associate dumps for free: https://drive.google.com/open?id=11liSvdp9bfh7XYIqjt66Q8YcIiOafxXG
If you fail Databricks-Certified-Data-Analyst-Associate exam with our Databricks-Certified-Data-Analyst-Associate exam dumps, we will full refund the cost that you purchased our Databricks-Certified-Data-Analyst-Associate exam dumps. However, our promise of "No help, full refund" doesn't shows our no confidence to our products; oppositely, it expresses our most sincere and responsible attitude to reassure our customers. With our professional Databricks-Certified-Data-Analyst-Associate Exam software, you will be at ease about your Databricks-Certified-Data-Analyst-Associate exam, and you will be satisfied with our after-sale service after you have purchased our Databricks-Certified-Data-Analyst-Associate exam software.
Databricks Databricks-Certified-Data-Analyst-Associate Exam Overview:
| Certification Vendor: | Databricks |
|---|
| Exam Name: | Databricks Certified Data Analyst Associate Exam |
|---|
| Exam Number: | Databricks-Certified-Data-Analyst-Associate |
|---|
| Real Exam Qty: | 45 |
|---|
| Exam Format: | Multiple Choice |
|---|
| Available Languages: | English |
|---|
| Certificate Validity Period: | 2 years |
|---|
| Passing Score: | 70% |
|---|
| Exam Price: | $200 USD |
|---|
| Exam Duration: | 90 minutes |
|---|
| Related Certifications: | Databricks Certified Machine Learning Associate
Databricks Certified Data Engineer Associate |
|---|
| Sample Questions: | Databricks Databricks-Certified-Data-Analyst-Associate Sample Questions |
|---|
| Exam Way: | Online proctored or test center proctored |
|---|
| Pre Condition: | No formal prerequisites. Databricks recommends 6+ months of hands-on experience with data analysis and Databricks SQL. |
|---|
| Official Syllabus URL: | https://www.databricks.com/learn/certification/data-analyst-associate |
|---|
>> Reliable Databricks-Certified-Data-Analyst-Associate Braindumps Free <<
Pdf Databricks-Certified-Data-Analyst-Associate Torrent | Exam Databricks-Certified-Data-Analyst-Associate Score
For candidates who are going to choose the Databricks-Certified-Data-Analyst-Associate training materials online, the quality must be one of the most important standards. With skilled experts to compile and verify, Databricks-Certified-Data-Analyst-Associate exam braindumps are high quality and accuracy, and you can use them at ease. In addition, Databricks-Certified-Data-Analyst-Associate exam materials are pass guarantee and money back guarantee. You can try free demo for Databricks-Certified-Data-Analyst-Associate Exam Materials, so that you can have a deeper understanding of what you are going to buy. We have online and offline chat service stuff, and if you have any questions for Databricks-Certified-Data-Analyst-Associate exam materials, you can consult us.
| Topic | Details |
|---|
| Topic 1 | - Analytics applications: It describes key moments of statistical distributions, data enhancement, and the blending of data between two source applications. Moroever, the topic also explains last-mile ETL, a scenario in which data blending would be beneficial, key statistical measures, descriptive statistics, and discrete and continuous statistics.
|
| Topic 2 | - Data Visualization and Dashboarding: Sub-topics of this topic are about of describing how notifications are sent, how to configure and troubleshoot a basic alert, how to configure a refresh schedule, the pros and cons of sharing dashboards, how query parameters change the output, and how to change the colors of all of the visualizations. It also discusses customized data visualizations, visualization formatting, Query Based Dropdown List, and the method for sharing a dashboard.
|
| Topic 3 | - SQL in the Lakehouse: It identifies a query that retrieves data from the database, the output of a SELECT query, a benefit of having ANSI SQL, access, and clean silver-level data. It also compares and contrasts MERGE INTO, INSERT TABLE, and COPY INTO. Lastly, this topic focuses on creating and applying UDFs in common scaling scenarios.
|
| Topic 4 | - Databricks SQL: This topic discusses key and side audiences, users, Databricks SQL benefits, complementing a basic Databricks SQL query, schema browser, Databricks SQL dashboards, and the purpose of Databricks SQL endpoints
- warehouses. Furthermore, the delves into Serverless Databricks SQL endpoint
- warehouses, trade-off between cluster size and cost for Databricks SQL endpoints
- warehouses, and Partner Connect. Lastly it discusses small-file upload, connecting Databricks SQL to visualization tools, the medallion architecture, the gold layer, and the benefits of working with streaming data.
|
| Topic 5 | - Data Management: The topic describes Delta Lake as a tool for managing data files, Delta Lake manages table metadata, benefits of Delta Lake within the Lakehouse, tables on Databricks, a table owner’s responsibilities, and the persistence of data. It also identifies management of a table, usage of Data Explorer by a table owner, and organization-specific considerations of PII data. Lastly, the topic it explains how the LOCATION keyword changes, usage of Data Explorer to secure data.
|
Databricks Certified Data Analyst Associate Exam Sample Questions (Q21-Q26):
NEW QUESTION # 21
A data analyst is working in an organization that utilizes a multi-hop, medallion architecture. They have been tasked with creating a new Gold table from an existing Silver table.
Which query is performing a hop from a Silver table to a Gold table?
Answer: B
Explanation:
Option C is the correct answer because it creates a new aggregated table, store_sales, from the existing cleaned
/refined table cleaned_transactions. In a medallion architecture, a table such as cleaned_transactions represents a Silver-layer table because it contains cleaned or validated transaction-level data. The query then creates store_sales by grouping by store_id and calculating SUM(sales), which is an aggregation suitable for analytics and reporting. That is exactly the Silver-to-Gold hop.
Option A creates cleaned_transactions from transactions, so it is moving toward a cleaned Silver table, not creating a Gold table. Option B creates transactions from raw_transactions, which is closer to a raw-to-Bronze or Bronze preparation step. Option D filters rows from transactions into cleaned_transactions, which is also a cleaning/validation step associated with Silver, not Gold.
Exact extract from official Databricks documentation: Databricks describes medallion architecture as improving data through "Bronze # Silver # Gold layer tables." The same official page identifies Silver as
"Data cleaning and validation" and Gold as "Dimensional modeling and aggregation." Databricks also states that the Gold layer "consists of aggregated data tailored for analytics and reporting."
NEW QUESTION # 22
Which of the following approaches can be used to ingest data directly from cloud-based object storage?
- A. Create an external table while specifying the DBFS storage path to FROM
- B. It is not possible to directly ingest data from cloud-based object storage
- C. Create an external table while specifying the DBFS storage path to PATH
- D. Create an external table while specifying the object storage path to LOCATION
- E. Create an external table while specifying the object storage path to FROM
Answer: D
Explanation:
External tables are tables that are defined in the Databricks metastore using the information stored in a cloud object storage location. External tables do not manage the data, but provide a schema and a table name to query the data. To create an external table, you can use the CREATE EXTERNAL TABLE statement and specify the object storage path to the LOCATION clause. For example, to create an external table named ext_table on a Parquet file stored in S3, you can use the following statement:
SQL
CREATE EXTERNAL TABLE ext_table (
col1 INT,
col2 STRING
)
STORED AS PARQUET
LOCATION 's3://bucket/path/file.parquet'
AI-generated code. Review and use carefully. More info on FAQ.
NEW QUESTION # 23
What describes the variance of a set of values?
- A. Variance is a measure of how far a set of values is spread out from the sets central value.
- B. Variance is a measure of how far a single observed value is from a set ot va IN
- C. Variance is a measure of how far an observed value is from the variable ' s maximum or minimum value.
- D. Variance is a measure of central tendency of a set of values.
Answer: A
Explanation:
Variance is a statistical measure that quantifies the dispersion or spread of a set of values around their mean (central value). It is calculated by taking the average of the squared differences between each value and the mean of the dataset. A higher variance indicates that the data points are more spread out from the mean, while a lower variance suggests that they are closer to the mean. This measure is fundamental in statistics to understand the degree of variability within a dataset.WikipediaWikipedia+1Investopedia+1 Reference: Variance - Wikipedia
NEW QUESTION # 24
A data analyst has created a Query in Databricks SQL, and now they want to create two data visualizations from that Query and add both of those data visualizations to the same Databricks SQL Dashboard.
Which of the following steps will they need to take when creating and adding both data visualizations to the Databricks SQL Dashboard?
- A. They will need to alter the Query to return two separate sets of results.
- B. They will need to copy the Query and create one data visualization per query.
- C. They will need to add two separate visualizations to the dashboard based on the same Query.
- D. They will need to decide on a single data visualization to add to the dashboard.
- E. They will need to create two separate dashboards.
Answer: C
Explanation:
A data analyst can create multiple visualizations from the same query in Databricks SQL by clicking the + button next to the Results tab and selecting Visualization. Each visualization can have a different type, name, and configuration. To add a visualization to a dashboard, the data analyst can click the vertical ellipsis button beneath the visualization, select + Add to Dashboard, and choose an existing or new dashboard. The data analyst can repeat this process for each visualization they want to add to the same dashboard. Reference: Visualization in Databricks SQL, Visualize queries and create a dashboard in Databricks SQL
NEW QUESTION # 25
A data analyst has developed a query that runs against a Delta table. They want help from the data engineering team to implement a series of tests to ensure the data returned by the query is clean. However, the data engineering team uses Python for its tests rather than SQL.
Which of the following operations could the data engineering team use to run the query and operate with the results in PySpark?
- A. spark.sql
- B. There is no way to share data between PySpark and SQL.
- C. spark.delta.table
- D. spark.table
- E. SELECT * FROM sales
Answer: A
Explanation:
Option C is correct because the requirement is to run the SQL query and then operate on the results in PySpark. spark.sql(...) executes SQL text and returns a Spark DataFrame that can be used in PySpark tests.
spark.table(...) can load a table directly, but it does not run an arbitrary SQL query. Option A is SQL text by itself, not a PySpark operation. Official Databricks documentation states that a SparkSession can be used to execute SQL over tables, and Databricks notebook documentation specifically references using SQL inside Python with a spark.sql command.
NEW QUESTION # 26
......
Pdf Databricks-Certified-Data-Analyst-Associate Torrent: https://www.itpass4sure.com/Databricks-Certified-Data-Analyst-Associate-practice-exam.html
- Pass-Sure Databricks Reliable Databricks-Certified-Data-Analyst-Associate Braindumps Free Offer You The Best Pdf Torrent | Databricks Certified Data Analyst Associate Exam ↪ The page for free download of ( Databricks-Certified-Data-Analyst-Associate ) on [ www.examcollectionpass.com ] will open immediately 👣Vce Databricks-Certified-Data-Analyst-Associate Exam
- Databricks Databricks-Certified-Data-Analyst-Associate PDF Questions - Best Exam Preparation Strategy ✅ Search for 《 Databricks-Certified-Data-Analyst-Associate 》 and easily obtain a free download on ( www.pdfvce.com ) 🦹Examcollection Databricks-Certified-Data-Analyst-Associate Questions Answers
- Real Databricks-Certified-Data-Analyst-Associate Torrent 🏁 PDF Databricks-Certified-Data-Analyst-Associate Cram Exam 😴 Pdf Databricks-Certified-Data-Analyst-Associate Format 🍛 Search for 「 Databricks-Certified-Data-Analyst-Associate 」 and obtain a free download on [ www.examcollectionpass.com ] 🏐Pdf Databricks-Certified-Data-Analyst-Associate Format
- Authorized Databricks-Certified-Data-Analyst-Associate Pdf 🧴 Training Databricks-Certified-Data-Analyst-Associate For Exam 🅰 Examcollection Databricks-Certified-Data-Analyst-Associate Questions Answers 🎸 Copy URL ➥ www.pdfvce.com 🡄 open and search for ▶ Databricks-Certified-Data-Analyst-Associate ◀ to download for free ✨Pdf Databricks-Certified-Data-Analyst-Associate Free
- Examcollection Databricks-Certified-Data-Analyst-Associate Questions Answers 🛑 Databricks-Certified-Data-Analyst-Associate Trusted Exam Resource 🥟 Pdf Databricks-Certified-Data-Analyst-Associate Format 🐷 Open website ➤ www.vceengine.com ⮘ and search for 「 Databricks-Certified-Data-Analyst-Associate 」 for free download 🍳New Databricks-Certified-Data-Analyst-Associate Test Guide
- Latest Databricks-Certified-Data-Analyst-Associate Dumps Ppt 🎈 New Databricks-Certified-Data-Analyst-Associate Test Guide 🥶 Authorized Databricks-Certified-Data-Analyst-Associate Pdf 😖 Search on ➠ www.pdfvce.com 🠰 for ▶ Databricks-Certified-Data-Analyst-Associate ◀ to obtain exam materials for free download ⚔Pdf Databricks-Certified-Data-Analyst-Associate Format
- Databricks-Certified-Data-Analyst-Associate Trusted Exam Resource 🏸 Pass Databricks-Certified-Data-Analyst-Associate Guarantee 🏤 Databricks-Certified-Data-Analyst-Associate Trusted Exam Resource 🚎 ⏩ www.prepawaypdf.com ⏪ is best website to obtain ➡ Databricks-Certified-Data-Analyst-Associate ️⬅️ for free download 🎑Latest Databricks-Certified-Data-Analyst-Associate Exam Review
- 2026 100% Free Databricks-Certified-Data-Analyst-Associate –Updated 100% Free Reliable Braindumps Free | Pdf Databricks Certified Data Analyst Associate Exam Torrent 🏧 Enter “ www.pdfvce.com ” and search for 《 Databricks-Certified-Data-Analyst-Associate 》 to download for free ⚫Examcollection Databricks-Certified-Data-Analyst-Associate Questions Answers
- New Databricks-Certified-Data-Analyst-Associate Test Guide 🦩 Databricks-Certified-Data-Analyst-Associate PDF Download 🏕 Real Databricks-Certified-Data-Analyst-Associate Torrent 🌀 Easily obtain free download of ⏩ Databricks-Certified-Data-Analyst-Associate ⏪ by searching on ➤ www.examcollectionpass.com ⮘ 🥺Trustworthy Databricks-Certified-Data-Analyst-Associate Exam Torrent
- Real Databricks-Certified-Data-Analyst-Associate Torrent 🤗 Vce Databricks-Certified-Data-Analyst-Associate Exam ◀ Trustworthy Databricks-Certified-Data-Analyst-Associate Exam Torrent 🍴 Download ➡ Databricks-Certified-Data-Analyst-Associate ️⬅️ for free by simply entering ▛ www.pdfvce.com ▟ website 🐫Examcollection Databricks-Certified-Data-Analyst-Associate Questions Answers
- Databricks Databricks-Certified-Data-Analyst-Associate PDF Questions - Best Exam Preparation Strategy 😰 Simply search for ⮆ Databricks-Certified-Data-Analyst-Associate ⮄ for free download on “ www.vce4dumps.com ” 🍡Databricks-Certified-Data-Analyst-Associate PDF Download
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, everlink.tools, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, jacobscott67888.blogspot.com, www.longisland.com, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.twosapp.com, Disposable vapes
BONUS!!! Download part of itPass4sure Databricks-Certified-Data-Analyst-Associate dumps for free: https://drive.google.com/open?id=11liSvdp9bfh7XYIqjt66Q8YcIiOafxXG


