Laden Sie die neuesten PrüfungFrage DP-600 PDF-Versionen von Prüfungsfragen kostenlos von Google Drive herunter: https://drive.google.com/open?id=1LWl2RTPsAy2QHx41wwe3MiM1VKBQ82oh
Die Konkurrenz in der IT-Branche wird immer heftiger. Wie können Sie sich beweisen, dass Sie wichig und unerlässlich ist? Die Zertifizierung der Microsoft DP-600 zu erwerben macht es überzeugend. Was wir für Sie tun können ist, dass Ihnen helfen, die Microsoft DP-600 Prüfung mit höhere Effizienz und weniger Mühen zu bestehen. Mit langjährigen Entwicklung besitzt jetzt PrüfungFrage große Menge von Ressourcen und Erfahrungen. Immer verbesserte Software gibt Ihnen bessere Vorbereitungsphase der Microsoft DP-600 Prüfung.
| Certification Vendor: | Microsoft |
|---|---|
| Exam Name: | Implementing Analytics Solutions Using Microsoft Fabric |
| Exam Number: | DP-600 |
| Certificate Validity Period: | 1 year (renewable via Microsoft certification renewal) |
| Exam Format: | Drag and drop, Scenario-based questions, Case studies, Multiple choice |
| Exam Duration: | 120 minutes |
| Exam Price: | $165 USD (varies by country) |
| Real Exam Qty: | 40-60 |
| Available Languages: | Korean, French, Portuguese (Brazil), Simplified Chinese, English, Spanish, Japanese, German |
| Related Certifications: | DP-900 PL-300 DP-203 |
| Passing Score: | 700 (out of 1000) |
| Recommended Training: | Microsoft Fabric Documentation DP-600 Learning Path (Microsoft Learn) |
| Exam Registration: | Microsoft Certification Dashboard Pearson VUE Microsoft Exams |
| Sample Questions: | Microsoft DP-600 Sample Questions |
| Exam Way: | Online proctored exam or in-person at Pearson VUE test centers |
| Pre Condition: | No formal prerequisites required, but familiarity with data analytics, Power BI, and Azure data services is recommended. |
| Official Syllabus URL: | https://learn.microsoft.com/credentials/certifications/fabric-analytics-engineer/ |
Die Schulungsunterlagen zur Microsoft DP-600 Zertifizierungsprüfung von PrüfungFrage werden die größte Erfolgsquote erzielen. Naben den Büchern sind heutztage das Internet als ein Wissensschatz angesehen. In PrüfungFrage können Sie Ihren Wissensschatz finden. Das ist eine Website, die Ihnen sehr helfen können. Sie werden sicher komplizierte Übungen treffen, Unser PrüfungFrage wird Ihnen helfen, die Prüfung ganz einfach zu bestehen, weil es alle erforderlichen Kenntnisse zur Microsoft DP-600 Zertifizierungsprüfung enthält.
| Thema | Einzelheiten |
|---|---|
| Thema 1 |
|
| Thema 2 |
|
| Thema 3 |
|
48. Frage
You have source data in a CSV file that has the following fields:
* SalesTra nsactionl D
* SaleDate
* CustomerCode
* CustomerName
* CustomerAddress
* ProductCode
* ProductName
* Quantity
* UnitPrice
You plan to implement a star schema for the tables in WH1. Thedimension tables in WH1 will implement Type 2 slowly changing dimension (SCD) logic.
You need to design the tables that will be used for sales transaction analysis and load the source data.
Which type of target table should you specify for the CustomerName, CustomerCode, and SaleDate fields?
To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.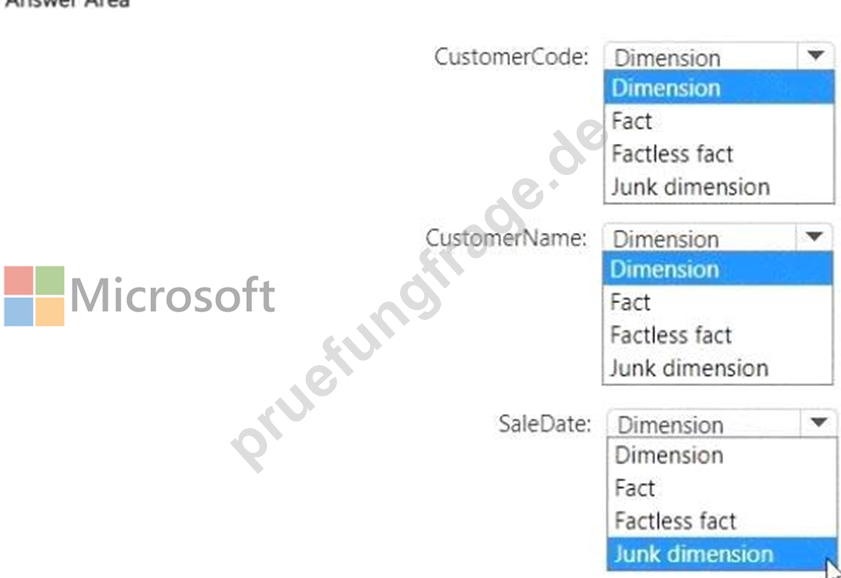
Antwort:
Begründung: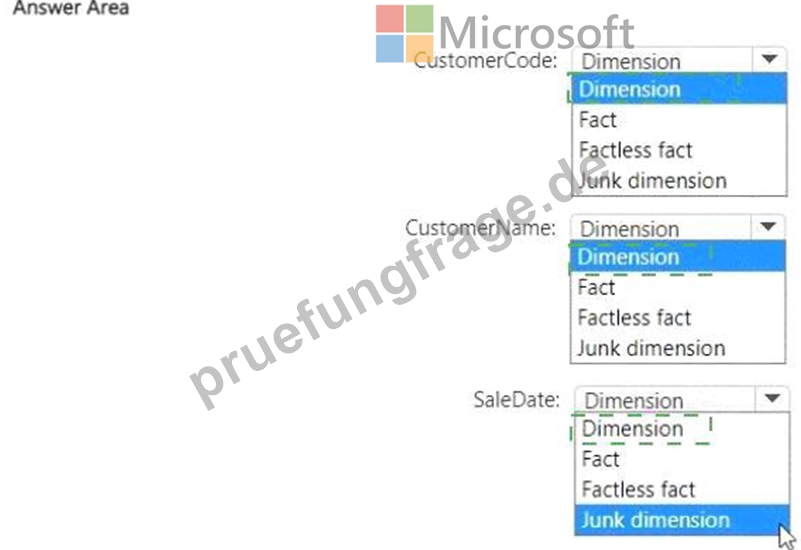
Explanation: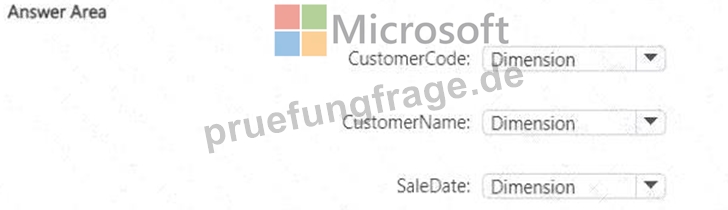
49. Frage
You have a Fabric workspace that contains a Dataflow Gen2 query. The query returns the following data.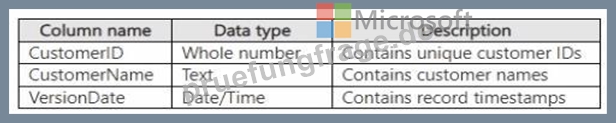
You need to filter the results to ensure that only the latest version of each customer's record is retained. The solution must ensure that no new columns are loaded to the semantic model.
Which four actions should you perform in sequence in Power Query Editor? To answer, move the appropriate actions from the list of actions to the answer area and arrange them in the correct order.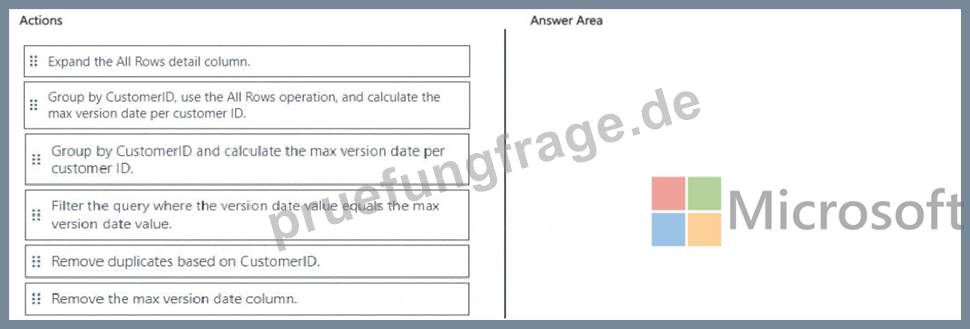
Antwort:
Begründung: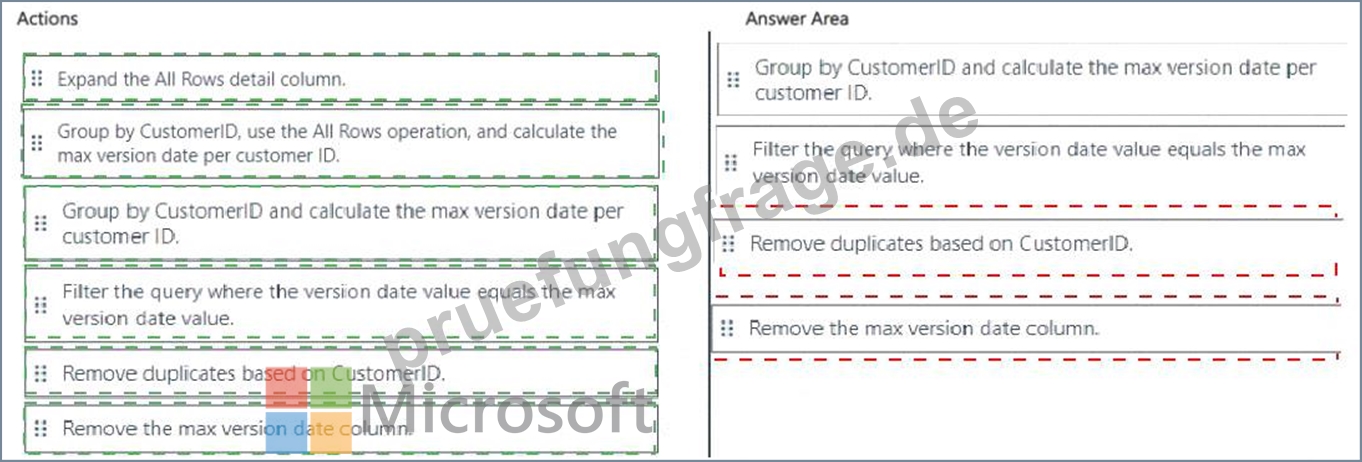
Explanation: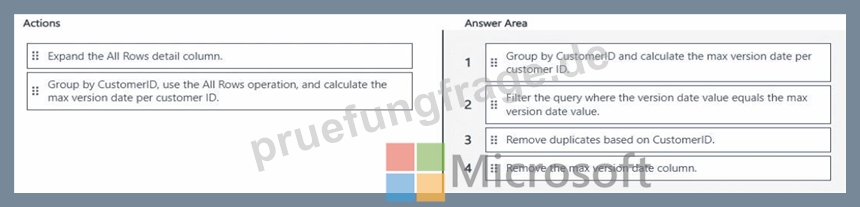
Comprehensive Detailed Explanation
We have a table with:
CustomerID # unique ID
CustomerName # customer's name
VersionDate # timestamp representing version history
The requirement:
Keep only the latest record per customer.
Ensure no new technical columns (like max version date) remain in the semantic model.
Step 1: Identify latest version per customer
We need to determine the latest VersionDate for each CustomerID.
Use Group By CustomerID and calculate Max of VersionDate.
This creates a mapping of CustomerID # latest VersionDate.
Step 2: Filter to keep only latest records
Join or filter original data so that only rows with VersionDate = Max(VersionDate) are retained.
This ensures that only the most recent record is kept per customer.
Step 3: Remove the helper column
The column holding Max VersionDate is only needed for filtering.
It must be removed because the requirement is that no new columns are loaded to the semantic model.
Step 4: Remove duplicates
As a final safeguard, remove duplicates by CustomerID, ensuring that each customer appears only once.
Final Ordered Actions
Group by CustomerID and calculate the max version date per customer ID.
Filter the query where the version date value equals the max version date value.
Remove the max version date column.
Remove duplicates based on CustomerID.
50. Frage
You have Fabric tenant that contains a semantic model named Mode1. Model! contains the following tables.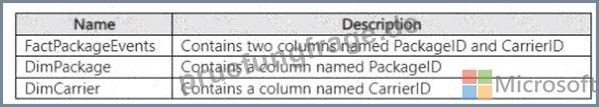
You are designing a Microsoft Power B1 report named Report! that will deliver near-real-time (NRT) shipping data. Report1 will contain data about many shipped packages.
You need to ensure that each table is in the appropriate storage mode to support Report1. The solution must support near-realtime data delivery while maintaining high query performance.
Which storage mode should you select for each table? To answer, drag the appropriate storage modes to the correct tables. Each mode may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.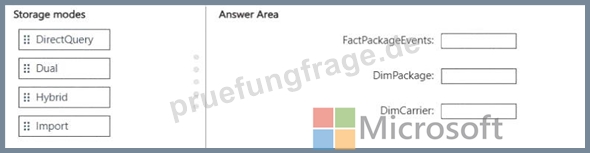
Antwort:
Begründung: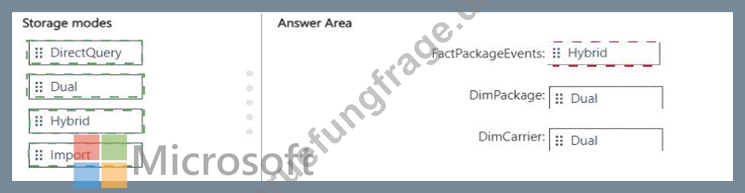
Explanation: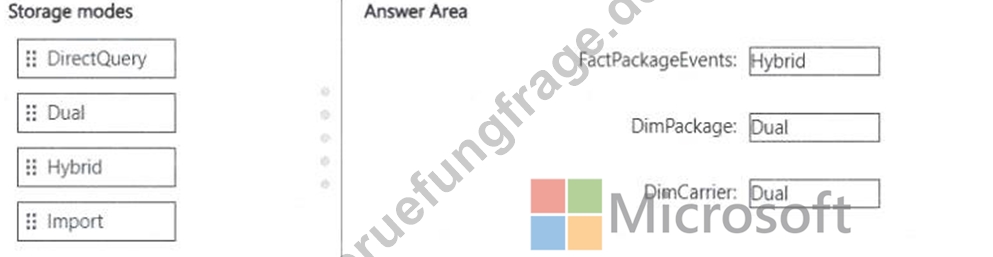
51. Frage
You have a semantic model named Model 1. Model 1 contains five tables that all use Import mode. Model1 contains a dynamic row-level security (RLS) role named HR. The HR role filters employee data so that HR managers only see the data of the department to which they are assigned.
You publish Model1 to a Fabric tenant and configure RLS role membership. You share the model and related reports to users.
An HR manager reports that the data they see in a report is incomplete.
What should you do to validate the data seen by the HR Manager?
Antwort: D
Begründung:
To validate the data seen by the HR manager, you should use the 'Test as role' feature in Power BI service.
This allows you to see the data exactly as it would appear for the HR role, considering the dynamic RLS setup. Here is how you would proceed:
* Navigate to the Power BI service and locate Model1.
* Access the dataset settings for Model1.
* Find the security/RLS settings where you configured the roles.
* Use the 'Test as role' feature to simulate the report viewing experience as the HR role.
* Review the data and the filters applied to ensure that the RLS is functioning correctly.
* If discrepancies are found, adjust the RLS expressions or the role membership as needed.
References: The 'Test as role' feature and its use for validating RLS in Power BI is covered in the Power BI documentation available on Microsoft's official documentation.
52. Frage
You have a KQL database that contains a table named Readings.
You need to query Readings and return the results shown in the following table.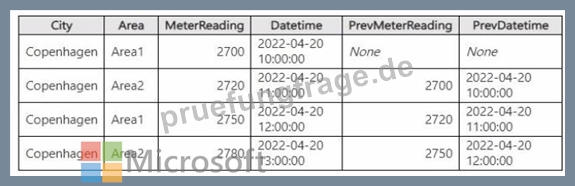
How should you complete the query? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.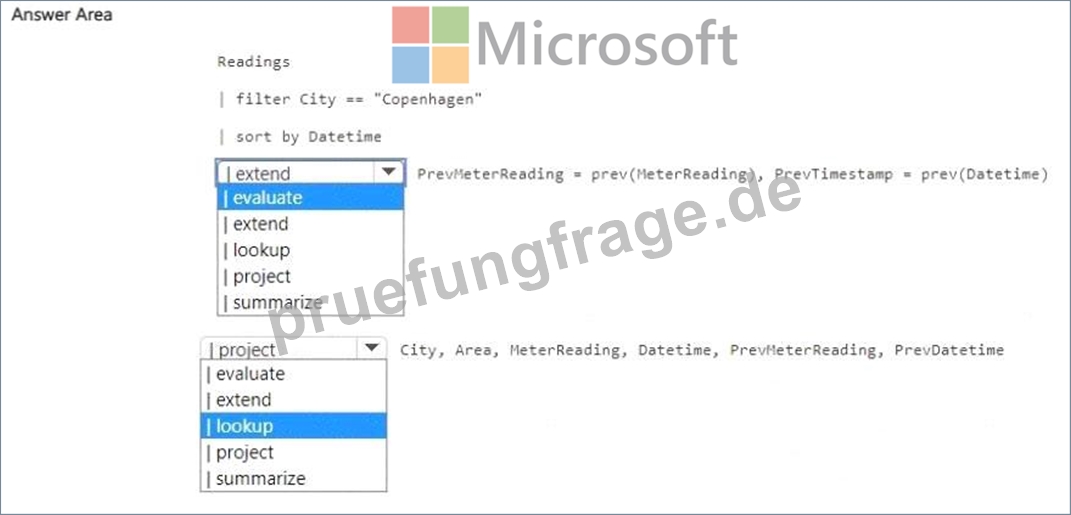
Antwort:
Begründung:
Explanation: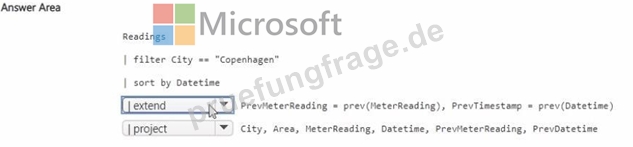
Comprehensive Detailed Explanation
We need to query a KQL database table named Readings to generate output that includes both the current reading and the previous reading values and datetime for each row.
Step 1: Understanding Requirements
The output table shows:
City, Area, MeterReading, Datetime
PrevMeterReading, PrevDatetime
The prev() function in KQL is used to access the value of a column from the previous row (based on order).
Step 2: Query Construction
We start with filtering:
Readings
| where City == "Copenhagen"
| sort by Datetime
To add columns that calculate the previous reading and previous datetime, we use extend:
| extend PrevMeterReading = prev(MeterReading), PrevDatetime = prev(Datetime) extend creates new columns.
prev() pulls the previous row's values.
Finally, we only want specific columns in the output. For this, we use project:
| project City, Area, MeterReading, Datetime, PrevMeterReading, PrevDatetime Step 3: Completed Query Readings
| where City == "Copenhagen"
| sort by Datetime
| extend PrevMeterReading = prev(MeterReading), PrevDatetime = prev(Datetime)
| project City, Area, MeterReading, Datetime, PrevMeterReading, PrevDatetime Why This is Correct extend adds calculated columns.
prev() gives access to the previous row.
project selects only the required columns.
This matches exactly the table shown in the question.
References
Kusto Query Language - extend operator
Kusto Query Language - project operator
prev() function in KQL
53. Frage
......
DP-600 Ausbildungsressourcen: https://www.pruefungfrage.de/DP-600-dumps-deutsch.html
P.S. Kostenlose und neue DP-600 Prüfungsfragen sind auf Google Drive freigegeben von PrüfungFrage verfügbar: https://drive.google.com/open?id=1LWl2RTPsAy2QHx41wwe3MiM1VKBQ82oh