Our Mule-Arch-201 exam questions provide with the software which has a variety of self-study and self-assessment functions to detect learning results. The statistical reporting function is provided to help students find weak points and deal with them. Our software is also equipped with many new functions, such as timed and simulated test functions. After you set up the simulation test timer with our Mule-Arch-201 Test Guide which can adjust speed and stay alert, you can devote your mind to learn the knowledge. There is no doubt that the function can help you pass the Mule-Arch-201 exam.
| Section | Weight | Objectives |
|---|---|---|
| Designing and Sharing APIs | 11% | - Asset sharing and reuse via Anypoint Exchange - API layering: Experience, Process, System APIs - API specification and documentation - API design standards and best practices |
| Meeting API Quality Goals | 8% | - Security and compliance standards - Performance and latency requirements - Maintainability and testability - Reliability and availability targets |
| Managing APIs | 12% | - API policies and security enforcement - Rate limiting and throttling - API lifecycle management - Versioning and deprecation strategies |
| Explaining Application Network Basics | 11% | - Core concepts of application networks - API-led connectivity principles - Benefits of modern API design |
| Monitoring and Analyzing Application Networks | 8% | - Analytics and insight generation - Monitoring strategies and tools - Operational visibility and optimization - Logging and alerting configuration |
| Establishing Organizational and Platform Foundations | 17% | - Platform strategy and roadmap definition - Center for Enablement (C4E) operating model - Anypoint Platform architecture and components - Governance and organizational structure |
| Applying Integration Patterns | 11% | - Scalability and performance patterns - Common integration patterns and use cases - Event-driven and synchronous integration - Error handling and reliability patterns |
| Architecting and Deploying API Implementations | 11% | - High availability and fault tolerance - Runtime architecture and deployment options - Networking and security configuration - CI/CD and DevOps integration |
| Deploying API Implementations to CloudHub | 11% | - Deployment optimization and scaling - CloudHub architecture and capabilities - VPC and private space configuration - Worker sizing and resource planning |
>> Mule-Arch-201 Valid Exam Papers <<
From your first contact with our Mule-Arch-201 practice guide, you can enjoy our excellent service. Before you purchase Mule-Arch-201 exam questions, you can consult our online customer service. Even if you choose to use our trial version of our Mule-Arch-201 Study Materials first, we will not give you any differential treatment. As long as you have questions on the Mule-Arch-201 learning guide, we will give you the professional suggestions.
NEW QUESTION # 45
A company is using an on-prem cluster in the data center as a runtime plane and MuleSoft-hosted control plane.
How can the company monitor the detailed performance metrics on the Mule applications deployed to the cluster from the control plane?
Answer: C
Explanation:
Monitoring On-Premise Mule Applications:
For Mule applications deployed on an on-premises cluster, monitoring detailed performance metrics requires communication with the MuleSoft-hosted control plane. The control plane, when used with on-premises runtimes, relies on Anypoint Monitoring and requires a Monitoring Agent to gather and send detailed performance metrics.
Setting Up Monitoring:
To enable detailed metrics, the Monitoring Agent must be installed on each node in the cluster where Mule applications are deployed. This agent collects data on memory usage, CPU load, response times, and other metrics, and sends it to the control plane for aggregation and visualization.
Evaluating the Options:
Option A: Updating settings in the control plane alone does not enable detailed monitoring; the agent must be installed on each node to capture detailed metrics.
Option B (Correct Answer): Installing the Monitoring Agent on each node ensures that each runtime node in the cluster can send its metrics to the control plane, enabling detailed monitoring.
Option C: Installing the agent on a separate server would not be effective, as each node in the cluster needs to independently report its metrics to ensure full visibility.
Option D: The on-prem runtime does not automatically send detailed metrics to the control plane without the Monitoring Agent installed.
Conclusion:
Option B is the correct answer, as installing the Monitoring Agent on each node is essential for detailed performance monitoring of on-prem applications in a cluster.
Refer to MuleSoft's documentation on configuring Anypoint Monitoring for on-premises deployments and using the Monitoring Agent.
NEW QUESTION # 46
A customer has an ELA contract with MuleSoft. An API deployed to CloudHub is consistently experiencing performance issues. Based on the root cause analysis, it is determined that autoscaling needs to be applied.
How can this be achieved?
Answer: B
Explanation:
In MuleSoft CloudHub, autoscaling is essential to managing application load efficiently. CloudHub supports horizontal scaling based on CPU usage, which is well-suited to applications experiencing variable demand and needing responsive resource allocation.
Autoscaling on CloudHub:
Horizontal scaling increases the number of workers in response to CPU usage thresholds, allowing the application to handle higher loads dynamically. This approach improves performance without downtime or manual intervention.
Why Option C is Correct:
Setting up autoscaling based on CPU usage aligns with MuleSoft's best practices for scalable and responsive applications on CloudHub, particularly in an environment with fluctuating load patterns.
Option C correctly leverages CloudHub's autoscaling features based on resource metrics, which are part of CloudHub's managed scaling solutions.
of Incorrect Options:
Option A (based on HTTP request thresholds) and Option B (separate policies for CPU and memory) do not represent CloudHub's recommended scaling practices.
Option D suggests vertical scaling based on response time, which is not how CloudHub handles autoscaling.
Reference
For more on CloudHub's autoscaling configuration, refer to MuleSoft documentation on CloudHub autoscaling policies.
NEW QUESTION # 47
An organization has built an application network following the API-led connectivity approach recommended by MuleSoft. To protect the application network against attacks from malicious external API clients, the organization plans to apply JSON Threat Protection policies.
To which API-led connectivity layer should the JSON Threat Protection policies most commonly be applied?
Answer: D
Explanation:
Understanding JSON Threat Protection Policies:
JSON Threat Protection policies are used to protect APIs from attacks that exploit JSON payloads, such as oversized payloads, deeply nested objects, and excessive array elements. This helps prevent Denial of Service (DoS) attacks and other malicious payload-related threats.
These policies are typically applied to safeguard APIs that are directly exposed to external clients, where the risk of receiving malicious payloads is highest.
API-led Connectivity Layers:
Experience Layer: This layer is designed to expose APIs to end-users or external API clients, often acting as the interface that interacts with users or applications.
Process Layer: This layer is used for orchestration and aggregation of data from various System APIs, typically operating within a trusted environment and not directly exposed to external clients.
System Layer: This layer provides access to backend systems and databases, often within the organization's secure environment and not directly accessible to external clients.
Evaluating the Options:
Option A (All layers): While JSON Threat Protection can technically be applied to all layers, it is most commonly applied at the Experience layer, where APIs are exposed to external traffic and are more vulnerable to attacks.
Option B (System layer): The System layer is generally not exposed to external clients directly, so JSON Threat Protection is less critical here.
Option C (Process layer): Similar to the System layer, the Process layer is typically internal and not exposed directly to external clients, so JSON Threat Protection is less commonly applied.
Option D (Correct Answer): The Experience layer is the correct answer because it is the layer that directly interacts with external clients, making it the primary target for malicious payloads. Applying JSON Threat Protection here effectively protects the application network from external threats.
Conclusion:
Option D is the correct answer, as the Experience layer is the most common layer for applying JSON Threat Protection policies to protect against external attacks.
For further reference, consult MuleSoft's documentation on API security policies and best practices for securing APIs at the Experience layer.
NEW QUESTION # 48
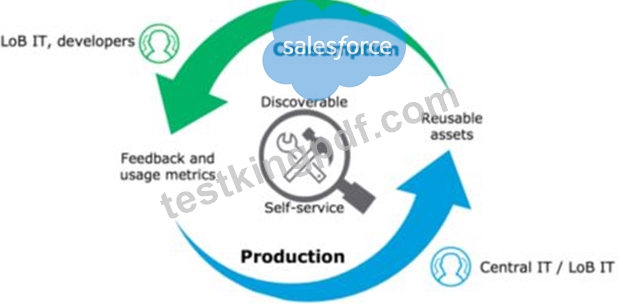
Which of the below, when used together, makes the IT Operational Model effective?
Answer: A
Explanation:
Correct Answe r: Create reusable assets, Make them discoverable so that LOB teams can self-serve and browse the APIs, Get active feedback and usage metrics.
*****************************************
NEW QUESTION # 49
Say, there is a legacy CRM system called CRM-Z which is offering below functions:
1. Customer creation
2. Amend details of an existing customer
3. Retrieve details of a customer
4. Suspend a customer
Answer: A
Explanation:
Correct Answe r: Implement different system APIs named createCustomer, amendCustomer, retrieveCustomer and suspendCustomer as they are modular and has seperation of concerns
*****************************************
>> It is quite normal to have a single API and different Verb + Resource combinations. However, this fits well for an Experience API or a Process API but not a best architecture style for System APIs. So, option with just one customerManagement API is not the best choice here.
>> The option with APIs in createCustomerInCRMZ format is next close choice w.r.t modularization and less maintenance but the naming of APIs is directly coupled with the legacy system. A better foreseen approach would be to name your APIs by abstracting the backend system names as it allows seamless replacement/migration of any backend system anytime. So, this is not the correct choice too.
>> createCustomer, amendCustomer, retrieveCustomer and suspendCustomer is the right approach and is the best fit compared to other options as they are both modular and same time got the names decoupled from backend system and it has covered all requirements a System API needs.
NEW QUESTION # 50
......
So many of our worthy customers have achieved success not only on the career but also on the life style due to the help of our Mule-Arch-201 study guide. You can also join them and learn our Mule-Arch-201 learning materials. You will gradually find your positive changes after a period of practices. Then you will finish all your tasks excellently. You will become the lucky guys if there has a chance. Our Mule-Arch-201 Exam Braindumps are waiting for you to have a try.
Mule-Arch-201 Exam Questions Vce: https://www.testkingpdf.com/Mule-Arch-201-testking-pdf-torrent.html