2026 Latest Pass4sures DP-750 PDF Dumps and DP-750 Exam Engine Free Share: https://drive.google.com/open?id=1cyj4hVD2lbDxFQ3eGNUTzV-dvOmyTnsU
The Microsoft DP-750 certification is one of the top-rated career advancement certifications in the market. This Implementing Data Engineering Solutions Using Azure Databricks (DP-750) certification exam has been inspiring candidates since its beginning. Over this long time period, thousands of DP-750 exam candidates have passed their Implementing Data Engineering Solutions Using Azure Databricks (DP-750) certification exam and now they are doing jobs in the world's top brands. The Pass4sures DP-750 Dumps will provide you with everything that you need to learn, prepare and pass the challenging Network Security Specialist DP-750 exam with flying colors. You must try Pass4sures DP-750 exam questions today.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Secure and govern data using Unity Catalog | 15-20% | - Access control and policies
|
| Topic 2: Prepare and process data | 30-35% | - Data transformation and modeling
|
| Topic 3: Deploy and manage data pipelines and workloads | 30-35% | - Pipeline design and orchestration
|
| Topic 4: Configure and manage Azure Databricks environments | 15-20% | - Security and authentication setup
|
Knowledge of the DP-750 real study dumps contains are very comprehensive, not only have the function of online learning, also can help the user to leak fill a vacancy, let those who deal with qualification exam users can easily and efficient use of the DP-750 question guide. By visit our website, the user can obtain an experimental demonstration, free after the user experience can choose the most appropriate and most favorite DP-750 Exam Questions download. Users can not only learn new knowledge, can also apply theory into the actual problem, but also can leak fill a vacancy, can say such case selection is to meet, so to grasp the opportunity!
NEW QUESTION # 91
Which ingestion option should you recommend for each data source? To answer, drag the appropriate options to the correct data sources. Each option may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.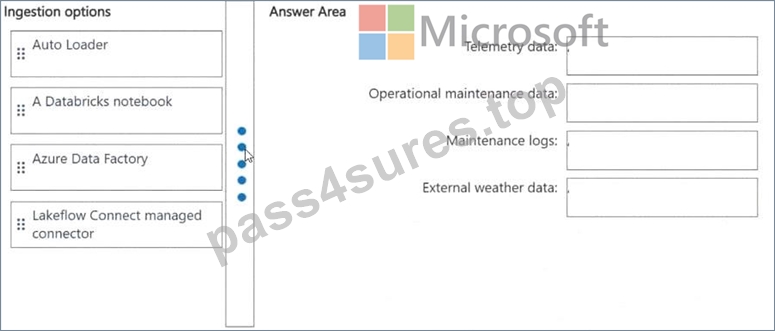
Answer:
Explanation: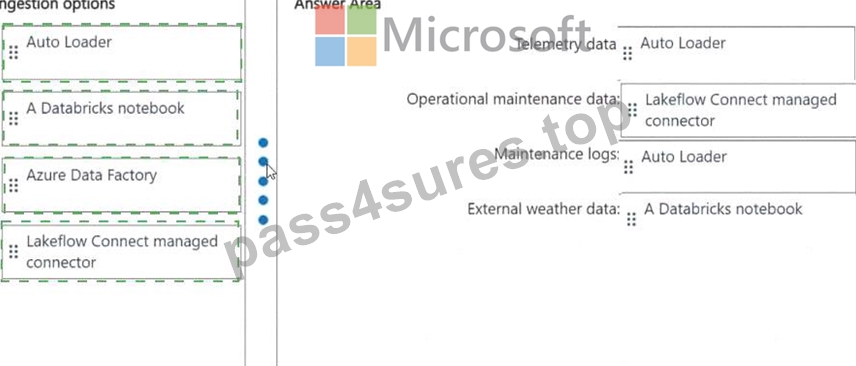
Explanation:
The right ingestion tool depends on the source characteristics:
File-based telemetry and maintenance data # Auto Loader (cloudFiles). It monitors ADLS Gen2 for new arrivals, handles schema inference and evolution for the frequent schema drift, and requires minimal operational effort.
Real-time telemetry from Event Hubs # Spark Structured Streaming with the azure-eventhubs-spark connector. This provides exactly-once semantics and checkpoint-based recovery, satisfying 'resume processing after failures without reprocessing.' Structured maintenance data from PostgreSQL # JDBC connector. Databricks supports direct JDBC reads from relational databases with pushdown predicates.
Daily CSV ERP extracts (50-100 GB) # COPY INTO or Auto Loader. Both support idempotent incremental batch loading into Delta tables with minimal code.
Reference: https://learn.microsoft.com/en-us/azure/databricks/ingestion/auto-loader/
NEW QUESTION # 92
What improves join performance for small lookup tables?
Answer: A
NEW QUESTION # 93
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a managed Delta table named Table1.
Table1 stores customer profile data.
Business users must analyze how customer profile records change over time. They must also be able to query earlier versions of the table.
You need to implement a solution that:
* Maintains persistent historical versions of customer profile records for long-term analysis.
* Allows users to query earlier versions of the Delta table.
* Minimizes maintenance effort.
What should you do? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.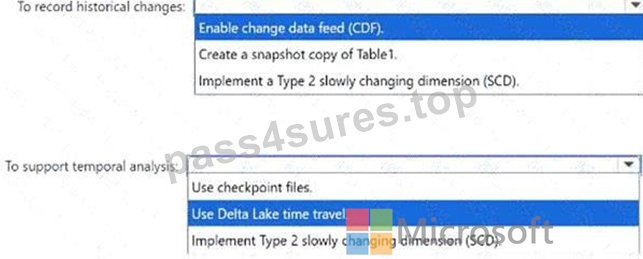
Answer:
Explanation: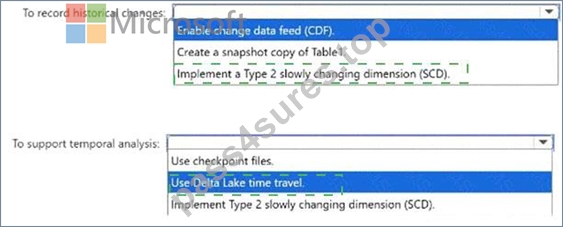
Explanation:
To record historical changes: Implement a Type 2 slowly changing dimension (SCD).
To support temporal analysis: Use Delta Lake time travel.
A Type 2 slowly changing dimension preserves customer-profile history by inserting a new record whenever a tracked attribute changes instead of overwriting the existing record. Effective dates, expiration dates, version values, or current-record indicators can identify which version applied during a particular period. This provides persistent business history for long-term analysis. Delta Lake time travel supports temporal analysis of the physical table by allowing users to query an earlier version with VERSION AS OF or TIMESTAMP AS OF. Time travel is useful for auditing and reproducing previous results, but its availability depends on retained Delta log entries and data files. Therefore, it should not replace a Type 2 SCD for permanent customer history. Together, the two features satisfy the historical-record and earlier-version requirements.
NEW QUESTION # 94
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a managed Delta table named Sales.
Sales stores transaction data and contains the following columns:
- transaction_id (string)
- transaction_date (date)
- amount (decimal)
You need to implement the following data quality requirements by using table-level data quality enforcement:
- amount must be greater than 0.
- transaction_id must never be null.
- Invalid records must be rejected when data is written to the Sales
table.
What should you do?
Answer: D
Explanation:
To enforce these table-level data quality rules and automatically reject any invalid write operations in Azure Databricks, you must configure NOT NULL and CHECK constraints on the Delta table using standard SQL commands.
In Delta Lake, these constraints are enforced instantly on write. If an incoming record violates any of them, the entire transaction fails, and the invalid records are rejected.
1. Enforce transaction_id Cannot Be Null
Add a NOT NULL constraint to the transaction_id column. This blocks any write attempt containing a null identifier.
ALTER TABLE sales_data ALTER COLUMN transaction_id SET NOT NULL;
2. Enforce amount Must Be Greater Than 0
Add a CHECK constraint to the table to validate that the amount values strictly exceed zero.
ALTER TABLE sales_data ADD CONSTRAINT check_amount_positive CHECK (amount > 0); Reference:
https://docs.databricks.com/aws/en/tables/constraints
NEW QUESTION # 95
Note: This section contains one or more sets of questions with the same scenario and problem. Each question presents a unique solution to the problem. You must determine whether the solution meets the stated goals. More than one solution in the set might solve the problem. It is also possible that none of the solutions in the set solve the problem.
After you answer a question in this section, you will NOT be able to return. As a result, these questions do not appear on the Review Screen.
You have an Azure Databricks workspace named Workspace1 that contains a lakehouse and is enabled for Unity Catalog.
You have a connection to a Microsoft SQL Server database named DB1.
You need to expose the schemas and tables of DB1 to meet the following requirements:
- The schemas and tables can be queried in Databricks.
- The schemas and tables appear alongside other Unity Catalog objects.
- The data is NOT copied into Databricks-managed storage.
Solution: You create a foreign catalog in Catalog Explorer.
Does this meet the goal?
Answer: A
Explanation:
Correct:
* You create a foreign catalog in Catalog Explorer.
You should create a Foreign Catalog using Lakehouse Federation.
Data Copying: Lakehouse Federation queries data directly in the source SQL Server without moving or copying it.
Seamless Integration: The database schemas and tables appear right inside Unity Catalog alongside your other data objects.Real-time Access: It provides immediate access to live SQL Server data.
Incorrect:
* You create a Databricks access connector.
* You create a Lakeflow Connect pipeline and connect it to DB1.
Data Copying: Lakeflow Connect is an ingestion tool that physically replicates and copies data into Databricks-managed storage (Delta tables).
Storage Costs: It violates your requirement to keep data out of Databricks storage.
* You create a new native catalog in Unity Catalog.
Note:
To expose the external SQL Server database in Unity Catalog without copying the data, you must use Lakehouse Federation.
Here are the step-by-step actions you need to take:
1. Create a Connection
Create a securable object in Unity Catalog that specifies the path and credentials to access the SQL Server database.
Go to Catalog Explorer or use SQL.
Select External Data > Connections.
Create a connection using the SQL Server connection details (URL, host, port, and database credentials).
*-> 2. Create a Foreign Catalog
Create a specific type of catalog in Unity Catalog that mirrors the external database.
Use the CREATE FOREIGN CATALOG SQL command or the Catalog Explorer UI.
Link this foreign catalog directly to the connection you created in step 1.
3. Query the DataOnce the foreign catalog is created, Unity Catalog automatically syncs the schemas and tables from SQL Server.
Reference:
https://docs.databricks.com/gcp/en/database-objects/
NEW QUESTION # 96
......
You can choose the number of Implementing Data Engineering Solutions Using Azure Databricks (DP-750) questions and time frame of the DP-750 Desktop practice exam software as per your learning needs. Performance reports of Microsoft DP-750 Practice Test will be useful for tracking your progress and identifying areas for further study.
Questions DP-750 Exam: https://www.pass4sures.top/Microsoft-Certified-Fabric-Data-Engineer-Associate/DP-750-testking-braindumps.html
What's more, part of that Pass4sures DP-750 dumps now are free: https://drive.google.com/open?id=1cyj4hVD2lbDxFQ3eGNUTzV-dvOmyTnsU