BONUS!!! Download part of Exam4Tests Professional-Machine-Learning-Engineer dumps for free: https://drive.google.com/open?id=1jLRE8orojLIpQ-yHUAV4OauSFxRVZvzy
The former customers who bought Professional-Machine-Learning-Engineer training materials in our company all are impressed by the help as well as our after-sales services. That is true. We offer the most considerate after-sales services on our Professional-Machine-Learning-Engineer exam questions for you 24/7 with the help of patient staff and employees. They are all professional and enthusiastic to offer help. All the actions on our Professional-Machine-Learning-Engineer Study Guide aim to mitigate the loss of you and in contrast, help you get the desirable outcome.
| Section | Objectives |
|---|---|
| Topic 1: Data preparation and processing | - Data ingestion and pipelines
|
| Topic 2: ML pipeline automation and orchestration | - Pipeline design
|
| Topic 3: Designing ML solutions | - ML architecture design
|
| Topic 4: Deployment and operations | - Model deployment
|
| Topic 5: ML model development | - Model training and tuning
|
>> Test Google Professional-Machine-Learning-Engineer Simulator <<
The free demo Professional-Machine-Learning-Engineer practice question is available for instant download. Download the Google Professional-Machine-Learning-Engineer exam dumps demo free of cost and explores the top features of Google Professional-Machine-Learning-Engineer Exam Questions and if you feel that the Google Professional Machine Learning Engineer exam questions can be helpful in Professional-Machine-Learning-Engineer exam preparation then take your buying decision.
NEW QUESTION # 146
You have developed an application that uses a chain of multiple scikit-learn models to predict the optimal price for your company's products. The workflow logic is shown in the diagram Members of your team use the individual models in other solution workflows. You want to deploy this workflow while ensuring version control for each individual model and the overall workflow Your application needs to be able to scale down to zero. You want to minimize the compute resource utilization and the manual effort required to manage this solution. What should you do?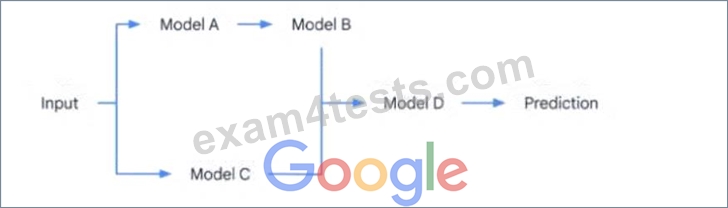
Answer: A
Explanation:
The option C is the most efficient and scalable solution for deploying a machine learning workflow with multiple models while ensuring version control and minimizing compute resource utilization. By exposing each model as an endpoint in Vertex AI Endpoints, it allows for easy versioning and management of individual models. Using Cloud Run to orchestrate the workflow ensures that the application can scale down to zero, thus minimizing resource utilization when not in use. Cloud Run is a service that allows you to run stateless containers on a fully managed environment or on Google Kubernetes Engine. You can use Cloud Run to invoke the endpoints of each model in the workflow and pass the data between them. You can also use Cloud Run to handle the input and output of the workflow and provide an HTTP interface for the application.
References:
* Vertex AI Endpoints documentation
* Cloud Run documentation
* Preparing for Google Cloud Certification: Machine Learning Engineer Professional Certificate
NEW QUESTION # 147
You are going to train a DNN regression model with Keras APIs using this code: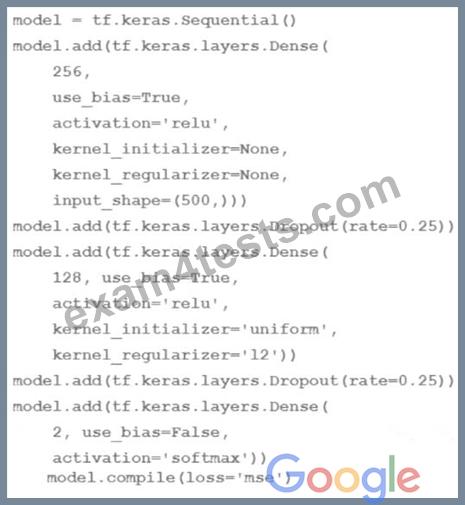
How many trainable weights does your model have? (The arithmetic below is correct.)
Answer: B
Explanation:
The number of trainable weights in a DNN regression model with Keras APIs can be calculated by multiplying the number of input units by the number of output units for each layer, and adding the number of bias units for each layer. The bias units are usually equal to the number of output units,except for the last layer, which does not have bias units if the activation function is softmax1. In this code, the model has three layers: a dense layer with 256 units and relu activation, a dropout layer with 0.25 rate, and a dense layer with 2 units and softmax activation. The input shape is 500. Therefore, the number of trainable weights is:
* For the first layer: 500 input units * 256 output units + 256 bias units = 128256
* For the second layer: The dropout layer does not have any trainable weights, as it only randomly sets some of the input units to zero to prevent overfitting2.
* For the third layer: 256 input units * 2 output units + 0 bias units = 512 The total number of trainable weights is 128256 + 512 = 161024. Therefore, the correct answer is B.
References:
* How to calculate the number of parameters for a Convolutional Neural Network?
* Dropout (keras.io)
NEW QUESTION # 148
You need to build an ML model for a social media application to predict whether a user's submitted profile photo meets the requirements. The application will inform the user if the picture meets the requirements. How should you build a model to ensure that the application does not falsely accept a non-compliant picture?
Answer: B
Explanation:
"Use AutoML to optimize the model's F1 score in order to balance the accuracy of false positives and false negatives", is the best approach to build an ML model that can predict whether a user's submitted profile photo meets the requirements while ensuring that the application does not falsely accept a non-compliant picture.
NEW QUESTION # 149
You have deployed a scikit-learn model to a Vertex Al endpoint using a custom model server. You enabled auto scaling; however, the deployed model fails to scale beyond one replica, which led to dropped requests.
You notice that CPU utilization remains low even during periods of high load. What should you do?
Answer: A
Explanation:
Auto scaling is a feature that allows you to automatically adjust the number of prediction nodes based on the traffic and load of your deployed model 1 . However, auto scaling depends on the CPU utilization of your prediction nodes, which is the percentage of CPU resources used by your model server 1 . If your CPU utilization is low, even during periods of high load, it means that your model server is not fully utilizing the available CPU resources, and thus au to scaling will not trigger more replicas 2 .
On e possible reason for low CPU utilization is that your model server is using a single worker process to handle prediction requests 3 . A worker process is a subprocess that runs your model code and handles prediction requests 3 . If you have only one worker process, it can only handle one request at a time, which can lead to dropped requests when the traffic is high 3 . To increase the CPU utilization and the throughput of your model server, you can increase the number of worker processes, which will allow your model server to handle multiple requests in parallel 3 .
To increase the number of workers i n your model server, you need to modify your custom model server code and use the --workers flag to specify the number of worker processes you want to use 3 . For example, if you are using a Gunicorn server, you can use the following command to start your model server with four worker processes:
gunicorn --bind :$PORT --workers 4 --threads 1 --timeout 60 main:app
By increasing the number of workers in your model server, you can increase the CPU utilization of your prediction nodes, and thus enable auto scaling to scale beyond one replica.
The other options are not suitable for your scenario, because they either do not address the root cause of low CPU utilization, such as attaching a GPU or scheduling scaling, or they do not enable auto scaling, such as increasing the minReplicaCount, which is a fixed number of nodes that will always run regardless of the traffi c 1 .
:
Scaling prediction nodes | Vertex AI | Google Cloud
Troubleshooting | Vertex AI | Google Cloud
Using a custom prediction routine with online prediction | Vertex AI | Google Cloud
NEW QUESTION # 150
You developed a Vertex Al pipeline that trains a classification model on data stored in a large BigQuery table. The pipeline has four steps, where each step is created by a Python function that uses the KubeFlow v2 API The components have the following names: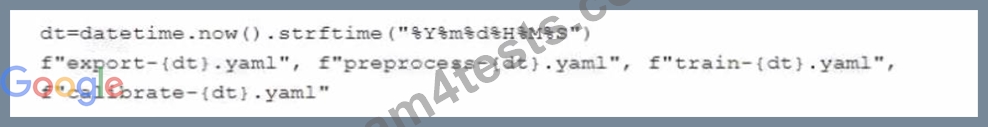
You launch your Vertex Al pipeline as the following: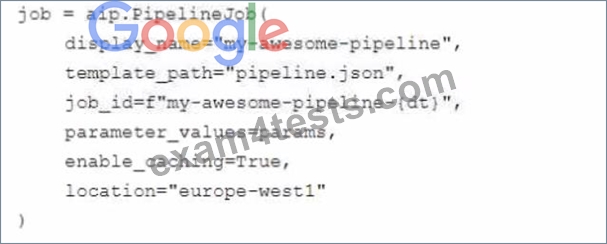
You perform many model iterations by adjusting the code and parameters of the training step. You observe high costs associated with the development, particularly the data export and preprocessing steps. You need to reduce model development costs. What should you do?




Answer: B
Explanation:
According to the official exam guide1, one of the skills assessed in the exam is to "automate and orchestrate ML pipelines using Cloud Composer". Vertex AI Pipelines2 is a service that allows you to orchestrate your ML workflows using Kubeflow Pipelines SDK v2 or TensorFlow Extended. Vertex AI Pipelines supports execution caching, which means that if you run a pipeline and it reaches a component that has already been run with the same inputs and parameters, the component does not run again. Instead, the component uses the output from the previous run. This can save you time and resources when you are iterating on your pipeline. Therefore, option A is the best way to reduce model development costs, as it enables execution caching for the data export and preprocessing steps, which are likely to be the same for each model iteration. The other options are not relevant or optimal for this scenario. Reference:
Professional ML Engineer Exam Guide
Vertex AI Pipelines
Google Professional Machine Learning Certification Exam 2023
Latest Google Professional Machine Learning Engineer Actual Free Exam Questions
NEW QUESTION # 151
......
Exam4Tests Google Professional-Machine-Learning-Engineer exam materials contain the complete unrestricted dump. So with it you can easily pass the exam. Exam4Tests Google Professional-Machine-Learning-Engineer exam training materials is a good guidance. It is the best training materials. You can use the questions and answers of Exam4Tests Google Professional-Machine-Learning-Engineer Exam Training materials to pass the exam.
Exam Professional-Machine-Learning-Engineer Cost: https://www.exam4tests.com/Professional-Machine-Learning-Engineer-valid-braindumps.html
DOWNLOAD the newest Exam4Tests Professional-Machine-Learning-Engineer PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1jLRE8orojLIpQ-yHUAV4OauSFxRVZvzy