BONUS!!! Pass4Test Databricks-Certified-Professional-Data-Engineer 시험 문제집 전체 버전을 무료로 다운로드하세요: https://drive.google.com/open?id=1MN0rrKj_Q-EiH23CHpI3u0SHFApp3478
Pass4Test의 인지도는 고객님께서 상상하는것보다 훨씬 높습니다.많은 분들이Pass4Test의 덤프공부가이드로 IT자격증 취득의 꿈을 이루었습니다. Pass4Test에서 출시한 Databricks인증 Databricks-Certified-Professional-Data-Engineer덤프는 IT인사들이 자격증 취득의 험난한 길에서 없어서는 안될중요한 존재입니다. Pass4Test의 Databricks인증 Databricks-Certified-Professional-Data-Engineer덤프를 한번 믿고 가보세요.시험불합격시 덤프비용은 환불해드리니 밑져봐야 본전 아니겠습니까?
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Data Modelling | 6% | - Delta Lake table design - Schema design and management - Medallion Architecture implementation |
| Topic 2: Data Sharing and Federation | 5% | - Cross-workspace and cross-cloud access - Unity Catalog data sharing |
| Topic 3: Data Transformation, Cleansing, and Quality | 10% | - Handling missing or inconsistent data - Standardization and normalization - Data validation and quality checks |
| Topic 4: Ensuring Data Security and Compliance | 10% | - Data encryption and masking - Access control and permissions - Compliance standards implementation |
| Topic 5: Developing Code for Data Processing using Python and SQL | 22% | - Batch and incremental processing logic - Data transformation and aggregation - Integration with Databricks APIs and tools |
| Topic 6: Debugging and Deploying | 10% | - CI/CD and DevOps practices - Troubleshooting pipelines and errors - Deployment using bundles, CLI, and APIs |
| Topic 7: Monitoring and Alerting | 10% | - Performance and health monitoring - Setting up alerts and notifications - Pipeline observability and logging |
| Topic 8: Data Ingestion & Acquisition | 7% | - Schema inference and evolution - Auto Loader and streaming ingestion - Connecting to diverse data sources |
| Topic 9: Cost & Performance Optimisation | 13% | - Cluster configuration and scaling - Storage optimization (partitioning, Z-order, indexing) - Query optimization and caching |
| Topic 10: Data Governance | 7% | - Data lineage and metadata tracking - Policy enforcement - Unity Catalog management |
>> Databricks-Certified-Professional-Data-Engineer최신 시험 최신 덤프자료 <<
목표가 있다면 목표를 향해 끊임없이 달려야 멋진 인생이 됩니다. 지금의 현황에 만족하여 아무런 노력도 하지 않는다면 언젠가는 치열한 경쟁을 이겨내지 못하게 될것입니다. IT업종에 종사중이시라면 다른분들이 모두 취득하는 자격증쯤은 마련해야 되지 않겠습니까? Databricks인증 Databricks-Certified-Professional-Data-Engineer시험은 요즘 가장 인기있는 자격증 시험의 한과목입니다. IT업계에서 살아남으려면Pass4Test에서Databricks인증 Databricks-Certified-Professional-Data-Engineer덤프를 마련하여 자격증에 도전하여 자기의 자리를 찾아보세요.
질문 # 179
A junior data engineer has been asked to develop a streaming data pipeline with a grouped aggregation using DataFrame df. The pipeline needs to calculate the average humidity and average temperature for each non- overlapping five-minute interval. Incremental state information should be maintained for 10 minutes for late- arriving data.
Streaming DataFrame df has the following schema:
"device_id INT, event_time TIMESTAMP, temp FLOAT, humidity FLOAT"
Code block: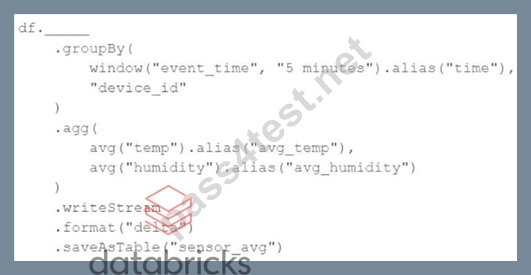
Choose the response that correctly fills in the blank within the code block to complete this task.
정답:D
설명:
The correct answer is A. withWatermark("event_time", "10 minutes"). This is because the question asks for incremental state information to be maintained for 10 minutes for late-arriving data. The withWatermark method is used to define the watermark for late data. The watermark is a timestamp column and a threshold that tells the system how long to wait for late data. In this case, the watermark is set to 10 minutes. The other options are incorrect because they are not valid methods or syntax for watermarking in Structured Streaming. References:
* Watermarking: https://docs.databricks.com/spark/latest/structured-streaming/watermarks.html
* Windowed aggregations: https://docs.databricks.com/spark/latest/structured-streaming/window- operations.html
질문 # 180
A data engineer is building a Lakeflow Declarative Pipelines pipeline to process healthcare claims data. A metadata JSON file defines data quality rules for multiple tables, including:
{
" claims " : [
{ " name " : " valid_patient_id " , " constraint " : " patient_id IS NOT NULL " },
{ " name " : " non_negative_amount " , " constraint " : " claim_amount > = 0 " }
]
}
The pipeline must dynamically apply these rules to the claims table without hardcoding the rules.
How should the data engineer achieve this?
정답:B
설명:
Lakeflow Declarative Pipelines provide the expect_all method for programmatically applying multiple data quality expectations at once. The documentation explains that @dlt.expect_all accepts a dictionary of expectation names mapped to SQL constraints, allowing rules to be dynamically loaded from metadata such as JSON files. This ensures that pipelines remain maintainable and scalable without needing to hardcode individual @dlt.expect decorators. The event logs will track each expectation's pass and fail counts individually, making it auditable. Other options are incorrect: invoking an external API introduces unnecessary complexity, individual decorators require hardcoding, and SQL constraints cannot dynamically reference external JSON.
질문 # 181
Which of the following Structured Streaming queries is performing a hop from a Bronze table to a Silver
table?
정답:A
질문 # 182
Which of the following is a correct statement on how the data is organized in the storage when when managing a DELTA table?
정답:D
설명:
Explanation
Answer is
All of the data is broken down into one or many parquet files, log files are broken down into one or many json files, and each transaction creates a new data file(s) and log file.
here is sample layout of how DELTA table might look,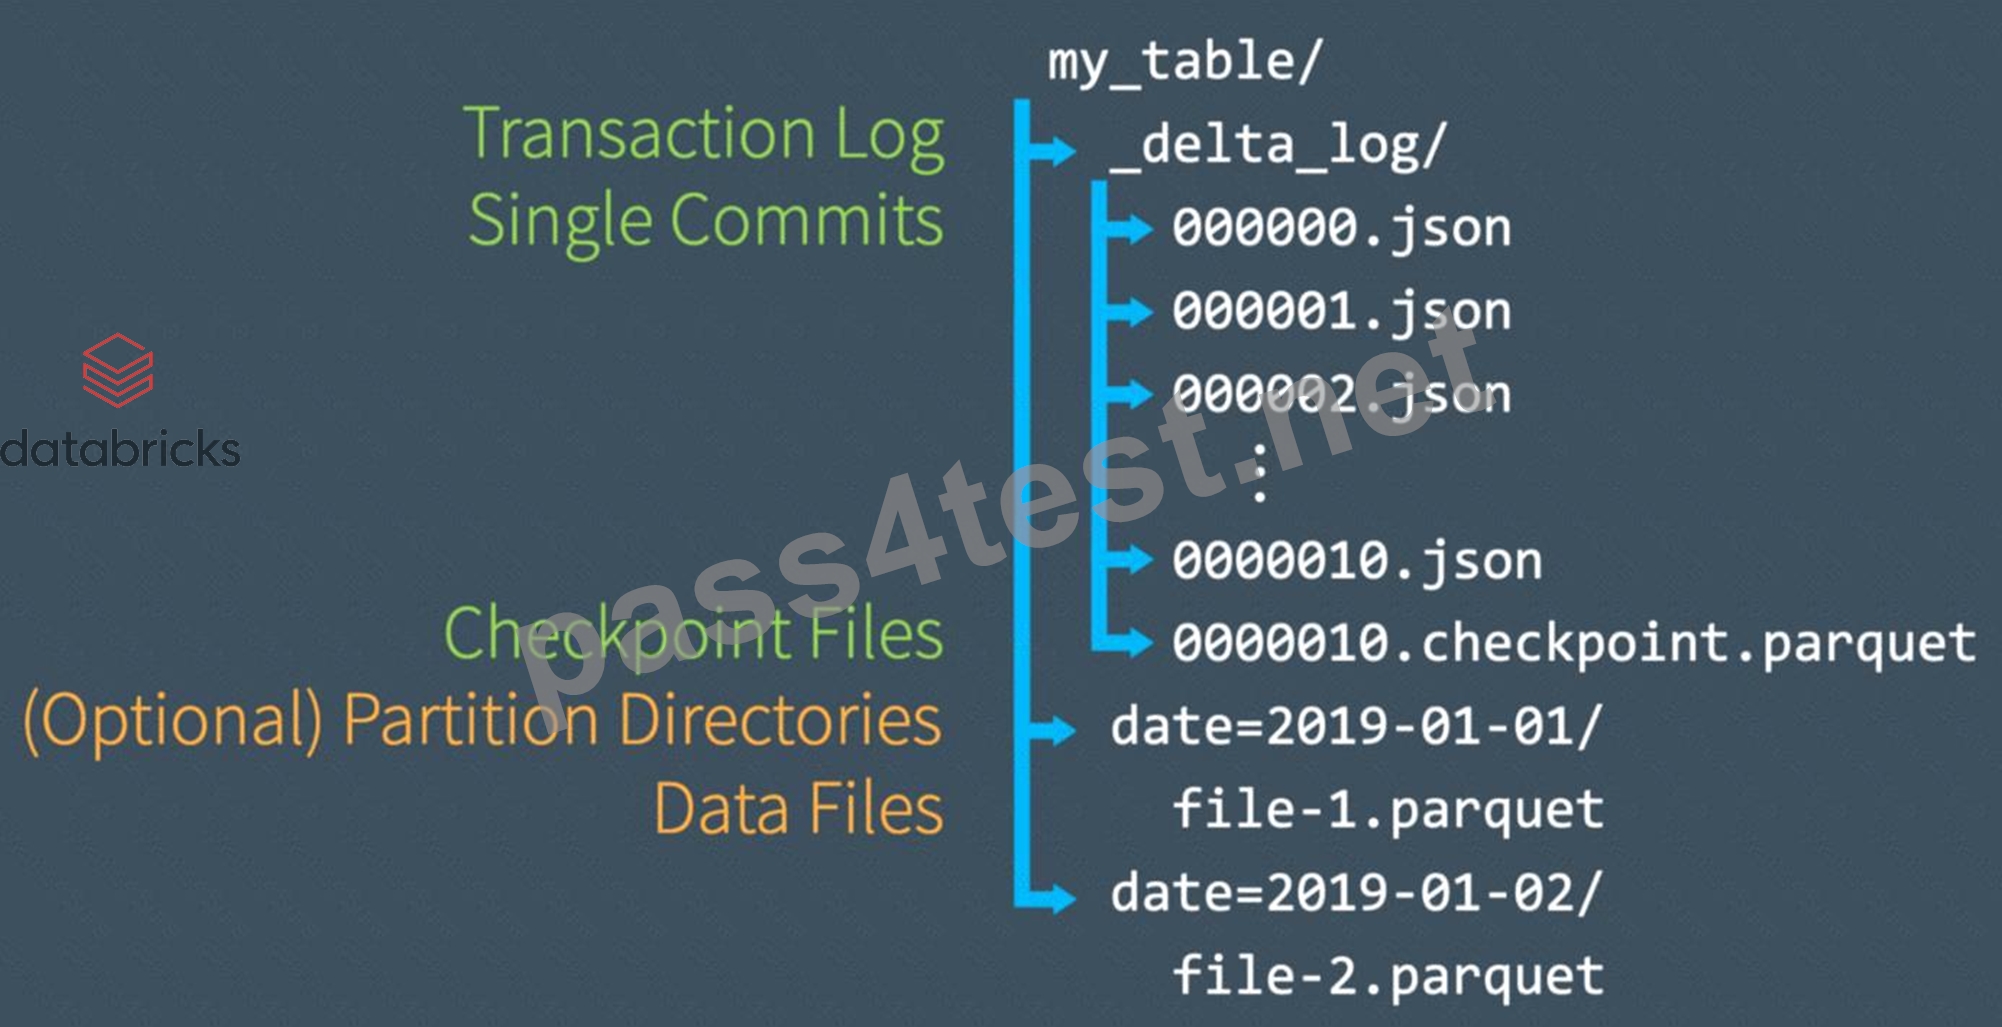
질문 # 183
A data engineer is configuring a Lakeflow Declarative Pipeline to process CDC (Change Data Capture) data from a source. The source events sometimes arrive out of order, and multiple updates may occur with the same update_timestamp but with different update_sequence_id.
What should the data engineer do to ensure events are sequenced correctly?
정답:C
설명:
Comprehensive and Detailed Explanation from Databricks Documentation:
When handling CDC data, sequencing is critical because updates may arrive out of order or multiple changes may occur for the same record at the same timestamp. Databricks' AUTO CDC APIs provide built-in constructs to handle ordering logic.
The correct mechanism is to use the SEQUENCE BY clause in the CDC configuration. Specifically, when both update_timestamp and update_sequence_id exist, the recommended approach is:
SEQUENCE BY STRUCT(event_timestamp, update_sequence_id)
This ensures that within the same record key, the engine applies updates in the exact sequence they occurred, resolving conflicts where multiple updates share the same timestamp but differ in sequence ID.
Option A (track_history_column_list) is used for historical tracking and auditing changes, not for sequencing logic. It ensures lineage but does not enforce correct event order.
Option B (dropDuplicates()) only removes exact duplicates; it cannot guarantee sequencing correctness when multiple updates exist.
Option C is correct: SEQUENCE BY STRUCT(event_timestamp, update_sequence_id) explicitly enforces ordering, as recommended by the CDC pipeline guidelines.
Option D (window function) would be a manual approach in Spark Structured Streaming, but Lakeflow Declarative Pipelines already provide native CDC sequencing support, making this unnecessary.
Thus, the best practice per Databricks CDC documentation is to use Option C with SEQUENCE BY STRUCT.
질문 # 184
......
Databricks Databricks-Certified-Professional-Data-Engineer 덤프로 많은 분들께서 Databricks Databricks-Certified-Professional-Data-Engineer시험을 패스하여 자격증을 취득하게 도와드렸지만 저희는 자만하지않고 항상 초심을 잊지않고 더욱더 퍼펙트한Databricks Databricks-Certified-Professional-Data-Engineer덤프를 만들기 위해 모든 심여를 기울일것을 약속드립니다.
Databricks-Certified-Professional-Data-Engineer시험합격덤프: https://www.pass4test.net/Databricks-Certified-Professional-Data-Engineer.html
2026 Pass4Test 최신 Databricks-Certified-Professional-Data-Engineer PDF 버전 시험 문제집과 Databricks-Certified-Professional-Data-Engineer 시험 문제 및 답변 무료 공유: https://drive.google.com/open?id=1MN0rrKj_Q-EiH23CHpI3u0SHFApp3478