
P.S. Free 2026 Amazon MLA-C01 dumps are available on Google Drive shared by Pass4sureCert: https://drive.google.com/open?id=1jjUobhkp_sbpULYHggCtzz-gGHqfUCoE
To improve our products’ quality we employ first-tier experts and professional staff and to ensure that all the clients can pass the test we devote a lot of efforts to compile the MLA-C01 learning guide. Even if you unfortunately fail in the test we won’t let you suffer the loss of the money and energy and we will return your money back at the first moment. After you pass the MLA-C01 test you will enjoy the benefits the certificate brings to you such as you will be promoted by your boss in a short time and your wage will surpass your colleagues. In short, buying the MLA-C01 exam guide deserves your money and energy spent on them.
| Certification Vendor: | Amazon Web Services (AWS) |
|---|---|
| Exam Name: | AWS Certified Machine Learning Engineer - Associate |
| Exam Number: | MLA-C01 |
| Passing Score: | 720 (scaled score 100–1000) |
| Exam Duration: | 130 minutes |
| Available Languages: | Korean, English, Simplified Chinese, Japanese |
| Related Certifications: | AWS Certified Machine Learning - Specialty AWS Certified AI Practitioner |
| Real Exam Qty: | 65 (50 scored, 15 unscored) |
| Certificate Validity Period: | 3 years |
| Exam Price: | 150 USD |
| Exam Format: | Ordering, Multiple choice, Case study, Matching, Multiple response |
| Recommended Training: | AWS Certified Machine Learning Engineer - Associate Official Exam Guide AWS Training and Certification |
| Exam Registration: | AWS Certification Portal Pearson VUE Registration |
| Sample Questions: | Amazon MLA-C01 Sample Questions |
| Exam Way: | Online proctored or onsite at Pearson VUE testing centers |
| Pre Condition: | Recommended: 1+ year hands-on experience with AWS services and machine learning engineering; familiarity with Amazon SageMaker and related ML services. No mandatory prerequisite exams. |
| Official Syllabus URL: | https://docs.aws.amazon.com/aws-certification/latest/machine-learning-engineer-associate-01/machine-learning-engineer-associate-01.html |
>> MLA-C01 Certification Test Answers <<
The exam time is coming, while you are not prepared well for MLA-C01 real test. Please do not be tense and worried, you can pass your MLA-C01 actual exam very simply and easily with Pass4sureCert MLA-C01 free pdf dumps. With the help of Amazon MLA-C01 free pdf practice, you can not only get high score in your actual test, but also can get more technology knowledge and be more professional.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
| Topic 4 |
|
NEW QUESTION # 95
An ML engineer is deploying a generative AI model-based customer support agent that uses Amazon SageMaker AI for inference. The customer support agent must respond to customer questions about topics such as shipping policies, refund processes, and account management. The generative AI model generates one token at a time.
Customers report dissatisfaction with how long the customer support agent takes to generate lengthy responses to questions. The ML engineer must apply an inference optimization technique to improve the performance of the customer support agent.
Which solution will meet this requirement?
Answer: C
Explanation:
Option B is correct because AWS documentation states that speculative decoding is specifically a technique to speed up the decoding process of large language models. The question highlights that the model generates one token at a time and that users are unhappy with the time needed to generate lengthy responses. That is exactly the stage of inference targeted by speculative decoding. AWS explains that this method improves latency without compromising the quality of the generated text.
According to AWS, speculative decoding works by using a smaller, faster draft model to generate candidate tokens first. The larger target model then verifies those tokens. AWS further explains that the draft model can generate multiple candidate tokens quickly, and the target model evaluates them in parallel, which speeds up the final response. This directly addresses the problem in the scenario: the customer support agent is slow not because of startup time, but because long answers require many decoding steps.
The other options are not the best fit. Compilation reduces deployment time and auto-scaling latency through ahead-of-time compilation, but AWS documents it primarily as helping model deployment and hardware optimization rather than token-by-token response generation. Quantization reduces hardware requirements and can lower cost, but the docs do not present it as the most direct answer to slow sequential decoding. Fast model loading improves how quickly the model loads onto instances, which helps startup and scale-out time, not long response generation after the model is already serving traffic. Therefore, the best AWS-documented answer is B.
NEW QUESTION # 96
A company has an ML model that generates text descriptions based on images that customers upload to the company's website. The images can be up to 50 MB in total size.
An ML engineer decides to store the images in an Amazon S3 bucket. The ML engineer must implement a processing solution that can scale to accommodate changes in demand.
Which solution will meet these requirements with the LEAST operational overhead?
Answer: A
NEW QUESTION # 97
An ML engineer develops a neural network model to predict whether customers will continue to subscribe to a service. The model performs well on training data. However, the accuracy of the model decreases significantly on evaluation data.
The ML engineer must resolve the model performance issue.
Which solution will meet this requirement?
Answer: B
Explanation:
This scenario clearly describes an overfitting problem. The neural network performs well on training data but fails to generalize to evaluation data. According to AWS Machine Learning and deep learning best practices, overfitting occurs when a model learns noise or overly specific patterns in the training data instead of generalizable relationships.
L1 and L2 regularization are well-established techniques to combat overfitting. They work by penalizing large weight values during optimization, effectively constraining the model's complexity. L1 regularization encourages sparsity, while L2 regularization (weight decay) smooths the weight distribution. AWS documentation recommends regularization as a primary method for improving generalization when a model shows a large gap between training and evaluation performance.
Option B is incorrect because removing dropout layers would increase overfitting, not reduce it. Dropout is itself a regularization technique.
Option C would likely worsen overfitting, as training for more epochs allows the model to memorize the training data even further.
Option D increases model complexity, which again exacerbates overfitting rather than resolving it.
Therefore, penalizing large weights using L1 or L2 regularization is the correct solution.
NEW QUESTION # 98
An ML engineer must choose the appropriate Amazon SageMaker algorithm to solve specific AI problems.
Select the correct SageMaker built-in algorithm from the following list for each use case. Each algorithm should be selected one time.
* Random Cut Forest (RCF) algorithm
* Semantic segmentation algorithm
* Sequence-to-Sequence (seq2seq) algorithm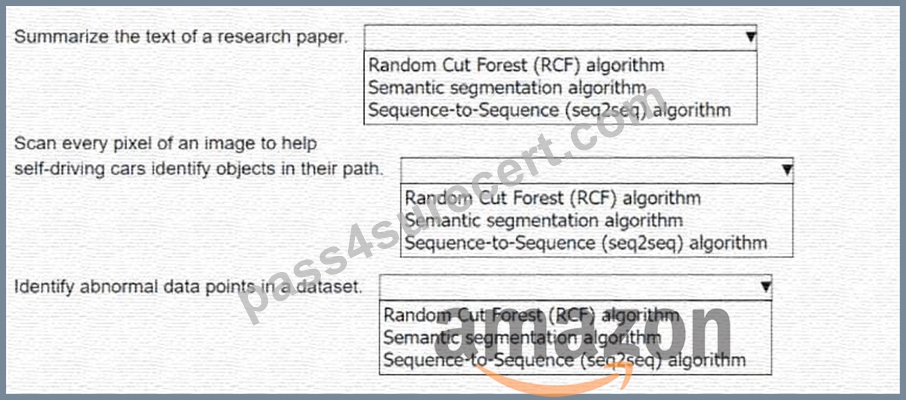
Answer:
Explanation: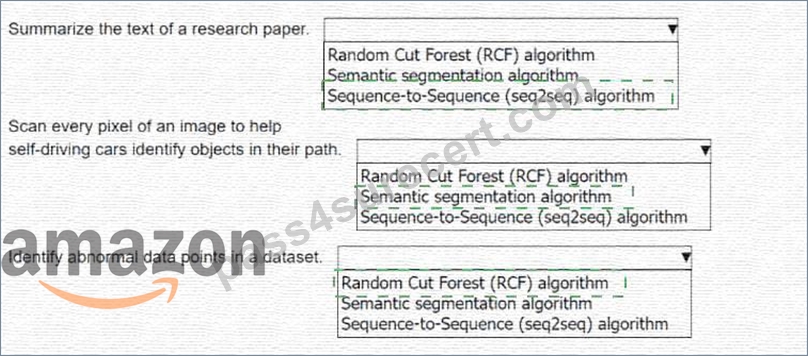
Explanation:
Use case 1:
Summarize the text of a research paper
## Sequence-to-Sequence (seq2seq) algorithm
Why:
Seq2seq models are designed for natural language generation tasks such as text summarization, translation, and paraphrasing. AWS documentation explicitly lists text summarization as a primary use case for the SageMaker seq2seq algorithm.
Use case 2:
Scan every pixel of an image to help self-driving cars identify objects in their path
## Semantic segmentation algorithm
Why:
Semantic segmentation performs pixel-level classification, assigning a class label to every pixel in an image.
This is exactly what is required for applications such as autonomous driving, road scene understanding, and object boundary detection.
Use case 3:
Identify abnormal data points in a dataset
## Random Cut Forest (RCF) algorithm
Why:
Random Cut Forest is an unsupervised anomaly detection algorithm. AWS SageMaker RCF is purpose-built to identify outliers, unusual patterns, and anomalies in numerical datasets, making it ideal for fraud detection, monitoring, and abnormal data point detection.
NEW QUESTION # 99
A company runs training jobs on Amazon SageMaker by using a compute optimized instance.
Demand for training runs will remain constant for the next 55 weeks. The instance needs to run for 35 hours each week. The company needs to reduce its model training costs.
Which solution will meet these requirements?
Answer: B
NEW QUESTION # 100
......
MLA-C01 Training Pdf: https://www.pass4surecert.com/Amazon/MLA-C01-practice-exam-dumps.html
P.S. Free & New MLA-C01 dumps are available on Google Drive shared by Pass4sureCert: https://drive.google.com/open?id=1jjUobhkp_sbpULYHggCtzz-gGHqfUCoE