Databricks Certified Data Engineer Associate Exam new practice materials & Databricks-Certified-Data-Engineer-Associate latest practice torrent & Databricks Certified Data Engineer Associate Exam pdf vce dumps

What's more, part of that PDFDumps Databricks-Certified-Data-Engineer-Associate dumps now are free: https://drive.google.com/open?id=1qeInvfcqq8j_wuJXBN_SeNdgbouhdHJh
It is the right time to think about your professional career. The right path is to enroll in Databricks Certified Data Engineer Associate Exam Databricks-Certified-Data-Engineer-Associate certification and start preparation with the assistance of Databricks Databricks-Certified-Data-Engineer-Associate PDF dumps and practice test software. The Databricks Databricks-Certified-Data-Engineer-Associate PDF Questions file and practice test software both are ready to download. Just pay an affordable Databricks Databricks-Certified-Data-Engineer-Associate exam dumps charge and download files and software.
| Section | Weight | Objectives |
|---|
| Productionizing Data Pipelines | 18% | - Monitoring and troubleshooting
- 1. Pipeline reliability and recovery
- 2. Logging and error handling
- Workflow orchestration
- 1. Scheduling, triggers, and dependencies
- 2. Lakeflow Jobs creation and management
- Deployment and CI/CD
- 1. Version control integration
- 2. Databricks Asset Bundles
|
| Data Processing & Transformations | 31% | - Query optimization and performance
- 1. Understanding query plans
- 2. Optimization strategies
- Data transformation techniques
- 1. Aggregations, joins, and window functions
- 2. DataFrame operations and transformations
- 3. Complex data processing logic
|
| Data Governance & Quality | 11% | - Unity Catalog implementation
- 1. Permissions and access control
- 2. Data governance model
- Data quality and reliability
- 1. Data validation and quality checks
- 2. Schema enforcement and evolution
|
| Development and Ingestion | 30% | - Notebook development fundamentals
- 1. Data exploration and validation
- 2. Using PySpark and Spark SQL
- Data ingestion patterns and methods
- 1. Connecting to external data sources
- 2. Batch and streaming ingestion
- 3. Delta Lake basics and usage
|
| Databricks Intelligence Platform | 10% | - Platform architecture and core concepts
- 1. Workspace navigation and management
- 2. Data layout and optimization: partitioning, file sizing, caching
- 3. Compute options: clusters, SQL warehouses, serverless
|
>> Databricks-Certified-Data-Engineer-Associate Online Training <<
Latest Databricks-Certified-Data-Engineer-Associate Test Preparation, Databricks-Certified-Data-Engineer-Associate Valid Exam Preparation
PDFDumps is an excellent platform where you get relevant, credible, and unique Databricks Databricks-Certified-Data-Engineer-Associate exam dumps designed according to the specified pattern, material, and format as suggested by the Databricks Databricks-Certified-Data-Engineer-Associate exam. To make the Databricks Databricks-Certified-Data-Engineer-Associate Exam Questions content up-to-date for free of cost up to 365 days after buying them, our certified trainers work strenuously to formulate the exam questions in compliance with the Databricks Databricks-Certified-Data-Engineer-Associate dumps.
Databricks Certified Data Engineer Associate Exam Sample Questions (Q287-Q292):
NEW QUESTION # 287
A data engineer must apply a daily batch of customer records to a Delta table so that existing customers are updated, new customers are inserted, and no duplicates are created.
Which statement accomplishes this in a single atomic operation?
- A. MERGE INTO customers t USING updates s ON t.customer_id = s.customer_id WHEN MATCHED THEN UPDATE SET * WHEN NOT MATCHED THEN INSERT *
- B. INSERT OVERWRITE TABLE customers SELECT * FROM updates
- C. INSERT INTO customers SELECT * FROM updates
- D. CREATE OR REPLACE TABLE customers AS SELECT * FROM updates
Answer: A
Explanation:
MERGE INTO performs upserts in a single ACID transaction, updating matched rows and inserting unmatched rows. INSERT INTO would create duplicates, and both INSERT OVERWRITE and CREATE OR REPLACE would discard existing records not present in the daily batch.
NEW QUESTION # 288
Which of the following is a benefit of the Databricks Lakehouse Platform embracing open source technologies?
- A. Avoiding vendor lock-in
- B. Ability to scale workloads
- C. Ability to scale storage
- D. Simplified governance
- E. Cloud-specific integrations
Answer: A
Explanation:
One of the benefits of the Databricks Lakehouse Platform embracing open source technologies is that it avoids vendor lock-in. This means that customers can use the same open source tools and frameworks across different cloud providers, and migrate their data and workloads without being tied to a specific vendor. The Databricks Lakehouse Platform is built on open source projects such as Apache Spark™, Delta Lake, MLflow, and Redash, which are widely used and trusted by millions of developers. By supporting these open source technologies, the DatabricksLakehouse Platform enables customers to leverage the innovation and community of the open source ecosystem, and avoid the risk of being locked into proprietary or closed solutions. The other options are either not related to open source technologies (A, B, C, D), or not benefits of the Databricks Lakehouse Platform (A, B). References: Databricks Documentation - Built on open source, Databricks Documentation - What is the Lakehouse Platform?, Databricks Blog - Introducing the Databricks Lakehouse Platform.
NEW QUESTION # 289
A data engineer wants to schedule their Databricks SQL dashboard to refresh once per day, but they only want the associated SQL endpoint to be running when it is necessary.
Which of the following approaches can the data engineer use to minimize the total running time of the SQL endpoint used in the refresh schedule of their dashboard?
- A. They can ensure the dashboard's SQL endpoint is not one of the included query's SQL endpoint.
- B. They can set up the dashboard's SQL endpoint to be serverless.
- C. They can turn on the Auto Stop feature for the SQL endpoint.
- D. They can reduce the cluster size of the SQL endpoint.
- E. They can ensure the dashboard's SQL endpoint matches each of the queries' SQL endpoints.
Answer: B
Explanation:
A serverless SQL endpoint is a compute resource that is automatically managed by Databricks and scales up or down based on the workload. A serverless SQL endpoint can be used to run queries and dashboards without requiring manual configuration or management. A serverless SQL endpoint is only active when it is needed and shuts down automatically when idle, minimizing the total running time and cost. A serverless SQL endpoint can be created and assigned to a dashboard using the Databricks SQL UI or the SQL Analytics API. References:
* Create a serverless SQL endpoint
* Assign a SQL endpoint to a dashboard
* SQL Analytics API
NEW QUESTION # 290
Which of the following describes when to use the CREATE STREAMING LIVE TABLE (formerly CREATE INCREMENTAL LIVE TABLE) syntax over the CREATE LIVE TABLE syntax when creating Delta Live Tables (DLT) tables using SQL?
- A. CREATE STREAMING LIVE TABLE should be used when data needs to be processed incrementally.
- B. CREATE STREAMING LIVE TABLE should be used when the previous step in the DLT pipeline is static.
- C. CREATE STREAMING LIVE TABLE should be used when data needs to be processed through complicated aggregations.
- D. CREATE STREAMING LIVE TABLE is redundant for DLT and it does not need to be used.
- E. CREATE STREAMING LIVE TABLE should be used when the subsequent step in the DLT pipeline is static.
Answer: A
Explanation:
A streaming live table or view processes data that has been added only since the last pipeline update.
Streaming tables and views are stateful; if the defining query changes, new data will be processed based on the new query and existing data is not recomputed. This is useful when data needs to be processed incrementally, such as when ingesting streaming data sources or performing incremental loads from batch data sources. A live table or view, on the other hand, may be entirely computed when possible to optimize computation resources and time. This is suitable when data needs to be processed in full, such as when performing complex transformations or aggregations that require scanning all the data. References: Difference between LIVE TABLE and STREAMING LIVE TABLE, CREATE STREAMING TABLE, Load data using streaming tables in Databricks SQL.
NEW QUESTION # 291
A data engineer has configured a Structured Streaming job to read from a table, manipulate the data, and then perform a streaming write into a new table.
The cade block used by the data engineer is below:
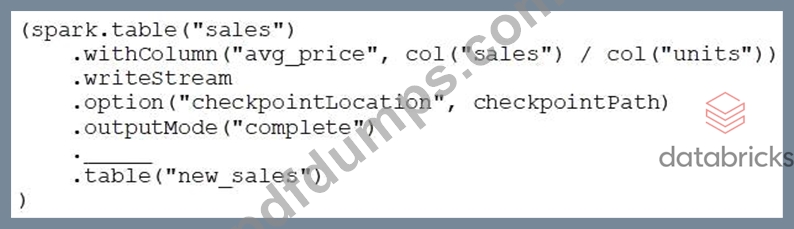
If the data engineer only wants the query to execute a micro-batch to process data every 5 seconds, which of the following lines of code should the data engineer use to fill in the blank?
- A. trigger(processingTime="5 seconds")
- B. trigger(once="5 seconds")
- C. trigger()
- D. trigger("5 seconds")
- E. trigger(continuous="5 seconds")
Answer: A
Explanation:
The processingTime option specifies a time-based trigger interval for fixed interval micro-batches. This means that the query will execute a micro-batch to process data every 5 seconds, regardless of how much data is available. This option is suitable for near-real time processing workloads that require low latency and consistent processing frequency. The other options are either invalid syntax (A, C), default behavior (B), or experimental feature (E). References: Databricks Documentation - Configure Structured Streaming trigger intervals, Databricks Documentation - Trigger.
NEW QUESTION # 292
......
The study system of our company will provide all customers with the best study materials. If you buy the Databricks-Certified-Data-Engineer-Associate study materials of our company, you will have the right to enjoy all the Databricks-Certified-Data-Engineer-Associate study materials from our company. More importantly, there are a lot of experts in our company; the first duty of these experts is to update the study system of our company day and night for all customers. By updating the study system of the Databricks-Certified-Data-Engineer-Associate study materials, we can guarantee that our company can provide the newest information about the exam for all people. We believe that getting the newest information about the exam will help all customers pass the Databricks-Certified-Data-Engineer-Associate Exam easily. If you purchase our study materials, you will have the opportunity to get the newest information about the Databricks-Certified-Data-Engineer-Associate exam. More importantly, the updating system of our company is free for all customers. It means that you can enjoy the updating system of our company for free.
Latest Databricks-Certified-Data-Engineer-Associate Test Preparation: https://www.pdfdumps.com/Databricks-Certified-Data-Engineer-Associate-valid-exam.html
- Databricks-Certified-Data-Engineer-Associate Online Training | Databricks Latest Databricks-Certified-Data-Engineer-Associate Test Preparation: Databricks Certified Data Engineer Associate Exam Latest Released 📇 Immediately open ⏩ www.practicevce.com ⏪ and search for ⏩ Databricks-Certified-Data-Engineer-Associate ⏪ to obtain a free download ⛪Databricks-Certified-Data-Engineer-Associate Examinations Actual Questions
- Practice Databricks-Certified-Data-Engineer-Associate Exams 👨 Databricks-Certified-Data-Engineer-Associate Latest Exam Forum 🎄 Databricks-Certified-Data-Engineer-Associate Simulated Test 🧃 Open ⇛ www.pdfvce.com ⇚ enter { Databricks-Certified-Data-Engineer-Associate } and obtain a free download 🧶Practice Databricks-Certified-Data-Engineer-Associate Exams Free
- In-Depth of Questions Databricks-Certified-Data-Engineer-Associate valuable resource 🧜 Search for { Databricks-Certified-Data-Engineer-Associate } and easily obtain a free download on ▛ www.pdfdumps.com ▟ 👭Databricks-Certified-Data-Engineer-Associate Valid Vce Dumps
- 100% Pass Quiz 2026 Professional Databricks Databricks-Certified-Data-Engineer-Associate: Databricks Certified Data Engineer Associate Exam Online Training 🧧 Search for ➤ Databricks-Certified-Data-Engineer-Associate ⮘ on ⮆ www.pdfvce.com ⮄ immediately to obtain a free download 🛣Exam Databricks-Certified-Data-Engineer-Associate Sample
- Databricks-Certified-Data-Engineer-Associate Actual Dumps 📋 Databricks-Certified-Data-Engineer-Associate Actual Dumps 🗯 Databricks-Certified-Data-Engineer-Associate Exam Registration 🌉 Easily obtain free download of ⏩ Databricks-Certified-Data-Engineer-Associate ⏪ by searching on ⇛ www.examcollectionpass.com ⇚ 💌New Databricks-Certified-Data-Engineer-Associate Test Bootcamp
- Databricks Databricks-Certified-Data-Engineer-Associate Practice Exams In Online Format 🏝 Search for [ Databricks-Certified-Data-Engineer-Associate ] and obtain a free download on 《 www.pdfvce.com 》 🥻Databricks-Certified-Data-Engineer-Associate Simulated Test
- Databricks-Certified-Data-Engineer-Associate Test Simulator Fee 🙆 Databricks-Certified-Data-Engineer-Associate Simulated Test 👛 Databricks-Certified-Data-Engineer-Associate Exam Registration 👾 Open ✔ www.vce4dumps.com ️✔️ enter 「 Databricks-Certified-Data-Engineer-Associate 」 and obtain a free download 🎈Databricks-Certified-Data-Engineer-Associate Valid Vce Dumps
- Databricks-Certified-Data-Engineer-Associate Latest Exam Forum ➰ Reliable Databricks-Certified-Data-Engineer-Associate Test Forum 🌭 Practice Databricks-Certified-Data-Engineer-Associate Exams Free 🔪 Search on ▶ www.pdfvce.com ◀ for ⏩ Databricks-Certified-Data-Engineer-Associate ⏪ to obtain exam materials for free download 🆎Databricks-Certified-Data-Engineer-Associate Simulated Test
- Latest Databricks-Certified-Data-Engineer-Associate Exam Questions Vce 🧒 Reliable Databricks-Certified-Data-Engineer-Associate Test Forum 🔋 Dumps Databricks-Certified-Data-Engineer-Associate Cost 📫 Open ( www.practicevce.com ) enter { Databricks-Certified-Data-Engineer-Associate } and obtain a free download 😜Practice Databricks-Certified-Data-Engineer-Associate Exams Free
- Databricks-Certified-Data-Engineer-Associate Latest Exam Book 🏀 Databricks-Certified-Data-Engineer-Associate Examinations Actual Questions ✡ Databricks-Certified-Data-Engineer-Associate Exam Registration 🦂 Immediately open ⮆ www.pdfvce.com ⮄ and search for 「 Databricks-Certified-Data-Engineer-Associate 」 to obtain a free download 📍Databricks-Certified-Data-Engineer-Associate Pdf Braindumps
- Reliable Databricks-Certified-Data-Engineer-Associate Test Forum 🔜 Reliable Databricks-Certified-Data-Engineer-Associate Test Forum 🕑 Databricks-Certified-Data-Engineer-Associate Pdf Braindumps 🤾 Easily obtain free download of ➡ Databricks-Certified-Data-Engineer-Associate ️⬅️ by searching on “ www.examcollectionpass.com ” ⏸Exam Databricks-Certified-Data-Engineer-Associate Sample
- www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes
DOWNLOAD the newest PDFDumps Databricks-Certified-Data-Engineer-Associate PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1qeInvfcqq8j_wuJXBN_SeNdgbouhdHJh