With ValidBraindumps's Microsoft DP-750 exam training materials, you can get the latest Microsoft DP-750 exam questions and answers. It can make you pass the Microsoft DP-750 exam. Microsoft DP-750 exam certification can help you to develop your career. ValidBraindumps's Microsoft DP-750 Exam Training materials is ensure that you fully understand the questions and issues behind the concept. t can help you pass the exam easily.
| Section | Weight | Objectives |
|---|---|---|
| Secure and govern data using Unity Catalog | 15-20% | - Data governance fundamentals
|
| Deploy and manage data pipelines and workloads | 30-35% | - Operational reliability
|
| Prepare and process data | 30-35% | - Data ingestion
|
| Configure and manage Azure Databricks environments | 15-20% | - Security and authentication setup
|
>> DP-750 Reliable Exam Question <<
Closed cars will not improve, and when we are reviewing our qualifying examinations, we should also pay attention to the overall layout of various qualifying examinations. For the convenience of users, our DP-750 learning materials will be timely updated information associated with the qualification of the home page, so users can reduce the time they spend on the Internet, blindly to find information. Our DP-750 Learning Materials get to the exam questions can help users in the first place, and what they care about the test information, can put more time in learning a new hot spot content.
NEW QUESTION # 57
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains two Delta tables named Table1 and Table2 of the same data type.
Table1 contains a column named Column1. Table2 contains a column named Column2.
You run the following query.
SELECT Colum1
FROM Table1
GROUP BY Column1
HAVING COUNT(*) > 1
INTERSECT
SELECT Column2
FROM Table2
GROUP BY Column2
HAVING COUNT(*) > 1;
What occurs when you run the query?
Answer: C
Explanation:
The query will output a single column containing only the values that are duplicated within Table1 and also duplicated within Table2.
Duplicates Isolated First: The GROUP BY and HAVING COUNT(*) > 1 clauses filter each table independently to find only their duplicate rows.
Matching Values Found: The INTERSECT operator compares the filtered results of both tables.
Shared Values Returned: Only values that exist in both filtered datasets are included in the final output.
Automatic Distinct Filtering: INTERSECT automatically removes any duplicate values from the final result set, ensuring each matching value appears exactly once.
Column Naming: The output column will inherit its name from the first SELECT statement (Column1).
Reference:
https://quizlet.com/study-guides/inf3707-chapter-4-data-retrieval-from-2-or-more-tables-
6ec17b26-76a8-4c33-8fa7-18d64154512d
NEW QUESTION # 58
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a Delta table named db1.sales_orders.
dbl sales_orders is updated nightly and has change data feed (CDF) enabled.
You need to ingest all the changes from the dbl.sales.ordets table, including inserts, updates, and deletes, into a downstream pipeline.
How should you complete the PsySpark code segment? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.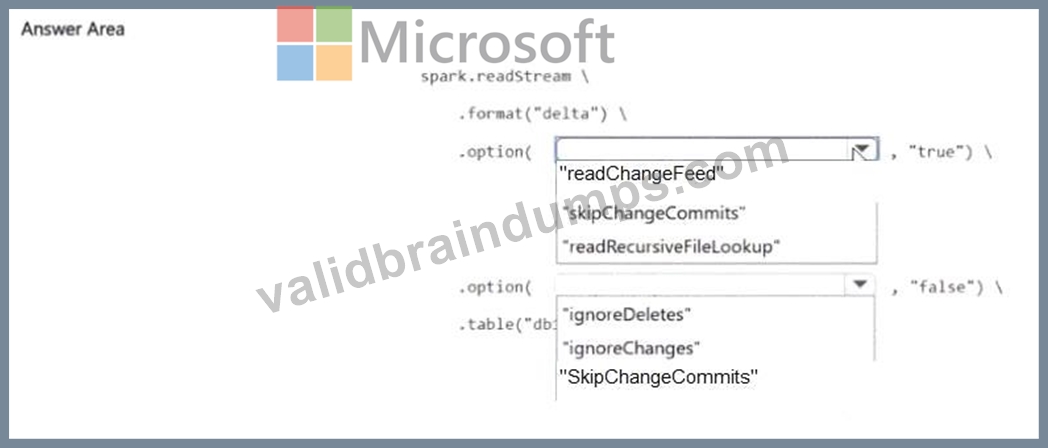
Answer:
Explanation: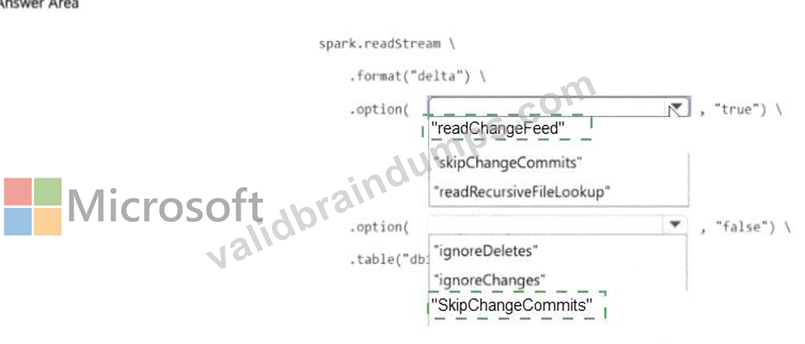
Explanation:
When Change Data Feed (CDF) is enabled on a Delta table, reading the full change stream - inserts, updates, and deletes - requires this pattern:
spark.readStream.format('delta').option('readChangeFeed', 'true').table('db1.sales_orders') The readChangeFeed option switches the reader from the default 'new rows only' mode to a mode that returns all change events. Each row in the resulting DataFrame includes a _change_type column (insert, update_preimage, update_postimage, delete) so downstream processing can distinguish what happened to each record.
Without readChangeFeed = true, streaming a Delta table only surfaces newly appended rows. Deletes and updates are invisible, making it unsuitable for true CDC pipelines. The stream also supports startingVersion or startingTimestamp options to begin from a specific point in table history rather than the current moment.
Reference: https://learn.microsoft.com/en-us/azure/databricks/delta/delta-change-data-feed
NEW QUESTION # 59
You need to configure resiliency for a job in Lakeflow Jobs named Job1 to meet the pipeline deployment and operation requirements.
What should you do?
Answer: B
Explanation:
Task-level retries allow the ingestion task to recover automatically from transient failures without rerunning unrelated tasks or restarting the complete workflow. Downstream tasks remain governed by their dependencies and start only after ingestion succeeds. This provides focused failure recovery and reduces unnecessary compute consumption. Disabling retries and relying on manual execution directly contradicts the requirement for resilient, automated pipeline operation. Setting the retry count to zero also prevents automatic retry behavior. Restarting the workflow from the first task whenever any task fails would repeat completed processing, increase costs, and potentially reingest data unnecessarily. Lakeflow Jobs supports individual retry policies for tasks, including the number of retries and delay between attempts, making option D the most controlled and operationally efficient configuration. Microsoft Learn
NEW QUESTION # 60
You have an Azure Databricks workspace named Workspace! that uses a Git repository. The repository contains a Databricks notebook named Notebook1.
From the main branch, you create a feature branch named Branch! and commit changes to Notebooks Another user commits changes to Notebook1 in main.
When you attempt to merge Branch! into main, the merge fails due to conflicts.
You need to merge Branch! into the main branch. The solution must ensure that Notebook1 includes all the changes from both the branches.
What should you do?
Answer: A
Explanation:
The correct answer is D - apply the main branch changes to Branch1 and resolve the conflicts.
When a merge fails due to conflicts, the right workflow is to bring main's changes into the feature branch, resolve conflicts there, and then merge the clean feature branch into main. This is the standard Git conflict resolution pattern - resolve in the feature branch, not in main - because it protects the main branch from partial or broken states during resolution.
Option A (clone Branch1 as a new repository) creates a disconnected copy; it doesn't resolve the conflict and breaks the relationship with the remote. Option B (apply changes directly to main) bypasses the feature branch entirely and risks overwriting the other developer's work. Option C (clone main as a new repository) again creates a disconnected copy - none of Branch1's changes would be incorporated, and history would be lost.
Reference: https://learn.microsoft.com/en-us/azure/databricks/repos/git-operations-with-repos
NEW QUESTION # 61
You have an Azure Databricks workspace that is enabled for Unity Catalog.
You need to recommend a pipeline that ingests files from cloud storage, performs cleansing and enrichment transformations, and writes created Delta tables for analytics. The solution must minimize development effort and provide built-in monitoring and automatic retries.
What should you include in the recommendation?
Answer: B
Explanation:
The correct answer is C - a Lakeflow Spark Declarative Pipelines (SDP) pipeline.
SDP is tailor-made for exactly this pattern: ingest from cloud storage, transform through cleansing and enrichment stages, and publish Delta tables to Unity Catalog. What sets it apart from the other options is built- in monitoring (the pipeline graph shows row counts, expectation metrics, and run history) and automatic retries (failed tasks retry automatically based on pipeline settings, without manual re-run triggers).
Option A (Structured Streaming job) gives you the streaming engine but nothing else - monitoring, alerting, and retry logic all have to be built from scratch. Option B (scheduled notebook job) is a batch approach that requires manual monitoring and lacks the declarative lineage tracking SDP provides. Option D (Azure Data Factory with data flows) works but adds a separate Azure service to manage, introduces ADF licensing costs, and doesn't integrate natively with Unity Catalog governance.
Reference: https://learn.microsoft.com/en-us/azure/databricks/delta-live-tables/what-is-delta-live-tables
NEW QUESTION # 62
......
As the captioned description said, our DP-750 practice materials are filled with the newest points of knowledge about the exam. With many years of experience in this line, we not only compile real test content into our DP-750 practice materials, but the newest in to them. Allowing for there is a steady and growing demand for our DP-750 practice materials with high quality at moderate prices, we never stop the pace of doing better. All newly supplementary updates will be sent to your mailbox one year long. And we shall appreciate it if you choose any version of our DP-750 practice materials for exam and related tests in the future.
DP-750 Answers Real Questions: https://www.validbraindumps.com/DP-750-exam-prep.html