如果你選擇了KaoGuTi的幫助,我們一定不遺餘力地幫助你通過考試。而且我們還會為你提供一年的免費的更新考試練習題和答案的售後服務。不用再猶豫了!請選擇KaoGuTi,它將會是你通過AI-500認證考試的最好保證。快將KaoGuTi加入你的購物車吧!
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Evaluate, optimize, and monitor multi-agent solutions | 20-25% | - Optimize prompt and model performance
|
| Topic 2: Secure, govern, and deploy multi-agent solutions | 20-25% | - Design and implement security for multi-agent solutions
|
| Topic 3: Architect multi-agent solutions | 15-20% | - Design logical architecture for multi-agent solutions
|
| Topic 4: Develop multi-agent solutions in Azure | 30-35% | - Implement multi-agent orchestration
|
每個IT人士都在努力,不是為了升職就是為了加薪,這也是現代社會所形成的壓力的一種體現。這樣討得上司的喜歡,還不如用實力說話。大家來通過Microsoft的AI-500考試認證吧,其實這個考試也沒有想像的那麼苦難,只需要你選擇合適的培訓資料就足夠,KaoGuTi Microsoft的AI-500考試培訓資料將是最好的培訓資料,選擇了它你就是選擇你最想要的,為了現實,趕緊行動吧。
問題 #48
You have a Microsoft Foundry agent that completes benefits enrollment during a single user conversation The agent collects the required enrollment fields during 15 turns. Users can correct earlier values before final submission. The current implementation sends the complete transcript with every model request.
You need to change the context accumulation strategy for the active enrollment. The solution must meet the following requirements:
* Preserve the latest value for each required enrollment field until submission.
* Bound the maximum number of tokens sent with each model request
* Preserve user corrections until submission.
* Prevent durable cross-session memory.
What should you do?
答案:C
解題說明:
The application must preserve the latest authoritative value of each enrollment field even when the user corrects an earlier value, while also placing a firm bound on prompt size. A session-scoped enrollment-state snapshot provides deterministic structured state: each correction overwrites the previous field value. A recent- turn sliding window then preserves enough conversational context for natural interaction without resending the full 15-turn transcript. Response chaining with a fixed number of prior turns can lose an important field once it falls outside the retained history. Summarization can omit or distort corrected values, and automatic truncation likewise offers no guarantee that the latest value of every required field survives. Because the state is scoped only to the active enrollment and is not written to long-term memory, the design also avoids durable cross-session memory. Therefore A is correct. At implementation time, the same rule should be expressed through the framework or service configuration rather than left only as a natural-language convention. That makes the behavior repeatable across runs, easier to test, and less sensitive to model variability.
Official Microsoft reference: Microsoft Agent Framework - workflow state and context management
問題 #49
You have a Microsoft Foundry multi-agent assistant that uses a Retrieval-Augmented Generation (RAG)- enabled workflow. A retrieval agent returns document chunks to an answer agent, and the answer agent produces the final response.
You have a dataset that contains query, context, and response without document relevance labels.
You need to implement built-in RAG evaluators that meet the following requirements:
* Identify final responses that include content that is NOT supported by the retrieved context.
* Assess whether the retrieved context chunks and final responses support the user query.
Which evaluator should you use for each requirement? To answer, drag the appropriate evaluators to the correct requirements. Each evaluator may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.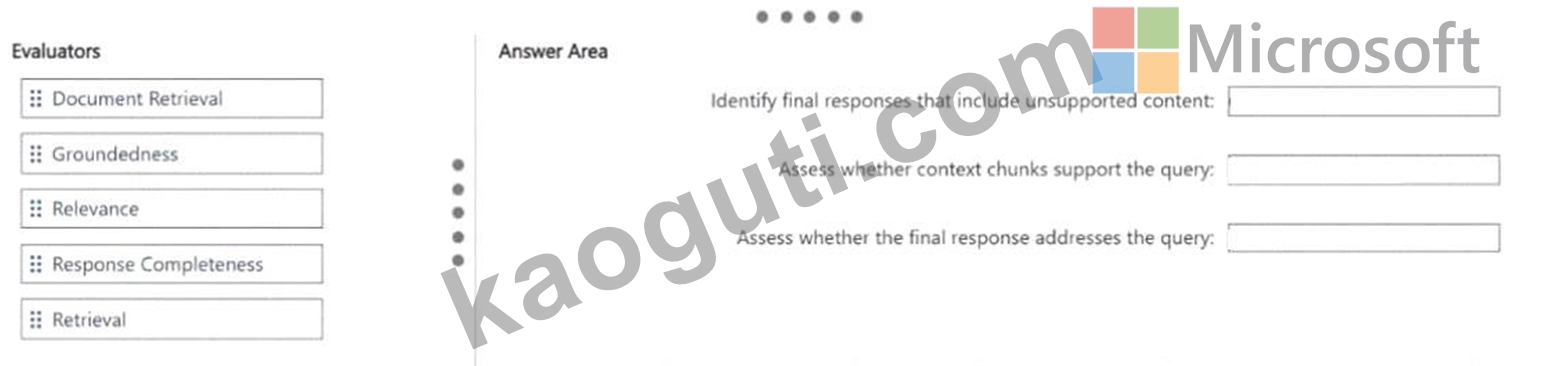
答案:
解題說明: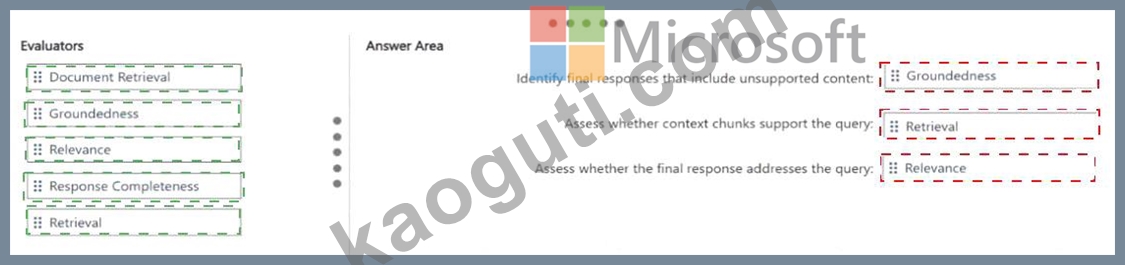
Explanation:
Unsupported final-response content: Groundedness; Context support for the query: Retrieval; Final- response support for the query: Relevance.
Groundedness detects whether the generated response contains claims that are not supported by the retrieved context, which directly matches the first requirement. Retrieval evaluates how relevant the provided context chunks are to the query when no document relevance ground truth is available. Relevance evaluates whether the final response directly and adequately answers the query. Microsoft Foundry separates these metrics so teams can diagnose whether a poor RAG result originated in retrieval or generation. Document Retrieval would require labeled retrieval ground truth, which the question explicitly says is absent. Response Completeness likewise depends on expected/ground-truth information. The supplied Groundedness, Retrieval, and Relevance mapping therefore matches the documented evaluator inputs and purposes. A robust evaluation program separates process metrics from final-response metrics. The selected answer measures the layer where the stated failure actually occurs, which is essential for deciding whether to change retrieval, orchestration, prompt behavior, or the final generator. For operational use, the measurement should be captured in a repeatable dataset, trace, or automated gate so that the same criterion can be compared across versions. That is more useful than a one-off manual observation and makes regressions visible before they become production incidents.
Official Microsoft reference: Microsoft Foundry - RAG evaluators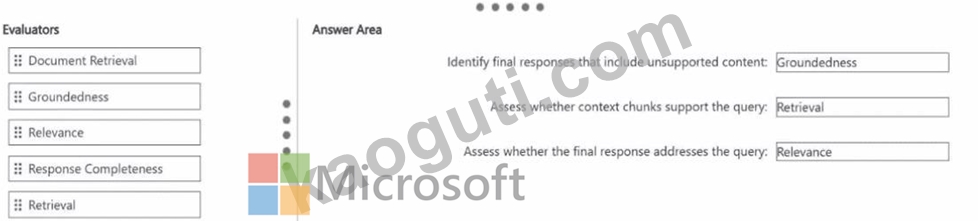
問題 #50
You need to recommend a knowledge integration design for a Microsoft Foundry multi-agent solution. The agents answer questions by using shared documentation. The solution must meet the following requirements:
* Updates must be available from a single maintained knowledge layer.
* Retrieval responses must include citations and query details
* Content must support natural-language queries.
Users will ask the agents complex conversational questions. The questions will include follow-up context and terminology that does NOT always match the wording in the documentation.
Which knowledge type should you recommend?
答案:B
解題說明:
Azure AI Search is the best fit for a centrally maintained documentation layer that must support natural- language retrieval, citations, and query details. Azure AI Search can combine keyword, vector, hybrid, and semantic retrieval so user terminology does not need to match the source wording exactly. It also supports agentic retrieval/knowledge-base patterns that decompose complex conversational questions and return references suitable for grounded citations. A raw File source does not provide the same managed retrieval and ranking capabilities. Work IQ is oriented toward Microsoft 365 work context such as people, mail, meetings, and files, while Fabric IQ focuses on semantic business data in Fabric/OneLake. For a shared documentation corpus with conversational follow-ups and terminology variation, an Azure AI Search index provides the required maintained retrieval layer and observability into the query process. In production, add telemetry and regression tests around this behavior so changes to prompts, models, tools, or orchestration do not silently alter the intended contract. The selected approach is the one that best matches the platform ' s native execution semantics.
Official Microsoft reference: Azure AI Search - agentic retrieval
問題 #51
You are designing a multitenant software as a service (SaaS) platform that uses multiple agents. Users will send latency-sensitive inference requests to the platform by using a shared API.
Initially, there will be 20 tenants, and the platform will expand to 200 tenants.
You need to identify the compute component for a production agent runtime. The solution must meet the following requirements:
Isolate workloads for each tenant by using containerization.
Dynamically scale based on demand.
Minimize administrative effort.
What should you use?
答案:A
解題說明:
Microsoft Foundry Agent Service is the managed option that best satisfies containerized production agent execution, dynamic scaling, and low administrative overhead. Hosted agents run in Foundry-managed container compute and scale according to workload demand while the platform manages much of the runtime, endpoint, identity, and operational plumbing. AKS could provide strong tenant/workload isolation and autoscaling, but it also requires Kubernetes cluster operations, policy, upgrades, node pools, and scaling configuration, which conflicts with the requirement to minimize administration as the tenant count grows.
Azure Container Instances is simpler but lacks the same managed autoscaling model, and GPU virtual machines create the highest infrastructure burden. Therefore C is the strongest fit for a SaaS platform that wants production agent compute without owning the orchestration platform. From an architecture perspective, the selection also creates explicit ownership and boundaries that can be tested independently. That matters in multi-agent systems because implicit sharing or loosely defined authority often becomes the source of cross- agent coupling, security drift, and difficult incident diagnosis.
Official Microsoft reference: Microsoft Foundry Agent Service overview
問題 #52
You have a Microsoft Foundry claims-assistance solution that includes a primary claims agent and three specialist agents. The primary claims agent invokes the specialist agents.
You need to recommend a coordination approach. The solution must meet the following requirements:
* The primary claims agent must retain ownership of the task and synthesize the final response.
* The specialist agents must have a least-privilege view of the claim for their assigned work.
What should you recommend? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.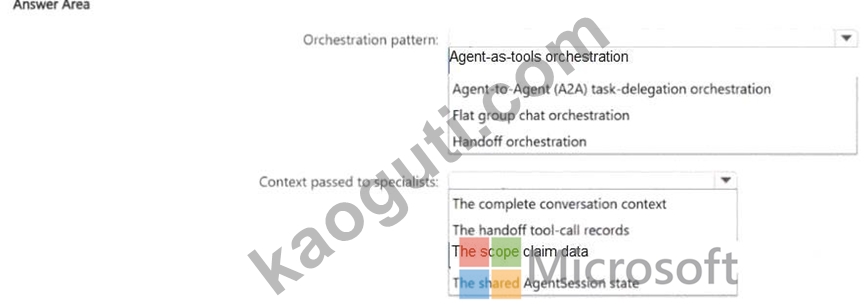
答案:
解題說明: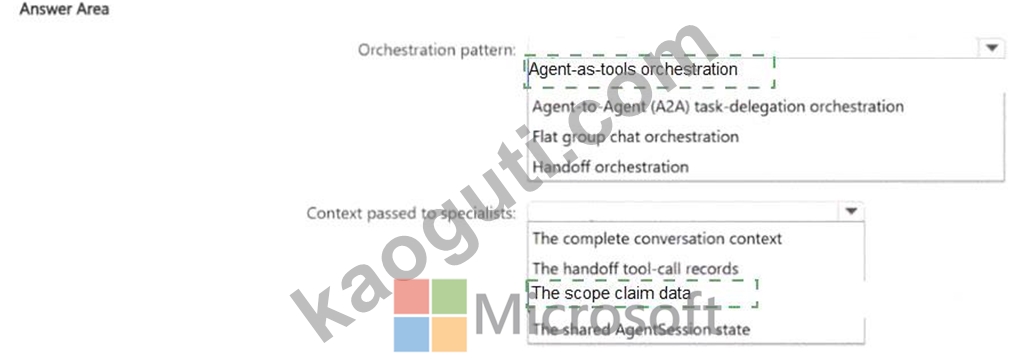
Explanation:
Orchestration pattern: Agent-as-tools; Context passed to specialists: Scoped claim data only.
The primary claims agent must retain task ownership and synthesize the final response, which is the defining property of the agents-as-tools pattern. The primary agent decides when to invoke each specialist, receives the specialist ' s result, and remains responsible for the overall conversation. Handoff orchestration would instead transfer control to another agent and therefore weaken the ownership requirement. Microsoft Agent Framework also makes it possible for the outer agent to pass only the arguments needed by the inner agent rather than sharing the entire conversation history automatically. That supports least-privilege context: each specialist receives only the claim fields required for its assigned work. Passing the whole claim or a shared transcript would unnecessarily expose data outside the specialist ' s domain. The selected combination therefore satisfies both control ownership and data minimization. The architecture should still be validated with representative end-to-end tests, but the selected component establishes the correct structural boundary first. Microsoft ' s AI-500 blueprint consistently favors explicit scopes, interfaces, and persistence or identity boundaries over prompt-only conventions.
Official Microsoft reference: Microsoft Agent Framework - Agents as tools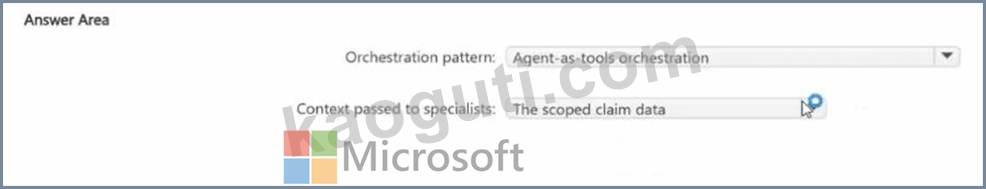
問題 #53
......
目前Microsoft的AI-500認證考試真的是一門人氣很高的考試。還沒有取得這個考試的認證資格的你,是不是也想參加考試呢?確實,這是一門很難的考試。但是這並不代表不能獲得高分輕鬆通過考試。那麼,還不知道通過這個考試的捷徑在哪里的你,是不是想知道通過考試的技巧呢?現在我來告訴你,就是利用KaoGuTi的AI-500考古題。
免費下載AI-500考題: https://www.kaoguti.com/AI-500_exam-pdf.html