Purchasing our SPS-C01 training test is not complicated, there are mainly four steps: first, you can choose corresponding version according to the needs you like. Next, you need to fill in the correct email address. And if the user changes the email during the subsequent release, you need to update the email. Then, the user needs to enter the payment page of the SPS-C01 Learning Materials to buy it. Finally, within ten minutes of payment, the system automatically sends the SPS-C01 study materials to the user's email address. And then you can quickly study and pass the SPS-C01 exam.
| Section | Weight | Objectives |
|---|---|---|
| Data Transformations and DataFrame Operations | 35% | - Complex data pipelines - Filtering, Aggregating, and Joining DataFrames - Using built-in functions - Persisting transformed data - Window functions |
| Snowpark API for Python | 30% | - Establishing connections and session management - User-Defined Functions (UDFs) and Stored Procedures - Reading and writing data - Working with Semi-structured data - DataFrame creation and manipulation |
| Performance Optimization and Best Practices | 20% | - Query pushdown and optimization - Caching strategies - Vectorized UDFs - Warehouse sizing for Snowpark - Debugging and explain plans - Minimizing data transfer |
| Snowpark Concepts | 15% | - Snowpark Sessions and connection management - Snowpark DataFrames and query plans - Transformations vs. Actions - Stored procedures and conditional logic - Snowpark architecture and core concepts - Client-side vs. Server-side execution |
SPS-C01 certification has great effect in this field and may affect your career even future. SPS-C01 real questions files are professional and high passing rate so that users can pass the exam at the first attempt. High quality and pass rate make us famous and growing faster and faster. Many candidates compliment that SPS-C01 Study Guide materials are best assistant and useful for qualification exams, they have no need to purchase other training courses or books to study, and only by practicing our SPS-C01 Snowflake Certification exam braindumps several times before exam, they can pass exam in short time easily.
NEW QUESTION # 139
You are working with a Snowpark DataFrame that contains product information including 'product_name' and 'description'. You need to create a new column named 'search_terms' that contains the first three words from the 'description' column, converted to lowercase. If the description has fewer than three words, the 'search_terms' column should contain all the words available. The words should be separated by a space. What is the MOST efficient way to achieve this using Snowpark?





Answer: C
Explanation:
Using a UDF (Option C) is a valid approach, but generally less efficient than leveraging built-in functions or existing Snowflake functions, especially for large datasets, because it involves serialization and deserialization between Python and Snowflake. Option A is not dynamic and will error on strings with fewer than three words. Option D will only correctly return the words if there are exactly three, otherwise it won 't match. E will just return the lowercased string and Snowflake UDF defined in SQL. Snowflake UDFs overhead, and are preferable for performance It is also less efficient than a UDF/Stored proc as it involves calling the Regex. Option is incorrect. Option B (UDF) is the most efficient, assuming GET FIRST THREE_WORDS is a are optimized for execution within the Snowflake environment, minimizing data transfer compared to Python UDFs in Snowpark.
NEW QUESTION # 140
You're building a Snowpark Python application that processes sensor data from various devices. The data arrives as a stream of JSON objects, each containing the device ID, timestamp, and sensor readings. You want to use a Streamlit application to visualize near real- time aggregates on the data'. You're aiming to create a Snowpark DataFrame from this data, perform transformations, and then serve this DataFrame to Streamlit. Which of the following approaches concerning creating the initial DataFrame from JSON data is generally the MOST efficient and scalable for handling such a stream of data?
Answer: C
Explanation:
Using Snowflake's Kafka connector (or a similar streaming ingestion service) is the most efficient and scalable way to handle streaming data. It allows for near real-time ingestion and avoids intermediate steps like writing to temporary files or using Pandas DataFrames. Using Snowpipe with auto-ingest is also a valid approach, however Kafka connector is slightly better suited for streaming data because of its real time data processing. Kafka is also a common real time streaming platform. Therefore, option C is the best answer. Other options may encounter scalability and performance issues with high-volume, continuous data streams.
NEW QUESTION # 141
You are tasked with building a data pipeline that uses Snowpark to process customer data in a table called 'CUSTOMERS'. The table contains sensitive information, and you need to ensure that any Personally Identifiable Information (PII) is removed from the table after 30 days. You decide to implement a mechanism to automatically delete records older than 30 days. Which of the following approaches would you consider when designing the deletion process with consideration of cost, performance and security?
Answer: A,B,E
Explanation:
Options B, C and E are viable and have tradeoffs. A and D will be less ideal. Option A : This approach can be very inefficient as it requires scanning the entire table daily to identify records for deletion. This can lead to high costs and performance issues. Option B : Using a Snowflake Task with a direct SQL DELETE statement is generally more efficient than reading the entire table in Snowpark, especially for large tables. Snowflake can optimize the DELETE operation internally. Option C : Encapsulating the deletion logic in a Snowpark Stored Procedure and scheduling it with a Snowflake Task allows you to leverage Snowpark's capabilities while benefiting from Snowflake's task scheduling and optimization. This can offer a good balance of flexibility and performance. Option D : This is an archive solution, not deletion; it's not as fast or space saving as truncating. Option E : Data masking is a secure alternative. It preserves the records while redacting sensitive data. No need to scan for old records, so its best on performance, cost, and security.
NEW QUESTION # 142
You have a Snowpark DataFrame 'df sales' containing sales data with columns like 'order id', 'product id', 'quantity', and 'sale_price' You want to persist this data into a Snowflake table named "SALES DATA'. You also want to create a dynamic table on top of this base table for faster analytics. You need to choose the appropriate persistence strategy and consider the implications of using a dynamic table. Which of the following options represents the BEST approach?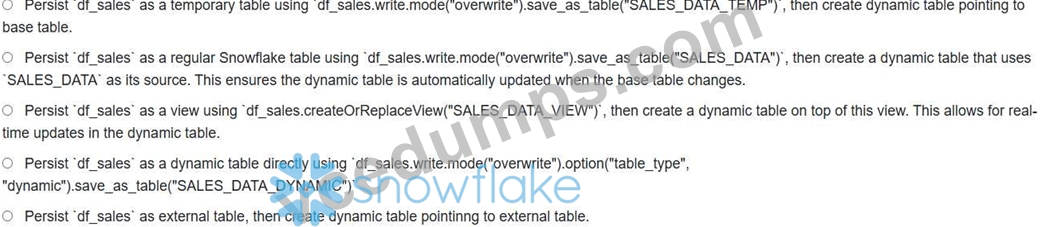
Answer: E
Explanation:
Option B is the best approach because it combines the advantages of persistence with the benefits of dynamic tables. Regular Table Persistence: Persisting as a regular table using DATA") ensures the data is stored durably in Snowflake. This serves as the foundation for the dynamic table. Dynamic Table Creation: Creating a dynamic table that uses 'SALES DATA' as its source provides a materialized view that automatically updates when the base table changes. This allows for faster analytics as the data is pre-computed and optimized for querying. Avoidance of Temporary Tables: Option A uses a temporary table, which is not suitable for long-term storage or scenarios where the data needs to persist beyond the session. Views vs. Dynamic Tables: Option C uses a view, which is not materialized. While views provide real-time access to the data, they can be slower for complex queries compared to dynamic tables. Option D isn't correct as 'table_type' is not a valid option for in Snowpark. Option E isnt valid scenario
NEW QUESTION # 143
A data scientist is developing a Snowpark application that needs to authenticate to Snowflake using Key Pair Authentication. Which of the following steps are essential for configuring the Snowflake CLI to enable Key Pair Authentication and then correctly create a Snowpark session? (Select TWO)
Answer: A,B
Explanation:
Key Pair Authentication requires generating an RSA key pair (Option A) and configuring the Snowflake user with the public key (Option D). Setting the 'AUTHENTICATOR parameter to 'snowflake' is the correct approach. 'EXTERNALBROWSER uses the web-based browser authentication, while the private key is specified within the connection parameters directly, not the Snowflake CLI config.
NEW QUESTION # 144
......
The VCEDumps is a leading platform that has been helping the Snowflake SPS-C01 exam aspirants for many years. Over this long time period, thousands of Snowflake Certified SnowPro Specialty - Snowpark (SPS-C01) exam candidates have passed their dream Snowflake SPS-C01 Certification Exam and have become a member of Snowflake SPS-C01 certification exam community. They all got help from valid, updated, and real SPS-C01 exam dumps.
Reliable SPS-C01 Exam Papers: https://www.vcedumps.com/SPS-C01-examcollection.html