
What's more, part of that PracticeVCE MLA-C01 dumps now are free: https://drive.google.com/open?id=1IvoU2EUH69tY5AuLIdTHLWGhhtOd927M
Quitters never win and winners never quit. If you are determined to clear MLA-C01 exam and obtain a certification you shouldn't give up because of one failure. If you are willing, our Amazon MLA-C01 valid exam simulations file can help you clear exam and regain confidence. Every year there are thousands of candidates choosing our products and obtain certifications so that our MLA-C01 valid exam simulations file is famous for its high passing-rate in this field. If you want to pass exam one-shot, you shouldn't miss our files.
| Certification Vendor: | Amazon Web Services (AWS) |
|---|---|
| Exam Name: | AWS Certified Machine Learning Engineer - Associate |
| Exam Number: | MLA-C01 |
| Available Languages: | Korean, Simplified Chinese, Traditional Chinese, English, Japanese |
| Exam Format: | Multiple response, Multiple choice |
| Exam Price: | 150 USD |
| Passing Score: | 1000-2000 scaled score (passing score approximately 720) |
| Related Certifications: | AWS Certified Solutions Architect - Associate AWS Certified Developer - Associate AWS Certified Data Engineer - Associate |
| Real Exam Qty: | 85 |
| Exam Duration: | 170 minutes |
| Certificate Validity Period: | 3 years |
| Sample Questions: | Amazon MLA-C01 Sample Questions |
| Exam Way: | Online proctored (Pearson VUE) or in-person testing center |
| Pre Condition: | Recommended: 2+ years of ML engineering experience, familiarity with AWS ML services |
| Official Syllabus URL: | https://aws.amazon.com/certification/certified-machine-learning-engineer-associate/ |
>> Amazon MLA-C01 Reliable Exam Labs <<
In the era of information, everything around us is changing all the time, so do the MLA-C01 exam. But you don’t need to worry it. We take our candidates’ future into consideration and pay attention to the development of our AWS Certified Machine Learning Engineer - Associate study training dumps constantly. Free renewal is provided for you for one year after purchase, so the MLA-C01 Latest Questions won’t be outdated. The latest MLA-C01 latest questions will be sent to you email, so please check then, and just feel free to contact with us if you have any problem. Our reliable MLA-C01 exam material will help pass the exam smoothly.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
| Topic 4 |
|
NEW QUESTION # 133
An ML engineer needs to use AWS services to identify and extract meaningful unique keywords from documents.
Which solution will meet these requirements with the LEAST operational overhead?
Answer: B
Explanation:
Amazon Comprehend provides pre-built functionality for key phrase extraction and can identify meaningful keywords from documents with minimal setup or operational overhead. It eliminates the need for manual preprocessing, stemming, or stop-word removal and does not require custom model development or infrastructure management. This makes it the most efficient and low-maintenance solution for the task.
NEW QUESTION # 134
A company has developed a new ML model. The company requires online model validation on 10% of the traffic before the company fully releases the model in production. The company uses an Amazon SageMaker endpoint behind an Application Load Balancer (ALB) to serve the model.
Which solution will set up the required online validation with the LEAST operational overhead?
Answer: C
Explanation:
Scenario: The company wants to perform online validation of a new ML model on 10% of the traffic before fully deploying the model in production. The setup must have minimal operational overhead.
Why Use SageMaker Production Variants?
* Built-In Traffic Splitting: Amazon SageMaker endpoints support production variants, allowing multiple models to run on a single endpoint. You can direct a percentage of incoming traffic to each variant by adjusting the variant weights.
* Ease of Management: Using production variants eliminates the need for additional infrastructure like separate endpoints or custom ALB configurations.
* Monitoring with CloudWatch: SageMaker automatically integrates with CloudWatch, enabling real- time monitoring of model performance and invocation metrics.
Steps to Implement:
* Deploy the New Model as a Production Variant:
* Update the existing SageMaker endpoint to include the new model as a production variant. This can be done via the SageMaker console, CLI, or SDK.
Example SDK Code:
import boto3
sm_client = boto3.client('sagemaker')
response = sm_client.update_endpoint_weights_and_capacities(
EndpointName='existing-endpoint-name',
DesiredWeightsAndCapacities=[
{'VariantName': 'current-model', 'DesiredWeight': 0.9},
{'VariantName': 'new-model', 'DesiredWeight': 0.1}
]
)
* Set the Variant Weight:
* Assign a weight of 0.1 to the new model and 0.9 to the existing model. This ensures 10% of traffic goes to the new model while the remaining 90% continues to use the current model.
* Monitor the Performance:
* Use Amazon CloudWatch metrics, such as InvocationCount and ModelLatency, to monitor the traffic and performance of each variant.
* Validate the Results:
* Analyze the performance of the new model based on metrics like accuracy, latency, and failure rates.
Why Not the Other Options?
* Option B: Setting the weight to 1 directs all traffic to the new model, which does not meet the requirement of splitting traffic for validation.
* Option C: Creating a new endpoint introduces additional operational overhead for traffic routing and monitoring, which is unnecessary given SageMaker's built-in production variant capability.
* Option D: Configuring the ALB to route traffic requires manual setup and lacks SageMaker's seamless variant monitoring and traffic splitting features.
Conclusion:
Using production variants with a weight of 0.1 for the new model on the existing SageMaker endpoint provides the required traffic split for online validation with minimal operational overhead.
References:
Amazon SageMaker Endpoints
SageMaker Production Variants
Monitoring SageMaker Endpoints with CloudWatch
NEW QUESTION # 135
An ML engineer wants to deploy a workflow that processes streaming IoT sensor data and periodically retrains ML models. The most recent model versions must be deployed to production.
Which service will meet these requirements?
Answer: D
Explanation:
Amazon SageMaker Pipelines is purpose-built for orchestrating end-to-end ML workflows, including data ingestion, training, evaluation, and deployment. It supports automation, versioning, and deployment of the latest model versions.
MWAA orchestrates general workflows but lacks ML-native features. Lambda cannot handle long-running ML training. Spark processes data but does not manage ML lifecycle.
Therefore, Option A is the correct AWS-native solution.
NEW QUESTION # 136
A company regularly receives new training data from a vendor of an ML model. The vendor delivers cleaned and prepared data to the company's Amazon S3 bucket every 3-4 days.
The company has an Amazon SageMaker AI pipeline to retrain the model. An ML engineer needs to run the pipeline automatically when new data is uploaded to the S3 bucket.
Which solution will meet these requirements with the LEAST operational effort?
Answer: B
Explanation:
AWS best practices recommend event-driven architectures to automate ML workflows with minimal operational overhead. Amazon EventBridge natively integrates with Amazon S3 and Amazon SageMaker Pipelines, making it the most efficient solution for triggering retraining when new data arrives.
Amazon S3 automatically emits object creation events. By creating an EventBridge rule that listens for these events and targets a SageMaker Pipeline execution, the pipeline can start immediately when new training data is uploaded. This solution requires no custom code, no polling, and no infrastructure management.
Option A is incorrect because S3 lifecycle rules manage storage transitions, not workflow execution. Option B introduces custom code and periodic scanning, which increases operational complexity and cost. Option D (MWAA) is powerful but requires maintaining an Airflow environment and is unnecessary for a simple event- based trigger.
AWS documentation explicitly highlights EventBridge + SageMaker Pipelines as the recommended pattern for automated retraining workflows triggered by data arrival.
Therefore, Option C is the correct and AWS-verified answer.
NEW QUESTION # 137
Hotspot Question
A company wants to host an ML model on Amazon SageMaker. An ML engineer is configuring a continuous integration and continuous delivery (Cl/CD) pipeline in AWS CodePipeline to deploy the model. The pipeline must run automatically when new training data for the model is uploaded to an Amazon S3 bucket.
Select and order the pipeline's correct steps from the following list. Each step should be selected one time or not at all. (Select and order three.)
- An S3 event notification invokes the pipeline when new data is
uploaded.
- S3 Lifecycle rule invokes the pipeline when new data is uploaded.
- SageMaker retrains the model by using the data in the S3 bucket.
- The pipeline deploys the model to a SageMaker endpoint.
- The pipeline deploys the model to SageMaker Model Registry.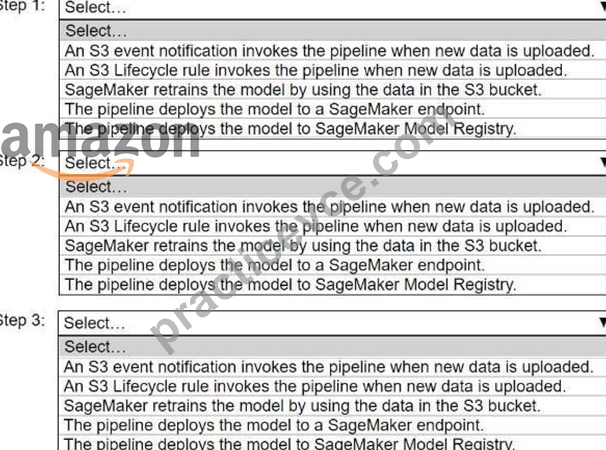
Answer:
Explanation: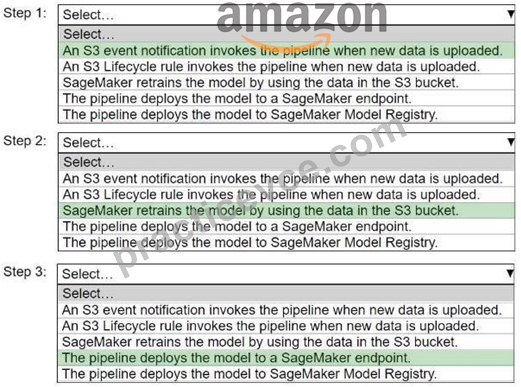
NEW QUESTION # 138
......
MLA-C01 Latest Exam Papers: https://www.practicevce.com/Amazon/MLA-C01-practice-exam-dumps.html
P.S. Free 2026 Amazon MLA-C01 dumps are available on Google Drive shared by PracticeVCE: https://drive.google.com/open?id=1IvoU2EUH69tY5AuLIdTHLWGhhtOd927M