P.S. Free 2026 Databricks Databricks-Certified-Data-Engineer-Associate dumps are available on Google Drive shared by Prep4pass: https://drive.google.com/open?id=18YTmJQbjRGzW_pYyr3MuL8uDlVGvbxad
Nowadays, using computer-aided software to pass the Databricks-Certified-Data-Engineer-Associate exam has become a new trend. Because the new technology enjoys a distinct advantage, that is convenient and comprehensive. In order to follow this trend, our company product such a Databricks-Certified-Data-Engineer-Associate exam questions that can bring you the combination of traditional and novel ways of studying. The passing rate of our study material is up to 99%. If you are not fortune enough to acquire the Databricks-Certified-Data-Engineer-Associate Certification at once, you can unlimitedly use our Databricks-Certified-Data-Engineer-Associate product at different discounts until you reach your goal and let your dream comes true.
| Section | Weight | Objectives |
|---|---|---|
| Apache Spark Data Processing Fundamentals | 20-25% | - Work with structured data types (arrays, maps, structs) - Create and use Spark DataFrames - Use Spark SQL for data processing - Apply transformations and actions on DataFrames |
| Python for Data Engineering | 10-15% | - Use PySpark for data processing - Implement user-defined functions (UDFs) - Work with Spark APIs in Python |
| Data Pipeline Architecture | 15-20% | - Monitor and optimize pipeline performance - Design data pipelines for batch and streaming - Implement incremental data processing - Understand ELT vs ETL patterns |
| Delta Lake Fundamentals | 20-25% | - Write to and read from Delta tables - Explain Delta Lake features and benefits - Understand ACID transactions and time travel - Create and manage Delta tables |
| Lakehouse Platform Concepts | 10-15% | - Understand the Lakehouse architecture and its benefits - Describe key Databricks Lakehouse platform components - Explain data governance and security concepts |
| Spark SQL and DataFrames | 15-20% | - Write and execute Spark SQL queries - Handle null values and data quality - Join and union DataFrames - Aggregate and group data |
>> Reliable Databricks-Certified-Data-Engineer-Associate Test Topics <<
Prep4pass is proud to announce that our Databricks Databricks-Certified-Data-Engineer-Associate exam dumps help the desiring candidates of Databricks Databricks-Certified-Data-Engineer-Associate certification to climb the ladder of success by grabbing the Databricks Exam Questions. Prep4pass trained experts have made sure to help the potential applicants of Databricks Certified Data Engineer Associate Exam (Databricks-Certified-Data-Engineer-Associate) certification to pass their Databricks Certified Data Engineer Associate Exam (Databricks-Certified-Data-Engineer-Associate) exam on the first try. Our PDF format carries real Databricks Certified Data Engineer Associate Exam (Databricks-Certified-Data-Engineer-Associate) exam dumps.
NEW QUESTION # 199
A data engineer needs to provide access to a group named manufacturing-team. The team needs privileges to create tables in the quality schema.
Which set of SQL commands will grant a group named manufacturing-team to create tables in a schema named production with the parent catalog named manufacturing with the least privileges?




Answer: C
NEW QUESTION # 200
A Delta Live Table pipeline includes two datasets defined using STREAMING LIVE TABLE. Three datasets are defined against Delta Lake table sources using LIVE TABLE.
The table is configured to run in Production mode using the Continuous Pipeline Mode.
Assuming previously unprocessed data exists and all definitions are valid, what is the expected outcome after clicking Start to update the pipeline?
Answer: C
Explanation:
Explanation
In a Delta Live Table pipeline running in Continuous Pipeline Mode, when you click Start to update the pipeline, the following outcome is expected: All datasets defined using STREAMING LIVE TABLE and LIVE TABLE against Delta Lake table sources will be updated at set intervals. The compute resources will be deployed for the update process and will be active during the execution of the pipeline. The compute resources will be terminated when the pipeline is stopped or shut down. This mode allows for continuous and periodic updates to the datasets as new data arrives or changes in the underlying Delta Lake tables occur. The compute resources are provisioned and utilized during the update intervals to process the data and perform the necessary operations.
NEW QUESTION # 201
A data engineer has configured a Structured Streaming job to read from a table, manipulate the data, and then perform a streaming write into a new table.
The code block used by the data engineer is below: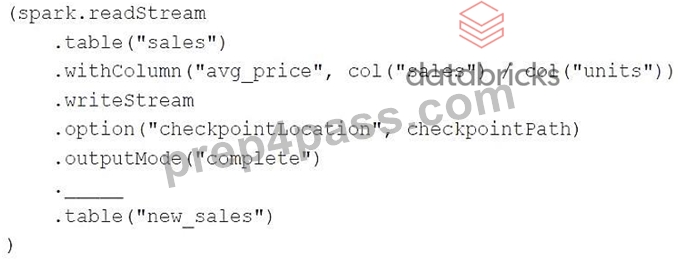
If the data engineer only wants the query to process all of the available data in as many batches as required, which of the following lines of code should the data engineer use to fill in the blank?
Answer: C
NEW QUESTION # 202
A data engineer is using the following code block as part of a batch ingestion pipeline to read from a composable table:
Which of the following changes needs to be made so this code block will work when the transactions table is a stream source?
Answer: A
Explanation:
To read from a stream source, the data engineer needs to use the spark.readStream method instead of the spark.
read method. The spark.readStream method returns a DataStreamReader object that can be used to specify the details of the input source, such as the format, the schema, the path, and the options. The spark.read method is only suitable for batch processing, not streaming processing. The other changes are not necessary or correct for reading from a stream source. References: Structured Streaming Programming Guide, Read a stream, Databricks Data Sources
NEW QUESTION # 203
Which of the following commands can be used to write data into a Delta table while avoiding the writing of duplicate records?
Answer: E
Explanation:
The MERGE command can be used to upsert data from a source table, view, or DataFrame into a target Delta table. It allows you to specify conditions for matching and updating existing records, and inserting new records when no match is found. This way, you can avoid writing duplicate records into a Delta table1. The other commands (DROP, IGNORE, APPEND, INSERT) do not have this functionality and may result in duplicate records or data loss234. References: 1: Upsert into a Delta Lake table using merge | Databricks on AWS 2: SQL DELETE | Databricks on AWS 3: SQL INSERT INTO | Databricks on AWS 4: SQL UPDATE
| Databricks on AWS
NEW QUESTION # 204
......
Never have we made our customers disappointed about our Databricks-Certified-Data-Engineer-Associate study guide. So we have enjoyed good reputation in the market for about ten years. In the future, we will stay integrity and research more useful Databricks-Certified-Data-Engineer-Associate learning materials for our customers. Please continue supporting our Databricks-Certified-Data-Engineer-Associate Exam Questions and we will make a better job with your warm encourages and suggestions. So if you have any opinions about our Databricks-Certified-Data-Engineer-Associate learning quiz, just leave them for us.
Standard Databricks-Certified-Data-Engineer-Associate Answers: https://www.prep4pass.com/Databricks-Certified-Data-Engineer-Associate_exam-braindumps.html
BTW, DOWNLOAD part of Prep4pass Databricks-Certified-Data-Engineer-Associate dumps from Cloud Storage: https://drive.google.com/open?id=18YTmJQbjRGzW_pYyr3MuL8uDlVGvbxad