What's more, part of that PassReview DP-750 dumps now are free: https://drive.google.com/open?id=1UdEZTPDa8SkIgpvYG35aOYZzIH7nFQFZ
We are professional at providing best and valid DP-750 exam materials to help the candidates successfully pass their DP-750 exams with ease as well as establish their confidence. The precise and valid DP-750 exam torrent compiled by our experts is outstanding and tested by our clients all over the world. The numerous feedbacks from our clients proved our influence and charisma. We can provide you the fastest way to get your dreaming DP-750 Certification.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Prepare and process data | 30-35% | - Data quality and validation
|
| Topic 2: Configure and manage Azure Databricks environments | 15-20% | - Security and authentication setup
|
| Topic 3: Deploy and manage data pipelines and workloads | 30-35% | - Operational reliability
|
| Topic 4: Secure and govern data using Unity Catalog | 15-20% | - Access control and policies
|
>> Reliable DP-750 Test Sims <<
You must be curious about your exercises after submitting to the system of our DP-750 study materials. Now, we have designed an automatic analysis programs to facilitate your study. You will soon get your learning report without delay. Not only can you review what you have done yesterday on the online engine of the DP-750 study materials, but also can find your wrong answers and mark them clearly. So your error can be corrected quickly. Then you are able to learn new knowledge of the DP-750 Study Materials. Day by day, your ability will be elevated greatly. Intelligent learning helper can relieve your heavy burden. Our DP-750 study materials deserve your purchasing. If you are always waiting and do not action, you will never grow up.
NEW QUESTION # 83
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains two Delta tables named Table1 and Table2 of the same data type.
Table1 contains a column named Columnl. Table2 contains a column named Column2. You run the following query.
SELECT Column1
FROM Table1
GROUP BY Column1
HAVING COUNT(") > 1
INTERSECT
SELECT C0lumn2
FROM Table2
GROUP BY Column2
HAVING COUNT(') > 1;
What occurs when you run the query?
Answer: D
Explanation:
The correct answer is B - values appear in both tables more than once.
Reading the query from the inside out: each subquery identifies values that appear more than once within their own table. The first subquery returns Column1 values that are duplicated in Table1. The second returns Column2 values that are duplicated in Table2. INTERSECT then returns only the values that appear in both result sets - meaning values that are duplicated in Table1 AND also duplicated in Table2.
Option A describes a UNION result (values in either table), not INTERSECT. Option C only considers duplicates in Table1, ignoring the Table2 condition - that would be the first subquery in isolation. Option D describes values exclusive to Table2 (EXCEPT or MINUS), the opposite of INTERSECT's requirement that values appear in both sets.
INTERSECT always requires membership in both operands - that's its fundamental definition in standard SQL.
Reference: https://learn.microsoft.com/en-us/azure/databricks/sql/language-manual/sql-ref-syntax-qry-select- setops
NEW QUESTION # 84
What ensures failure recovery in Databricks Structured Streaming?
Answer: B
Explanation:
Checkpointing stores streaming state and progress, allowing recovery after failures without data loss or duplication. Auto scaling adjusts compute resources but does not ensure reliability.
Partition pruning improves query performance. Broadcast joins optimize joins but are unrelated to recovery.
NEW QUESTION # 85
You need to develop the task logic for a new job in Lakeflow Jobs that processes telemetry data.
Each task must contain only the appropriate logic for its step in the pipeline. The solution must support the planned changes and meet the data ingestion and processing requirements.
What should you do?
Answer: D
Explanation:
The correct answer is D. Breaking the pipeline into separate tasks for ingestion, cleansing, and curation is the foundation of well-designed Lakeflow Jobs pipelines. Each task should own one responsibility - when a task does too much, debugging a failure becomes a hunt through unrelated code, and retry logic becomes expensive because you re-execute work that already succeeded.
Contoso ' s planned changes explicitly call for ' a clear execution order and dependencies ' and ' orchestrate multi-step ingestion and transformation workflows. ' Separate tasks map directly to those goals: Lakeflow Jobs tracks each task ' s status independently, so if cleansing fails, ingestion doesn ' t re-run.
Option A bundles everything into one notebook, which means a curation bug forces a full re-ingestion. Option B copies logic three times - any future change must be applied in triplicate, which is a maintenance hazard.
Option C forces everything through SQL MERGE, which is the wrong tool for raw-event ingestion and doesn
' t address cleansing or schema drift.
Reference: https://learn.microsoft.com/en-us/azure/databricks/jobs/
NEW QUESTION # 86
You have an Azure Databricks job named Job1 that contains an ingestion task named Task1 and transformation task named Task2. You need to ensure that if Task1 fails, the task retries automatically, and Task2 is prevented from running How should you configure Job1? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.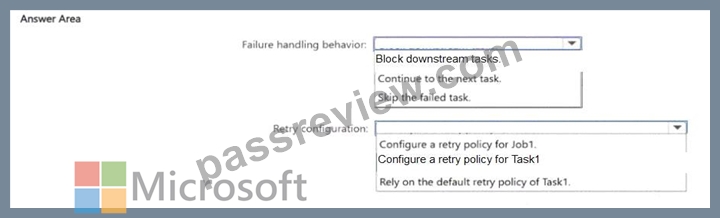
Answer:
Explanation: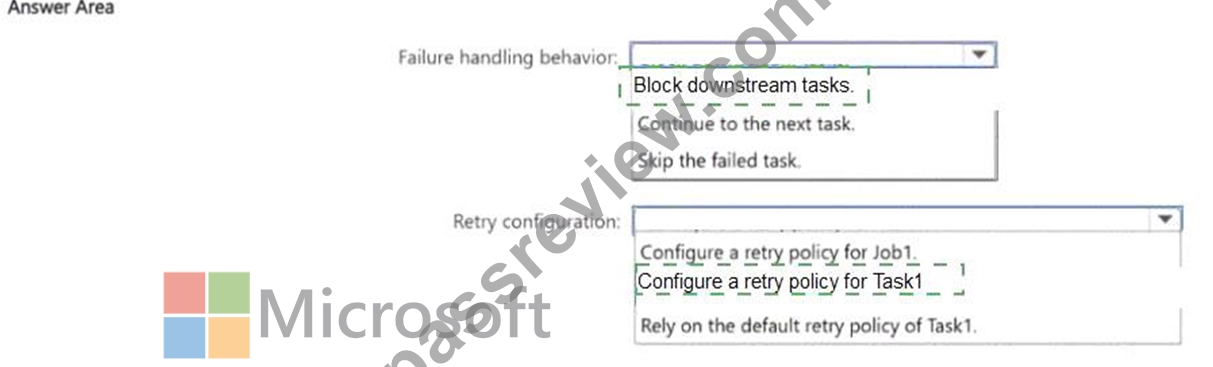
Explanation:
Two task-level settings solve this:
Task1 retry policy: configure Task1 with a maximum number of retries and a retry interval. When Task1 fails, Lakeflow Jobs automatically re-runs it up to the retry limit without any manual intervention. This handles transient infrastructure failures transparently.
Task2 run condition set to 'All succeeded' with Task1 as its dependency: this means Task2 only starts when Task1 has succeeded. If Task1 fails and exhausts all retries, Task2 remains blocked - it never runs on data from a failed upstream ingestion. The dependency is declared in Task2's 'Depends on' setting in the job configuration.
These two settings are independent and composable. Task1's retry policy gives it multiple chances to recover.
Task2's dependency and run condition ensure the downstream transformation only runs on clean, successfully ingested data.
Reference: https://learn.microsoft.com/en-us/azure/databricks/jobs/configure-jobs#task-retries
NEW QUESTION # 87
You have an Azure Databricks workspace that contains an all-purpose cluster named Cluster1.
You need to configure Cluster1 to meet the following requirements:
- The cluster must scale up automatically when workloads increase.
- The cluster must scale down automatically when workloads decrease.
The solution must minimize costs.
Which two actions should you perform? Each correct answer presents part of the solution.
NOTE: Each correct selection is worth one point.
Answer: B,D
Explanation:
Enabling autoscaling and setting a 30-minute auto-termination timeout is the correct configuration to meet the goals.
Autoscaling handles fluctuating workloads, while auto-termination prevents you from paying for idle compute resources.
Dynamic Scaling: Autoscaling automatically adds workers during high loads and removes them when demand drops.
Cost Control: The 30-minute termination window ensures the cluster shuts down completely if no jobs are running, stopping all compute charges.
Reference:
https://community.databricks.com/t5/get-started-discussions/cluster-auto-termination-best- practices/td-p/75826
NEW QUESTION # 88
......
You cannot pass the DP-750 exam if you do not have real Implementing Data Engineering Solutions Using Azure Databricks (DP-750) exam questions. It is the foremost thing that everyone should have to nail the Microsoft DP-750 Exam. The DP-750 practice test material of PassReview is available in web-based practice tests, desktop practice exam software, and PDF.
Test DP-750 Cram: https://www.passreview.com/DP-750_exam-braindumps.html
P.S. Free & New DP-750 dumps are available on Google Drive shared by PassReview: https://drive.google.com/open?id=1UdEZTPDa8SkIgpvYG35aOYZzIH7nFQFZ