What's more, part of that BraindumpStudy AI-103 dumps now are free: https://drive.google.com/open?id=1LxIaHCwBErS8R8WLPgdkYY0SubCOOFOG
AI-103 practice dumps offers you more than 99% pass guarantee, which means that if you study our AI-103 learning guide by heart and take our suggestion into consideration, you will absolutely get the certificate and achieve your goal. Meanwhile, if you want to keep studying this course , you can still enjoy the well-rounded services by AI-103 Test Prep, our after-sale services can update your existing AI-103 study quiz within a year and a discount more than one year.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Implement computer vision solutions | 10–15% | - Implement image analysis and processing
|
| Topic 2: Implement generative AI and agentic solutions | 30–35% | - Design and implement intelligent agents
|
| Topic 3: Implement information extraction and knowledge mining | 10–15% | - Extract structured data from documents
|
| Topic 4: Implement text and speech analysis solutions | 10–15% | - Implement natural language processing
|
| Topic 5: Plan and manage Azure AI solutions | 25–30% | - Manage AI solution development lifecycle
|
>> AI-103 Reliable Study Materials <<
There is no another great way to pass the Microsoft AI-103 exam in the first attempt only by doing a selective study with valid AI-103 braindumps. If you already have a job and you are searching for the best way to improve your current AI-103 test situation, then you should consider the AI-103 Exam Dumps. By using our updated AI-103 products, you will be able to get reliable and relative AI-103 exam prep questions, so you can pass the exam easily. You can get one-year free AI-103 exam updates from the date of purchase.
NEW QUESTION # 59
You have a Microsoft Foundry project that contains an agent and uses a GitHub repository. The repository contains a YAM file named File1 that defines the evaluation settings of the agent. You need to create a GitHub Actions workflow that runs the evaluation defined in File1 when a pull request (PR) is opened. How should you configure the workflow?
Answer: B
Explanation:
The correct configuration choice is to set project-endpoint to the endpoint of the project.
azure-ai-project-endpoint: This parameter is required and must be set to the URL endpoint of your Microsoft Foundry project. This aligns with setting project-endpoint.
Reference:
https://learn.microsoft.com/en-us/azure/foundry/how-to/evaluation-github-action
NEW QUESTION # 60
You have a Microsoft Foundry project that contains an agent.
The agent uses a knowledge source built from documents stored in Azure Blob Storage. The documents include digitally scanned PDFs that contain multipage tables.
You have an ingestion job that extracts only plain text, causing loss of table structure, headings, and page- number metadata.
Users frequently ask questions that require the retrieval of specific table rows across the pages.
You need to configure an ingestion job for a Retrieval Augmented Generation (RAG) pipeline that performs optical character recognition (OCR) on scanned PDFs, preserves tables and headings as structure-aware chunks, and stores page-number metadata with each chunk.
How should you configure the ingestion job?
Answer: D
Explanation:
The correct configuration is advanced data parsing because the issue is not merely OCR; the ingestion job must preserve document structure for reliable RAG retrieval. Microsoft guidance for advanced parsing states that it automatically detects tables across all pages, including tables in scanned documents, merges tables that span multiple pages, restores column headers, and creates table chunks with metadata such as table index, shape, page numbers, section headings, and table previews. This directly satisfies the requirement to retrieve specific rows from multipage tables while retaining source-page context.
Basic parsing with fixed-size chunking would flatten the document into arbitrary text fragments, which is the current failure mode. OCR with page-level chunking improves text extraction from scanned PDFs, but it does not provide structure-aware chunks that preserve headings and table relationships across pages. Storing each page as a single chunk is too coarse for row-level retrieval and can bury relevant table rows in excessive context. Advanced data parsing is purpose-built for RAG ingestion because it produces semantically meaningful, retrievable chunks and enriches them with metadata needed for citations and grounding.
Reference topics: RAG ingestion, advanced parsing, OCR, table extraction, structure-aware chunking, page metadata, and Azure Blob Storage document ingestion.
NEW QUESTION # 61
You have a Microsoft Foundry project that contains an agent.
The agent accepts user-uploaded screenshots and uses a multimodal chat model.
Some screenshots contain potentially malicious embedded text.
You need to prevent a prompt injection attack and ensure that third-party content is treated as lower trust.
How should you configure prompt shields for document attacks? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.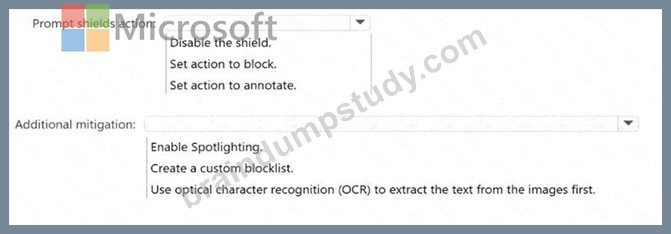
Answer:
Explanation: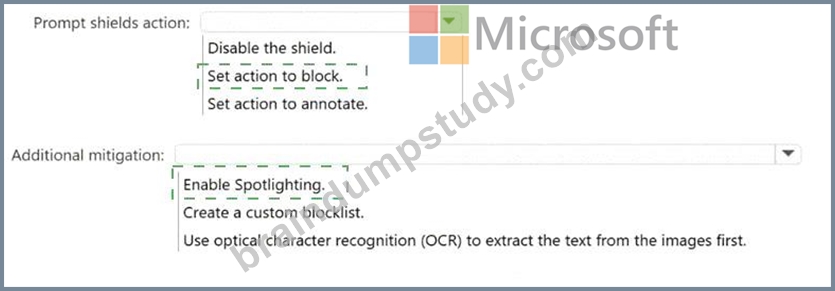
Explanation:
Prompt shields action: Set action to block.
Additional mitigation: Enable Spotlighting.
The correct configuration is to set the Prompt Shields document attack action to block and enable Spotlighting . Prompt Shields in Microsoft Foundry are designed to detect attempts to manipulate model behavior through adversarial input. Microsoft distinguishes document attacks from direct user prompt attacks:
document attacks are malicious instructions embedded in third-party content such as documents, webpages, emails, or other externally supplied material. In this scenario, the embedded text inside uploaded screenshots is third-party content and can attempt to override the agent's instructions. Setting the action to block prevents detected document-attack content from being processed normally, which is required because the goal is prevention rather than passive logging or annotation.
Spotlighting is the additional mitigation because it marks or transforms document content so the model treats it as lower trust than system and user instructions. Microsoft's Foundry guidance describes Spotlighting as a Prompt Shields subfeature that helps protect against indirect or embedded document attacks by tagging input documents with special formatting to indicate lower trust. A custom blocklist is insufficient for unknown attacks, and OCR alone only extracts the malicious text; it does not mitigate prompt injection. Reference topics: Prompt Shields, document attacks, guardrails, Spotlighting, multimodal safety, and prompt injection defense.
NEW QUESTION # 62
Hotspot Question
You have a Python application collects customer comments before posting them to a public forum.
You need to send a text comment to Azure AI Content Safety and return the self-harm severity from the response.
How should you complete the code? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.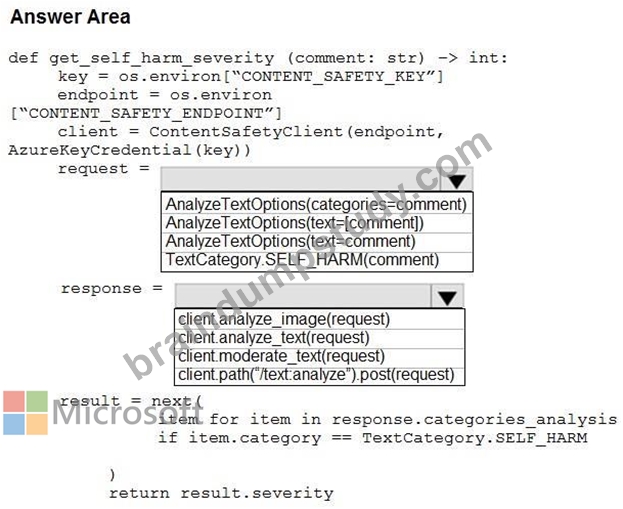
Answer:
Explanation:
Explanation:
Box 1: AnalyzeTextOptions(text=comment)
To set up the request in your Python script, you must use AnalyzeTextOptions(text=comment), passing the text as a single string rather than a list.
Example:
Build the request options focusing on Text analysis
# You can optionally restrict analysis to specific categories
request_options = AnalyzeTextOptions(
text=user_comment,
categories=[TextCategory.SELF_HARM]
Box 2: client.analyze_text(request)
You must use client.analyze_text(request)
1. Send the request: Call client.analyze_text(request) to retrieve the multi-severity results.
2. Extract the self-harm result: Locate the self-harm categories from the response list.
3. Return the severity: Access the .severity attribute
Reference:
https://learn.microsoft.com/en-us/python/api/overview/azure/ai-contentsafety-readme
NEW QUESTION # 63
You have a Microsoft Foundry project that generates short promotional product videos.
After several clips are approved, reviewers notice a small watermark in the top-right corner of some videos.
You need to remove the watermark without regenerating the videos.
What should you do?
Answer: B
Explanation:
The correct action to take is to apply a mask-based inpainting edit to the affected part of the video.
This is the only option that directly modifies the existing, approved video files. Inpainting allows you to isolate the specific top-right corner using a mask and seamlessly blend it with the surrounding pixels to erase the watermark without altering or regenerating the rest of the video footage.
Reference:
https://openart.ai/features/ai-video-inpainting/
NEW QUESTION # 64
......
However, how can you get the AI-103 certification successfully in the shortest time? We also know you can’t spend your all time on preparing for your exam, so it is very difficult for you to get the certification in a short time. Don’t worry; AI-103 question torrent is willing to help you solve your problem. We have compiled such a AI-103 Guide torrents that can help you pass the exam easily, it has higher pass rate and higher quality than other study materials. So, are you ready? Buy our AI-103 guide questions; it will not let you down.
Reliable AI-103 Test Review: https://www.braindumpstudy.com/AI-103_braindumps.html
BTW, DOWNLOAD part of BraindumpStudy AI-103 dumps from Cloud Storage: https://drive.google.com/open?id=1LxIaHCwBErS8R8WLPgdkYY0SubCOOFOG