Up to now, there are three versions of AI-103 exam materials for your choice. So high-quality contents and flexible choices of AI-103 learning mode will bring about the excellent learning experience for you. Though the content of these three versions of our AI-103 study questions is the same, their displays are totally different. And you can be surprised to find that our AI-103 learning quiz is developed with the latest technologies as well.
| Section | Weight | Objectives |
|---|---|---|
| Plan and manage Azure AI solutions | 25–30% | - Design Azure AI infrastructure
|
| Implement computer vision solutions | 10–15% | - Build multimodal solutions
|
| Implement information extraction and knowledge mining | 10–15% | - Extract structured data from documents
|
| Implement generative AI and agentic solutions | 30–35% | - Design and implement intelligent agents
|
| Implement text and speech analysis solutions | 10–15% | - Implement natural language processing
|
>> AI-103 Latest Test Online <<
Do you want to pass exam 100% one-shot? Do you want to get certification fast? Microsoft AI-103 actual test question is a good way. If you study hard, 20-40 hours' preparation will help you pass exam. Once you clear AI-103 exam and obtain certification you will have a bright future. You have a great advantage over the other people. Microsoft AI-103 Actual Test questions have effective high-quality content and cover at least more than 88% of the real test questions. Looking for the best exam preparation, ours is the best.
NEW QUESTION # 66
Note: This section contains one or more sets of questions with the same scenario and problem. Each question presents a unique solution to the problem. You must determine whether the solution meets the stated goals. More than one solution in the set might solve the problem. It is also possible that none of the solutions in the set solve the problem.
After you answer a question in this section, you will NOT be able to return. As a result, these questions do not appear on the Review Screen.
You have a Microsoft Foundry project that contains an agent. The agent generates summaries from retrieved policy documents.
Users report that some responses omit required regulatory clauses, even when the clauses are present in the retrieved content.
You need to improve response completeness.
Solution: You increase the value of the max_tokensparameter.
Does this meet the goal?
Answer: A
Explanation:
Correct:
* You add a reflection pass that regenerates the response if the required clauses are missing.
This is Self-Correction Strategy: A reflection pass allows an agent to evaluate its own initial output against specified constraints (e.g., checking for the presence of mandatory regulatory clauses). If the required text is missing, the agent triggers a programmatic self-correction or regeneration loop to include them before final delivery.
Incorrect:
* You increase the value of the max_tokens parameter.
Increasing the max_tokens parameter prevents the response from being cut off mid-sentence due to length constraints. However, it does not force the model's logic to explicitly include missing information that it chose to leave out earlier in the text.
* You increase the value of the temperature parameter.
Raising the temperature parameter increases randomness and creativity. For rigid compliance tasks like summarizing regulatory documents, higher temperature actually increases the risk of hallucination and omission.
* You run an evaluation flow that scores responses for completeness and blocks responses that fall below a defined threshold.
Evaluation Flow Block: Running an evaluation flow to score completeness and blocking bad responses identifies and stops low-quality outputs, but it does not fix or actively improve the response completeness. It simply filters failures out of the system.
Reference:
https://pub.towardsai.net/reflection-with-llm-how-to-make-ai-review-its-own-work-2db122fca1d8
NEW QUESTION # 67
You have a Microsoft Foundry project that contains a customer support agent built by using the Foundry Agent Service.
The agent uploads user-provided screenshots to Azure Storage through a ticketing tool and receives a blob URL for additional reasoning.
You need to use image moderation during agent runs and prevent harmful content from being returned during runs. Azure Al Content Safety must access the images by using the blob URL. The solution must follow the principle of least privilege.
What should you configure for Content Safety? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.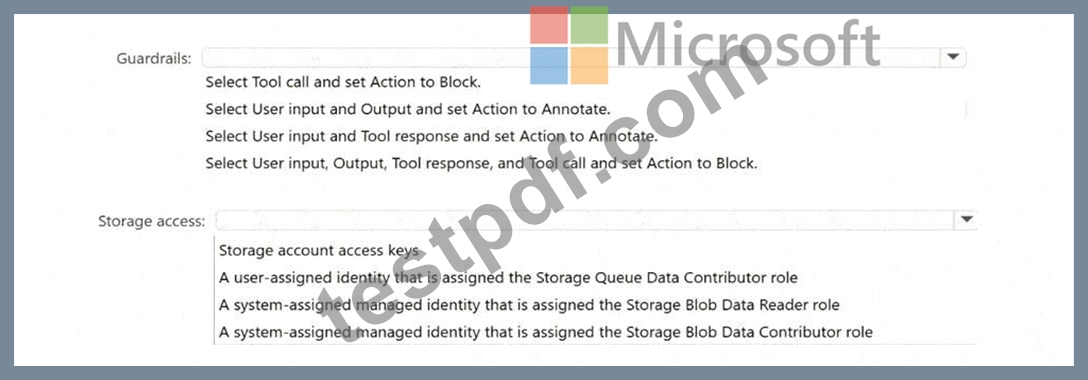
Answer:
Explanation: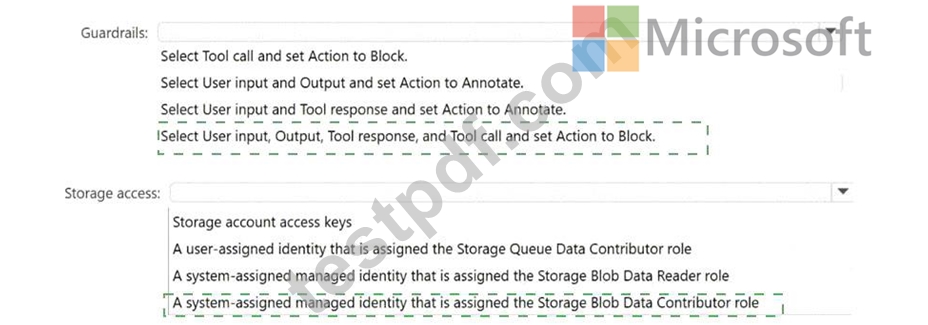
Explanation:
Guardrails: Select User input, Output, Tool response, and Tool call and set Action to Block.
Storage access: A system-assigned managed identity that is assigned the Storage Blob Data Contributor role The guardrail must be applied to User input, Output, Tool response, and Tool call with the action set to Block . Microsoft Foundry guardrails support four intervention points: user input, tool call, tool response, and output. This scenario includes user-provided screenshots, a ticketing tool that uploads images and returns blob URLs, and final agent responses. Applying blocking controls at all four points ensures harmful image-related content is inspected throughout the agent run and prevented from continuing or being returned to the user.
Microsoft's guardrails guidance also states that tool call and tool response controls are specifically required when harmful content can pass through agent tools.
For storage, configure the Azure AI Content Safety resource with a system-assigned managed identity and grant it Storage Blob Data Contributor on the storage account or container. The Content Safety image moderation quickstart states that images can be supplied by blob storage URL and that the Content Safety resource must be given storage access by enabling its system-assigned managed identity and assigning Storage Blob Data Contributor or Owner; Contributor is the least-privileged valid option shown. Reference topics: Foundry guardrails, agent intervention points, image moderation, managed identity, and Azure Storage RBAC.
NEW QUESTION # 68
You plan to deploy a containerized version of an Azure Al Language service that will be used for sentiment analysis.
You configure https: //contoso.cognitiveservices.azure, cow as the endpoint URI for the service.
You need to run the container on an Azure virtual machine by using Docker.
How should you complete the command? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.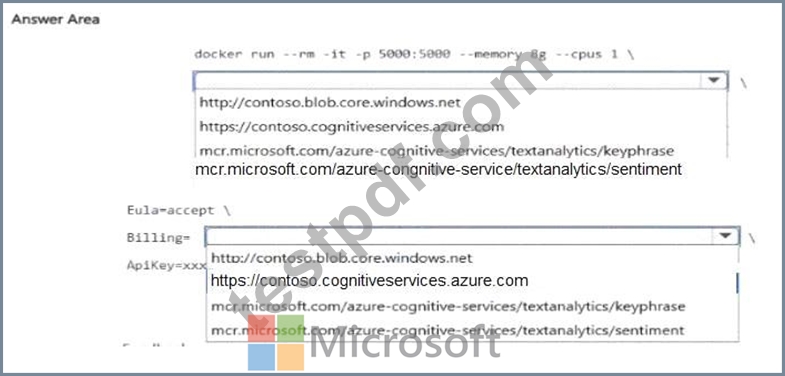
Answer:
Explanation: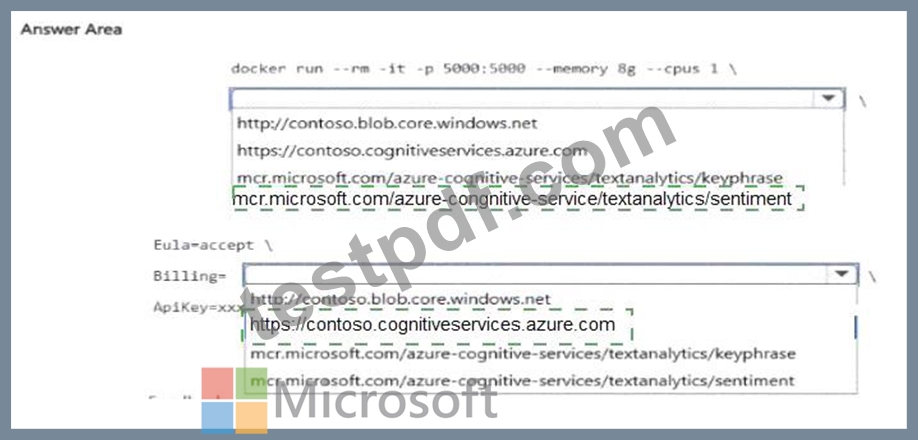
Explanation:
First selection:
mcr.microsoft.com/azure-cognitive-services/textanalytics/sentiment
Second selection:
https://contoso.cognitiveservices.azure.com
Completed command:
docker run --rm -it -p 5000:5000 --memory 8g --cpus 1 \
mcr.microsoft.com/azure-cognitive-services/textanalytics/sentiment \
Eula=accept \
Billing=https://contoso.cognitiveservices.azure.com \
ApiKey=xxx
The image mcr.microsoft.com/azure-cognitive-services/textanalytics/sentiment is the official Microsoft Container Registry image for Azure AI Language sentiment analysis. The Billing argument must reference the endpoint of the provisioned Azure AI Language resource associated with the supplied API key. It is not the address used by applications to invoke the locally running container.
Azure
AI containers require three licensing and metering parameters: Eula=accept, a valid Billing endpoint, and ApiKey. Without all three values, the container does not start. The command maps host port 5000 to container port 5000, allocates 8 GB of memory and one CPU, creates an interactive terminal, and automatically removes the stopped container. Applications subsequently invoke the locally hosted service through an address such as http://
< vm-address > :5000. The Azure endpoint remains responsible for metering and authentication; analyzed customer text is processed by the container rather than sent to the billing endpoint.
Study Guide alignment: Implement text analysis solutions - perform sentiment analysis and opinion mining, deploy Azure Language containers, and configure container billing parameters.
NEW QUESTION # 69
Your company is piloting a customer support agent in a Microsoft Foundry project name Project1. Project1 is connected to an existing Application Insights resource, and the company ' s support team reviews runs in the Traces tab.
The Foundry Agent Service is configured to perform the following actions:
* Retrieve the Application Insights connection string by calling
project_client.telemetry.get_application_insights_connection_string().
* Call configure_azure_monitor(connection_string=...) to enable telemetry.
A separate LangChain service configured to use OpenTelemetry and has the following configurations:
* Uses AzureAIOpenTelemetryTracer(connection_string=..., enable_content_recording=False)
* Passes the tracer by using config={ " callbacks " :[azure_tracer]}
Company policy has the following requirements:
* Telemetry from LangChain and OpenTelemetry must be distinguishable within the same Application Insights resource.
* Secrets and credentials must NOT be stored in prompts, tool arguments, or span attributes.
For each of the following statements, select Yes if the statement is true. Otherwise, select No.
NOTE: Each correct selection is worth one point.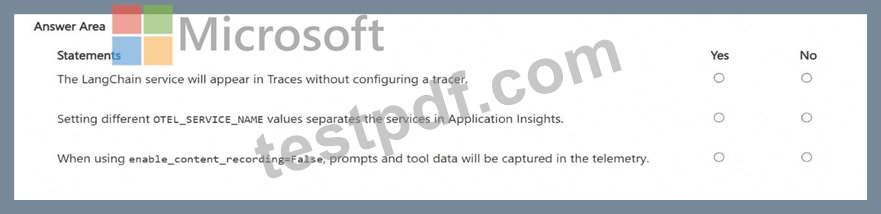
Answer:
Explanation: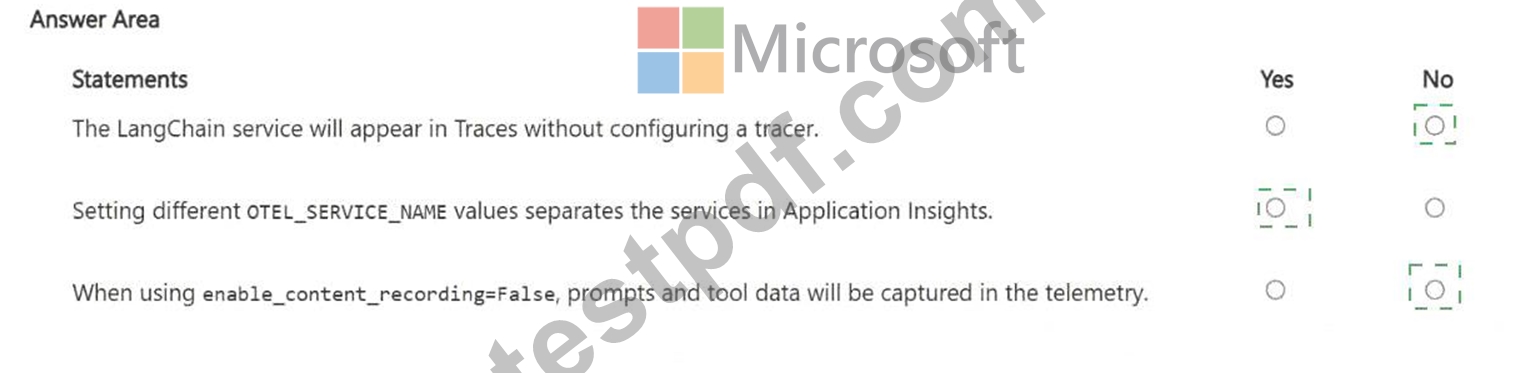
Explanation:
The LangChain service will appear in Traces without configuring a tracer: No Setting different OTEL_SERVICE_NAME values separates the services in Application Insights: Yes When using enable_content_recording=False, prompts and tool data will be captured in the telemetry: No The first statement is No because a separate LangChain or LangGraph application must emit telemetry through the configured tracing integration. Microsoft's LangChain tracing guidance states that you configure AzureAIOpenTelemetryTracer, attach it to the runnable or agent through callbacks, and then inspect the emitted traces in Azure Monitor. The troubleshooting guidance also states that missing LangChain or LangGraph spans are caused by tracing callbacks not being attached to the run.
The second statement is Yes . In OpenTelemetry, OTEL_SERVICE_NAME maps to the service.name resource attribute. Azure Monitor Application Insights uses cloud role names to represent separate services, and Microsoft states that when multiple services emit to the same Application Insights resource, cloud role names must be set so services are represented properly.
The third statement is No . enable_content_recording=False is specifically used to redact message content and tool call arguments from traces. Microsoft also advises disabling content recording in production and not storing secrets, credentials, or tokens in prompts or tool arguments. Reference topics: Microsoft Foundry tracing, LangChain tracing, OpenTelemetry service naming, Application Insights, and secure telemetry configuration.
NEW QUESTION # 70
You have a Microsoft Foundry project that contains a deployed chat model.
You have a Python service that sends API requests to the model. The service is integrated with an automated validation system that compares generated outputs against approved response patterns.
Stakeholders report that small wording differences are causing validation mismatches.
You need to update the request parameters to improve output stability. The solution must maximize reasoning quality.
How should you complete the Python code? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.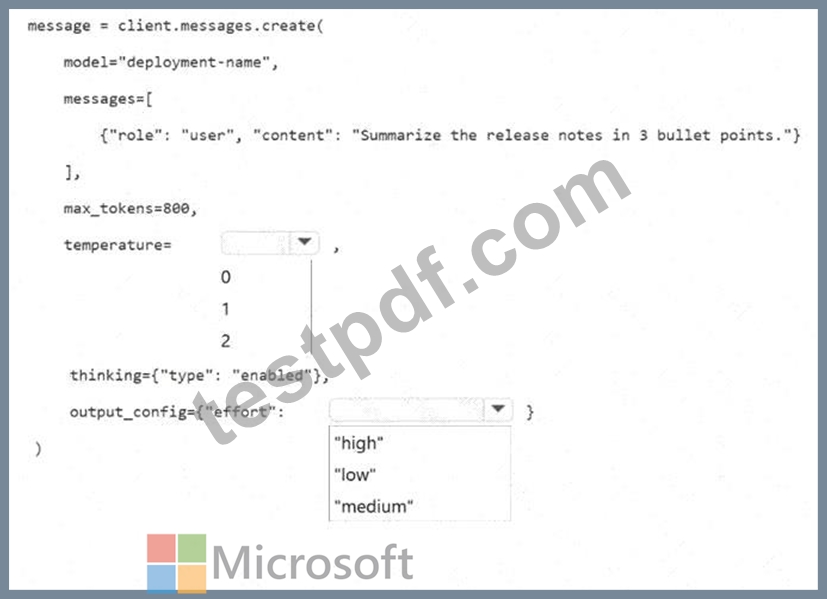
Answer:
Explanation: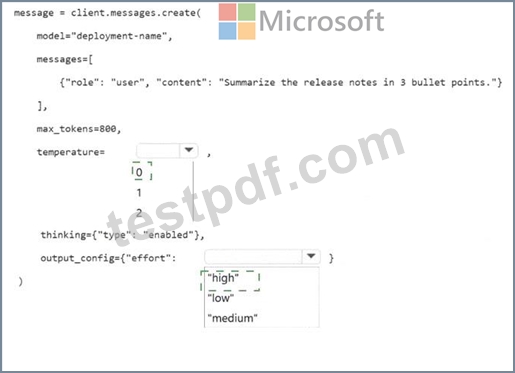
Explanation:
temperature = 0
output_config = { " effort " : " high " }
The correct configuration is temperature = 0 and output_config = { " effort " : " high " }. The requirement is to reduce small wording variations that are breaking automated validation. In chat completion requests, temperature controls sampling randomness. Microsoft's Azure OpenAI reference states that temperature ranges between 0 and 2, and that higher values make output more random while lower values make output more focused and deterministic. Therefore, the most stable setting from the available choices is 0, because it minimizes randomness and improves repeatability for validation-sensitive response patterns.
The solution must also maximize reasoning quality. The code already enables thinking with thinking={ " type
" : " enabled " }, so the remaining reasoning-quality control is the effort setting. Microsoft Foundry model guidance states that the effort parameter controls the quality/cost tradeoff and supports low, medium, and high effort levels. Selecting " high " maximizes reasoning quality among the available options.
Using temperature values of 1 or 2 would increase variability and make validation mismatches more likely.
Selecting low or medium effort would not meet the requirement to maximize reasoning quality. Reference topics: Microsoft Foundry model inference, chat model parameters, temperature, thinking, effort, and output stability.
NEW QUESTION # 71
......
Our product boosts many advantages and it is worthy for you to buy it. You can have a free download and tryout of our AI-103 exam torrents before purchasing. After you purchase our product you can download our AI-103 study materials immediately. We will send our product by mails in 5-10 minutes. We provide free update and the discounts for the old client. If you have any doubts or questions you can contact us by mails or the online customer service personnel and we will solve your problem as quickly as we can. Our AI-103 Exam Materials boost high passing rate and if you are unfortunate to fail in exam we can refund you in full at one time immediately. The learning costs you little time and energy and you can commit yourself mainly to your jobs or other important things.
AI-103 Simulation Questions: https://www.testpdf.com/AI-103-exam-braindumps.html