참고: Pass4Test에서 Google Drive로 공유하는 무료, 최신 Databricks-Certified-Professional-Data-Engineer 시험 문제집이 있습니다: https://drive.google.com/open?id=1SgXcieROQBhvuqNNdp8-xNTXK8aGMPZu
인터넷에는Databricks인증 Databricks-Certified-Professional-Data-Engineer시험대비공부자료가 헤아릴수 없을 정도로 많습니다.이렇게 많은Databricks인증 Databricks-Certified-Professional-Data-Engineer공부자료중 대부분 분들께서 저희Pass4Test를 선택하는 이유는 덤프 업데이트가 다른 사이트보다 빠르다는 것이 제일 큰 이유가 아닐가 싶습니다. Pass4Test의 Databricks인증 Databricks-Certified-Professional-Data-Engineer덤프를 구매하시면 덤프가 업데이트되면 무료로 업데이트된 버전을 제공받을수 있습니다.
Databricks Certified Professional Data Engineer 시험은 Databricks를 사용하여 대규모 데이터를 처리하는 데 전문성을 증명하려는 데이터 엔지니어들에게 탁월한 선택입니다. 이 자격증 시험은 전 세계적으로 인정되며 Databricks를 사용하는 기관에서 높은 가치를 두고 있습니다. 시험에 통과함으로써, 데이터 엔지니어는 자신의 지식과 기술을 검증하고 경력 발전의 기회를 높일 수 있습니다.
>> Databricks-Certified-Professional-Data-Engineer시험대비 최신버전 덤프자료 <<
Databricks Databricks-Certified-Professional-Data-Engineer시험이 정말 어렵다는 말을 많이 들으신 만큼 저희 Pass4Test는Databricks Databricks-Certified-Professional-Data-Engineer덤프만 있으면Databricks Databricks-Certified-Professional-Data-Engineer시험이 정말 쉬워진다고 전해드리고 싶습니다. Databricks Databricks-Certified-Professional-Data-Engineer덤프로 시험패스하고 자격증 한방에 따보세요. 자격증 많이 취득하면 더욱 여유롭게 직장생활을 즐길수 있습니다.
이 시험은 Databricks를 사용하여 데이터 솔루션을 디자인하고 구현하는 경험을 갖고 있는 데이터 엔지니어를 대상으로 합니다. 이 인증을 위한 후보자는 데이터 엔지니어링 개념, 데이터 처리 프레임워크 및 Python, SQL과 같은 프로그래밍 언어에 대한 좋은 이해도를 가져야 합니다. 또한 AWS, Azure 및 Google Cloud Platform과 같은 클라우드 플랫폼에 익숙해야 합니다.
Databricks 인증 전문 데이터 엔지니어 시험은 벤더 중립적인 자격증으로, 특정 기술이나 제품에 특화되어 있지 않습니다. 이는 다른 대용량 데이터 기술을 사용하는 데이터 엔지니어들이 Databricks의 지식을 증명하고자 하는 경우에는 훌륭한 선택입니다. 이 자격증 시험은 전 세계적으로 인정받으며, 대용량 데이터 처리에 Databricks를 사용하는 조직들에게 매우 높은 가치를 두고 있습니다.
질문 # 93
A workspace admin has created a new catalog called finance_data and wants to delegate permission management to a finance team lead without giving them full admin rights.
Which privilege should be granted to the finance team lead?
정답:D
설명:
Comprehensive and Detailed Explanation From Exact Extract of Databricks Data Engineer Documents:
The MANAGE privilege in Unity Catalog provides the ability to grant and revoke privileges on the specified object (in this case, a catalog) without giving full administrative access or ownership.
This is the Databricks-recommended approach for delegating governance responsibilities while preserving the principle of least privilege.
By contrast, the ALL PRIVILEGES option grants excessive access (including read and write permissions), and metastore admin status provides global control over all catalogs-far exceeding the requirement. The MANAGE privilege enables the finance team lead to control access to objects within finance_data responsibly while limiting overall administrative exposure.
질문 # 94
An upstream system has been configured to pass the date for a given batch of data to the Databricks Jobs API as a parameter. The notebook to be scheduled will use this parameter to load data with the following code:
df = spark.read.format("parquet").load(f"/mnt/source/(date)")
Which code block should be used to create the date Python variable used in the above code block?
정답:B
설명:
The code block that should be used to create the date Python variable used in the above code block is:
dbutils.widgets.text("date", "null") date = dbutils.widgets.get("date") This code block uses the dbutils.widgets API to create and get a text widget named "date" that can accept a string value as a parameter1. The default value of the widget is "null", which means that if no parameter is passed, the date variable will be "null". However, if a parameter is passed through the Databricks Jobs API, the date variable will be assigned the value of the parameter. For example, if the parameter is "2021-11-01", the date variable will be "2021-11-01". This way, the notebook can use the date variable to load data from the specified path.
The other options are not correct, because:
* Option A is incorrect because spark.conf.get("date") is not a valid way to get a parameter passed through the Databricks Jobs API. The spark.conf API is used to get or set Spark configuration properties, not notebook parameters2.
* Option B is incorrect because input() is not a valid way to get a parameter passed through the Databricks Jobs API. The input() function is used to get user input from the standard input stream, not from the API request3.
* Option C is incorrect because sys.argv1 is not a valid way to get a parameter passed through the Databricks Jobs API. The sys.argv list is used to get the command-line arguments passed to a Python script, not to a notebook4.
* Option D is incorrect because dbutils.notebooks.getParam("date") is not a valid way to get a parameter passed through the Databricks Jobs API. The dbutils.notebooks API is used to get or set notebook parameters when running a notebook as a job or as a subnotebook, not when passing parameters through the API5.
References: Widgets, Spark Configuration, input(), sys.argv, Notebooks
질문 # 95
A junior member of the data engineering team is exploring the language interoperability of Databricks notebooks. The intended outcome of the below code is to register a view of all sales that occurred in countries on the continent of Africa that appear in the geo_lookup table.
Before executing the code, running SHOW TABLES on the current database indicates the database contains only two tables: geo_lookup and sales .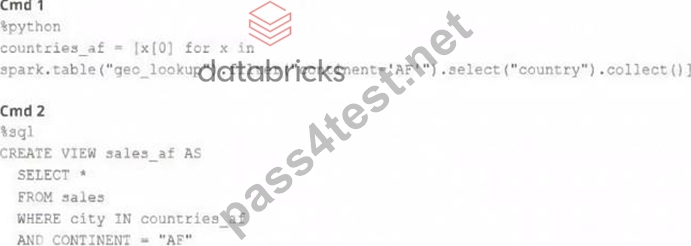
Which statement correctly describes the outcome of executing these command cells in order in an interactive notebook?
정답:E
설명:
This is the correct answer because Cmd 1 is written in Python and uses a list comprehension to extract the country names from the geo_lookup table and store them in a Python variable named countries af. This variable will contain a list of strings, not a PySpark DataFrame or a SQL view. Cmd 2 is written in SQL and tries to create a view named sales af by selecting from the sales table where city is in countries af. However, this command will fail because countries af is not a valid SQL entity and cannot be used in a SQL query. To fix this, a better approach would be to use spark.sql() to execute a SQL query in Python and pass the countries af variable as a parameter. Verified References: [Databricks Certified Data Engineer Professional], under
"Language Interoperability" section; Databricks Documentation, under "Mix languages" section.
질문 # 96
A data engineering team is migrating off its legacy Hadoop platform. As part of the process, they are evaluating storage formats for performance comparison. The legacy platform uses ORC and RCFile formats.
After converting a subset of data to Delta Lake , they noticed significantly better query performance. Upon investigation, they discovered that queries reading from Delta tables leveraged a Shuffle Hash Join , whereas queries on legacy formats used Sort Merge Joins . The queries reading Delta Lake data also scanned less data.
Which reason could be attributed to the difference in query performance?
정답:B
설명:
Delta Lake outperforms legacy Hadoop formats because it leverages Parquet-based storage , data skipping
, and file pruning . According to Databricks documentation, Delta Lake automatically stores detailed statistics (min/max values and file-level metadata) in the transaction log. During query planning, the engine uses these statistics to skip entire files that do not match query filters , a process called data skipping and file pruning . Additionally, Delta uses a vectorized Parquet reader , which reduces I/O and CPU overhead.
Together, these optimizations allow Delta to scan significantly less data and produce more efficient physical query plans (e.g., Shuffle Hash Join instead of Sort Merge Join). The performance gain is due to efficient data skipping, not the inherent superiority of join type.
질문 # 97
Question-3: In machine learning, feature hashing, also known as the hashing trick (by analogy to the kernel
trick), is a fast and space-efficient way of vectorizing features (such as the words in a language), i.e., turning
arbitrary features into indices in a vector or matrix. It works by applying a hash function to the features and
using their hash values modulo the number of features as indices directly, rather than looking the indices up in
an associative array. So what is the primary reason of the hashing trick for building classifiers?
정답:D
설명:
Explanation
This hashed feature approach has the distinct advantage of requiring less memory and one less pass through
the training data, but it can make it much harder to reverse engineer vectors to determine which original
feature mapped to a vector location. This is because multiple features may hash to the same location. With
large vectors or with multiple locations per feature, this isn't a problem for accuracy but it can make it hard to
understand what a classifier is doing.
Models always have a coefficient per feature, which are stored in memory during model building. The hashing
trick collapses a high number of features to a small number which reduces the number of coefficients and thus
memory requirements. Noisy features are not removed; they are combined with other features and so still have
an impact.
The validity of this approach depends a lot on the nature of the features and problem domain; knowledge of
the domain is important to understand whether it is applicable or will likely produce poor results. While
hashing features may produce a smaller model, it will be one built from odd combinations of real-world
features, and so will be harder to interpret.
An additional benefit of feature hashing is that the unknown and unbounded vocabularies typical of word-like
variables aren't a problem.
질문 # 98
......
Databricks-Certified-Professional-Data-Engineer시험기출문제: https://www.pass4test.net/Databricks-Certified-Professional-Data-Engineer.html
Pass4Test Databricks-Certified-Professional-Data-Engineer 최신 PDF 버전 시험 문제집을 무료로 Google Drive에서 다운로드하세요: https://drive.google.com/open?id=1SgXcieROQBhvuqNNdp8-xNTXK8aGMPZu