DOWNLOAD the newest Real4Prep MLA-C01 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1KMAcSKQLmQv9gfNBu4pIB0sSb-DQVeke
Good news comes that our company has successfully launched the new version of the MLA-C01 guide tests. Perhaps you are deeply bothered by preparing the exam; perhaps you have wanted to give it up. Now, you can totally feel relaxed with the assistance of our MLA-C01 Actual Test. It is very worthy for you to buy our product. Not only can our study materials help you pass the exam, but also it can save your much time. What are you waiting for? Follow your passion and heart.
| Certification Vendor: | Amazon Web Services (AWS) |
|---|---|
| Exam Name: | AWS Certified Machine Learning Engineer – Associate (MLA-C01) |
| Exam Number: | MLA-C01 |
| Related Certifications: | AWS Certified Solutions Architect – Associate AWS Certified AI Practitioner AWS Certified DevOps Engineer – Professional AWS Certified Data Engineer – Associate |
| Exam Duration: | 130 minutes |
| Exam Price: | USD 150 |
| Real Exam Qty: | 65 scored questions + 15 unscored questions |
| Passing Score: | 720/1000 |
| Certificate Validity Period: | 3 years |
| Available Languages: | Japanese, Simplified Chinese, Korean, English |
| Exam Format: | Multiple response, Matching, Multiple choice, Ordering |
| Recommended Training: | AWS Skill Builder - ML Engineer Associate Exam Prep Amazon SageMaker Documentation |
| Exam Registration: | AWS Certification Registration |
| Sample Questions: | Amazon MLA-C01 Sample Questions |
| Exam Way: | Online proctored or test center exam |
| Pre Condition: | Recommended: ~1 year experience with Amazon SageMaker and AWS-based ML or data engineering roles |
| Official Syllabus URL: | https://aws.amazon.com/certification/certified-machine-learning-engineer-associate/ |
The desktop practice test format comes with all features of the web-based practice exam. Real4Prep has made all of the different formats so the exam applicants won't face any additional issues and prepare themselves with the real questions and crack Amazon MLA-C01 Certification test for the betterment of their futures. One can set the time and questions numbers of practice exams (desktop and web-based) according to their needs. Real4Prep is giving multiple mock exams to the customers so they can practice and make themselves perfect.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
| Topic 4 |
|
NEW QUESTION # 75
Case Study
A company is building a web-based AI application by using Amazon SageMaker. The application will provide the following capabilities and features: ML experimentation, training, a central model registry, model deployment, and model monitoring.
The application must ensure secure and isolated use of training data during the ML lifecycle. The training data is stored in Amazon S3.
The company needs to use the central model registry to manage different versions of models in the application.
Which action will meet this requirement with the LEAST operational overhead?
Answer: D
Explanation:
Amazon SageMaker Model Registry is a feature designed to manage machine learning (ML) models throughout their lifecycle. It allows users to catalog, version, and deploy models systematically, ensuring efficient model governance and management.
Key Features of SageMaker Model Registry:
* Centralized Cataloging: Organizes models intoModel Groups, each containing multiple versions.
* Version Control: Maintains a history of model iterations, making it easier to track changes.
* Metadata Association: Attach metadata such as training metrics and performance evaluations to models.
* Approval Status Management: Allows setting statuses like PendingManualApproval or Approved to ensure only vetted models are deployed.
* Seamless Deployment: Direct integration with SageMaker deployment capabilities for real-time inference or batch processing.
Implementation Steps:
* Create a Model Group: Organize related models into groups to simplify management and versioning.
* Register Model Versions: Each model iteration is registered as a version within a specific Model Group.
* Set Approval Status: Assign approval statuses to models before deploying them to ensure quality control.
* Deploy the Model: Use SageMaker endpoints for deployment once the model is approved.
Benefits:
* Centralized Management: Provides a unified platform to manage models efficiently.
* Streamlined Deployment: Facilitates smooth transitions from development to production.
* Governance and Compliance: Supports metadata association and approval processes.
By leveraging the SageMaker Model Registry, the company can ensure organized management of models, version control, and efficient deployment workflows with minimal operational overhead.
References:
* AWS Documentation: SageMaker Model Registry
* AWS Blog: Model Registry Features and Usage
NEW QUESTION # 76
A company has implemented a data ingestion pipeline for sales transactions from its ecommerce website. The company uses Amazon Data Firehose to ingest data into Amazon OpenSearch Service. The buffer interval of the Firehose stream is set for 60 seconds. An OpenSearch linear model generates real-time sales forecasts based on the data and presents the data in an OpenSearch dashboard.
The company needs to optimize the data ingestion pipeline to support sub-second latency for the real-time dashboard.
Which change to the architecture will meet these requirements?
Answer: B
Explanation:
The primary requirement in this scenario is achieving sub-second latency for a real-time analytics dashboard powered by Amazon OpenSearch Service. The current architecture uses Amazon Data Firehose, which buffers incoming records based on time or size before delivering them to the destination. A buffer interval of
60 seconds introduces unavoidable latency, making it unsuitable for near-real-time or sub-second use cases.
According to AWS documentation, reducing or eliminating buffering in Firehose is the correct approach when low-latency ingestion is required. Setting the Firehose buffer interval to zero seconds forces Firehose to deliver records as soon as they are received. Additionally, tuning the PutRecordBatch batch size allows efficient ingestion while minimizing delivery delay. This configuration is explicitly recommended for latency- sensitive analytics pipelines.
Option B is incorrect because AWS DataSync is designed for batch-oriented data transfers between storage systems, not real-time streaming. Enhanced fan-out consumers are a feature of Amazon Kinesis Data Streams, not DataSync, making this option invalid.
Option C directly contradicts the requirement. Increasing the buffer interval from 60 seconds to 120 seconds would further increase latency and degrade real-time performance.
Option D is also incorrect because Amazon SQS is a message queueing service, not a streaming ingestion service optimized for indexing data into OpenSearch with minimal latency. Using SQS would add additional processing layers and would not inherently provide sub-second ingestion into OpenSearch.
Therefore, using zero buffering in the Firehose stream and tuning the PutRecordBatch batch size is the only change that aligns with AWS best practices for achieving sub-second latency in real-time analytics pipelines.
NEW QUESTION # 77
A company is building an enterprise AI platform. The company must catalog models for production, manage model versions, and associate metadata such as training metrics with models. The company needs to eliminate the burden of managing different versions of models.
Which solution will meet these requirements?
Answer: D
Explanation:
The correct answer is B. Use the Amazon SageMaker Model Registry to catalog the models. Create model groups for each model to manage the model versions and to maintain associated metadata.
The Amazon SageMaker Model Registry is a managed repository within SageMaker designed specifically for production-grade ML model lifecycle management. It allows organizations to catalog models, track multiple versions of a model, associate rich metadata, and manage deployment workflows in a scalable, controlled manner. Each model can belong to a model group, which acts as a container for all versions of that particular model. Versions can store training metrics, hyperparameters, model artifacts, and other key metadata, enabling reproducibility, auditing, and automated promotion between stages (e.g., Staging # Production).
Option A, while using the Model Registry, relies on manually tagging versions and creating key-value pairs to store metadata. This approach is error-prone, lacks structured versioning, and does not integrate with SageMaker's deployment pipelines.
Options C and D suggest using Amazon ECR repositories. While ECR can store containerized model artifacts, it is not designed for ML-specific metadata, versioning, or automated model stage transitions. Using ECR alone would require custom-built solutions for metadata management, auditing, and version tracking, adding unnecessary operational overhead.
By leveraging the Model Registry with model groups, organizations can automate promotions, apply approval workflows, and track lineage efficiently, fully aligning with AWS best practices for ML model development and production readiness. This ensures compliance, reproducibility, and reduces operational complexity in enterprise AI platforms.
Using the Model Registry and model groups is the standard AWS-recommended approach for enterprise-scale model cataloging and version control, enabling teams to focus on model improvement rather than infrastructure management.
NEW QUESTION # 78
A company wants to improve the sustainability of its ML operations.
Which actions will reduce the energy usage and computational resources that are associated with the company
' s training jobs? (Choose two.)
Answer: D,E
Explanation:
SageMaker Debugger can identify when a training job is not converging or is stuck in a non-productive state.
By stopping these jobs early, unnecessary energy and computational resources are conserved, improving sustainability.
AWS Trainium instances are purpose-built for ML training and are optimized for energy efficiency and cost- effectiveness. They use less energy per training task compared to general-purpose instances, making them a sustainable choice.
NEW QUESTION # 79
A company needs to update the model definition of an existing Amazon SageMaker Al endpoint.
Select and order the correct steps from the following list to update the model definition settings with the LEAST interruption of inferences. Select each step one time or not at all. (Select and order THREE.)
* Create a new endpoint configuration that uses the new model definition.
* Create a new model definition with updated settings by using the CreateModel action in the SageMaker AI API.
* Delete the endpoint that needs to be updated and recreate the endpoint with the new endpoint configuration.
* Delete the IAM role and permissions for the ExecutionRoleArn parameter.
* Update the endpoint with the new endpoint configuration.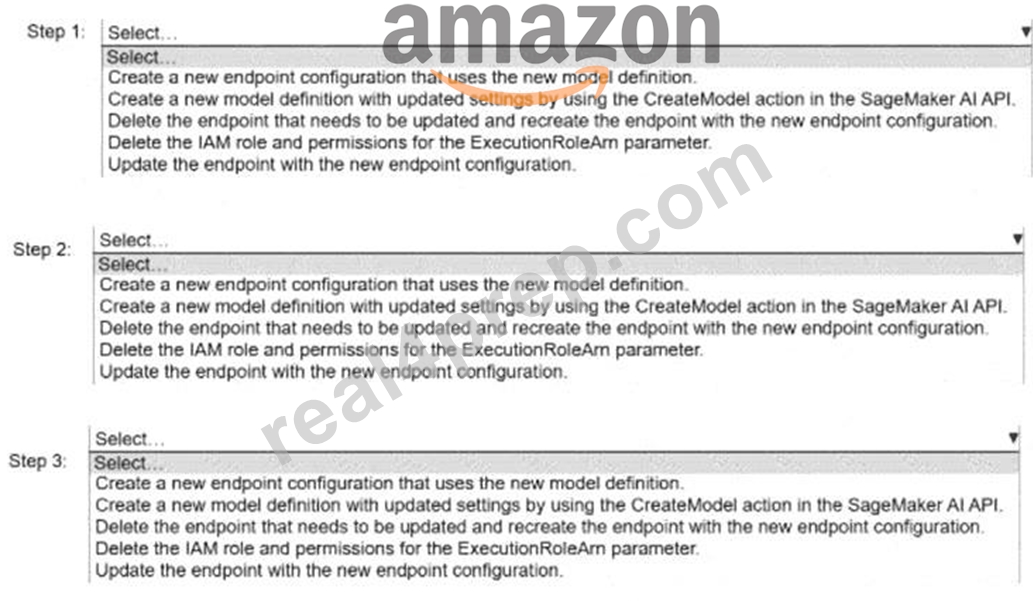
Answer:
Explanation: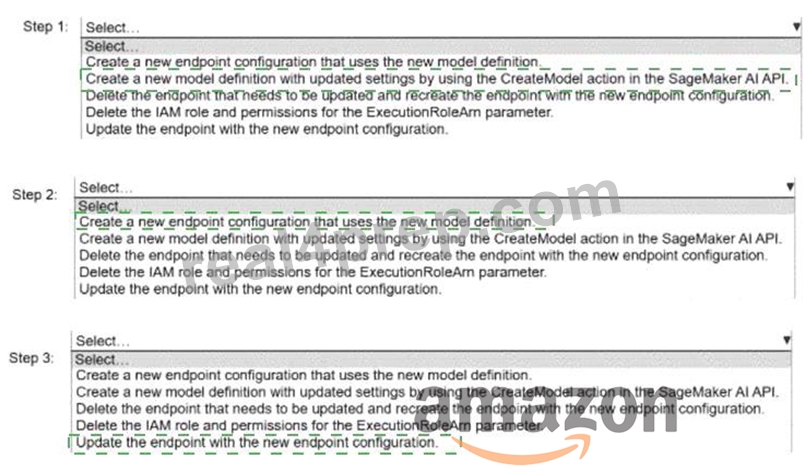
Explanation:
Step 1: Create a new model definition with updated settings by using the CreateModel action in the SageMaker AI API.
Step 2: Create a new endpoint configuration that uses the new model definition.
Step 3: Update the endpoint with the new endpoint configuration.
Do not delete and recreate the endpoint. That causes unnecessary inference interruption. SageMaker endpoint updates are designed to use a new EndpointConfig; AWS explicitly states that to update an endpoint, you must create a new endpoint configuration, then call UpdateEndpoint on the existing endpoint. During the update, SageMaker changes the endpoint to Updating and then back to InService.
NEW QUESTION # 80
......
Interactive MLA-C01 Questions: https://www.real4prep.com/MLA-C01-exam.html
BTW, DOWNLOAD part of Real4Prep MLA-C01 dumps from Cloud Storage: https://drive.google.com/open?id=1KMAcSKQLmQv9gfNBu4pIB0sSb-DQVeke