Databricks Certified Professional Data Engineer Exam Certification Sample Questions and Practice Exam

As the tech industry continues to evolve and adapt to new technologies, professionals who hold the Databricks Certified Professional Data Engineer Exam (Databricks-Certified-Professional-Data-Engineer) certification are better equipped to navigate these changes and stay ahead of the curve, increasing their value to employers and clients. In today's fast-paced and ever-changing Databricks sector, having the Databricks Certified Professional Data Engineer Exam (Databricks-Certified-Professional-Data-Engineer) certification has become a necessary requirement for individuals looking to advance their careers and stay competitive in the job market.
| Section | Objectives |
|---|
| Production Pipelines and Orchestration | - Automate ETL pipelines and scheduling
- Build and manage workflows using Databricks Jobs
- Pipeline reliability and fault tolerance
|
| Data Ingestion and Transformation | - Transform and clean datasets using Spark SQL and DataFrame APIs
- Ingest data using Apache Spark and Databricks
- Handle batch and streaming data pipelines
|
| Data Modeling and Storage | - Delta Lake table design and optimization
- Design scalable data lakehouse architectures
- Schema evolution and data partitioning strategies
|
| Security, Governance, Monitoring, and Optimization | - Cost optimization and performance tuning
- Monitor and optimize Spark workloads
- Implement Unity Catalog governance and access control
|
>> Databricks-Certified-Professional-Data-Engineer Reliable Exam Braindumps <<
Free PDF Databricks - Databricks-Certified-Professional-Data-Engineer –Professional Reliable Exam Braindumps
With the best quality and high accuracy, our Databricks-Certified-Professional-Data-Engineer vce braindumps are the best study materials for the certification exam among the dumps vendors. Our experts constantly keep the pace of the current exam requirement for Databricks-Certified-Professional-Data-Engineer Actual Test to ensure the accuracy of our questions. The pass rate of our Databricks-Certified-Professional-Data-Engineer exam dumps almost reach to 98% because our questions and answers always updated according to the latest exam information.
Databricks Certified Professional Data Engineer Exam Sample Questions (Q61-Q66):
NEW QUESTION # 61
The security team is exploring whether or not the Databricks secrets module can be leveraged for connecting to an external database.
After testing the code with all Python variables being defined with strings, they upload the password to the secrets module and configure the correct permissions for the currently active user. They then modify their code to the following (leaving all other variables unchanged).
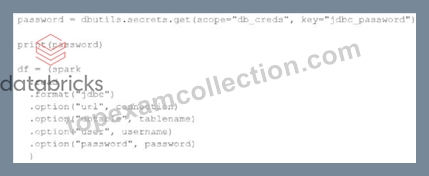
Which statement describes what will happen when the above code is executed?
- A. The connection to the external table will succeed; the string value of password will be printed in plain text.
- B. An interactive input box will appear in the notebook; if the right password is provided, the connection will succeed and the password will be printed in plain text.
- C. An interactive input box will appear in the notebook; if the right password is provided, the connection will succeed and the encoded password will be saved to DBFS.
- D. The connection to the external table will succeed; the string "redacted" will be printed.
- E. The connection to the external table will fail; the string "redacted" will be printed.
Answer: D
Explanation:
This is the correct answer because the code is using the dbutils.secrets.get method to retrieve the password from the secrets module and store it in a variable. The secrets module allows users to securely store and access sensitive information such as passwords, tokens, or API keys. The connection to the external table will succeed because the password variable will contain the actual password value. However, when printing the password variable, the string "redacted" will be displayed instead of the plain text password, as a security measure to prevent exposing sensitive information in notebooks. Verified References: [Databricks Certified Data Engineer Professional], under "Security & Governance" section; Databricks Documentation, under
"Secrets" section.
NEW QUESTION # 62
What is a method of installing a Python package scoped at the notebook level to all nodes in the currently active cluster?
- A. Use &sh install in a notebook cell
- B. Run source env/bin/activate in a notebook setup script
- C. Use &Pip install in a notebook cell
- D. Install libraries from PyPi using the cluster UI
Answer: C
Explanation:
In Databricks notebooks, you can use the %pip install command in a notebook cell to install a Python package. This will install the package on all nodes in the currently active cluster at the notebook level. It is a feature provided by Databricks to facilitate the installation of Python libraries for the notebook environment specifically.
NEW QUESTION # 63
A data engineer is attempting to execute the following PySpark code:
df = spark.read.table("sales")
result = df.groupBy("region").agg(sum("revenue"))
However, upon inspecting the execution plan and profiling the Spark job, they observe excessive data shuffling during the aggregation phase.
Which technique should be applied to reduce shuffling during the groupBy aggregation operation?
- A. Repartition by region before aggregation.
- B. Use coalesce() after the aggregation.
- C. Use broadcast join.
- D. Caching the DataFrame df.
Answer: A
Explanation:
Comprehensive and Detailed Explanation From Exact Extract of Databricks Data Engineer Documents:
Databricks documents that shuffle occurs when Spark redistributes data across partitions for grouping or joining. To optimize aggregation performance, repartitioning by the grouping key (region) ensures rows with the same key are co-located in the same partition, thus minimizing shuffle movement. Caching improves reuse of DataFrames but does not reduce shuffle volume. coalesce() reduces the number of partitions after computation and cannot prevent shuffle. Broadcast joins are unrelated to single-table aggregations. The recommended practice for reducing shuffle in aggregation is explicit repartitioning by the grouping column.
NEW QUESTION # 64
Review the following error traceback:
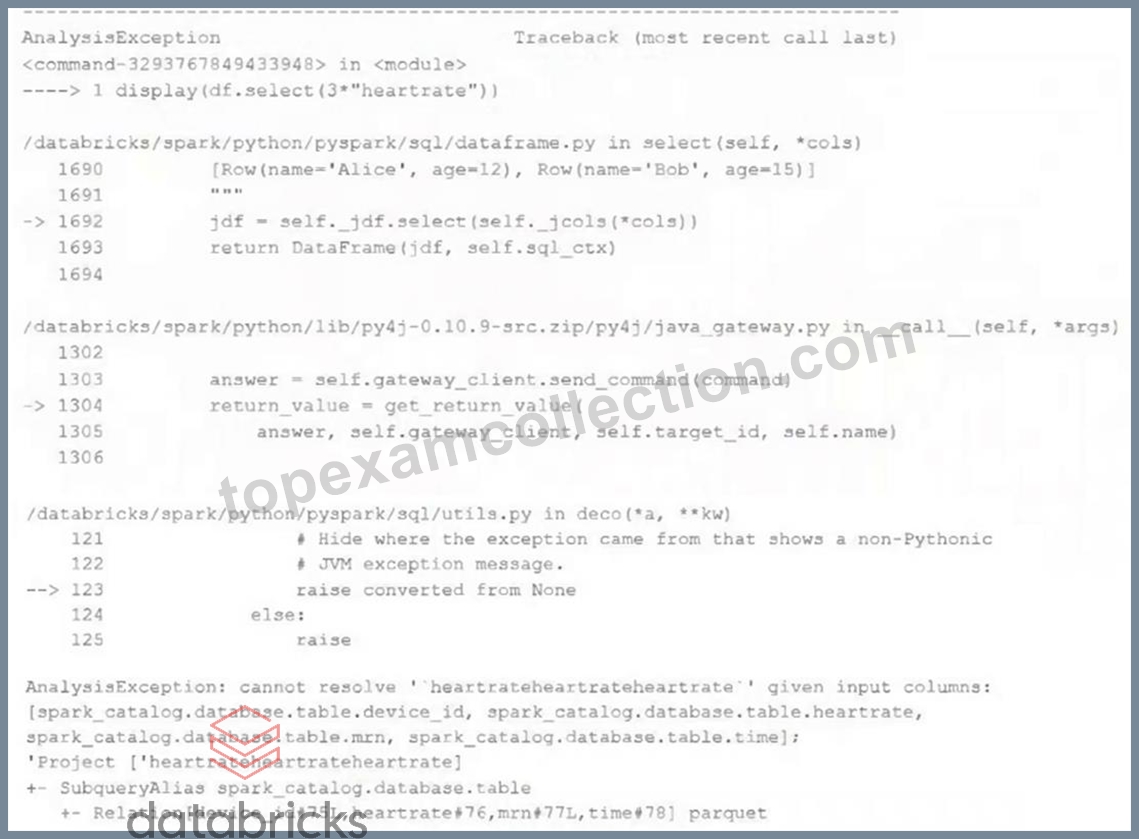
Which statement describes the error being raised?
- A. There is a type error because a column object cannot be multiplied.
- B. There is a syntax error because the heartrate column is not correctly identified as a column.
- C. The code executed was PvSoark but was executed in a Scala notebook.
- D. There is a type error because a DataFrame object cannot be multiplied.
- E. There is no column in the table named heartrateheartrateheartrate
Answer: E
Explanation:
The error being raised is an AnalysisException, which is a type of exception that occurs when Spark SQL cannot analyze or execute a query due to some logical or semantic error 1 . In this case, the error message indicates that the query cannot resolve the column name 'heartrateheartrateheartrate' given the input columns
'heartrate' and 'age'. This means that there is no column in the table named 'heartrateheartrateheartrate', and the query is invalid. A possible cause of this error is a typo or a copy-paste mistake in the query. To fix this error, the query should use a valid column name that exists in the table, such as
'heartrate'. References: AnalysisException
NEW QUESTION # 65
A data architect is designing a Databricks solution to efficiently process data for different business requirements.
In which scenario should a data engineer use a materialized view compared to a streaming table?
- A. Processing high-volume, continuous clickstream data from a website to monitor user behavior in real-time.
- B. Precomputing complex aggregations and joins from multiple large tables to accelerate BI dashboard performance.
- C. Ingesting data from Apache Kafka topics with sub-second processing requirements for immediate alerting.
- D. Implementing a CDC (Change Data Capture) pipeline that needs to detect and respond to database changes within seconds.
Answer: B
Explanation:
Comprehensive and Detailed Explanation From Exact Extract of Databricks Data Engineer Documents:
Materialized views in Databricks are optimized for precomputing and caching results of complex SQL queries, joins, and aggregations. They store query outputs physically and automatically refresh on a schedule or incremental change basis, drastically improving BI dashboard performance and reducing compute costs.
Conversely, streaming tables are designed for real-time data ingestion and processing, enabling event-driven analytics and low-latency use cases.
Databricks documentation explicitly recommends materialized views for analytical workloads with periodic updates and streaming tables for continuously updating sources. Therefore, the correct choice is C, where complex aggregations from large tables benefit most from materialized precomputation for fast reporting.
NEW QUESTION # 66
......
As a dumps provider, TopExamCollection have a good reputation in the field. We are equipped with a team of IT elites who do much study in the Databricks test questions and training materials. We check the updating of Databricks-Certified-Professional-Data-Engineer Dumps PDF everyday to make sure you pass Databricks-Certified-Professional-Data-Engineer valid test easily. The pass rate will be 100%.
Databricks-Certified-Professional-Data-Engineer Reliable Study Guide: https://www.topexamcollection.com/Databricks-Certified-Professional-Data-Engineer-vce-collection.html
- Reliable Databricks-Certified-Professional-Data-Engineer Test Labs 🌑 Databricks-Certified-Professional-Data-Engineer Study Test 🏋 Databricks-Certified-Professional-Data-Engineer PDF Download 🏢 Search for 《 Databricks-Certified-Professional-Data-Engineer 》 and obtain a free download on [ www.troytecdumps.com ] 🕖Simulation Databricks-Certified-Professional-Data-Engineer Questions
- Online Databricks-Certified-Professional-Data-Engineer Test 🍍 Valid Databricks-Certified-Professional-Data-Engineer Exam Pattern 🌐 Databricks-Certified-Professional-Data-Engineer Latest Exam Dumps 🐟 Copy URL ▶ www.pdfvce.com ◀ open and search for ▛ Databricks-Certified-Professional-Data-Engineer ▟ to download for free 📪Databricks-Certified-Professional-Data-Engineer Training Tools
- Quiz 2026 Valid Databricks-Certified-Professional-Data-Engineer: Databricks Certified Professional Data Engineer Exam Reliable Exam Braindumps 🔒 Open website ➽ www.exam4labs.com 🢪 and search for ▶ Databricks-Certified-Professional-Data-Engineer ◀ for free download 📅Free Databricks-Certified-Professional-Data-Engineer Exam
- Quiz 2026 Valid Databricks-Certified-Professional-Data-Engineer: Databricks Certified Professional Data Engineer Exam Reliable Exam Braindumps 🌆 Easily obtain ▷ Databricks-Certified-Professional-Data-Engineer ◁ for free download through ➤ www.pdfvce.com ⮘ 🕡Databricks-Certified-Professional-Data-Engineer Boot Camp
- Quiz 2026 Valid Databricks-Certified-Professional-Data-Engineer: Databricks Certified Professional Data Engineer Exam Reliable Exam Braindumps 🆒 Easily obtain free download of ☀ Databricks-Certified-Professional-Data-Engineer ️☀️ by searching on ➡ www.practicevce.com ️⬅️ 🎈Databricks-Certified-Professional-Data-Engineer Boot Camp
- Quiz 2026 Valid Databricks-Certified-Professional-Data-Engineer: Databricks Certified Professional Data Engineer Exam Reliable Exam Braindumps 🏕 Open ✔ www.pdfvce.com ️✔️ enter ➡ Databricks-Certified-Professional-Data-Engineer ️⬅️ and obtain a free download 🎬Valid Databricks-Certified-Professional-Data-Engineer Exam Pattern
- Test Databricks-Certified-Professional-Data-Engineer Discount Voucher 🍒 Reliable Databricks-Certified-Professional-Data-Engineer Test Labs 💅 Exam Databricks-Certified-Professional-Data-Engineer Pattern 🏈 Open website “ www.prepawayexam.com ” and search for [ Databricks-Certified-Professional-Data-Engineer ] for free download 📕Free Databricks-Certified-Professional-Data-Engineer Exam
- Reliable Databricks-Certified-Professional-Data-Engineer Study Notes 🈵 Databricks-Certified-Professional-Data-Engineer Valid Exam Forum 🚒 Databricks-Certified-Professional-Data-Engineer Valid Exam Forum 👮 Search on ☀ www.pdfvce.com ️☀️ for ➡ Databricks-Certified-Professional-Data-Engineer ️⬅️ to obtain exam materials for free download ❕Databricks-Certified-Professional-Data-Engineer Test Dumps Free
- Valid Databricks-Certified-Professional-Data-Engineer Exam Materials 🚗 Valid Databricks-Certified-Professional-Data-Engineer Exam Pattern 🏌 Updated Databricks-Certified-Professional-Data-Engineer Testkings 🐲 Go to website ➤ www.dumpsquestion.com ⮘ open and search for ➤ Databricks-Certified-Professional-Data-Engineer ⮘ to download for free 🎉Databricks-Certified-Professional-Data-Engineer Valid Exam Forum
- Updated Databricks-Certified-Professional-Data-Engineer Testkings ➖ Databricks-Certified-Professional-Data-Engineer Latest Exam Dumps 🧦 Databricks-Certified-Professional-Data-Engineer Test Dumps Free 📞 Immediately open ⮆ www.pdfvce.com ⮄ and search for ▶ Databricks-Certified-Professional-Data-Engineer ◀ to obtain a free download 🙃Databricks-Certified-Professional-Data-Engineer Valid Exam Forum
- The advent of Databricks certification Databricks-Certified-Professional-Data-Engineer exam practice questions and answers 🐻 Search for ⇛ Databricks-Certified-Professional-Data-Engineer ⇚ and obtain a free download on ➽ www.practicevce.com 🢪 🕢Exam Databricks-Certified-Professional-Data-Engineer Pattern
- me.muz.li, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, zenwriting.net, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes