P.S. Free 2026 Nutanix NCP-BC-7.5 dumps are available on Google Drive shared by It-Tests: https://drive.google.com/open?id=1JB_LszTVrdcZ_cL-Tc5vplBFDXGZFvj3
We believe that every customer pays most attention to quality when he is shopping. Only high-quality goods can meet the needs of every customer better. And our NCP-BC-7.5 study materials have such high quality, because its hit rate of test questions is extremely high. Perhaps you will find in the examination that a lot of questions you have seen many times in our NCP-BC-7.5 Study Materials. In addition, the passing rate is the best test for quality of study materials. And we can be very proud to tell you that the passing rate of our NCP-BC-7.5 study materials is almost 100 %.
| Section | Objectives |
|---|---|
| Topic 1: Monitoring, Testing and Troubleshooting | - Non-disruptive recovery testing - Diagnosing network, storage and replication failures - Setting up alerts for replication lag - Resolving third-party backup integration problems - Documenting runbooks for incident response - Troubleshooting permission issues and misconfigured DR environments |
| Topic 2: Replication and Failover Architecture | - Network segmentation for BCDR environments - Failover readiness validation - Recovery site capacity management - Synchronous replication across sites - Asynchronous replication planning |
| Topic 3: BCDR Fundamentals and Requirements Interpretation | - Selecting appropriate replication types (async, near-sync, synchronous, metro) - Understanding RTO and RPO concepts and business impact analysis - Availability metrics and SLA definitions - Defining recovery strategies aligned to business requirements and risk tolerance - Translating business requirements into resilient recovery architectures |
| Topic 4: Security and Hardening | - Approval policies configuration - Designing secure BCDR environments - Security best practices for replication - RBAC implementation for disaster recovery |
| Topic 5: Nutanix Disaster Recovery Solutions | - Metro Availability configuration and management - Recovery workflows using Nutanix native tools - Configuring and managing replication policies - Failover procedures and execution - Integration with third-party backup solutions |
| Topic 6: Data Protection and Snapshots | - Snapshot scheduling and management - Storage configuration for BCDR - Data restoration at VM and application level - Snapshot retention policies design - Incremental backup implementation |
>> NCP-BC-7.5 Instant Discount <<
As is known to us, a good product is not only reflected in the strict management system, complete quality guarantee system but also the fine pre-sale and after-sale service system. In order to provide the best NCP-BC-7.5 study materials for all people, our company already established the integrate quality manage system, before sell serve and promise after sale. If you buy the NCP-BC-7.5 Study Materials from our company, we can make sure that you will have the right to enjoy the 24 hours full-time online service.
NEW QUESTION # 91
Refer to Exhibit: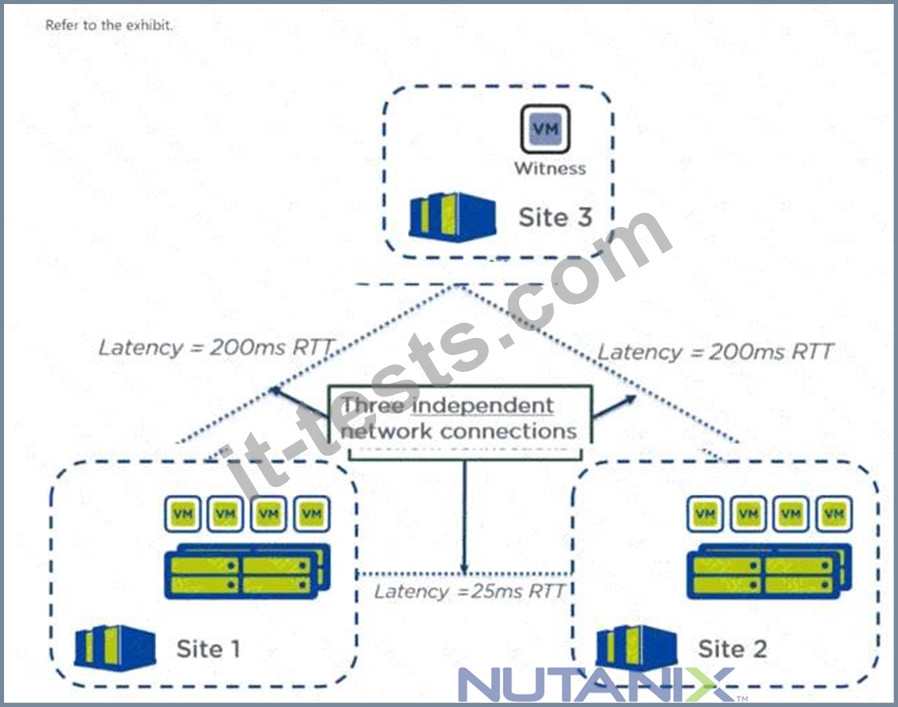
An administrator is configuring Metro Availability in their environment, as shown in the diagram. What issue in the configuration will prevent Metro from working correctly?
Answer: D
Explanation:
Nutanix Metro Availability and Synchronous Replication have very strict networking requirements to ensure that real-time data mirroring does not introduce unacceptable application latency. The industry-standard requirement for Nutanix synchronous operations is a maximum Round Trip Time (RTT) latency of 5ms between the two primary clusters (Site 1 and Site 2). According to the diagram provided in the question, the latency between Site 1 and Site 2 is 25ms RTT. This latency is significantly higher than the 5ms threshold and will prevent the Metro Availability configuration from functioning correctly. While the latency to the Witness VM (200ms RTT) is perfectly acceptable (Option D), and having a Witness at a third site (Option A) is a best practice, the " data path " between the storage clusters is the bottleneck here. If an administrator attempts to enable Metro with 25ms of latency, the guest VMs would experience severe performance degradation because every write would be delayed by the 25ms it takes to receive an acknowledgment from the remote site.
Therefore, the high latency between the data-serving sites is the primary configuration issue that must be resolved, typically by moving the clusters closer together or upgrading the inter-site fiber connection.
NEW QUESTION # 92
An administrator intends to configure a NearSync replication schedule with a 15-minute Recovery Point Objective (RPO) on a hybrid 3-node cluster. The current nodes in the cluster are configured with one SSD and four HDDs each. Which cost-effective modification is required to support this specific replication schedule?
Answer: A
Explanation:
Nutanix NearSync replication provides low RPOs (1 to 15 minutes) by using " Lightweight Snapshots " (LWS). NearSync has higher performance and hardware requirements than standard Asynchronous replication because it must handle metadata operations and data transfers much more frequently.
For a cluster to support NearSync, it must have sufficient high-performance storage to handle the additional I
/O load associated with LWS. On hybrid nodes (those with both SSDs and HDDs), Nutanix has a specific hardware requirement: each node must have at least two SSDs. This is because the NearSync LWS metadata and incoming replicated data are initially written to the SSD tier to ensure low latency and high throughput. A single SSD per node is typically insufficient to handle both active VM production I/O and the high-frequency NearSync overhead without performance degradation. Therefore, adding a second SSD to each node (Option D) is the mandatory modification. While upgrading to NVMe (Option A) or adding more nodes (Option B) would also improve performance, adding a second SSD is the minimum " cost-effective " requirement specified by Nutanix engineering for NearSync support on hybrid clusters. Meeting these hardware prerequisites is essential to ensure that the cluster can maintain the 15-minute RPO without transitioning back to an hourly schedule due to resource constraints.
NEW QUESTION # 93
An administrator at a retail company is preparing to apply a critical OS security patch to a production SQL Server VM. Before starting, the administrator ensures the VM is part of a Protection Domain and manually creates a local snapshot (Recovery Point). Ten minutes after the patch is applied, the SQL service fails to start, and the database logs indicate corruption in the system registry. The administrator needs to return the VM to its functional state from ten minutes ago as quickly as possible. The administrator decides to perform a Restore from the local snapshot. Under which condition would an In-place Restore (Revert) fail, forcing the administrator to use the Clone (Out-of-place) option instead?
Answer: D
Explanation:
An In-place Restore (Revert) is the fastest way to roll back a VM because it overwrites the current vDisks with the data from the snapshot. However, this operation has strict requirements regarding the consistency of the VM ' s hardware configuration. The most common technical blocker for an in-place revert is a change in the disk topology between the time the snapshot was taken and the time of the restore.
If the administrator added a new 50GB data disk (Option D) after taking the snapshot, the VM ' s current configuration now includes a vDisk that does not exist in the snapshot ' s metadata. Nutanix AOS cannot " revert " a disk that has no point-in-time reference in the recovery point. In this situation, the " In-place Restore
" button is typically disabled or will throw an error, forcing the administrator to use the " Clone " (Out-of- place) option. Cloning creates a new VM based exactly on the snapshot ' s metadata, effectively ignoring the newly added disk. While changing memory (Option B) or NGT versions (Option A) might affect performance or guest features, they do not usually prevent the storage-level revert operation. Being forced into a " Clone " restore increases the RTO slightly, as the administrator must then delete the corrupted VM and ensure the new clone has the correct network settings.
NEW QUESTION # 94
The Disaster Recovery dashboard in Prism Central shows that the protection domain is out of sync and new recovery points are no longer being created at the recovery site. No recent changes were made to the protection policy configuration or RPO settings. During initial troubleshooting, an administrator has observed the following:
* Production VMs are running normally at the primary site.
* The recovery cluster is reachable from Prism Central.
* No storage capacity alerts are seen on either cluster.
* A recent network change was implemented to enable network segmentation between clusters.
* New firewall rules were introduced recently as part of a security hardening effort.
Which action should the administrator take first when evaluating this issue?
Answer: A
Explanation:
Network segmentation is a powerful Nutanix feature used to isolate replication and storage traffic from standard management traffic. However, implementing this in a " brownfield " environment-where replication is already active-requires careful coordination. In this scenario, the replication failure coincides with the implementation of network segmentation and new firewall rules. The administrator ' s first action must be to verify if segmentation was enabled while replication was actively running. If segmentation is enabled on one site without a matching configuration on the remote cluster, or if the services (Cerebro
/Stargate) were not properly restarted to bind to the new interfaces, the replication stream will " hang " .
Furthermore, enabling segmentation changes the source and destination IP addresses used for replication traffic. If these new segmented IP addresses were not whitelisted in the recent firewall hardening effort, all " Snapshot-on-wire " traffic will be dropped. By verifying the segmentation state first, the administrator can determine if the network plumbing is consistent across both sites. Recreating policies (Option A) or triggering failover (Option C) would not resolve an underlying network isolation issue and would likely result in further failures until the segmentation and firewall rules are properly aligned.
NEW QUESTION # 95
What is the expected outcome that the administrator must manage?
Answer: B
Explanation:
This question refers to the behavior of Nutanix Metro Availability in conjunction with a Witness VM during a site-to-site communication failure. Metro Availability provides a zero-RPO, synchronous replication solution.
To prevent " split-brain " (where both sites try to serve the same data independently), the Witness VM acts as a tie-breaker. When the two clusters lose connectivity with each other, both will immediately attempt to contact the Witness to " acquire the lock " on the protection domain. The Witness is programmed to prioritize the original " Active " site. If the primary cluster can reach the Witness, it will successfully acquire the lock and continue serving I/O locally to the guest VMs, ensuring zero downtime for the applications. The secondary site, unable to reach the primary or acquire the lock from the Witness, will transition its storage container to an " Inactive " state to protect data integrity. The administrator must manage this state by ensuring the Witness is always reachable from both clusters via independent network paths. If the primary site cannot reach the Witness, it will stop serving I/O to prevent inconsistent data states, highlighting the critical importance of Witness availability in a high-availability BCDR design.
NEW QUESTION # 96
......
If you are already determined to obtain an international certificate, you must immediately purchase our NCP-BC-7.5 exam practice. Our products have been certified as the highest quality products in the industry. If you know NCP-BC-7.5 Training Materials through acquaintance introduction, then you must also know the advantages of NCP-BC-7.5. We are both perfect on the quality and the price of the NCP-BC-7.5 study braindumps.
Study NCP-BC-7.5 Test: https://www.it-tests.com/NCP-BC-7.5.html
DOWNLOAD the newest It-Tests NCP-BC-7.5 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1JB_LszTVrdcZ_cL-Tc5vplBFDXGZFvj3