P.S. Free 2026 Snowflake SPS-C01 dumps are available on Google Drive shared by TestBraindump: https://drive.google.com/open?id=1ydt5AryxJUzrGsnoQBF7l9gugZ7LYRyt
The software keeps track of the previous Snowflake Certified SnowPro Specialty - Snowpark (SPS-C01) practice exam attempts and shows the changes of each attempt. You don't need to wait days or weeks to get your performance report. The software displays the result of the Snowflake Certified SnowPro Specialty - Snowpark (SPS-C01) practice test immediately, which is an excellent way to understand which area needs more attention.
| Section | Objectives |
|---|---|
| Testing, Debugging, and Deployment | - Production readiness
|
| Data Engineering with Snowpark | - Pipeline development
|
| Performance Optimization and Best Practices | - Efficient Snowpark execution
|
| Snowpark Fundamentals | - Snowpark architecture and concepts
|
| DataFrame Operations and Data Processing | - Data transformation workflows
|
| User Defined Functions and Stored Procedures | - Extending Snowpark with custom logic
|
This is a crucial part of your study to know your mistakes and overcome them before the Snowflake SPS-C01 final test. Customizable test sessions allow you to modify the setting of the SPS-C01 mock test according to your training needs. Both Snowflake SPS-C01 Practice Tests desktop and web-based create a scenario that gives an exact feeling of the Snowflake SPS-C01 real test.
NEW QUESTION # 31
You have a Snowpark DataFrame 'customer data df containing customer information, including 'customer id', 'email', and phone number'. You need to anonymize the 'email' and 'phone number" columns for customers residing in specific countries (e.g., 'USA', 'Canada') before persisting the changes back to the 'customers' table. Anonymization should replace sensitive data with 'XXXXX'. You want to leverage UDF for obfuscation. What is correct and optimal approach considering performance and security?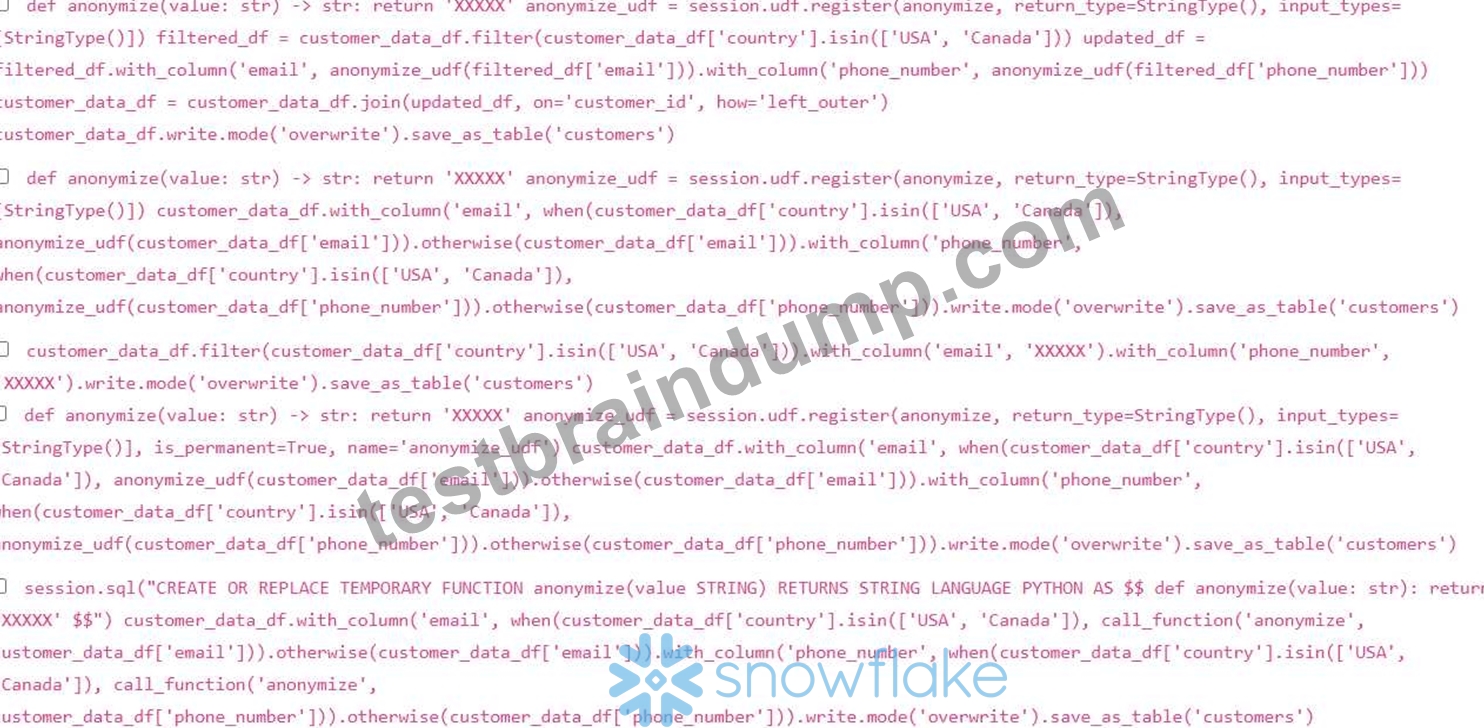
Answer: A,B
Explanation:
Options B and E provide the most efficient and secure solutions. Option B correctly utilizes the 'when' function along with a registered UDF ('anonymize_udf) to conditionally anonymize the 'email' and 'phone_number' columns only for customers in 'USA' or 'Canada'. This ensures that only the necessary data is modified. Option E creates and uses a temporary UDF with SQL, achieving the same result in a different (yet valid) way. Option A is less efficient because it filters the DataFrame, updates it, and then joins it back with the original, which can be computationally expensive. Additionally, join can produce cartesian results if not done properly. Option C, while straightforward, hardcodes the anonymized value directly, which might not be the best practice in all scenarios and doesn't use a UDF. Option D, although similar to B, attempts to create a permanent UDF without specifying the stage location, which may lead to errors and is not best practice unless you manage it. Also creating a UDF in Python using SQL can be faster and safer.
NEW QUESTION # 32
You are developing a Snowpark Python application that reads data from an external stage (AWS S3) and performs several transformations before loading it into a Snowflake table. During testing, you encounter the following error: net.snowflake.client.jdbc.SnowflakeSQLException: SQL compilation error: User does not have OWNERSHIP privilege on integration object 'YOUR INTEGRATION NAME". You have confirmed that the user has the 'USAGE privilege on the integration. Besides granting ownership, which of the following actions could resolve this issue in the MOST secure and efficient way?
Answer: C
Explanation:
Option B is the MOST secure and efficient. The error indicates that the user lacks necessary privileges to utilize the integration for creating objects (in this case, likely an internal stage used during the transformation process). Granting a custom role with both 'USAGE on the integration and 'CREATE TABLE on the database adheres to the principle of least privilege. Option A grants broad privileges to the user, which is less secure. Option C involves complex integration setup and might not be necessary for a simple data loading scenario. Option D is related to reading data from the external stage, not using the integration for internal operations. Option E bypasses the error without addressing the underlying permission issue.
NEW QUESTION # 33
Consider the following Snowpark code snippet: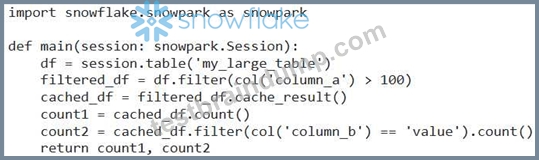
Which of the following statements are TRUE regarding the execution and performance of this code?
Answer: A,B,C
Explanation:
The 'filter' operation is executed only once because materializes the intermediate result. 'countl triggers the materialization. 'count? uses the cached data and applies an additional filter. Removing the caching would likely degrade performance because the initial filter would need to be recomputed for 'count?. Caching is beneficial when a DataFrame is used multiple times.
NEW QUESTION # 34
You have created a Python UDTF in Snowpark to process large volumes of image data'. This UDTF resizes each image and extracts certain features from it. The process is memory-intensive and sometimes fails due to Python process exceeding memory limits. You need to optimize this UDTF for memory usage. Which of the following strategies would be MOST effective? (Select TWO)
Answer: A,C
Explanation:
Lazy evaluation (B) and iterators allow processing data in smaller chunks, reducing memory consumption. Utilizing image compression techniques (D) reduces the memory footprint of each image, allowing more images to be processed within the available memory. Using scalar UDFs would not help and might perform worse. Decreasing the warehouse size would not solve the underlying problem and may make it worse. MAX_BATCH_SIZE determines how many records are sent over to UDF for each batch. It can help increasing performance but decreasing batch sizes might help with memory management, however its dependent on each case.
NEW QUESTION # 35
You have a Snowpark DataFrame with columns 'sale_date', 'product_id', and 'revenue'. You need to calculate the cumulative revenue for each product over time. Which of the following approaches will accomplish this in Snowpark using window functions?





Answer: C,D
Explanation:
Options A and E both achieve the desired result of calculating cumulative revenue for each product. Option A utilizes 'rowsBetween' specifying that the window frame should include all rows from the beginning ('Window.unboundedPreceding') up to the current row ('Window.currentRow'). This calculates a running sum of revenue for each product over time. Option E uses 'rangeBetween' , which is equivalent to when the order-by expression is of a numeric or date type. Option B does not partition by product_id, so the cumulative revenue is calculated over the entire dataset. Option C does not include frame specification 'rowsBetween()' or 'rangeBetween(Y , therefore defaults to 'RANGE BETWEEN UNBOUNDED PRECEDING AND CURRENT ROW, which is valid for this question. While it's functionally correct, it's implicit, so 'A' is preferrable if one option is to be selected. Option D partitions incorrectly by sale_date.
NEW QUESTION # 36
......
Now is not the time to be afraid to take any more difficult certification exams. Our SPS-C01 learning quiz can relieve you of the issue within limited time. Our website provides excellent SPS-C01 learning guidance, practical questions and answers, and questions for your choice which are your real strength. You can take the SPS-C01 Training Materials and pass it without any difficulty. As long as you can practice SPS-C01 study guide regularly and persistently your goals of making progress and getting certificates smoothly will be realized just like a piece of cake.
SPS-C01 Exam Outline: https://www.testbraindump.com/SPS-C01-exam-prep.html
P.S. Free & New SPS-C01 dumps are available on Google Drive shared by TestBraindump: https://drive.google.com/open?id=1ydt5AryxJUzrGsnoQBF7l9gugZ7LYRyt