試験Databricks Databricks-Certified-Professional-Data-Engineerトレーリング学習 &一番優秀なDatabricks-Certified-Professional-Data-Engineer受験資格 |大人気Databricks-Certified-Professional-Data-Engineer最新テスト

P.S. MogiExamがGoogle Driveで共有している無料かつ新しいDatabricks-Certified-Professional-Data-Engineerダンプ:https://drive.google.com/open?id=1AHQT0jlcyeFvYyrQTox-K3JHJ1ueZMGt
MogiExamのDatabricksのDatabricks-Certified-Professional-Data-Engineer試験トレーニング資料はPDF形式とソフトウェアの形式で提供します。それはMogiExamのDatabricksのDatabricks-Certified-Professional-Data-Engineer試験の問題と解答を含まれます。そして、その学習教材の内容はカバー率が高くて、正確率も高いです。それはきっと君のDatabricksのDatabricks-Certified-Professional-Data-Engineer試験に合格することの良い参考資料です。もし不合格になる場合は、ご心配なく、私たちは資料の費用を全部返金します。
Databricks認定プロフェッショナルデータエンジニア試験は、Databricksプラットフォームで作業する能力をデータエンジニアが証明するための優れた方法です。これにより、雇用主は潜在的な候補者のスキルを検証し、データエンジニアがDatabricksを効果的に使用するために必要な知識とスキルを持っていることを保証できます。
Databricks認定プロフェッショナルデータエンジニア(Databricks認定プロフェッショナルDATA-Engineer)認定試験は、DataBricksを使用してデータパイプラインを構築および管理する際のデータエンジニアのスキルと専門知識を検証する非常に価値のある業界認定です。 DataBricksは、ビッグデータと機械学習用の統一された分析エンジンを提供するクラウドベースのデータプラットフォームです。この認定試験は、Databricksアーキテクチャ、データエンジニアリングのベストプラクティス、データパイプラインの設計と実装に関する候補者の知識をテストするように設計されています。
>> Databricks-Certified-Professional-Data-Engineerトレーリング学習 <<
Databricks-Certified-Professional-Data-Engineer受験資格、Databricks-Certified-Professional-Data-Engineer最新テスト
あなたもそれらの1人かもしれませんが、試験の準備のために高品質で高い合格率のDatabricks-Certified-Professional-Data-Engineer学習問題を見つけるのに苦労するかもしれません。当社の製品は、主要な質問と回答で精巧に構成されています。学習資料では、過去の資料からキーを選択して、Databricks-Certified-Professional-Data-Engineerトレント準備を完了しています。練習するのに20時間から30時間しかかかりません。効果的な練習の後、Databricks-Certified-Professional-Data-Engineer試験トレントから試験ポイントを習得できます。そうすれば、合格するのに十分な自信があります。だから、これからDatabricks-Certified-Professional-Data-Engineerトレント準備から始めましょう。
Databricks Databricks-Certified-Professional-Data-Engineer 認定試験の出題範囲:
| トピック | 出題範囲 |
|---|
| トピック 1 | - Testing & Deployment: It discusses adapting notebook dependencies to use Python file dependencies, leveraging Wheels for imports, repairing and rerunning failed jobs, creating jobs based on common use cases, designing systems to control cost and latency SLAs, configuring the Databricks CLI, and using the REST API to clone a job, trigger a run, and export the run output.
|
| トピック 2 | - Security & Governance: It discusses creating Dynamic views to accomplishing data masking and using dynamic views to control access to rows and columns.
|
| トピック 3 | - Databricks Tooling: The Databricks Tooling topic encompasses the various features and functionalities of Delta Lake. This includes understanding the transaction log, Optimistic Concurrency Control, Delta clone, indexing optimizations, and strategies for partitioning data for optimal performance in the Databricks SQL service.
|
Databricks Certified Professional Data Engineer Exam 認定 Databricks-Certified-Professional-Data-Engineer 試験問題 (Q153-Q158):
質問 # 153
A junior data engineer on your team has implemented the following code block.
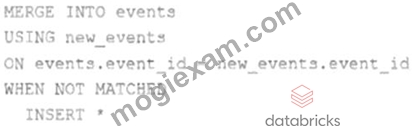
The viewnew_eventscontains a batch of records with the same schema as theeventsDelta table.
Theevent_idfield serves as a unique key for this table.
When this query is executed, what will happen with new records that have the sameevent_idas an existing record?
- A. They are inserted.
- B. They are ignored.
- C. They are updated.
- D. They are deleted.
- E. They are merged.
正解:B
解説:
This is the correct answer because it describes what will happen with new records that have the same event_id as an existing record when the query is executed. The query uses the INSERT INTO command to append new records from the view new_events to the table events. However, the INSERT INTO command does not check for duplicate values in the primary key column (event_id) and does not perform any update or delete operations on existing records. Therefore, if there are new records that have the same event_id as an existing record, they will be ignored and not inserted into the table events. Verified References: [Databricks Certified Data Engineer Professional], under "Delta Lake" section; Databricks Documentation, under "Append data using INSERT INTO" section.
"If none of the WHEN MATCHED conditions evaluate to true for a source and target row pair that matches the merge_condition, then the target row is left unchanged."https://docs.databricks.com/en/sql/language-manual/delta-merge-into.html#:~:text=If%20none%20o
質問 # 154
The downstream consumers of a Delta Lake table have been complaining about data quality issues impacting performance in their applications. Specifically, they have complained that invalidlatitudeandlongitudevalues in theactivity_detailstable have been breaking their ability to use other geolocation processes.
A junior engineer has written the following code to addCHECKconstraints to the Delta Lake table:
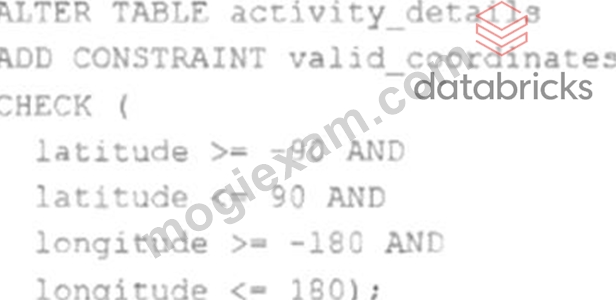
A senior engineer has confirmed the above logic is correct and the valid ranges for latitude and longitude are provided, but the code fails when executed.
Which statement explains the cause of this failure?
- A. Because another team uses this table to support a frequently running application, two-phase locking is preventing the operation from committing.
- B. The activity details table already contains records; CHECK constraints can only be added prior to inserting values into a table.
- C. The current table schema does not contain the field valid coordinates; schema evolution will need to be enabled before altering the table to add a constraint.
- D. The activity details table already contains records that violate the constraints; all existing data must pass CHECK constraints in order to add them to an existing table.
- E. The activity details table already exists; CHECK constraints can only be added during initial table creation.
正解:D
解説:
The failure is that the code to add CHECK constraints to the Delta Lake table fails when executed. The code uses ALTER TABLE ADD CONSTRAINT commands to add two CHECK constraints to a table named activity_details. The first constraint checks if the latitude value is between -90 and 90, and the second constraint checks if the longitude value is between -180 and 180. The cause of this failure is that the activity_details table already contains records that violate these constraints, meaning that they have invalid latitude or longitude values outside of these ranges. When adding CHECK constraints to an existing table, Delta Lake verifies that all existing data satisfies the constraints before adding them to the table. If any record violates the constraints, Delta Lake throws an exception and aborts the operation. Verified References:
[Databricks Certified Data Engineer Professional], under "Delta Lake" section; Databricks Documentation, under "Add a CHECK constraint to an existing table" section.
https://docs.databricks.com/en/sql/language-manual/sql-ref-syntax-ddl-alter-table.html#add-constraint
質問 # 155
A user wants to use DLT expectations to validate that a derived table report contains all records from the source, included in the table validation_copy.
The user attempts and fails to accomplish this by adding an expectation to the report table definition.
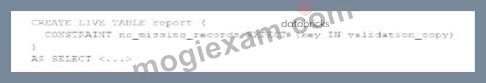
Which approach would allow using DLT expectations to validate all expected records are present in this table?
- A. Define a view that performs a left outer join on validation_copy and report, and reference this view in DLT expectations for the report table
- B. Define a SQL UDF that performs a left outer join on two tables, and check if this returns null values for report key values in a DLT expectation for the report table.
- C. Define a temporary table that perform a left outer join on validation_copy and report, and define an expectation that no report key values are null
- D. Define a function that performs a left outer join on validation_copy and report and report, and check against the result in a DLT expectation for the report table
正解:A
解説:
To validate that all records from the source are included in the derived table, creating a view that performs a left outer join between thevalidation_copytable and thereporttable is effective. The view can highlight any discrepancies, such as null values in the report table's key columns, indicating missing records. This view can then be referenced in DLT (Delta Live Tables) expectations for thereporttable to ensure data integrity. This approach allows for a comprehensive comparison between the source and the derived table.
References:
* Databricks Documentation on Delta Live Tables and Expectations: Delta Live Tables Expectations
質問 # 156
A data engineer wants to automate job monitoring and recovery in Databricks using the Jobs API. They need to list all jobs, identify a failed job, and rerun it.
Which sequence of API actions should the data engineer perform?
- A. Use the jobs/get endpoint to retrieve job details, then use jobs/update to rerun failed jobs.
- B. Use the jobs/list endpoint to list jobs, then use the jobs/create endpoint to create a new job, and run the new job using jobs/run-now.
- C. Use the jobs/list endpoint to list jobs, check job run statuses with jobs/runs/list, and rerun a failed job using jobs/run-now.
- D. Use the jobs/cancel endpoint to remove failed jobs, then recreate them with jobs/create and run the new ones.
正解:C
解説:
Comprehensive and Detailed Explanation From Exact Extract of Databricks Data Engineer Documents:
The Databricks Jobs REST API provides several endpoints for automation. The correct monitoring and rerun flow uses three specific calls:
GET /api/2.1/jobs/list - Lists all available jobs within the workspace.
GET /api/2.1/jobs/runs/list - Returns all runs for a specific job, including their current state (e.g., TERMINATED: FAILED).
POST /api/2.1/jobs/run-now - Immediately triggers a rerun of the specified job.
This sequence aligns with Databricks' prescribed automation model for job observability and recovery. Using jobs/update modifies metadata but does not rerun jobs, and jobs/create is only used for creating new jobs, not rerunning failed ones. Cancelling and recreating jobs introduces unnecessary duplication. Therefore, option A is the correct automated recovery workflow.
質問 # 157
A data engineer is configuring Delta Sharing for a Databricks-to-Databricks scenario to optimize read performance. The recipient needs to perform time travel queries and streaming reads on shared sales data.
Which configuration will provide the optimal performance while enabling these capabilities?
- A. Use the open sharing protocol instead of Databricks-to-Databricks sharing for better performance.
- B. Share tables WITHOUT HISTORY and enable partitioning for better query performance.
- C. Share the entire schema WITHOUT HISTORY and rely on recipient-side caching for performance.
- D. Share tables WITH HISTORY , ensure tables don't have partitioning enabled, and enable CDF before sharing.
正解:D
解説:
The official Delta Sharing guidance specifies that in order for recipients to use time travel queries and streaming reads , providers must share Delta tables WITH HISTORY . Sharing history ensures the Delta log is included, which enables efficient access to table snapshots and incremental data streams. Additionally, Change Data Feed (CDF) must be enabled prior to sharing if downstream consumers require streaming CDC queries. Without history, recipients cannot perform time travel or streaming queries. Open sharing supports static Delta tables but lacks streaming support. Therefore, sharing tables WITH HISTORY and enabling CDF is the required configuration for both performance and functionality.
質問 # 158
......
Databricks-Certified-Professional-Data-Engineer受験資格: https://www.mogiexam.com/Databricks-Certified-Professional-Data-Engineer-exam.html
- Databricks-Certified-Professional-Data-Engineer認定試験トレーリング 💸 Databricks-Certified-Professional-Data-Engineer受験料 ↩ Databricks-Certified-Professional-Data-Engineerテストトレーニング ⏭ ( Databricks-Certified-Professional-Data-Engineer )の試験問題は➠ www.goshiken.com 🠰で無料配信中Databricks-Certified-Professional-Data-Engineer実際試験
- Databricks-Certified-Professional-Data-Engineer資格問題集 🔡 Databricks-Certified-Professional-Data-Engineerテスト資料 ✍ Databricks-Certified-Professional-Data-Engineer合格記 ☸ ( www.goshiken.com )を開き、[ Databricks-Certified-Professional-Data-Engineer ]を入力して、無料でダウンロードしてくださいDatabricks-Certified-Professional-Data-Engineer実際試験
- 有効的なDatabricks-Certified-Professional-Data-Engineerトレーリング学習 | 素晴らしい合格率のDatabricks-Certified-Professional-Data-Engineer: Databricks Certified Professional Data Engineer Exam | 最新の更新Databricks-Certified-Professional-Data-Engineer受験資格 ⌨ ⇛ www.xhs1991.com ⇚サイトで⇛ Databricks-Certified-Professional-Data-Engineer ⇚の最新問題が使えるDatabricks-Certified-Professional-Data-Engineer復習教材
- Databricks-Certified-Professional-Data-Engineer資格問題集 😼 Databricks-Certified-Professional-Data-Engineer資格模擬 😅 Databricks-Certified-Professional-Data-Engineer試験解説問題 😅 ➠ www.goshiken.com 🠰サイトにて最新➠ Databricks-Certified-Professional-Data-Engineer 🠰問題集をダウンロードDatabricks-Certified-Professional-Data-Engineer合格記
- Databricks-Certified-Professional-Data-Engineer試験の準備方法|ユニークなDatabricks-Certified-Professional-Data-Engineerトレーリング学習試験|素晴らしいDatabricks Certified Professional Data Engineer Exam受験資格 〰 URL ▛ www.xhs1991.com ▟をコピーして開き、▶ Databricks-Certified-Professional-Data-Engineer ◀を検索して無料でダウンロードしてくださいDatabricks-Certified-Professional-Data-Engineer対応問題集
- Databricks-Certified-Professional-Data-Engineer試験関連情報 ♿ Databricks-Certified-Professional-Data-Engineer技術試験 📱 Databricks-Certified-Professional-Data-Engineer試験解説問題 👓 最新⇛ Databricks-Certified-Professional-Data-Engineer ⇚問題集ファイルは▛ www.goshiken.com ▟にて検索Databricks-Certified-Professional-Data-Engineerトレーニング
- Databricks-Certified-Professional-Data-Engineer資格模擬 🆖 Databricks-Certified-Professional-Data-Engineer技術試験 📗 Databricks-Certified-Professional-Data-Engineer資格問題集 🚥 検索するだけで《 www.topexam.jp 》から➤ Databricks-Certified-Professional-Data-Engineer ⮘を無料でダウンロードDatabricks-Certified-Professional-Data-Engineer模試エンジン
- Databricks-Certified-Professional-Data-Engineer資格模擬 🥱 Databricks-Certified-Professional-Data-Engineerテスト資料 🏉 Databricks-Certified-Professional-Data-Engineer資格問題集 🥦 ➥ www.goshiken.com 🡄で《 Databricks-Certified-Professional-Data-Engineer 》を検索して、無料でダウンロードしてくださいDatabricks-Certified-Professional-Data-Engineer試験関連情報
- 認定するDatabricks-Certified-Professional-Data-Engineerトレーリング学習一回合格-高品質なDatabricks-Certified-Professional-Data-Engineer受験資格 🥕 《 www.passtest.jp 》に移動し、⏩ Databricks-Certified-Professional-Data-Engineer ⏪を検索して無料でダウンロードしてくださいDatabricks-Certified-Professional-Data-Engineer資格模擬
- 最高のDatabricks-Certified-Professional-Data-Engineerトレーリング学習 - 合格スムーズDatabricks-Certified-Professional-Data-Engineer受験資格 | 正確的なDatabricks-Certified-Professional-Data-Engineer最新テスト 🟦 ウェブサイト➥ www.goshiken.com 🡄から➤ Databricks-Certified-Professional-Data-Engineer ⮘を開いて検索し、無料でダウンロードしてくださいDatabricks-Certified-Professional-Data-Engineer認定試験トレーリング
- Databricks-Certified-Professional-Data-Engineer対応問題集 🌙 Databricks-Certified-Professional-Data-Engineer対応問題集 🧒 Databricks-Certified-Professional-Data-Engineer復習教材 🌜 《 www.shikenpass.com 》には無料の[ Databricks-Certified-Professional-Data-Engineer ]問題集がありますDatabricks-Certified-Professional-Data-Engineer資格模擬
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes
P.S.MogiExamがGoogle Driveで共有している無料の2026 Databricks Databricks-Certified-Professional-Data-Engineerダンプ:https://drive.google.com/open?id=1AHQT0jlcyeFvYyrQTox-K3JHJ1ueZMGt