
BONUS!!! Download part of Prep4away AIF-C01 dumps for free: https://drive.google.com/open?id=1yyniWrxXv950Gw4ZMKP_NEjbMSRU9yOR
Everyone has different learning habits, AIF-C01 exam simulation provide you with different system versions: PDF version, Software version and APP version. Based on your specific situation, you can choose the version that is most suitable for you, or use multiple versions at the same time. After all, each version of AIF-C01 Preparation questions have its own advantages. If you are very busy, you can only use some of the very fragmented time to use our AIF-C01 study materials. And each of our AIF-C01 exam questions can help you pass the exam for sure.
| Certification Vendor: | Amazon AWS |
|---|---|
| Exam Name: | AWS Certified AI Practitioner |
| Exam Number: | AIF-C01 |
| Available Languages: | Traditional Chinese, Korean, English, Simplified Chinese, Japanese |
| Exam Price: | 100 USD |
| Passing Score: | 700 (scaled score 100–1000) |
| Exam Duration: | 90 minutes |
| Certificate Validity Period: | 3 years |
| Real Exam Qty: | 65 (50 scored, 15 unscored) |
| Related Certifications: | AWS Certified Cloud Practitioner AWS Certified Machine Learning – Specialty |
| Exam Format: | Multiple choice, Ordering, Multiple response |
| Recommended Training: | AWS Skill Builder - AI Practitioner Learning Path AWS Certified AI Practitioner Official Training |
| Exam Registration: | AWS Certification Registration Pearson VUE Scheduling |
| Sample Questions: | Amazon AIF-C01 Sample Questions |
| Exam Way: | Online proctored or testing center delivery |
| Pre Condition: | No required prerequisites; recommended basic understanding of cloud computing and general IT concepts |
| Official Syllabus URL: | https://docs.aws.amazon.com/aws-certification/latest/ai-practitioner-01/ai-practitioner-01.html |
>> Reliable AIF-C01 Test Preparation <<
Through our investigation and analysis of the real problem over the years, our AIF-C01 prepare questions can accurately predict the annual AIF-C01 exams. In the actual exam process, users will encounter almost half of the problem is similar in our products. Even if the syllabus is changing every year, the AIF-C01 quiz guide’s experts still have the ability to master propositional trends. Believe that such a high hit rate can better help users in the review process to build confidence, and finally help users through the qualification examination to obtain a certificate. All in all, we want you to have the courage to challenge yourself, and our AIF-C01 Exam Prep will do the best for the user's expectations.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
| Topic 4 |
|
| Topic 5 |
|
NEW QUESTION # 245
A company is working on a large language model (LLM) and noticed that the LLM's outputs are not as diverse as expected. Which parameter should the company adjust?
Answer: B
Explanation:
The correct answer is A because temperature controls the randomness of a language model ' s output. A higher temperature increases diversity by making the model more likely to explore less probable tokens, while a lower temperature results in more deterministic and repetitive outputs.
From AWS documentation:
" The temperature parameter in LLMs adjusts the randomness of generated responses. Higher values (e.g.,
0.8-1.0) produce more creative and diverse output, while lower values (e.g., 0.1-0.3) make output more focused and repetitive. " Explanation of other options:
B). Batch size is related to training efficiency, not output diversity.
C). Learning rate affects the training convergence rate, not inference-time output variety.
D). Optimizer type is a training configuration that influences how the model learns during training, not diversity during inference.
Referenced AWS AI/ML Documents and Study Guides:
Amazon Bedrock - Parameter Tuning Guide
AWS Machine Learning Specialty Guide - LLM Inference Parameters
NEW QUESTION # 246
A company is using Amazon SageMaker to develop AI models.
Select the correct SageMaker feature or resource from the following list for each step in the AI model lifecycle workflow. Each SageMaker feature or resource should be selected one time or not at all. (Select TWO.) SageMaker Clarify SageMaker Model Registry SageMaker Serverless Inference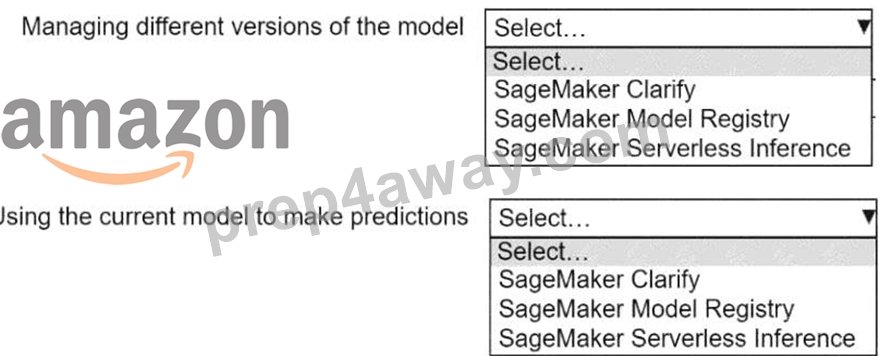
Answer:
Explanation: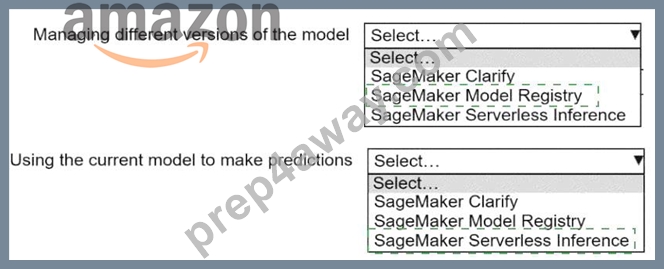
Explanation:
SageMaker Model Registry, SageMaker Serverless interference
This question requires selecting the appropriate Amazon SageMaker feature for two distinct steps in the AI model lifecycle. Let's break down each step and evaluate the options:
Step 1: Managing different versions of the model
The goal here is to identify a SageMaker feature that supports version control and management of machine learning models. Let's analyze the options:
SageMaker Clarify: This feature is used to detect bias in models and explain model predictions, helping with fairness and interpretability. It does not provide functionality for managing model versions.
SageMaker Model Registry: This is a centralized repository in Amazon SageMaker that allows users to catalog, manage, and track different versions of machine learning models. It supports model versioning, approval workflows, and deployment tracking, making it ideal for managing different versions of a model.
SageMaker Serverless Inference: This feature enables users to deploy models for inference without managing servers, automatically scaling based on demand. It is focused on inference (predictions), not on managing model versions.
Conclusion for Step 1: The SageMaker Model Registry is the correct choice for managing different versions of the model.
Exact Extract Reference: According to the AWS SageMaker documentation, "The SageMaker Model Registry allows you to catalog models for production, manage model versions, associate metadata, and manage approval status for deployment." (Source: AWS SageMaker Documentation - Model Registry,
https://docs.aws.amazon.com/sagemaker/latest/dg/model-registry.html).
Step 2: Using the current model to make predictions
The goal here is to identify a SageMaker feature that facilitates making predictions (inference) with a deployed model. Let's evaluate the options:
SageMaker Clarify: As mentioned, this feature focuses on bias detection and explainability, not on performing inference or making predictions.
SageMaker Model Registry: While the Model Registry helps manage and catalog models, it is not used directly for making predictions. It can store models, but the actual inference process requires a deployment mechanism.
SageMaker Serverless Inference: This feature allows users to deploy models for inference without managing infrastructure. It automatically scales based on traffic and is specifically designed for making predictions in a cost-efficient, serverless manner.
Conclusion for Step 2: SageMaker Serverless Inference is the correct choice for using the current model to make predictions.
Exact Extract Reference: The AWS documentation states, "SageMaker Serverless Inference is a deployment option that allows you to deploy machine learning models for inference without configuring or managing servers. It automatically scales to handle inference requests, making it ideal for workloads with intermittent or unpredictable traffic." (Source: AWS SageMaker Documentation - Serverless Inference, https://docs.aws.
amazon.com/sagemaker/latest/dg/serverless-inference.html).
Why Not Use the Same Feature Twice?
The question specifies that each SageMaker feature or resource should be selected one time or not at all. Since SageMaker Model Registry is used for version management and SageMaker Serverless Inference is used for predictions, each feature is selected exactly once. SageMaker Clarify is not applicable to either step, so it is not selected at all, fulfilling the question's requirements.
References:
AWS SageMaker Documentation: Model Registry (https://docs.aws.amazon.com/sagemaker/latest/dg/model- registry.html) AWS SageMaker Documentation: Serverless Inference (https://docs.aws.amazon.com/sagemaker/latest/dg
/serverless-inference.html)
AWS AI Practitioner Study Guide (conceptual alignment with SageMaker features for model lifecycle management and inference) Let's format this question according to the specified structure and provide a detailed, verified answer based on AWS AI Practitioner knowledge and official AWS documentation. The question focuses on selecting an AWS database service that supports storage and queries of embeddings as vectors, which is relevant to generative AI applications.
NEW QUESTION # 247
A company creates video content. The company wants to use generative AI to generate new creative content and to reduce video creation time. Which solution will meet these requirements in the MOST operationally efficient way?
Answer: D
Explanation:
Amazon Nova Pro is intended for high-end professional-grade image or 3D content generation, but not specifically optimized for video generation like Nova Reel.
NEW QUESTION # 248
An AI practitioner is developing a prompt for large language models (LLMs) in Amazon Bedrock. The AI practitioner must ensure that the prompt works across all Amazon Bedrock LLMs.
Which characteristic can differ across the LLMs?
Answer: C
Explanation:
The correct answer is A because each foundation model on Amazon Bedrock (e.g., Claude, Titan, Mistral, Meta Llama) has a different maximum token limit, which defines the maximum number of tokens the model can accept in the prompt and generate in the response.
From AWS documentation:
"Each model in Amazon Bedrock has its own maximum token limit. Prompts exceeding the limit must be truncated or adjusted depending on the selected model." Explanation of other options:
B). On-demand inference support is a platform feature that is uniformly supported across models on Bedrock.
C). All Bedrock LLMs support randomness control through temperature and top-p parameters.
D). Amazon Bedrock Guardrails are designed to work across supported models, though specific behaviors may vary slightly.
Referenced AWS AI/ML Documents and Study Guides:
* Amazon Bedrock Model Comparison Guide
* AWS Prompt Engineering and LLM Deployment Documentation
* AWS ML Specialty Study Guide - Bedrock Model Capabilities
NEW QUESTION # 249
A company uses a foundation model (FM) from Amazon Bedrock for an AI search tool. The company wants to fine-tune the model to be more accurate by using the company's data.
Which strategy will successfully fine-tune the model?
Answer: B
NEW QUESTION # 250
......
AIF-C01 Test Registration: https://www.prep4away.com/Amazon-certification/braindumps.AIF-C01.ete.file.html
2026 Latest Prep4away AIF-C01 PDF Dumps and AIF-C01 Exam Engine Free Share: https://drive.google.com/open?id=1yyniWrxXv950Gw4ZMKP_NEjbMSRU9yOR