P.S. Free & New Professional-Machine-Learning-Engineer dumps are available on Google Drive shared by FreeCram: https://drive.google.com/open?id=1mq5VNhq6UDxA0c3dVAI_bLfy3kLabapV
If you do not quickly begin to improve your own strength, the next one facing the unemployment crisis is you. The time is very tight, and choosing our Professional-Machine-Learning-Engineer study materials can save you a lot of time. And our Professional-Machine-Learning-Engineer Exam Questions can really save you time and efforts. If you study with our Professional-Machine-Learning-Engineer learning guide for 20 to 30 hours, then you will be able to pass the exam and get the certification.
The Google Professional Machine Learning Engineer exam is two hours long. The candidates can expect multiple-choice as well as multiple-select questions in their delivery of the certification test. The exam is currently given to the learners in the English language. To register for and schedule it, you need to pay $200 (plus applicable taxes). While registering for the test, the potential applicants will be offered to select the convenient mode of exam delivery: an online proctored session from a remote location or an in-person proctored session at the nearest testing center.
>> Professional-Machine-Learning-Engineer Online Training Materials <<
Thus, it will allow you to examine the Google Professional-Machine-Learning-Engineer Dumps before purchasing it. FreeCram proudly presents the exceptional Google Professional-Machine-Learning-Engineer material that will meet your expectations. Beware that the sections of the exam change from time to time. Therefore, be alert by checking the updates frequently. It will prevent you from wasting time, material expenses, and inner peace.
Google Professional Machine Learning Engineer certification is a highly sought-after certification in the field of machine learning. Google Professional Machine Learning Engineer certification is designed for professionals who are looking to validate their expertise in designing, building and deploying machine learning models using the Google Cloud Platform. Google Professional Machine Learning Engineer certification exam tests the candidate's ability to apply machine learning technologies to real-world scenarios.
Google Professional Machine Learning Engineer exam is designed to test the expertise of individuals in the field of machine learning. Google Professional Machine Learning Engineer certification provides a strong foundation in machine learning concepts and tools, as well as the ability to develop and deploy sophisticated machine learning models using Google Cloud technologies. Professional-Machine-Learning-Engineer Exam assesses one's ability to use Google’s machine learning tools and services to build and deploy robust, scalable, and efficient machine learning models.
NEW QUESTION # 197
You are developing a custom TensorFlow classification model based on tabular dat a. Your raw data is stored in BigQuery contains hundreds of millions of rows, and includes both categorical and numerical features. You need to use a MaxMin scaler on some numerical features, and apply a one-hot encoding to some categorical features such as SKU names. Your model will be trained over multiple epochs. You want to minimize the effort and cost of your solution. What should you do?
Answer: B
Explanation:
TFX (TensorFlow Extended) is a platform for end-to-end machine learning pipelines. It provides components for data ingestion, preprocessing, validation, model training, serving, and monitoring. Dataflow is a fully managed service for scalable data processing. By using TFX components with Dataflow, you can perform feature engineering on large-scale tabular data in a distributed and efficient way. You can use the Transform component to apply the MaxMin scaler and the one-hot encoding to the numerical and categorical features, respectively. You can also use the ExampleGen component to read data from BigQuery and the Trainer component to train your TensorFlow model. The output of the Transform component is a TFRecord file, which is a binary format for storing TensorFlow data. You can export the TFRecord file to Cloud Storage and feed it into Vertex AI Training, which is a managed service for training custom machine learning models on Google Cloud. Reference:
TFX | TensorFlow
Dataflow | Google Cloud
Vertex AI Training | Google Cloud
NEW QUESTION # 198
You are working on a system log anomaly detection model for a cybersecurity organization. You have developed the model using TensorFlow, and you plan to use it for real-time prediction. You need to create a Dataflow pipeline to ingest data via Pub/Sub and write the results to BigQuery. You want to minimize the serving latency as much as possible. What should you do?
Answer: C
Explanation:
The best option for creating a Dataflow pipeline for real-time anomaly detection is to load the model directly into the Dataflow job as a dependency, and use it for prediction. This option has the following advantages:
* It minimizes the serving latency, as the model prediction logic is executed within the same Dataflow pipeline that ingests and processes the data. There is no need to invoke external services or containers, which can introduce network overhead and latency.
* It simplifies the deployment and management of the model, as the model is packaged with the Dataflow job and does not require a separate service or container. The model can be updated by redeploying the Dataflow job with a new model version.
* It leverages the scalability and reliability of Dataflow, as the model prediction logic can scale up or down with the data volume and handle failures and retries automatically.
The other options are less optimal for the following reasons:
* Option A: Containerizing the model prediction logic in Cloud Run, which is invoked by Dataflow, introduces additional latency and complexity. Cloud Run is a serverless platform that runs stateless containers, which means that the model prediction logic needs to be initialized and loaded every time a request is made. This can increase the cold start latency and reduce the throughput. Moreover, Cloud Run has a limit on the number of concurrent requests per container, which can affect the scalability of the model prediction logic. Additionally, this option requires managing two separate services: the Dataflow pipeline and the Cloud Run container.
* Option C: Deploying the model to a Vertex AI endpoint, and invoking this endpoint in the Dataflow job, also introduces additional latency and complexity. Vertex AI is a managed service that provides various tools and features for machine learning, such as training, tuning, serving, and monitoring.
However, invoking a Vertex AI endpoint from a Dataflow job requires making an HTTP request, which can incur network overhead and latency. Moreover, this option requires managing two separate services: the Dataflow pipeline and the Vertex AI endpoint.
* Option D: Deploying the model in a TFServing container on Google Kubernetes Engine, and invoking it in the Dataflow job, also introduces additional latency and complexity. TFServing is a high- performance serving system for TensorFlow models, which can handle multiple versions and variants of a model. However, invoking a TFServing container from a Dataflow job requires making a gRPC or REST request, which can incur network overhead and latency. Moreover, this option requires managing two separate services: the Dataflow pipeline and the Google Kubernetes Engine cluster.
:
[Dataflow documentation]
[TensorFlow documentation]
[Cloud Run documentation]
[Vertex AI documentation]
[TFServing documentation]
NEW QUESTION # 199
Your company manages an application that aggregates news articles from many different online sources and sends them to users. You need to build a recommendation model that will suggest articles to readers that are similar to the articles they are currently reading. Which approach should you use?
Answer: A
Explanation:
https://cloud.google.com/blog/topics/developers-practitioners/meet-ais-multitool-vector-embeddings
NEW QUESTION # 200
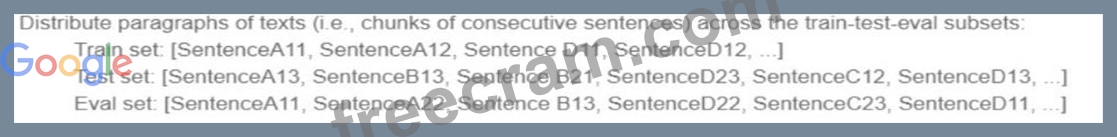
Your team is working on an NLP research project to predict political affiliation of authors based on articles they have written. You have a large training dataset that is structured like this: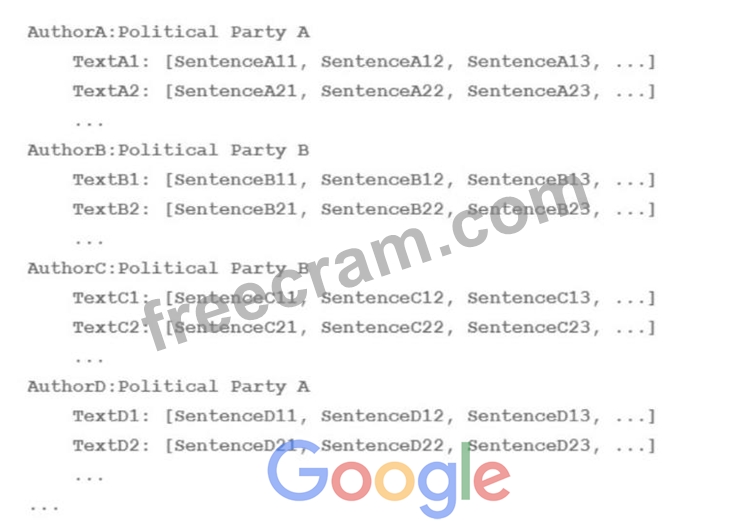
You followed the standard 80%-10%-10% data distribution across the training, testing, and evaluation subsets. How should you distribute the training examples across the train-test-eval subsets while maintaining the 80-10-10 proportion?
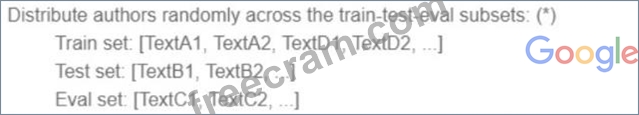
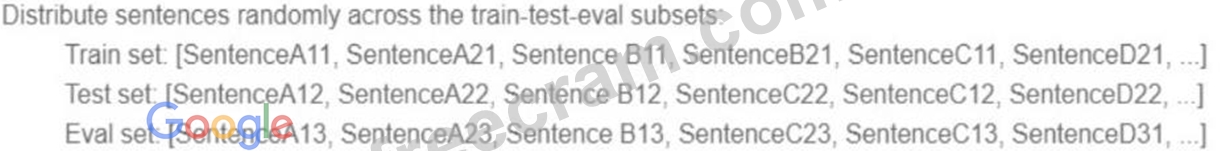
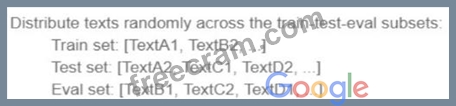
Answer: A
Explanation:
If we just put inside the Training set , Validation set and Test set , randomly Text, Paragraph or sentences the model will have the ability to learn specific qualities about The Author's use of language beyond just his own articles. Therefore the model will mixed up different opinions. Rather if we divided things up a the author level, so that given authors were only on the training data, or only in the test data or only in the validation data. The model will find more difficult to get a high accuracy on the test validation (What is correct and have more sense!). Because it will need to really focus in author by author articles rather than get a single political affiliation based on a bunch of mixed articles from different authors. https://developers.google.com/machine-learning/crash-course/18th-century-literature For example, suppose you are training a model with purchase data from a number of stores. You know, however, that the model will be used primarily to make predictions for stores that are not in the training data. To ensure that the model can generalize to unseen stores, you should segregate your data sets by stores. In other words, your test set should include only stores different from the evaluation set, and the evaluation set should include only stores different from the training set. https://cloud.google.com/automl-tables/docs/prepare#ml-use
NEW QUESTION # 201
Your team has a model deployed to a Vertex Al endpoint You have created a Vertex Al pipeline that automates the model training process and is triggered by a Cloud Function. You need to prioritize keeping the model up-to-date, but also minimize retraining costs. How should you configure retraining'?
Answer: C
Explanation:
According to the official exam guide1, one of the skills assessed in the exam is to "configure and optimize model monitoring jobs". Vertex AI Model Monitoring documentation states that "model monitoring helps you detect when your model's performance degrades over time due to changes in the data that your model receives or returns" and that "you can configure model monitoring to send notifications to Pub/Sub when it detects anomalies or drift in your model's predictions"2. Therefore, enabling model monitoring on the Vertex AI endpoint and configuring Pub/Sub to call the Cloud Function when feature drift is detected would help you keep the model up-to-date and minimize retraining costs. The other options are not relevant or optimal for this scenario. References:
* Professional ML Engineer Exam Guide
* Vertex AI Model Monitoring
* Google Professional Machine Learning Certification Exam 2023
* Latest Google Professional Machine Learning Engineer Actual Free Exam Questions
NEW QUESTION # 202
......
Professional-Machine-Learning-Engineer Reliable Dumps Ppt: https://www.freecram.com/Google-certification/Professional-Machine-Learning-Engineer-exam-dumps.html
2026 Latest FreeCram Professional-Machine-Learning-Engineer PDF Dumps and Professional-Machine-Learning-Engineer Exam Engine Free Share: https://drive.google.com/open?id=1mq5VNhq6UDxA0c3dVAI_bLfy3kLabapV