さらに、Fast2test DY0-001ダンプの一部が現在無料で提供されています:https://drive.google.com/open?id=1iYVPfeu_3EFgtv8i-G_d9vRG0-rLgD-n
Fast2testが提供しておりますのは専門家チームの研究したDY0-001問題と真題で弊社の高い名誉はたぶり信頼をうけられます。安心で弊社の商品を使うために無料なDY0-001サンブルをダウンロードしてください。
| Certification Vendor: | CompTIA |
|---|---|
| Exam Name: | CompTIA DataAI Certification Exam |
| Exam Number: | DY0-001 |
| Certificate Validity Period: | 3 years |
| Passing Score: | Pass/Fail (no numerical score) |
| Related Certifications: | CompTIA Data+ CompTIA AI Essentials |
| Available Languages: | Japanese, English |
| Exam Format: | Multiple Choice, Performance-Based Questions (PBQs) |
| Real Exam Qty: | Up to 90 |
| Exam Duration: | 165 minutes |
| Exam Price: | $544 USD |
| Recommended Training: | CompTIA Official Study Guide CompTIA CertMaster Learn for DataAI |
| Exam Registration: | Pearson VUE Scheduling CompTIA Official Registration |
| Sample Questions: | CompTIA DY0-001 Sample Questions |
| Exam Way: | Online proctored or in-person at Pearson VUE test centers |
| Pre Condition: | No mandatory prerequisites; recommended 5+ years of experience in data science, analytics, or related fields |
| Official Syllabus URL: | https://www.comptia.org/certifications/dataai |
DY0-001学習ツールの魂としての「信頼できる信用」、経営理念としての「最大限のサービス意識」により、高品質のサービスをお客様に提供するよう努めています。あなたの小さなヘルパーになり、DY0-001認定テストに関するご質問にお答えするサービススタッフは、すべてのユーザーとの包括的で調整された持続可能な協力関係を目指します。 DY0-001テストトレントに関するパズルは、タイムリーで効果的な応答を受け取ります。公式ウェブサイトにメッセージを残すか、都合の良いときにメールを送信してください。
| トピック | 出題範囲 |
|---|---|
| トピック 1 |
|
| トピック 2 |
|
| トピック 3 |
|
| トピック 4 |
|
| トピック 5 |
|
質問 # 25
Which of the following is a classic example of a constrained optimization problem?
正解:A
解説:
# The Traveling Salesman Problem (TSP) is a classic example of a constrained optimization problem. The goal is to find the shortest possible route that visits a set of locations once and returns to the origin point - under constraints such as distance, order, and time.
Why the other options are incorrect:
* A: The cold start problem is related to recommender systems, not optimization.
* C: Calculating a local maximum is part of optimization but not necessarily constrained.
* D: Gradient descent is an optimization method, but not itself a problem with constraints.
Official References:
* CompTIA DataX (DY0-001) Official Study Guide - Section 3.4:"Constrained optimization involves solving problems under defined limitations - e.g., distance or time constraints in routing."
* Optimization Techniques in Data Science, Chapter 6:"TSP is a benchmark in combinatorial optimization, representing a multi-variable problem with strict constraints."
-
質問 # 26
A movie production company would like to find the actors appearing in its top movies using data from the tables below. The resulting data must show all movies in Table 1, enriched with actors listed in Table 2.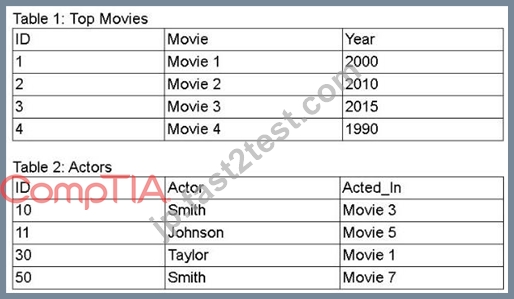
Which of the following query operations achieves the desired data set?
正解:A
解説:
A LEFT JOIN returns every row from Table 1 (all top movies) and brings in matching actors from Table 2 where the Movie = Acted_In, leaving NULLs for movies without listed actors.
質問 # 27
Which of the following modeling tools is appropriate for solving a scheduling problem?
正解:B
解説:
Scheduling problems typically involve the assignment of limited resources (e.g., time, personnel, machines) over time to tasks, often under constraints. These problems are inherently mathematical and are typically solved using:
# Constrained Optimization - which is a mathematical technique for optimizing an objective function subject to one or more constraints. This tool is widely used for operations research problems such as scheduling, resource allocation, logistics, and supply chain optimization.
Why the other options are incorrect:
* A. One-armed bandit: Refers to a class of algorithms used for balancing exploration and exploitation, not scheduling.
* C. Decision tree: Used for classification and regression, not for constraint-based scheduling.
* D. Gradient descent: An optimization method for training models (typically ML), but not specifically suitable for complex constraint-based scheduling.
Official References:
* CompTIA DataX (DY0-001) Official Study Guide - Section 3.4 (Modeling Tools):"Scheduling and allocation problems are best addressed using constrained optimization techniques which allow incorporation of resource limits and goal functions."
* Data Science and Operations Research Foundations, Chapter 7:"Constraint-based optimization is the primary mathematical strategy used in scheduling problems to meet deadlines, minimize cost, or maximize throughput."
-
質問 # 28
A data scientist needs to:
Build a predictive model that gives the likelihood that a car will get a flat tire.
Provide a data set of cars that had flat tires and cars that did not.
All the cars in the data set had sensors taking weekly measurements of tire pressure similar to the sensors that will be installed in the cars consumers drive.
Which of the following is the most immediate data concern?
正解:C
解説:
# Granularity misalignment refers to a mismatch between the level of detail in the predictor variables and the event being predicted.
In this case, flat tires are likely discrete, infrequent events, while tire pressure is measured weekly. If the prediction model is trying to link a specific tire pressure value to a binary outcome (flat tire: yes/no), and the timing doesn't align precisely, the predictor variable (pressure) may not be granular enough to accurately associate with the event.
Why the other options are incorrect:
* B: While outliers can exist, they are not the most immediate concern given the time-series nature of the data.
* C: While domain expertise is helpful, it doesn't directly address the data structure issue.
* D: Lagged observations can be engineered in modeling but aren't the primary problem here.
Official References:
* CompTIA DataX (DY0-001) Official Study Guide - Section 3.1 (Data Granularity):"Granularity misalignment occurs when the temporal or spatial resolution of features does not align with the prediction target."
* Data Science Process Guide, Section 2.3:"Predictive performance can suffer when temporal mismatch exists between observations and outcomes. Granularity issues must be resolved prior to modeling."
-
質問 # 29
A data scientist wants to digitize historical hard copies of documents. Which of the following is the best method for this task?
正解:A
解説:
OCR converts scanned images of text into machine‐readable characters, making it the appropriate tool for digitizing printed or handwritten historical documents.
質問 # 30
......
DY0-001勉強時間: https://jp.fast2test.com/DY0-001-premium-file.html
さらに、Fast2test DY0-001ダンプの一部が現在無料で提供されています:https://drive.google.com/open?id=1iYVPfeu_3EFgtv8i-G_d9vRG0-rLgD-n