P.S.CertShikenがGoogle Driveで共有している無料の2026 Amazon MLA-C01ダンプ:https://drive.google.com/open?id=1yXgypTrzFqU4QG3df4QkpEk3A2alXV5_
MLA-C01試験には多くの利点があり、Amazon購入する価値があります。購入前にMLA-C01ガイドの質問デモをダウンロードして試用し、支払いが完了したらすぐに使用できます。支払いが完了したら、5〜10分以内に送信します。その後、あなたはそれを学び、実践することができます。AWS Certified Machine Learning Engineer - Associate試験に合格するための最新のMLA-C01試験問題があることを確認するために、MLA-C01トレント質問を頻繁に更新します。 MLA-C01試験に合格すると、大企業に入社して賃金を2倍にすることができます。
| トピック | 出題範囲 |
|---|---|
| トピック 1 |
|
| トピック 2 |
|
| トピック 3 |
|
| トピック 4 |
|
研究により、学習への関心を刺激することが最善の解決策であることがわかっています。したがって、MLA-C01準備ガイドの焦点は、MLA-C01試験の準備方法を変更することにより、厳格で無駄なメモリモードを改革することです。 MLA-C01実践教材のソフトバージョンは、知識と最新テクノロジーを組み合わせて学習力を大幅に刺激します。楽しい学習シーンと鮮明な説明をシミュレートすることにより、ユーザーは資格のあるMLA-C01試験に合格する自信が大きくなります。
質問 # 115
An ML engineer needs to use an ML model to predict the price of apartments in a specific location.
Which metric should the ML engineer use to evaluate the model ' s performance?
正解:D
解説:
When predicting continuous variables, such as apartment prices, it ' s essential to evaluate the model ' s performance using appropriate regression metrics. The Mean Absolute Error (MAE) is a widely used metric for this purpose.
Understanding Mean Absolute Error (MAE):
MAE measures the average magnitude of errors in a set of predictions, without considering their direction. It calculates the average absolute difference between predicted values and actual values, providing a straightforward interpretation of prediction accuracy.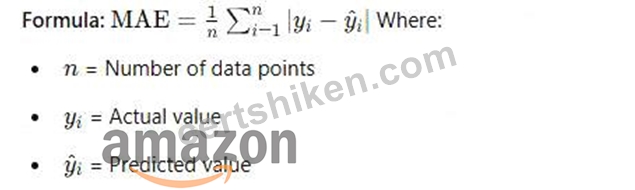
Advantages of MAE:
Interpretability: MAE is expressed in the same units as the target variable, making it easy to understand.
Robustness to Outliers: Unlike metrics that square the errors (e.g., Mean Squared Error), MAE does not disproportionately penalize larger errors, making it more robust to outliers.
Comparison with Other Metrics:
Accuracy, AUC, F1 Score: These metrics are designed for classification tasks, where the goal is to predict discrete labels. They are not suitable for regression problems involving continuous target variables.
Mean Squared Error (MSE): While MSE also measures prediction errors, it squares the differences, giving more weight to larger errors. This can be useful in certain contexts but may be sensitive to outliers.
Conclusion:
For evaluating the performance of a model predicting apartment prices-a continuous variable-MAE is an appropriate and effective metric. It provides a clear indication of the average prediction error in the same units as the target variable, facilitating straightforward interpretation and comparison.
References:
Regression Metrics - GeeksforGeeks
Evaluation Metrics for Your Regression Model - Analytics Vidhya
Regression Metrics for Machine Learning - Machine Learning Mastery
質問 # 116
An ML engineer needs to process thousands of existing CSV objects and new CSV objects that are uploaded. The CSV objects are stored in a central Amazon S3 bucket and have the same number of columns. One of the columns is a transaction date. The ML engineer must query the data based on the transaction date.
Which solution will meet these requirements with the LEAST operational overhead?
正解:D
質問 # 117
An airline company deploys ML models to one dozen Amazon SageMaker Al inference endpoints. The inference endpoints must be able to handle different types of workloads in a cost-effective way.
Select the correct inference option from the following list to handle each type of workload. Select each inference option one time. (Select FOUR.)
* Asynchronous inference
* Batch inference
* Real-time inference
* Serverless inference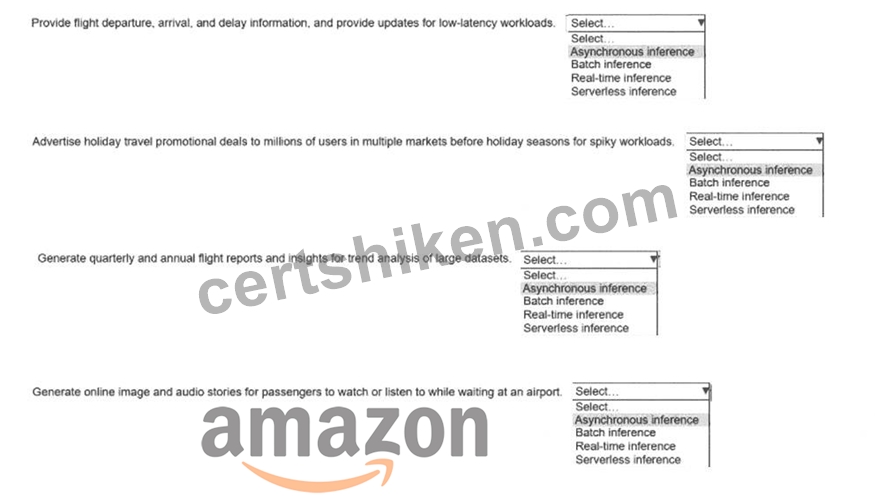
正解:
解説: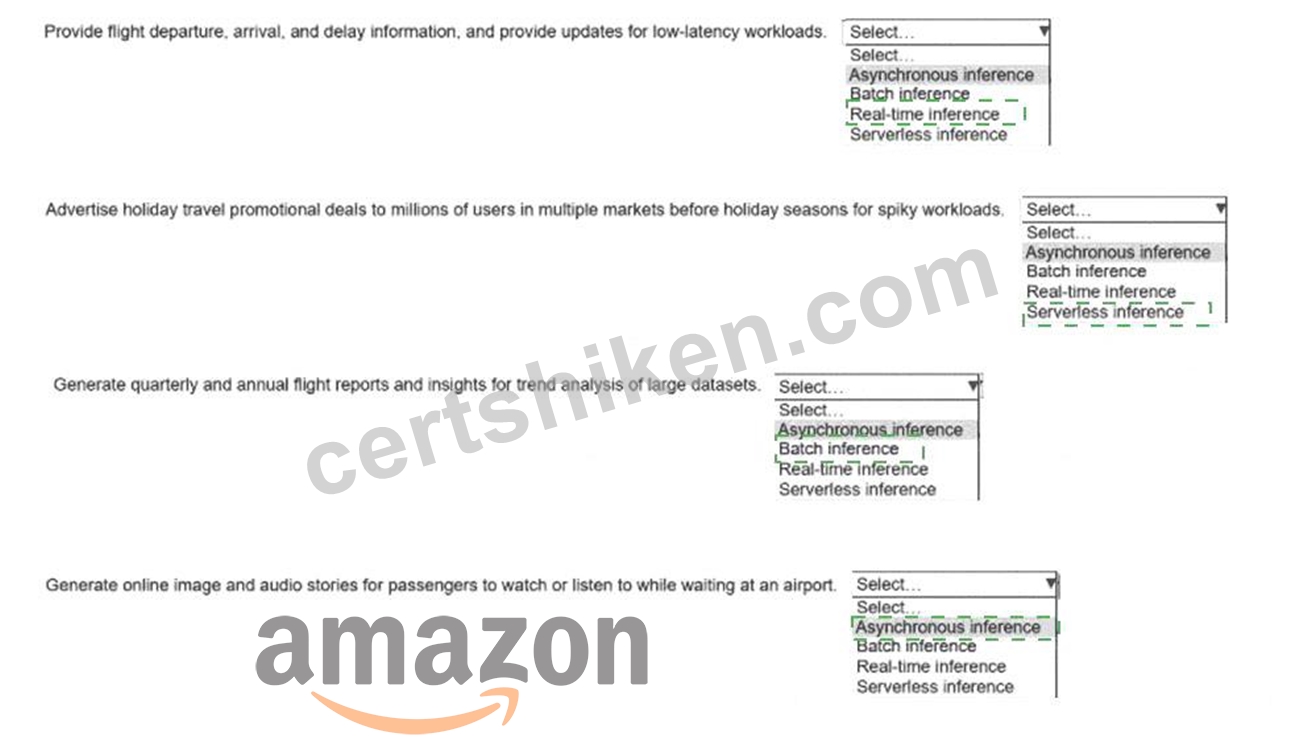
* Provide flight departure, arrival, and delay information, and provide updates for low-latency workloads# Real-time inference
* Advertise holiday travel promotional deals to millions of users in multiple markets before holiday seasons for spiky workloads# Serverless inference
* Generate quarterly and annual flight reports and insights for trend analysis of large datasets# Batch inference
* Generate online image and audio stories for passengers to watch or listen to while waiting at an airport# Asynchronous inference
* The correct mapping depends on latency requirement, traffic pattern, payload size, processing duration, and whether the workload needs a persistent endpoint.
* Real-time inference is the right choice for flight departure, arrival, and delay updates because this is an online user-facing workload that requires low latency. AWS states that SageMaker real-time inference is ideal for online inference workloads with low-latency or high-throughput requirements and uses a persistent fully managed endpoint. That fits flight status information because passengers and airline systems expect immediate responses.
* Serverless inference is the best choice for holiday promotional deals because this traffic is spiky, seasonal, and unpredictable. AWS describes SageMaker Serverless Inference as suitable for intermittent or unpredictable traffic patterns. It is cost-effective because SageMaker manages the infrastructure and scales down when there are no requests, so the company does not pay for idle endpoint capacity.
* Batch inference is correct for quarterly and annual flight reports because this workload analyzes large datasets offline and does not need an always-running endpoint. AWS says SageMaker batch transform is used to get inferences from large datasets and when a persistent endpoint is not required. Reports and trend analysis are scheduled, non-real-time analytics workloads, so batch inference is the most cost- effective option.
* Asynchronous inference is the right choice for generating online image and audio stories. These requests can have larger payloads and longer processing times than normal low-latency API calls. AWS states that SageMaker Asynchronous Inference queues incoming requests and is ideal for large payloads, long processing times, and near-real-time latency requirements. Image and audio generation can take seconds or minutes, so asynchronous inference is more appropriate than real-time inference.
質問 # 118
An ML engineer is training an ML model to identify people's health risk based on 20 features and
1 target. The target class has two values:
- Likely to have health risk (positive class)
- Unlikely to have health risk (negative class)
The age range of people in the dataset is 30 years old to 60 years old. Age is one of the features.
The ML engineer analyzes the features. For the positive class, the difference in proportions of labels (DPL) value is (+0.9) for the age range of 40 to 45 compared with all other age ranges.
What should the ML engineer do to correct this data imbalance?
正解:C
解説:
A DPL of +0.9 indicates that the positive class is heavily overrepresented in the 40-45 age range compared to other age ranges. To correct this imbalance, the solution is to undersample the positive class within the 40-45 range, reducing its dominance and improving fairness in the dataset.
質問 # 119
A company needs to combine data from multiple sources. The company must use Amazon Redshift Serverless to query an AWS Glue Data Catalog database and underlying data that is stored in an Amazon S3 bucket.
Select and order the correct steps from the following list to meet these requirements. Select each step one time or not at all. (Select and order three.)
* Attach the IAM role to the Redshift cluster.
* Attach the IAM role to the Redshift namespace.
* Create an external database in Amazon Redshift to point to the Data Catalog schema.
* Create an external schema in Amazon Redshift to point to the Data Catalog database.
* Create an IAM role for Amazon Redshift to use to access only the S3 bucket that contains underlying data.
* Create an IAM role for Amazon Redshift to use to access the Data Catalog and the S3 bucket that contains underlying data.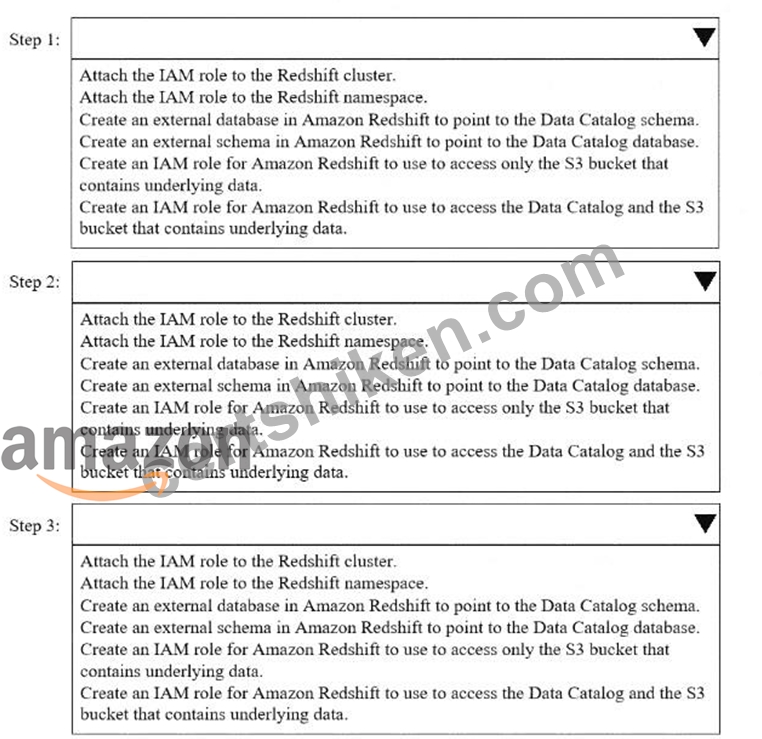
正解:
解説: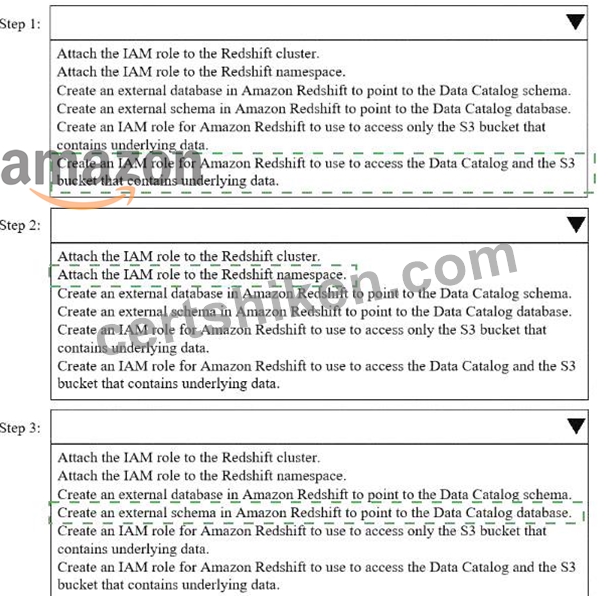
Explanation:
Step 1
Create an IAM role for Amazon Redshift to use to access the Data Catalog and the S3 bucket that contains underlying data.
This role must include:
Permissions for AWS Glue Data Catalog (e.g., glue:GetDatabase, glue:GetTables) Permissions for the Amazon S3 bucket that stores the underlying data Step 2 Attach the IAM role to the Redshift namespace.
Redshift Serverless uses a namespace, not a cluster, so the role must be associated with the namespace to allow Redshift to assume it when querying external data.
Step 3
Create an external schema in Amazon Redshift to point to the Data Catalog database.
The external schema maps Redshift to the Glue Data Catalog database so Redshift can query the tables stored in S3.
質問 # 120
......
「学ぶのに遅すぎることはありません」、MLA-C01認定の準備が一般的になりつつあります。特に今日の職場では、さまざまなトレーニング資料やツールが常に混乱を招き、品質をテストする時間を無駄にしています。実際、当社のMLA-C01テスト問題を完全に信じて、MLA-C01試験に合格することを100%保証します。 MLA-C01のテスト問題を使用した後、残念ながら試験に不合格になった場合、証明証明書により当社から全額返金されます。
MLA-C01対応資料: https://www.certshiken.com/MLA-C01-shiken.html
ちなみに、CertShiken MLA-C01の一部をクラウドストレージからダウンロードできます:https://drive.google.com/open?id=1yXgypTrzFqU4QG3df4QkpEk3A2alXV5_