Reliable NCA-GENM Test Practice - NCA-GENM Exam Revision Plan

2026 Latest ActualVCE NCA-GENM PDF Dumps and NCA-GENM Exam Engine Free Share: https://drive.google.com/open?id=1nSFNC5Ux0v-FpZHWTNJ6Kcpzl0A0U8bi
In order to let you have a deep understanding of our NCA-GENM learning guide, our company designed the trial version for our customers. We will provide you with the trial version of our study materials before you buy our products. If you want to know our NCA-GENM training materials, you can download the trial version from the web page of our company. If you use the trial version of our NCA-GENM Study Materials, you will find that our products are very useful for you to pass your exam and get the certification. If you buy our NCA-GENM exam questions, we can promise that you will enjoy a discount.
| Section | Objectives |
|---|
| Topic 1: Generative AI Concepts | - Generative models
- 1. Transformers and LLM basics
- 2. Diffusion models
|
| Topic 2: Multimodal AI Systems | - Multimodal model design
- Cross-modal learning
- 1. Audio-visual understanding
- 2. Text-image integration
|
| Topic 3: Core AI and Machine Learning Fundamentals | - Machine learning basics
- 1. Supervised and unsupervised learning
- 2. Neural networks fundamentals
|
| Topic 4: Responsible and Trustworthy AI | - Bias and safety considerations
- Ethical AI principles
|
| Topic 5: NVIDIA AI Ecosystem | - NVIDIA tools and frameworks
- 1. GPU-accelerated AI workflows
- 2. NeMo framework usage
|
>> Reliable NCA-GENM Test Practice <<
NCA-GENM Exam Revision Plan, NCA-GENM Latest Test Discount
If you still have no confidence for passing test, here we will recommend you an excellent reference material. Our valid NCA-GENM exam collection pdf will help you pass exam and go to success, you will approach to IT field top. You can just spend short time in preparing for real test with our latest NCA-GENM Exam Collection Pdf. You can download free demo in our website for your reference to verify the reliability of our dumps before purchasing.
NVIDIA Generative AI Multimodal Sample Questions (Q52-Q57):
NEW QUESTION # 52
Consider a scenario where you are training a multimodal Generative A1 model using both image and text dat a. The image data is stored in a directory with millions of high-resolution images, and the text data is in a large CSV file. What is the MOST efficient way to load and preprocess this data for training, minimizing memory usage and maximizing throughput?
- A. Resize all images to a very small size before loading them into memory.
- B. Use a data generator (e.g., TensorFlow's 'tf.data.Dataset' or PyTorch's *DataLoadeN) to load and preprocess data in batches.
- C. Load all images and text data into memory at once, preprocess them, and then feed them to the model.
- D. Use a distributed file system to store the data and load it directly into the model during training.
- E. Convert all images to a single large video file and load it into memory along with the text data.
Answer: B
Explanation:
Data generators are the most efficient way to handle large datasets because they load and preprocess data in batches, minimizing memory usage. Option A is infeasible for large datasets. Option C is not a standard or efficient approach. Option D is relevant for distributed training but doesn't address the memory issue of loading the entire dataset. Option E reduces memory usage but may sacrifice important image details.
NEW QUESTION # 53
Consider the following Python code snippet used for processing image and text data for a multimodal model:
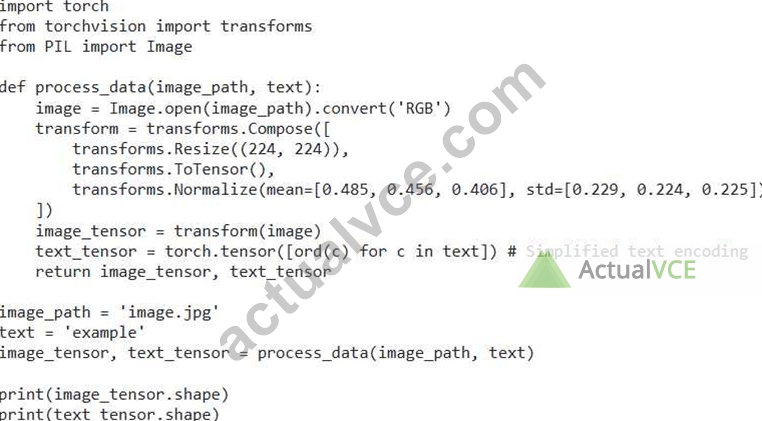
What is the primary limitation of the text encoding method used in this code, and how could it be improved for use in a real-world multimodal model?
- A. The text encoding is efficient but incompatible with common deep learning architectures.
- B. The text encoding is overly complex and should be simplified to reduce computational overhead.
- C. It adequately addresses the complexities inherent in natural language, making it suitable for a variety of multimodal models.
- D. The text encoding only supports ASCII characters and does not account for word embeddings or sequence length variations. Use a tokenizer like BERT or SentencePiece to generate embeddings and pad sequences to a fixed length
- E. The text encoding is suitable for small datasets but will not scale to larger datasets.
Answer: D
Explanation:
The code simply converts each character to its ASCII value, which loses semantic meaning and doesn't handle variable-length sequences or word relationships. Real-world models use tokenizers and embeddings to capture the nuances of language. BERT and SentencePiece are common tools for this. Option B accurately describes this limitation and suggests a practical solution.
NEW QUESTION # 54
You are using NeMo to fine-tune a pre-trained language model for a specific text generation task. You want to implement a custom data augmentation technique to improve the model's robustness. Which of the following approaches is most appropriate for integrating your custom augmentation within the NeMo framework?
- A. Monkey-patch the existing NeMo data loading functions to inject your augmentation logic.
- B. Augment the data directly within the training loop, applying transformations to each batch before feeding it to the model. method.
- C. Use a separate data processing pipeline outside of NeMo and save the augmented data to disk before training.
- D. Modify the core NeMo library files to directly incorporate your augmentation logic.
- E. Create a custom *Dataset* class that inherits from 'nemo.core.Dataset' and implements your augmentation within the '_getitem
Answer: E
Explanation:
Creating a custom 'Dataset' class that inherits from 'nemo.core.Dataset' is the recommended and most maintainable way to integrate custom data augmentation in NeMo. This allows you to leverage NeMo's data loading and processing pipelines while seamlessly incorporating your specific augmentation logic within the '_getitem method. Modifying core NeMo files (A) is strongly discouraged. Using a separate pipeline (C) disconnects augmentation from the NeMo workflow. Monkey-patching (D) is brittle. Augmenting within the training loop (E) can be inefficient.
NEW QUESTION # 55
You are deploying a multimodal model that uses both video and audio data for real-time emotion recognition. The model is deployed on an edge device with limited computational resources. Which optimization techniques would be MOST effective for reducing latency and improving the model's inference speed on the edge device?
- A. Increasing the resolution of the video input.
- B. Using full precision (FP32) for all model operations.
- C. Quantizing the model to a lower precision (e.g., INT8) and pruning less important connections.
- D. Transmitting the video and audio data to a cloud server for inference.
- E. Increasing the model's complexity to improve accuracy.
Answer: C
Explanation:
Quantization to a lower precision (e.g., INT8) significantly reduces the model size and computational requirements, leading to faster inference speeds on edge devices. Pruning further reduces the model's complexity. Increasing model complexity (A) or using FP32 (B) would increase latency. Offloading to the cloud (D) introduces network latency. Increasing video resolution (E) increases the computational load.
NEW QUESTION # 56
You are developing a multimodal system for medical diagnosis using MRI images and patient history text. Your initial model performs poorly on patients with rare conditions. Which of the following data augmentation techniques would be MOST effective in improving the model's performance on these under-represented cases?
- A. Using a Generative Adversarial Network (GAN) to synthesize new MRI images conditioned on the patient history text, specifically targeting the rare conditions-
- B. Back-translating the patient history text to generate paraphrased versions-
- C. Adding Gaussian noise to the pixel values of MRI images.
- D. Replacing named entities in the patient history text with other random entities-
- E. Randomly cropping and rotating MRI images.
Answer: A
Explanation:
Using a GAN to synthesize new data specifically for rare conditions is the most effective option. It directly addresses the class imbalance problem by creating more examples of the under-represented cases, conditioned on both the image and text modalities. While random image augmentations (AD) and text paraphrasing (B) can help, they don't directly target the rare conditions. Entity replacement could change the meaning of the history.
NEW QUESTION # 57
......
With these mock exams, it is easy to track your progress by monitoring your marks each time you go through the NCA-GENM practice test. Our NCA-GENM practice exams will give you an experience of attempting the NCA-GENM original examination. You will be able to deal with the actual exam pressure better when you have already experienced it in our NVIDIA NCA-GENM practice exams.
NCA-GENM Exam Revision Plan: https://www.actualvce.com/NVIDIA/NCA-GENM-valid-vce-dumps.html
- NCA-GENM Latest Exam Pdf 🥊 NCA-GENM Latest Exam Pdf 😼 Knowledge NCA-GENM Points 🤞 Simply search for ➠ NCA-GENM 🠰 for free download on [ www.practicevce.com ] 😻NCA-GENM Testking Learning Materials
- NCA-GENM Upgrade Dumps 🎢 Dump NCA-GENM Collection 👟 NCA-GENM Frenquent Update 🦰 Search on ✔ www.pdfvce.com ️✔️ for ➤ NCA-GENM ⮘ to obtain exam materials for free download 🏂NCA-GENM Frenquent Update
- NCA-GENM Latest Exam Notes 🦱 New NCA-GENM Test Labs 🚬 Reliable NCA-GENM Exam Braindumps 📋 ⮆ www.pass4test.com ⮄ is best website to obtain ➥ NCA-GENM 🡄 for free download 👶NCA-GENM Testking Learning Materials
- 2026 NVIDIA NCA-GENM Authoritative Reliable Test Practice 🐽 Simply search for ▶ NCA-GENM ◀ for free download on ➽ www.pdfvce.com 🢪 🦧NCA-GENM Latest Braindumps Pdf
- NCA-GENM Valid Vce 🔩 New NCA-GENM Mock Test 🐡 New NCA-GENM Exam Objectives 🥭 Search on “ www.examcollectionpass.com ” for ☀ NCA-GENM ️☀️ to obtain exam materials for free download ⭐NCA-GENM Test Engine Version
- NVIDIA NCA-GENM Dumps - Hassle-Free Accomplishment 🌉 Search for ▛ NCA-GENM ▟ and easily obtain a free download on ➡ www.pdfvce.com ️⬅️ 🎈NCA-GENM Latest Braindumps Pdf
- Download Free Updated www.testkingpass.com NVIDIA NCA-GENM Dumps PDF after Paying Affordable Charges ⭐ Search for ⏩ NCA-GENM ⏪ and obtain a free download on ⏩ www.testkingpass.com ⏪ 📝NCA-GENM Test Engine Version
- NCA-GENM Latest Braindumps Pdf 🍚 NCA-GENM Latest Exam Pattern 🥂 NCA-GENM Upgrade Dumps 🧑 Search for ⇛ NCA-GENM ⇚ and obtain a free download on ☀ www.pdfvce.com ️☀️ 💘New NCA-GENM Study Plan
- NCA-GENM Reliable Exam Pdf 🎃 Reliable NCA-GENM Exam Braindumps 🦘 New NCA-GENM Test Labs 🎅 Search for ➤ NCA-GENM ⮘ and obtain a free download on { www.verifieddumps.com } 🕴Reliable NCA-GENM Exam Braindumps
- Pass Guaranteed 2026 Latest NVIDIA Reliable NCA-GENM Test Practice 🌽 Search for 「 NCA-GENM 」 on 《 www.pdfvce.com 》 immediately to obtain a free download 🛫NCA-GENM Latest Exam Pattern
- NCA-GENM Valid Vce 🍀 NCA-GENM Positive Feedback ☁ NCA-GENM Latest Exam Pdf 🛅 Simply search for ▷ NCA-GENM ◁ for free download on ▶ www.prepawayete.com ◀ 🚞NCA-GENM Reliable Exam Pdf
- www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, blogfreely.net, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.bandlab.com, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, Disposable vapes
P.S. Free & New NCA-GENM dumps are available on Google Drive shared by ActualVCE: https://drive.google.com/open?id=1nSFNC5Ux0v-FpZHWTNJ6Kcpzl0A0U8bi