BONUS!!! Download part of BraindumpStudy MLA-C01 dumps for free: https://drive.google.com/open?id=1TbAXKKjcWDFboa_gfZqX361YuDsPLklY
Due to busy routines, applicants of the AWS Certified Machine Learning Engineer - Associate (MLA-C01) exam need real AWS Certified Machine Learning Engineer - Associate (MLA-C01) exam questions. When they don't study with updated Amazon MLA-C01 practice test questions, they fail and lose money. If you want to save your resources, choose updated and actual AWS Certified Machine Learning Engineer - Associate (MLA-C01) exam questions of BraindumpStudy.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
| Topic 4 |
|
In order to meet different needs of our customers, we offer you three versions of MLA-C01 study materials for you. Each version has its own advantages, and you can choose the most suitable one according to your own needs. MLA-C01 PDF version is printable, and if you like paper one, you can choose this version. MLA-C01 soft test engine can stimulate the real exam environment, and you can build your confidence if you choose this version. MLA-C01 Online test engine can practice offline and can record the training process, if you have the needs like this, you can choose this version.
NEW QUESTION # 40
An ML engineer is developing a classification model. The ML engineer needs to use custom libraries in processing jobs, training jobs, and pipelines in Amazon SageMaker AI.
Which solution will provide this functionality with the LEAST implementation effort?
Answer: C
Explanation:
AWS documentation strongly recommends using custom Docker containers when ML workloads require consistent access to custom dependencies across processing jobs, training jobs, and pipelines.
By building a single Docker image that contains all required libraries and hosting it in Amazon ECR, the ML engineer ensures that every SageMaker job uses the same runtime environment. This approach eliminates the need for repetitive installation steps and avoids environment drift.
Manually installing libraries in managed containers is error-prone and not reusable across jobs. Notebook instances are not designed to host production jobs and pipelines. Running code externally breaks the SageMaker workflow and increases operational complexity.
Using a custom container is a one-time setup that provides maximum reuse with minimal ongoing effort, making it the least implementation effort option in the long run.
Therefore, Option B is the correct and AWS-recommended answer.
NEW QUESTION # 41
A company uses a batching solution to process data analytics each day. The company wants to build an analytics platform to provide near real-time updates. The company wants to use open source technology and does not want to manage or scale the infrastructure.
Which solution will meet these requirements?
Answer: B
Explanation:
The correct answer is A. Create Amazon Managed Streaming for Apache Kafka (Amazon MSK) Serverless clusters to process the data.
Amazon MSK Serverless allows organizations to run Apache Kafka workloads without managing or provisioning the underlying infrastructure. Unlike MSK Provisioned clusters (Option B), serverless clusters automatically scale to accommodate variable workloads and handle operational tasks such as patching, scaling, and monitoring. This meets the company's requirement to avoid managing or scaling infrastructure while providing near real-time streaming analytics.
Option C, using Amazon Kinesis Data Streams with Application Auto Scaling, provides a managed streaming solution but is not based on open-source technology. While Kinesis can handle near real-time data, the question specifically emphasizes the company's desire for open-source technology, which points toward Kafka.
Option D, self-hosting Apache Flink on EC2, requires manual management of servers, scaling, patching, and container orchestration. This approach contradicts the requirement of not managing or scaling infrastructure and introduces operational complexity.
MSK Serverless provides seamless integration with open-source Kafka APIs, enabling applications to produce and consume streaming data in real time while AWS handles scaling and availability. It is ideal for analytics pipelines where data ingestion is continuous and variable, and infrastructure overhead must be minimized.
By choosing MSK Serverless, the company can implement near real-time updates for its analytics platform using open-source Kafka without the operational burden of cluster management, fully aligning with AWS best practices for deployment and orchestration of ML workflows in a managed, scalable, and serverless manner.
NEW QUESTION # 42
An ML engineer needs to use data with Amazon SageMaker Canvas to train an ML model. The data is stored in Amazon S3 and is complex in structure. The ML engineer must use a file format that minimizes processing time for the data.
Which file format will meet these requirements?
Answer: A
Explanation:
Apache Parquet is a columnar storage file format optimized for complex and large datasets. It provides efficient reading and processing by accessing only the required columns, which reduces I/O and speeds up data handling. This makes it ideal for use with Amazon SageMaker Canvas, where minimizing processing time is important for training ML models. Parquet is also compatible with S3 and widely supported in data analytics and ML workflows.
NEW QUESTION # 43
A company has multiple models that are hosted on Amazon SageMaker Al. The models need to be re-trained.
The requirements for each model are different, so the company needs to choose different deployment strategies to transfer all requests to a new model.
Select the correct strategy from the following list for each requirement. Select each strategy one time. (Select THREE.)
. Canary traffic shifting
. Linear traffic shifting guardrail
. All at once traffic shifting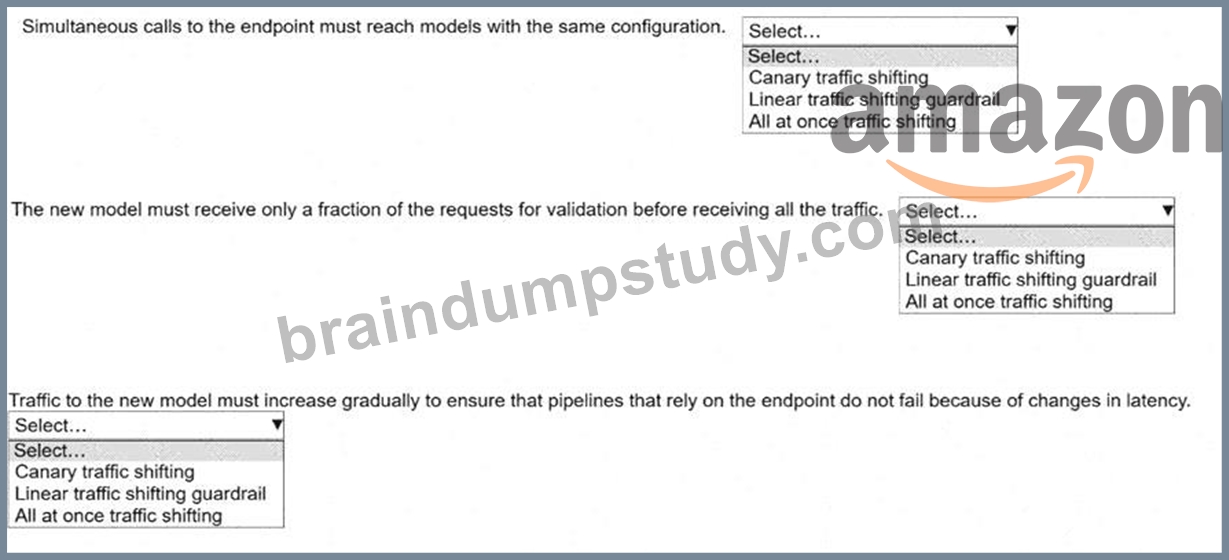
Answer:
Explanation: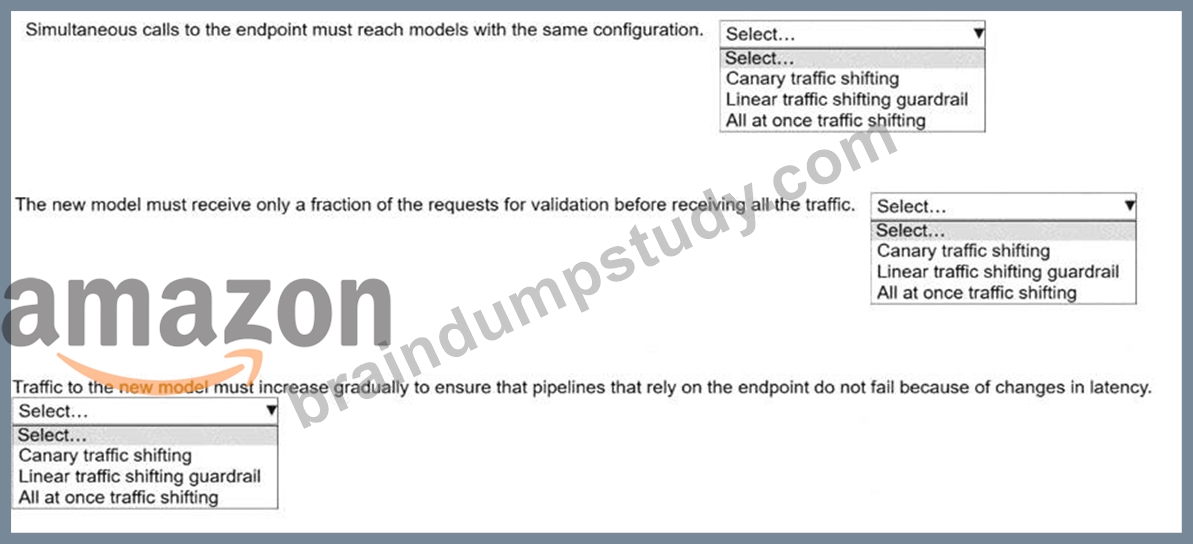
Explanation:
1## Simultaneous calls to the endpoint must reach models with the same configuration Correct strategy: All at once traffic shifting Why:
"All at once" replaces the old model with the new model immediately. After the switch, all concurrent requests hit only the new model configuration, guaranteeing configuration consistency across simultaneous calls.
2## The new model must receive only a fraction of the requests for validation before receiving all the traffic Correct strategy: Canary traffic shifting Why:
Canary deployments route a small percentage of traffic (for example, 5% or 10%) to the new model first. This allows validation of correctness and performance before shifting 100% of traffic.
3## Traffic to the new model must increase gradually to ensure that pipelines that rely on the endpoint do not fail because of changes in latency Correct strategy: Linear traffic shifting guardrail Why:
Linear traffic shifting gradually increases traffic in equal increments over time and includes guardrails (such as CloudWatch alarms) to automatically roll back if latency or errors exceed thresholds.
NEW QUESTION # 44
A company is developing an ML model for a customer. The training data is stored in an Amazon S3 bucket in the customer's AWS account (Account A). The company runs Amazon SageMaker AI training jobs in a separate AWS account (Account B).
The company defines an S3 bucket policy and an IAM policy to allow reads to the S3 bucket.
Which additional steps will meet the cross-account access requirement?
Answer: A
Explanation:
For cross-account Amazon S3 access, AWS requires two components:
* An S3 bucket policy in the owning account (Account A) that grants access to a principal in another account
* An IAM role policy in the consuming account (Account B) that allows the service to access the bucket Amazon SageMaker training jobs assume an IAM role in the account where the job runs-in this case, Account B. Therefore, the IAM policy must be attached to the SageMaker execution role in Account B.
The S3 bucket policy must reside in Account A because bucket policies are owned and enforced by the bucket owner. This policy explicitly allows the IAM role from Account B to read the training data.
Any other combination fails either because the policy is in the wrong account or because the role is not the one used by SageMaker.
AWS documentation clearly describes this pattern as the correct way to grant cross-account access for SageMaker training jobs.
Therefore, Option B is the correct and AWS-aligned solution.
NEW QUESTION # 45
......
If you want to buy our MLA-C01 training engine, you must ensure that you have credit card. We do not support deposit card and debit card to pay for the MLA-C01 exam questions. Also, the system will deduct the relevant money. If you find that you need to pay extra money for the MLA-C01 Study Materials, please check whether you choose extra products or there is intellectual property tax. All in all, you will receive our MLA-C01 learning guide via email in a few minutes.
Valid MLA-C01 Test Pattern: https://www.braindumpstudy.com/MLA-C01_braindumps.html
BONUS!!! Download part of BraindumpStudy MLA-C01 dumps for free: https://drive.google.com/open?id=1TbAXKKjcWDFboa_gfZqX361YuDsPLklY