P.S. Free 2026 Databricks Databricks-Certified-Data-Engineer-Associate dumps are available on Google Drive shared by ExamDiscuss: https://drive.google.com/open?id=1Flz0A5oE7PHoyMnjJ-0SaUD35FIkmCZO
And you can also use the Databricks Databricks-Certified-Data-Engineer-Associate PDF on smart devices like smartphones, laptops, and tablets. The second one is the web-based Databricks Databricks-Certified-Data-Engineer-Associate practice exam which can be accessed through the browsers like Firefox, Safari, and Databricks Chrome. The customers don't need to download or install excessive plugins or software to get the full advantage from web-based Databricks-Certified-Data-Engineer-Associate Practice Tests.
| Section | Objectives |
|---|---|
| Topic 1: Data Processing and Transformations | - PySpark DataFrame transformations - Apache Spark SQL operations (joins, aggregations, filtering) - User-defined functions (UDFs) - Delta Lake fundamentals (tables, transactions, optimization) |
| Topic 2: Data Ingestion and ELT Development | - ETL patterns and transformations - Handling structured and semi-structured data - Data ingestion using Spark SQL and PySpark |
| Topic 3: Data Governance and Quality | - Unity Catalog basics - Data quality concepts and management - Data access control and governance |
| Topic 4: Productionizing Data Pipelines | - Scheduling and monitoring jobs - Databricks Workflows / Jobs orchestration - Pipeline deployment and operationalization |
| Topic 5: Databricks Lakehouse Platform Fundamentals | - Clusters, notebooks, and basic Databricks environment usage - Workspace, architecture, and core platform concepts |
>> Latest Databricks-Certified-Data-Engineer-Associate Study Materials <<
Databricks-Certified-Data-Engineer-Associate certification exam opens the doors for starting a bright career. After passing the Databricks Certified Data Engineer Associate Exam Databricks-Certified-Data-Engineer-Associate test you will easily apply for well-paid jobs in top companies all over the world. Databricks-Certified-Data-Engineer-Associate exam offers multiple advantages including, high salaries, promotions, enhancing resumes, and skills improvement. Once you pass the Databricks-Certified-Data-Engineer-Associate Exam, you can avail all these benefits. If you want to pass the Databricks Databricks-Certified-Data-Engineer-Associate certification exam, you must find the best resource to prepare for the Databricks-Certified-Data-Engineer-Associate test.
NEW QUESTION # 216
A data engineer is developing a small proof of concept in a notebook. When running the entire notebook, cluster usage spikes. The data engineer wants to keep the development experience and get real-time results.
Which cluster meets these requirements?
Answer: B
Explanation:
For interactive notebook development, Databricks distinguishes between all-purpose compute and job compute. All-purpose compute is designed for analysis, notebook development, and interactive workloads, while job compute is intended for automated scheduled or triggered jobs. Because the engineer is actively developing a proof of concept in a notebook and wants real-time feedback, an all-purpose cluster is the right compute type. Adding autoscaling makes it better suited to the observed usage spikes, because the cluster can expand when notebook execution demands more resources and scale down afterward, reducing waste compared with a large fixed-size cluster. That makes option B the best answer. Option A keeps the interactive development model, but the fixed large size is less efficient. Options C and D use job clusters, which are better aligned with production jobs rather than iterative notebook-based development. Databricks documentation consistently positions all-purpose compute for collaborative and interactive development, and autoscaling is a standard mechanism to handle variable workloads more efficiently.
=========
NEW QUESTION # 217
A data engineer is attempting to drop a Spark SQL table my_table. The data engineer wants to delete all table metadata and data.
They run the following command:
DROP TABLE IF EXISTS my_table
While the object no longer appears when they run SHOW TABLES, the data files still exist.
Which of the following describes why the data files still exist and the metadata files were deleted?
Answer: C
Explanation:
Explanation
The reason why the data files still exist while the metadata files were deleted is because the table was external.
When a table is external in Spark SQL (or in other database systems), it means that the table metadata (such as schema information and table structure) is managed externally, and Spark SQL assumes that the data is managed and maintained outside of the system. Therefore, when you execute a DROP TABLE statement for an external table, it removes only the table metadata from the catalog, leaving the data files intact. On the other hand, for managed tables (option E), Spark SQL manages both the metadata and the data files. When you drop a managed table, it deletes both the metadata and the associated data files, resulting in a complete removal of the table.
NEW QUESTION # 218
A data engineer wants to schedule their Databricks SQL dashboard to refresh every hour, but they only want the associated SQL endpoint to be running when It is necessary. The dashboard has multiple queries on multiple datasets associated with it. The data that feeds the dashboard is automatically processed using a Databricks Job.
Which approach can the data engineer use to minimize the total running time of the SQL endpoint used in the refresh schedule of their dashboard?
Answer: B
Explanation:
To minimize the total running time of the SQL endpoint used in the refresh schedule of a dashboard in Databricks, the most effective approach is to utilize the Auto Stop feature. This feature allows the SQL endpoint to automatically stop after a period of inactivity, ensuring that it only runs when necessary, such as during the dashboard refresh or when actively queried. This minimizes resource usage and associated costs by ensuring the SQL endpoint is not running idle outside of these operations.
References:Databricks documentation on SQL endpoints: SQL Endpoints in Databricks
NEW QUESTION # 219
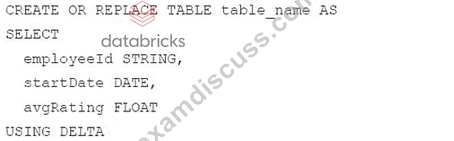
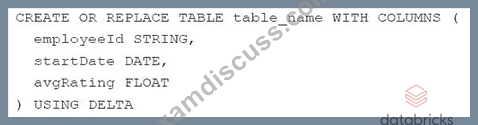
A data architect has determined that a table of the following format is necessary: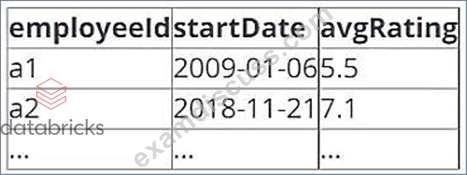
Which of the following code blocks uses SQL DDL commands to create an empty Delta table in the above format regardless of whether a table already exists with this name?
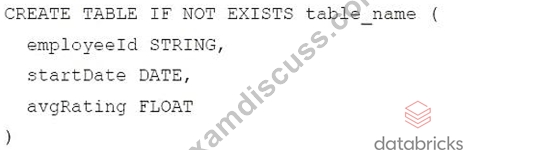
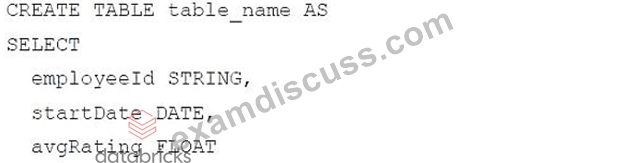
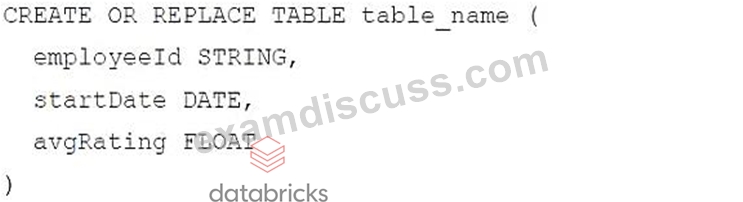
Answer: C
NEW QUESTION # 220
In which of the following scenarios should a data engineer select a Task in the Depends On field of a new Databricks Job Task?
Answer: D
Explanation:
A data engineer can create a multi-task job in Databricks that consists of multiple tasks that run in a specific order. Each task can have one or more dependencies, which are other tasks that must run before the current task. The Depends On field of a new Databricks Job Task allows the data engineer to specify the dependencies of the task. The data engineer should select a task in the Depends On field when they want the new task to run only after the selected task has successfully completed. This can help the data engineer to create a logical sequence of tasks that depend on each other's outputs or results. For example, a data engineer can create a multi-task job that consists of the following tasks:
Task A: Ingest data from a source using Auto Loader
Task B: Transform the data using Spark SQL
Task C: Write the data to a Delta Lake table
Task D: Analyze the data using Spark ML
Task E: Visualize the data using Databricks SQL
In this case, the data engineer can set the dependencies of each task as follows:
Task A: No dependencies
Task B: Depends on Task A
Task C: Depends on Task B
Task D: Depends on Task C
Task E: Depends on Task D
This way, the data engineer can ensure that each task runs only after the previous task has successfully completed, and the data flows smoothly from ingestion to visualization.
The other options are incorrect because they do not describe valid scenarios for selecting a task in the Depends On field. The Depends On field does not affect the following aspects of a task:
Whether the task needs to be replaced by another task
Whether the task needs to fail before another task begins
Whether the task has the same dependency libraries as another task
Whether the task needs to use as little compute resources as possible Reference: Create a multi-task job, Run tasks conditionally in a Databricks job, Databricks Jobs.
NEW QUESTION # 221
......
In order to gain the Databricks-Certified-Data-Engineer-Associate certification quickly, people have bought a lot of Databricks-Certified-Data-Engineer-Associate study materials, but they also find that these materials don't suitable for them and also cannot help them. If you also don't find the suitable Databricks-Certified-Data-Engineer-Associate test guide, we are willing to recommend that you should use our Databricks-Certified-Data-Engineer-Associate Study Materials. Because our products will help you solve the problem, it will never let you down if you decide to purchase and practice our Databricks-Certified-Data-Engineer-Associate latest question. And our Databricks-Certified-Data-Engineer-Associate exam questions have a high pass rate of 99% to 100%.
Reliable Databricks-Certified-Data-Engineer-Associate Test Pass4sure: https://www.examdiscuss.com/Databricks/exam/Databricks-Certified-Data-Engineer-Associate/
P.S. Free & New Databricks-Certified-Data-Engineer-Associate dumps are available on Google Drive shared by ExamDiscuss: https://drive.google.com/open?id=1Flz0A5oE7PHoyMnjJ-0SaUD35FIkmCZO