BTW, DOWNLOAD part of NewPassLeader SPS-C01 dumps from Cloud Storage: https://drive.google.com/open?id=14QdSUSJP57XWfuikgQoXaPq5ztxBng3f
Every year, countless Snowflake aspirants face challenges to prove their skills and knowledge by attempting the Snowflake SPS-C01 certification exam. Once they pass this examination, lucrative job opportunities in the tech industry await them. But fear not! NewPassLeader has got you covered with their collection of real and updated SPS-C01 Exam Questions. These affordable SPS-C01 questions are available in three user-friendly formats, ensuring a smooth and efficient preparation experience for the SPS-C01 exam.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Snowpark API for Python | 30% | - Reading and writing data - User-Defined Functions (UDFs) and Stored Procedures - Establishing connections and session management - Working with Semi-structured data - DataFrame creation and manipulation |
| Topic 2: Snowpark Concepts | 15% | - Stored procedures and conditional logic - Transformations vs. Actions - Snowpark DataFrames and query plans - Snowpark Sessions and connection management - Client-side vs. Server-side execution - Snowpark architecture and core concepts |
| Topic 3: Performance Optimization and Best Practices | 20% | - Debugging and explain plans - Warehouse sizing for Snowpark - Minimizing data transfer - Vectorized UDFs - Query pushdown and optimization - Caching strategies |
| Topic 4: Data Transformations and DataFrame Operations | 35% | - Using built-in functions - Filtering, Aggregating, and Joining DataFrames - Window functions - Persisting transformed data - Complex data pipelines |
NewPassLeader is a leading platform that is committed to offering to make the Snowflake Exam Questions preparation simple, smart, and successful. To achieve this objective NewPassLeader has got the services of experienced and qualified SPS-C01 Exam trainers. They work together and put all their efforts and ensure the top standard of NewPassLeader Snowflake SPS-C01 exam dumps all the time.
NEW QUESTION # 118
A data engineering team is building a Snowpark pipeline to process IoT sensor data'. They want to create a UDF that uses a 3rd-party Python library (not available in Snowflake's Anaconda channel) to analyze the sensor readings. The UDF needs to be efficiently deployed and managed within Snowflake. Which of the following approaches represents the MOST robust and scalable way to register and deploy this UDF using Snowpark?
Answer: A
Explanation:
Option B is the correct answer. It describes the best practice for deploying UDFs with external Python libraries in Snowflake. Creating a virtual environment, zipping it, uploading it to a stage, and referencing it during UDF registration ensures proper dependency management and avoids conflicts. Option A is problematic because embedding the library directly makes the UDF definition very large and unmanageable. Option C will not work if the required version isn't available. Option D is incorrect because functions.udf relies on packages available in the Snowflake Anaconda channel and doesn't manage custom packages. While Option E could work, its overly complex for this specific scenario compared to utilizing Snowpark virtual enviornment and stage management. Option B is more efficient and streamlined.
NEW QUESTION # 119
You have a Snowpark application that processes sensor data from a large number of devices. You've implemented a scalar UDF in Python to calculate a complex statistical metric for each sensor reading. Initial tests show poor performance. Which of the following strategies would be MOST effective in improving the performance of this application, considering the nature of the computation and the data volume?
Answer: E
Explanation:
Vectorized UDFs process data in batches (vectors), significantly reducing the overhead associated with individual row processing, which is the primary bottleneck of scalar UDFs. While increasing warehouse size (C) might provide some improvement, it doesn't address the fundamental inefficiency of scalar processing. Java might be faster (A), but the biggest gain comes from vectorization. Caching (D) is useful for repeated calculations, but doesn't address the inherent UDF overhead if computations are unique. SQL (E) is good, but might not be possible due to the complexity.
NEW QUESTION # 120
You have a Snowpark DataFrame 'sales df with columns 'product_id' (INTEGER), 'sale date' (DATE), and 'sale_amount' (DOUBLE). You need to filter the DataFrame to include only sales that occurred in the year 2023 and where the 'sale_amount' is greater than the average 'sale_amount' for that specific 'product id'. Which of the following Snowpark Python code snippets will correctly achieve this?





Answer: B
Explanation:
Option C is the most efficient and correct. It calculates the average sale amount per product ID using a window function and then filters the DataFrame based on both the year and the comparison with the average. It avoids joins and 'collect()' which can be inefficient. Option A doesn't import Window or properly use avg over a window, causing an error. Option B requires a join, which is less efficient. Option D uses "mean' which is available but 'avg' is preferrable. Option E 'collects data to the client which is also generally avoided in Snowpark.
NEW QUESTION # 121
You have a Snowpark DataFrame named with columns 'category', , and You want to perform the following transformations using Snowpark:





Answer: C
Explanation:
Option E is correct, because the 'pivot' operation needs to be inside 'groupBy' . It first groups the data by 'category', then pivots the data based on the 'date' column, aggregating the 'value' column using the sum function. Options A,B,C, and D, will cause a Snowflake error.
NEW QUESTION # 122
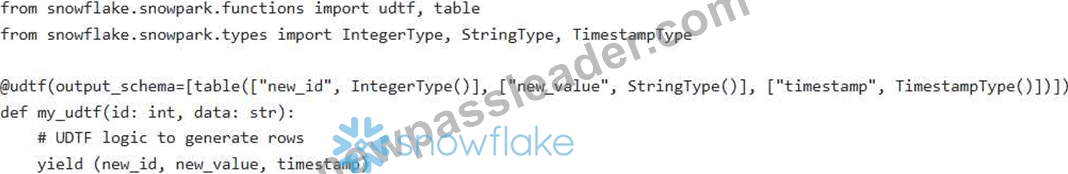
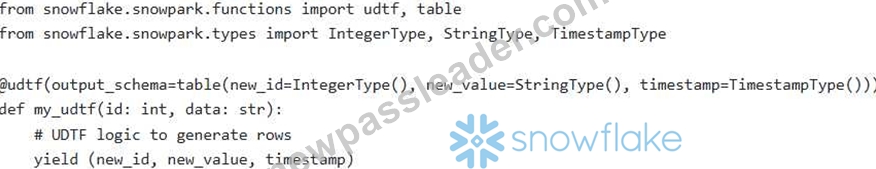
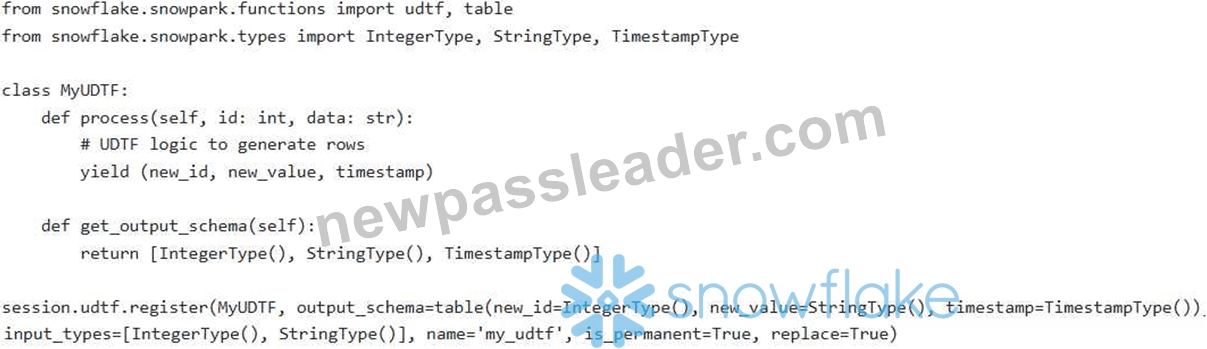
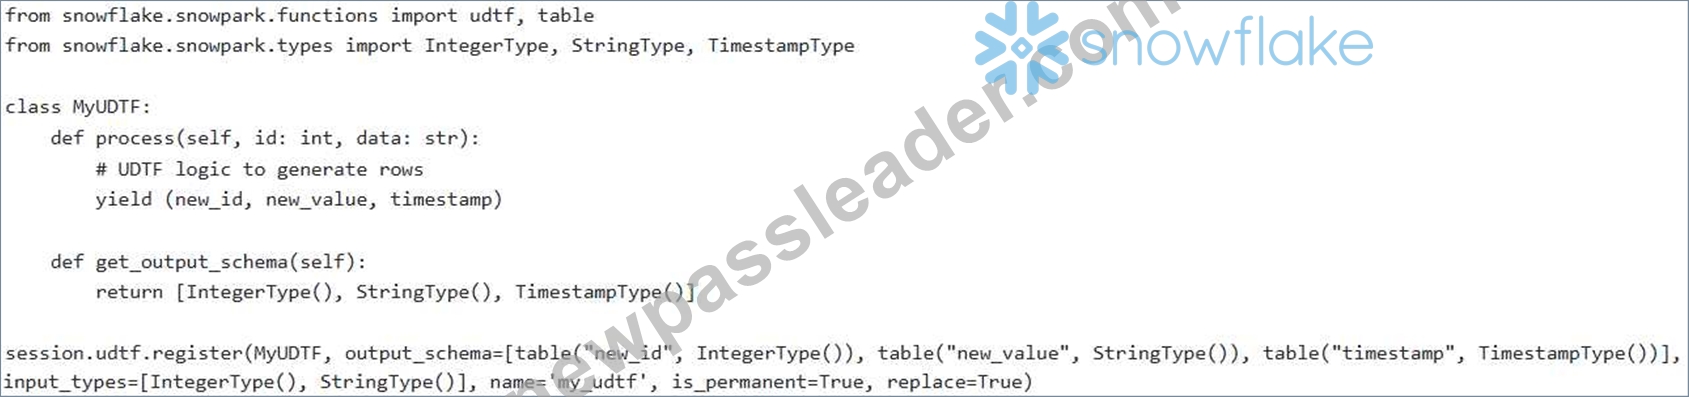
You have a Python function that performs complex data transformations, too intricate to express directly in Snowpark SQL. You want to register this as a User-Defined Table Function (UDTF) so that it can be used to expand rows in a Snowpark DataFrame. The UDTF takes two arguments: an ID (integer) and a string. It returns a table with three columns: (integer), (string), and 'timestamp' (timestamp). Which of the following code snippets correctly registers this UDTF, making it available for use within Snowpark?
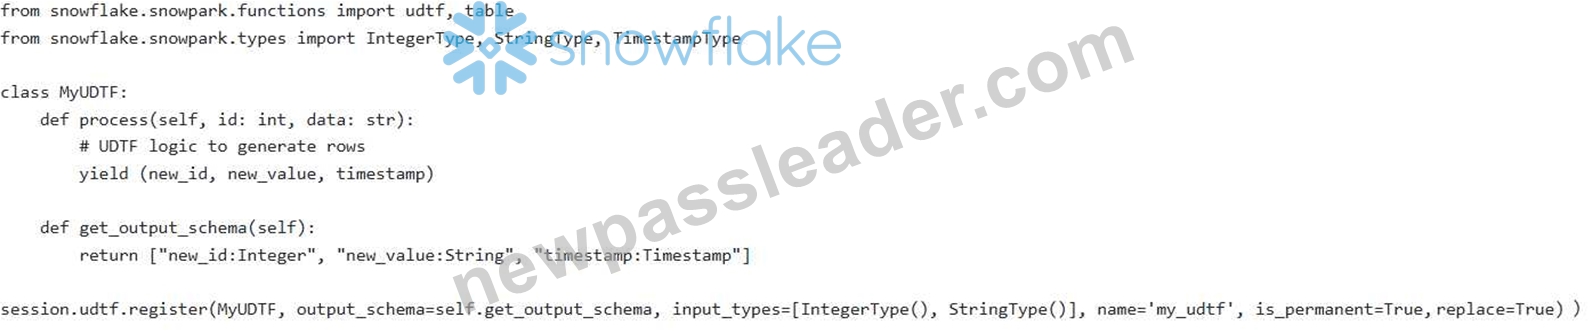
Answer: C
Explanation:
Option C provides the correct way to define and register UDTFs using the class-based approach in Snowpark. It defines the UDTF class with 'process' and methods. returns the schema using 'table' function correctly. Options A and B use the decorator approach, which is valid for simple UDTFs, but it's less flexible than the class-based approach, especially for managing complex state or schema. Option D uses the class-based approach but incorrectly defines the 'output_schema' when registering. Option E has an incorrect definition of return type.
NEW QUESTION # 123
......
If you want to SPS-C01 practice testing the product of NewPassLeader, feel free to try a free demo and overcome your doubts. A full refund offer according to terms and conditions is also available if you don't clear the Snowflake Certified SnowPro Specialty - Snowpark (SPS-C01) practice test after using the Snowflake Certified SnowPro Specialty - Snowpark (SPS-C01) exam product. Purchase NewPassLeader best SPS-C01 study material today and get these stunning offers.
Useful SPS-C01 Dumps: https://www.newpassleader.com/Snowflake/SPS-C01-exam-preparation-materials.html
DOWNLOAD the newest NewPassLeader SPS-C01 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=14QdSUSJP57XWfuikgQoXaPq5ztxBng3f