To obtain the Databricks certificate is a wonderful and rapid way to advance your position in your career. In order to reach this goal of passing the Certified-Data-Engineer-Professional exam, you need more external assistance to help yourself. You are lucky to click into this link for we are the most popular vendor in the market. We have engaged in this career for more than ten years and with our Certified-Data-Engineer-Professional Exam Questions, you will not only get aid to gain your dreaming Databricks certification, but also you can enjoy the first-class service online.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Security and Governance | ~10% | - Manage Unity Catalog permissions and ACLs - Implement row-level security, column masking, and compliance |
| Topic 2: Developing Code for Data Processing using Python and SQL | ~22% | - Build pipelines with Lakeflow Spark Declarative Pipelines and Auto Loader - Manage dependencies, libraries, and UDFs - Implement scalable Python/SQL code and project structures |
| Topic 3: Data Transformation, Cleansing, and Quality | ~12% | - Apply advanced Spark transformations - Enforce data quality and quarantine bad data |
| Topic 4: Monitoring, Logging, and Troubleshooting | ~8% | - Diagnose common pipeline and job failures - Use Spark UI, Query Profiler, and system tables |
| Topic 5: CI/CD, Testing, and Deployment | ~6% | - Implement testing and deployment pipelines - Deploy with Declarative Automation Bundles, CLI, and REST API |
| Topic 6: Data Sharing and Federation | ~8% | - Configure Delta Sharing and Lakehouse Federation |
| Topic 7: Streaming Workloads and Change Data Capture | ~11% | - Implement reliable streaming pipelines - Apply AUTO CDC APIs and exactly-once semantics |
| Topic 8: Cost and Performance Optimization | ~13% | - Leverage system tables and observability tools - Optimize queries, clusters, and storage |
| Topic 9: Data Modeling | ~10% | - Design scalable Delta Lake schemas and clustering - Apply dimensional modeling techniques |
>> Certified-Data-Engineer-Professional Exam Objectives <<
Candidates can also check the explanations for the answers to have more understanding of the Databricks Certified-Data-Engineer-Professional questions that are asked on the Certified-Data-Engineer-Professional practice test by Actual4Cert You can customize the Databricks Certified-Data-Engineer-Professional exam questions and time for the Certified-Data-Engineer-Professional practice exam on the software. Assessing their Databricks Certified-Data-Engineer-Professional Exam Preparation and speed on the practice exam software helps candidates in making required improvements and succeeding at the Databricks Certified-Data-Engineer-Professional exam. The software by Actual4Cert gives the candidates the results and progress reports to help them monitor their performance for the Databricks Certified-Data-Engineer-Professional exam.
NEW QUESTION # 28
What describes a primary technical challenge in ensuring consistent PII masking across all nodes in large-scale, distributed Databricks batch and streaming pipelines?
Answer: A
Explanation:
Consistent PII masking in distributed batch and streaming pipelines requires centrally defined and governed masking logic. Standardizing masking functions and enforcing them through Unity Catalog ensures that the same rules are applied uniformly across all datasets and execution paths, preventing inconsistencies across nodes and workloads.
NEW QUESTION # 29
A data engineer is implementing a job to download multiple PDF files from a third-party provided REST API endpoint by specifying different report types. The REST API is time-consuming and encounters intermittent errors, so the engineer wants to track each download activity to know when it fails and to retry partially, while providing scalable throughput. The engineer needs to download ten report types, and the list can be changed over time. How should the data engineer achieve this?
Answer: D
Explanation:
A foreach task allows the job to dynamically iterate over a configurable list of report types, execute downloads in parallel, and track the success or failure of each item independently. This enables scalable throughput, partial retries for failed downloads, and easy updates when the list of report types changes, without hardcoding tasks or introducing unnecessary complexity.
NEW QUESTION # 30
A Delta Lake table was created with the below query: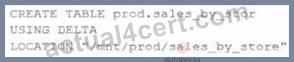
Realizing that the original query had a typographical error, the below code was executed:
ALTER TABLE prod.sales_by_stor RENAME TO prod.sales_by_store
Which result will occur after running the second command?
Answer: A
Explanation:
The query uses the CREATE TABLE USING DELTA syntax to create a Delta Lake table from an existing Parquet file stored in DBFS. The query also uses the LOCATION keyword to specify the path to the Parquet file as /mnt/finance_eda_bucket/tx_sales.parquet. By using the LOCATION keyword, the query creates an external table, which is a table that is stored outside of the default warehouse directory and whose metadata is not managed by Databricks. An external table can be created from an existing directory in a cloud storage system, such as DBFS or S3, that contains data files in a supported format, such as Parquet or CSV.
The result that will occur after running the second command is that the table reference in the metastore is updated and no data is changed. The metastore is a service that stores metadata about tables, such as their schema, location, properties, and partitions. The metastore allows users to access tables using SQL commands or Spark APIs without knowing their physical location or format. When renaming an external table using the ALTER TABLE RENAME TO command, only the table reference in the metastore is updated with the new name; no data files or directories are moved or changed in the storage system. The table will still point to the same location and use the same format as before. However, if renaming a managed table, which is a table whose metadata and data are both managed by Databricks, both the table reference in the metastore and the data files in the default warehouse directory are moved and renamed accordingly.
NEW QUESTION # 31
An organization processes customer data from web and mobile applications. Data includes names, emails, phone numbers, and location history. Data arrives both as batch files (from SFTP daily) and streaming JSON events (from Kafka in real-time).
To comply with data privacy policies, the following requirements must be met:
- Personally Identifiable Information (PII) such as email, phone
number, and IP address must be masked or anonymized before storage.
- Both batch and streaming pipelines must apply consistent PII
handling.
- Masking logic must be auditable and reproducible.
- The masked data must remain usable for downstream analytics.
How should the data engineer design a compliant data pipeline on Databricks that supports both batch and streaming modes, applies data masking to PII, and maintains traceability for audits?
Answer: C
Explanation:
Databricks recommends applying data masking or anonymization before persisting PII to ensure compliance with privacy regulations such as GDPR and HIPAA. In a Lakeflow Declarative Pipeline, developers can define custom Python or SQL-based masking functions to standardize PII handling across both batch and streaming inputs.
This approach ensures that data entering the Delta Lake is already anonymized, guaranteeing consistent and auditable behavior. By applying masking during ingestion (in the Bronze layer), audit trails are preserved through pipeline event logs.
While Unity Catalog column masks (option C) can enforce dynamic masking at query time, they do not prevent PII storage. Thus, option D aligns with the best practice of securing PII before storage, while still supporting reproducibility and analytics usability.
NEW QUESTION # 32
A data engineering team is setting up a Git project to automate integration tests using Databricks Asset Bundles and the Git provider's CI/CD functionalities. When a pull containing changes to their pipleline is sent, they need to run a Job to test their data pipeline. What is the correct databricks bundle command sequence to be executed from the Git provider's CI/CD automation for this task?
Answer: D
Explanation:
The correct sequence is to first validate the bundle to ensure the configuration is correct, then deploy it to provision or update the defined resources, and finally run the job to execute the integration tests. This aligns with CI/CD best practices by catching configuration issues early and only running tests after a successful deployment.
NEW QUESTION # 33
......
As is known to us, the Certified-Data-Engineer-Professional certification has been increasingly important for a lot of modern people in the rapid development world. Why is the Certified-Data-Engineer-Professional certification so significant for many people? Because having the certification can help people make their dreams come true, including have a better job, gain more wealth, have a higher social position and so on. Many people are difficult in getting the Certified-Data-Engineer-Professional Certification successfully. If you also have trouble in passing your exam and getting your certification, we think it is time for you to use our Certified-Data-Engineer-Professional quiz prep.
Certified-Data-Engineer-Professional Certificate Exam: https://www.actual4cert.com/Certified-Data-Engineer-Professional-real-questions.html