BONUS!!! Download part of Prep4pass AI-200 dumps for free: https://drive.google.com/open?id=1yBPjXF0FY6bokNluxpgPntEo2EflNfJc
Our Microsoft AI-200 test questions are the latest, under the premise of ensuring quality, we also offer the best price. Prep4pass provide the candidates with the most reliable training materials and the most accurate examination dumps. In addition, free demo and pdf real questions and answers will enable you to understand Prep4pass Microsoft AI-200. What's more, we provide you with study guide and exam simulations, which will help you to get more about Microsoft AI-200.
| Section | Objectives |
|---|---|
| Develop containerized solutions on Azure | - Implement containerized applications
|
| Develop AI solutions by using Azure data management services | - Work with Azure data platforms for AI workloads
|
| Connect to and consume Azure services | - Integrate Azure services
|
| Secure, monitor, troubleshoot Azure solutions | - Operate AI cloud solutions
|
Our Prep4pass's AI-200 exam training materials are mainly downloaded in PDF and software. We will regularly update, and will always provide the latest and the most accurate Microsoft AI-200 exam authentication information. With efforts for many years, the passing rate of our AI-200 Exam has reached as high as 100%. If you have any concerns, you can try our AI-200 pdf free demo and answers on probation first, and then make a decision whether to choose our AI-200 dumps or not.
NEW QUESTION # 96
Case Study 1 - Fabrikam Inc.
Background
Fabrikam Inc. is a global retail analytics company that provides AI-driven demand forecasting and product recommendation services to online retailers. The company is modernizing its solution to run entirely on Microsoft Azure.
The platform ingests transaction data, generates embeddings for semantic retrieval, performs vector similarity search, and returns product recommendations through containerized microservices. Developers use Python and Azure SDKs. Operations teams manage container orchestration, scaling, monitoring, and security.
The solution must meet strict performance, scalability, and security requirements.
Current environment
Application architecture
The Recommendation engine is a customer-facing HTTP API running as a containerized Python application. The engine is deployed to Azure Container Apps (ACA).
Embeddings are stored in Azure Database for PostgreSQL by using pgvector.
Semantic retrieval uses metadata filtering combined with vector similarity search.
Azure Managed Redis is used as a caching layer.
Front-end and API workloads are deployed to Azure Container Apps (ACA).
Batch model retraining workloads run in Azure Kubernetes Service (AKS).
Container and CI/CD
Container images are stored in Azure Container Registry (ACR).
CI/CD uses ACR Tasks to build images on commit.
ACA environments support revision management.
AKS workloads are deployed by using Kubernetes manifest files stored in Git.
Monitoring
Logs are collected in Azure Monitor.
Teams inspect container logs and Kubernetes events when troubleshooting.
Developers write KQL queries to analyze latency spikes.
Business requirements
Customer experience: Maintain a seamless, low-latency recommendation experience for end- users, even during unpredictable seasonal traffic spikes.
Operational cost efficiency: Minimize compute expenditures by deallocating resources during periods of inactivity and by preventing runaway scaling costs.
Data integrity and freshness: Ensure that product recommendations always reflect the most current catalog metadata and pricing to prevent customer dissatisfaction.
Security and compliance: Adhere to a Zero Trust security model by eliminating long-lived credentials and centralizing the management of all sensitive secrets.
Global scalability: Support the rapid ingestion of millions of new product embeddings daily without degrading query performance for existing retailers.
Technical requirements
Performance: Semantic search latency must remain under 200 milliseconds at peak load.
Database optimization: Use pgvector for embeddings and implement metadata filtering to reduce compute overhead. Configure compute and memory appropriately for vector workloads to ensure high-dimensional index residency in RAM and efficient mathematical throughput. Vector similarity calculations must be performed only against products that satisfy mandatory metadata constraints.
Database performance: Database connections must support high concurrency with minimal latency through the implementation of connection optimization.
Data load strategy: To ensure maximum ingestion throughput, secondary indexes must be applied only after bulk loading of embeddings is complete.
Caching: Redis cache entries must expire automatically after 10 minutes. Implement a reactive mechanism to invalidate cache entries upon metadata updates.
Identity: Use managed identities for all service-to-service and service-to-database authentication.
Plain-text credentials in configuration files are strictly prohibited.
Secret management: All secrets must be stored centrally. Secrets must be rotated automatically by using a centralized lifecycle policy.
Scaling: Use Kubernetes event-driven autoscaling (KEDA) for event-driven scaling. The Recommendation API must scale based on HTTP traffic, while batch jobs must scale based on queue length and support scale-to-zero.
CI/CD: All images must be stored in Azure Container Registry. Use ACR Tasks to automate image builds triggered by source code commits.
Monitoring: Use KQL to analyze performance telemetry and troubleshoot microservice connectivity failures. Inspect logs and events when troubleshooting AKS and ACA.
Drag and Drop Question
You need to configure the Redis integration for the Recommendation API.
Which configurations should you use? To answer, move the appropriate configurations to the correct requirements. You may use each configuration once, more than once, or not at all. You may need to move the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.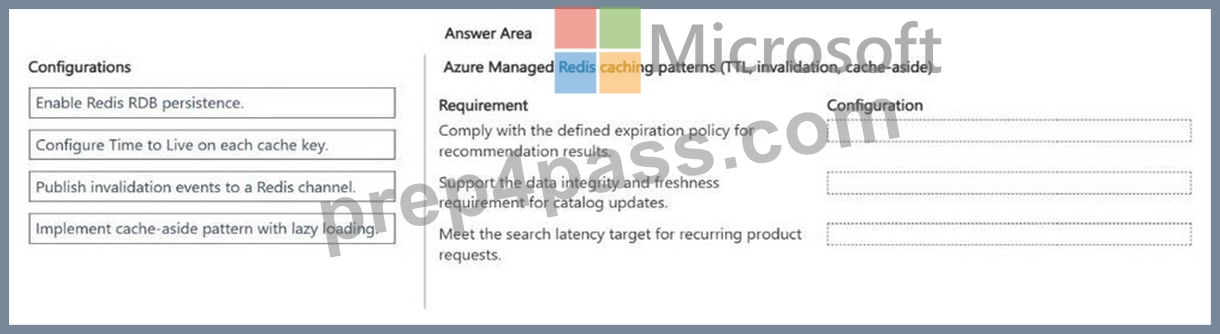
Answer:
Explanation: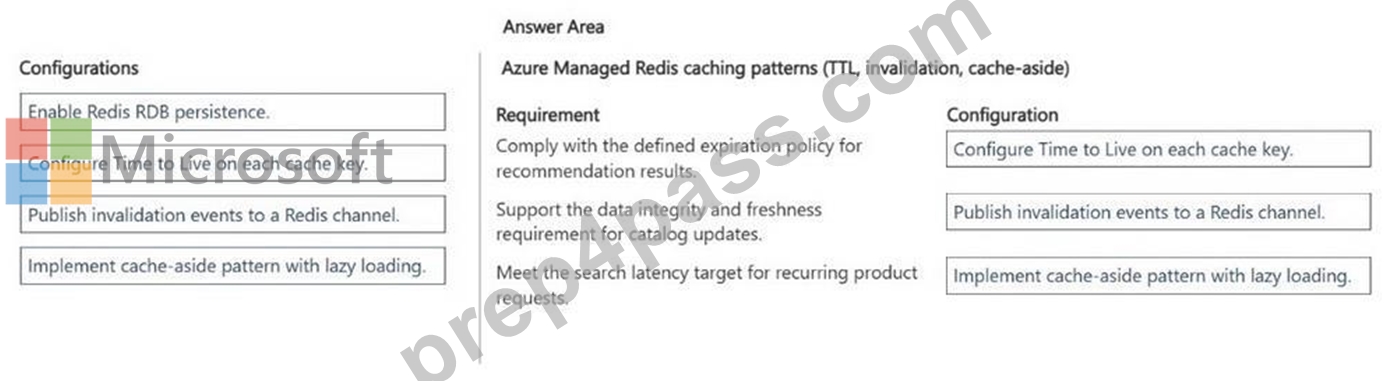
Explanation:
Scenario, Application: Azure Managed Redis is used as a caching layer.
Box 1: Configure the Time to Live (TTL) on each cache key
You must configure the Time to Live (TTL) on each cache key to meet this requirement. Azure Managed Redis (like standard Redis) does not support a global, database-wide default TTL configuration for newly created keys.
Scenario: Technical requirements: Caching: Redis cache entries must expire automatically after
10 minutes.
Box 2: Publish invalidation events to a Redis channel
Publishing invalidation events to a Redis Pub/Sub channel is a highly effective, standard architecture to invalidate cache entries across microservices or application nodes. It establishes a reactive, event-driven backplane that ensures system data integrity without requiring tight coupling between your database updates and web servers.
Scenario: Technical requirements: Implement a reactive mechanism to invalidate cache entries upon metadata updates.
Box 3: Implement the cache-aside pattern with lazy loading
To meet your search latency target for recurring product requests, you should implement the cache-aside pattern with lazy loading.
Directly reduces latency: Lazy loading ensures that frequently requested product data is kept in memory (Redis), allowing subsequent recurring requests to bypass the slower database completely.
Optimizes memory usage: Data is only loaded into the cache when actually requested, preventing your Azure Managed Redis instance from filling up with rarely accessed product data.
Reference:
https://learn.microsoft.com/en-us/azure/architecture/databases/architecture/write-through-caching-azure-sql-managed-redis
https://www.gigson.co/blog/what-is-redis-a-beginners-guide-to-in-memory-caching
NEW QUESTION # 97
You are deploying a model in Azure AI Foundry and must ensure the endpoint can handle unpredictable bursts of traffic while keeping cost low during idle periods. Which deployment type should you choose?
Answer: C
Explanation:
Standard pay-as-you-go deployments scale with token-based consumption and don't require reserving fixed throughput, making them cost-efficient for variable or bursty workloads. PTU is better suited for predictable, high-volume, latency-sensitive workloads where reserved capacity is justified.
NEW QUESTION # 98
You are developing a Java application that uses Apache Cassandra to store key and value data.
You plan to use a new Azure Cosmos DB resource and the Azure Cosmos DB for Apache Cassandra API in the application. You create a Microsoft Entra ID group named Azure Cosmos DB Creators to enable provisioning of Azure Cosmos DB accounts, databases, and containers.
The Microsoft Entra ID group must not be able to access the keys that are required to access the data.
You need to restrict access to the Microsoft Entra ID group.
Which role-based access control should you use?
Answer: D
Explanation:
The Azure Cosmos DB Operator built-in role should be used.
Provisioning Capabilities: The Azure Cosmos DB Operator role provides permissions to manage and provision Azure Cosmos accounts, databases, and containers (such as keyspaces and tables for the Apache Cassandra API).
Key Restriction: Unlike the DocumentDB Account Contributor role, it explicitly cannot access or read the account keys or connection strings. This satisfies the security requirement that the Microsoft Entra ID group must not have access to the keys required to read/write the underlying data.
Reference:
https://medium.com/azure-terraformer/terraforming-cosmos-db-access-control-arm-role-definitions-and-their-not-so-evil-twin-5de03cd92965
NEW QUESTION # 99
Drag and Drop Question
A Python API running in ACA must send distributed traces to Azure Monitor.
The API creates spans. However, no traces appear in Azure Monitor.
You need to configure the OpenTelemetry SDK pipeline to export traces to Azure Monitor.
What should you do? To answer, move the appropriate actions to the correct requirements. You may use each action once, more than once, or not at all. You may need to move the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.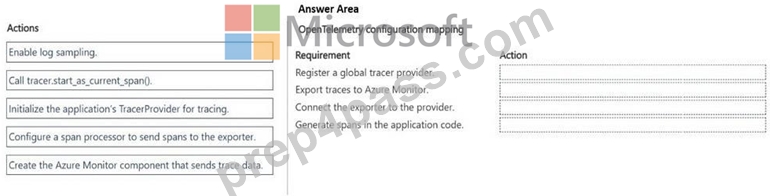
Answer:
Explanation: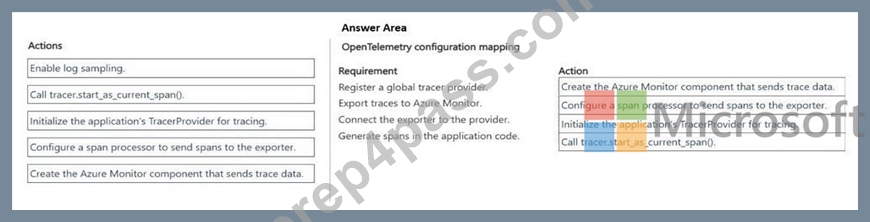
Explanation:
Box 1: Create the Azure Monitor component that sends trace data
To register a global TracerProvider in OpenTelemetry, you must call the SetTracerProvider method on the global tracer provider object, passing in your fully configured TracerProvider instance.
Box 2: Configure a span processor to send spans to the exporter
To export OpenTelemetry traces to Azure Monitor using the Python SDK, you must configure a span processor (such as BatchExportSpanProcessor), pass your initialized Azure Monitor trace exporter to it, and register that span processor with your global tracer provider.
Box 3: Initialize the application's TracerProvider for tracing
Box 4: Call tracer.start_as_current_span()
Acquire your tracer and create spans. Example code (continued from box 2 above):
tracer = trace.get_tracer(__name__)
with tracer.start_as_current_span("hello-aca-span")
Reference:
https://learn.microsoft.com/en-us/azure/durable-task/sdks/durable-task-scheduler-opentelemetry-tracing
https://learn.microsoft.com/en-us/python/api/overview/azure/monitor-opentelemetry-exporter-readme
NEW QUESTION # 100
You configure ACR Tasks to automate image builds.
Container images must rebuild when:
- Application updates occur.
- Base image updates occur, such as when the underlying OS image is
updated.
- Regular scheduled rebuilds are required.
You need to configure ACR Tasks to support automated image rebuilds.
Which three triggers should you configure? Each correct answer presents part of the solution.
NOTE: Each correct selection is worth one point.
Answer: B,C,E
Explanation:
To support automated container image rebuilds based on your requirements, you need to configure source triggers, base image triggers, and timer triggers in Azure Container Registry (ACR) Tasks.
Timer Triggers: Automates regular scheduled rebuilds. This uses a cron schedule expression to run image builds at specific intervals (e.g., weekly or monthly) regardless of code changes.
Source Triggers: Automates rebuilds when application updates occur. This monitors changes in your source code repository (like GitHub or Azure Repos) and fires a build when code is committed.
Base Image Triggers: Automates rebuilds when the underlying OS or framework image updates.
ACR tracks dependencies and automatically kicks off a new build when your defined FROM image changes in the public registry or your private registry.
Reference:
https://oneuptime.com/blog/post/2026-02-16-how-to-set-up-acr-tasks-for-automated-container-image-builds-on-git-commit/view
NEW QUESTION # 101
......
Success in the AI-200 certification exam is essential to advance your career. The Developing AI Cloud Solutions on Azure (AI-200) certification can set you apart from the competition and give you the edge you need to grow in your career. However, preparing for the AI-200 test can be challenging, mainly if you have limited time. Here's where Prep4pass comes in with actual AI-200 Questions. We at Prep4pass are well aware of the importance of the Microsoft AI-200 certification in order to stand out in today's competitive job environment.
Real AI-200 Exam Answers: https://www.prep4pass.com/AI-200_exam-braindumps.html
DOWNLOAD the newest Prep4pass AI-200 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1yBPjXF0FY6bokNluxpgPntEo2EflNfJc