2026 Latest PassLeaderVCE DP-750 PDF Dumps and DP-750 Exam Engine Free Share: https://drive.google.com/open?id=1buPrAkjwdxwzxYvzcbwmU4YdxKBIb2ex
DP-750 practice dumps offers you more than 99% pass guarantee, which means that if you study our DP-750 learning guide by heart and take our suggestion into consideration, you will absolutely get the certificate and achieve your goal. Meanwhile, if you want to keep studying this course , you can still enjoy the well-rounded services by DP-750 Test Prep, our after-sale services can update your existing DP-750 study quiz within a year and a discount more than one year.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Deploy and maintain data pipelines and workloads | 30–35% | - Monitor, troubleshoot, and maintain workloads
|
| Topic 2: Secure and govern Unity Catalog objects | 15–20% | - Manage data sharing and permissions
|
| Topic 3: Prepare and process data | 30–35% | - Ingest and transform data
|
| Topic 4: Set up and configure an Azure Databricks environment | 15–20% | - Select and configure compute resources
|
The "PassLeaderVCE" is one of the top-rated and reliable platforms that offer real, valid, and updated Implementing Data Engineering Solutions Using Azure Databricks (DP-750) exam questions in three different formats. The names of these formats are PassLeaderVCE DP-750 PDF dumps file, desktop practice test software, and web-based practice test software. All these three PassLeaderVCE DP-750 Exam Questions formats are easy to use and perfectly work with desktop computers, laptops, tabs, or even on your smartphone devices.
NEW QUESTION # 88
You have an Azure Databricks workspace that contains a Git folder and uses Azure Repos as the Git provider.
From the main branch, you create a branch named Branch1. You commit changes to Branch1.
You need to incorporate the changes from Branch1 into main The solution must preserve the commit history in the repository. Which command should you run?
Answer: A
Explanation:
The correct answer is A - merge.
A Git merge combines the histories of two branches by creating a merge commit that joins them. Every individual commit from Branch1 remains visible in the repository log - the full development history is preserved. This is the requirement: 'the solution must preserve the commit history in the repository.' Option C (rebase) moves Branch1's commits on top of main by replaying them as new commits with new hashes. The end result looks like a linear history, but the original commit hashes are rewritten - the prior history is not preserved in its original form. For a shared repository, rebase rewrites public history, which is considered problematic.
Option B (pull) fetches remote changes and merges or rebases them into the current branch - it's used to sync with a remote, not to incorporate a feature branch. Option D (push) sends local commits to the remote but doesn't incorporate any branch into another.
Reference: https://learn.microsoft.com/en-us/azure/databricks/repos/git-operations-with-repos
NEW QUESTION # 89
Hotspot Question
You have an Azure Databricks workspace that contains a job in Lakeflow Jobs named Job1.
Job1 runs every hour.
Occasionally, the job run takes longer than one hour to complete. Overlapping runs must be prevented to avoid data corruption.
You need to configure the job scheduling behavior.
What should you configure? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.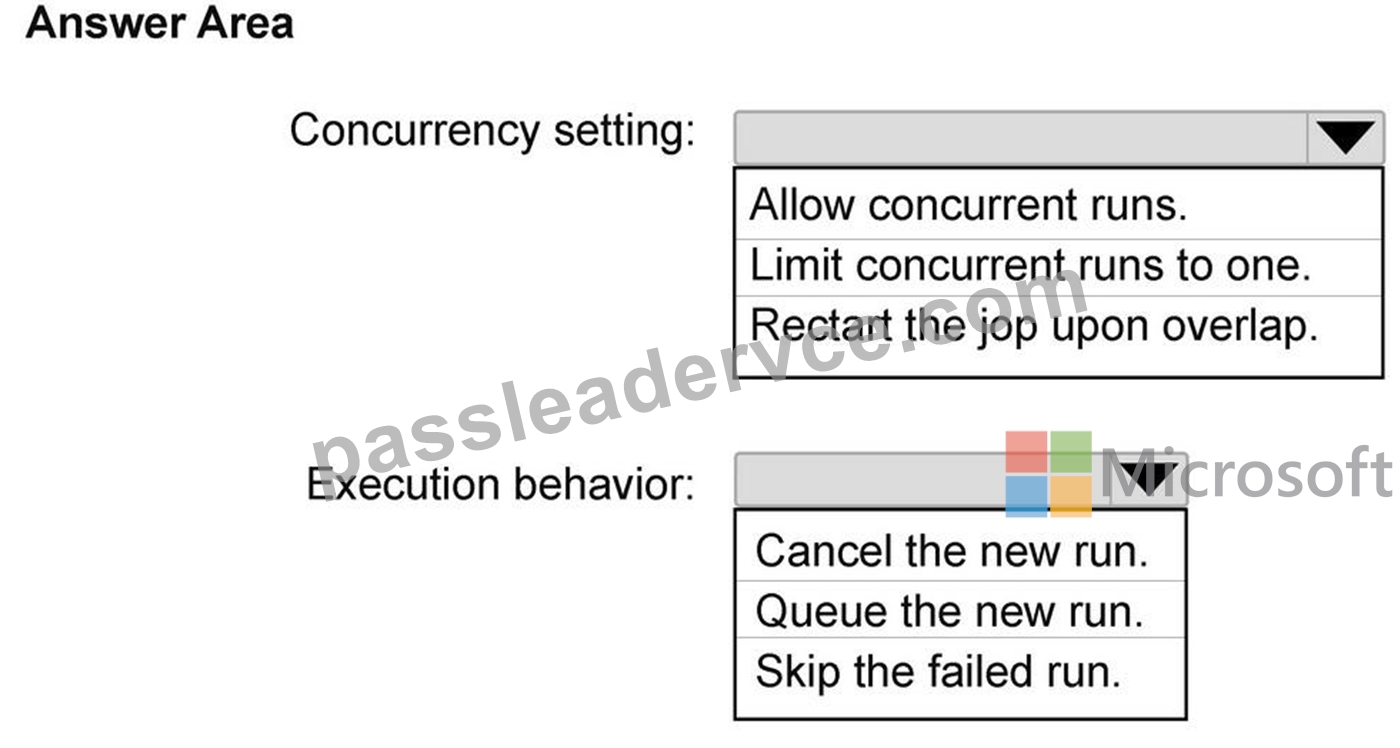
Answer:
Explanation: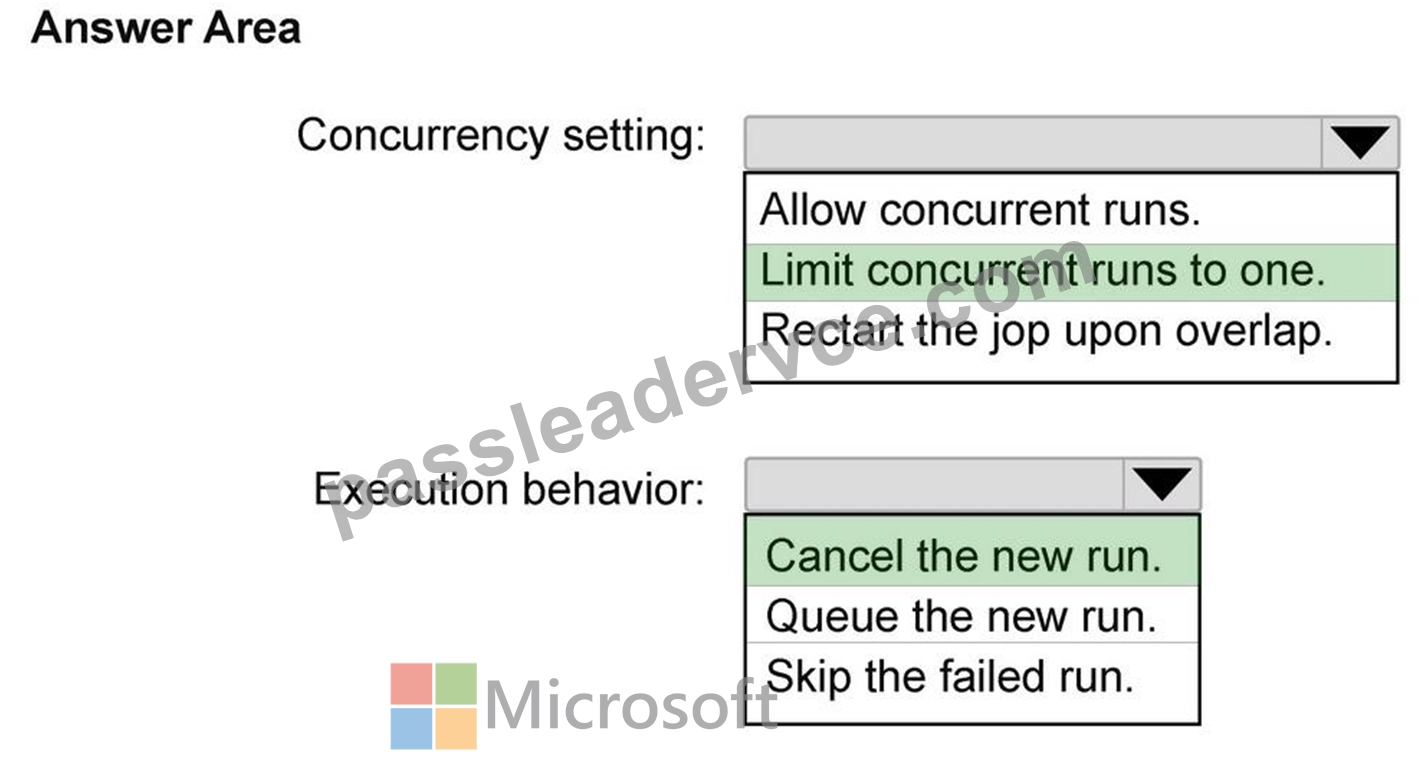
NEW QUESTION # 90
You have an Azure Databricks workspace named Workspace1 that contains a lakehouse and is enabled for Unity Catalog.
You have a connection to a Microsoft SQL Server database named DB1.
You need to expose the schemas and tables of DB1 to meet the following requirements:
* The schemas and tables can be queried in Databricks.
* The schemas and tables appear alongside other Unity Catalog objects.
* The data is NOT copied into Databricks-managed storage.
Solution: You create a Databricks access connector.
Does this meet the goal?
Answer: A
Explanation:
The correct answer is B - No.
A Databricks Access Connector is an Azure resource that provides a managed identity for Databricks to authenticate to Azure Storage services. It is an authentication bridge - nothing more. Creating one doesn't register any external database, doesn't create any Unity Catalog objects representing DB1, and doesn't enable querying of SQL Server data from Databricks.
An Access Connector is a prerequisite for setting up storage credentials and external locations in Unity Catalog (to access ADLS Gen2, for example), but it has no role in Lakehouse Federation or foreign catalog creation. It cannot expose an external database's schemas and tables in Unity Catalog alongside native objects.
The correct solution for this scenario is a foreign catalog (Q47), which requires a connection object pointing to DB1 - not an Access Connector.
Reference: https://learn.microsoft.com/en-us/azure/databricks/connect/unity-catalog/storage-credentials
NEW QUESTION # 91
You have an Azure Databricks workspace that is enabled for Unity Catalog.
You have a complex job named Job1 that contains eight tasks. Job1 takes multiple hours to complete.
During the last job run, the final task fails due to a transient issue.
You need to retry the last task without rerunning tasks that have already completed.
What should you do?
Answer: C
Explanation:
You can retry only the failed final task by using the Repair Run feature in Azure Databricks. This allows you to rerun failed or skipped tasks without restarting the successful ones, preserving your Unity Catalog data lineage and saving hours of compute time.
Reference:
https://www.databricks.com/blog/2022/05/06/save-time-and-money-on-data-and-ml-workflows- with-repair-and-rerun.html
NEW QUESTION # 92
You have an Azure Databricks workspace.
Users report that a Databricks notebook that runs each day takes longer than expected to run.
When reading the Directed Acyclic Graph (DAG), you discover the following issues concerning the Apache Spark stage:
* Most tasks in the stage finish quickly.
* A few tasks in the stage run more slowly.
* The CPU is underutilized at the end of the stage.
* The slow tasks process many more input records.
* The stage is blocked while it waits for the few slow tasks.
What is the root cause of the issues?
Answer: A
NEW QUESTION # 93
......
The desktop practice test format comes with all features of the web-based practice exam. PassLeaderVCE has made all of the different formats so the exam applicants won't face any additional issues and prepare themselves with the real questions and crack Microsoft DP-750 Certification test for the betterment of their futures. One can set the time and questions numbers of practice exams (desktop and web-based) according to their needs. PassLeaderVCE is giving multiple mock exams to the customers so they can practice and make themselves perfect.
DP-750 Reliable Test Tutorial: https://www.passleadervce.com/Microsoft-Certified-Fabric-Data-Engineer-Associate/reliable-DP-750-exam-learning-guide.html
What's more, part of that PassLeaderVCE DP-750 dumps now are free: https://drive.google.com/open?id=1buPrAkjwdxwzxYvzcbwmU4YdxKBIb2ex