IT업계에 종사하시는 분은 국제공인 IT인증자격증 취득이 얼마나 힘든지 알고 계실것입니다. 특히 시험이 영어로 되어있어 부담을 느끼시는 분도 계시는데 ExamPassdump를 알게 된 이상 이런 고민은 버리셔도 됩니다. ExamPassdump의CMA Category-Manager덤프는 모두 영어버전으로 되어있어CMA Category-Manager시험의 가장 최근 기출문제를 분석하여 정답까지 작성해두었기에 문제와 답만 외우시면 시험합격가능합니다.
| Section | Weight | Objectives |
|---|---|---|
| Tactical Planning & Execution | 25% | - Space Management & Store Clustering - Pricing Strategy & Analysis - Efficient Assortment Development - Promotional Strategy & Evaluation |
| Data Competency & Analysis | 25% | - Shopper Data & Geo-demographic Analysis - Panel Data & Advanced Analytics - POS Data Analytics |
| Category Assessment & Strategy | 25% | - Root Cause Analysis & Insight Generation - Category Health Measurement - Category Definition, Segmentation & Role |
| Business & Supply Chain Knowledge | 15% | - Retailer Economics & Profitability - Supply Chain Principles |
| Professional Standards & Communication | 10% | - Ethics & Legal Implications - Fact-Based Storytelling & Presentation |
ExamPassdump를 선택함으로 여러분은 CMA 인증Category-Manager시험에 대한 부담은 사라질 것입니다.우리 ExamPassdump는 끊임없는 업데이트로 항상 최신버전의 CMA 인증Category-Manager시험덤프임을 보장해드립니다.만약 덤프품질을 확인하고 싶다면ExamPassdump 에서 무료로 제공되는CMA 인증Category-Manager덤프의 일부분 문제를 체험하시면 됩니다.ExamPassdump 는 100%의 보장도를 자랑하며CMA 인증Category-Manager시험을 한번에 패스하도록 도와드립니다.
질문 # 33
Which of the following is the first step in the multivariate clustering process?
정답:D
설명:
The correct answer is A .
The multivariate store clustering process starts by identifying the Product Demographic Affinity Profile , because the analyst first needs to understand which demographic groups have the strongest relationship or affinity with the product/category being studied. ARC's category-specific store clustering guidance identifies
"Identify the Product Demographic Affinity Profile (PDAP)" as a core step and then moves into calculating product demand potential.
This sequence matters. You cannot calculate demand potential correctly until you understand the demographic profile that is most relevant to the product or category. Once the product's demographic affinity is known, the analyst can compare that profile to store-level demographic profiles and then create meaningful clusters based on demand and opportunity.
Option B is later in the process because clusters are created after the relevant product and store-level measures are understood. Option C is important, but it follows the product affinity logic. Option D also comes after identifying the demographic affinity profile.
질문 # 34
How many units do we need to sell at $16 to Break-Even on Gross Profit?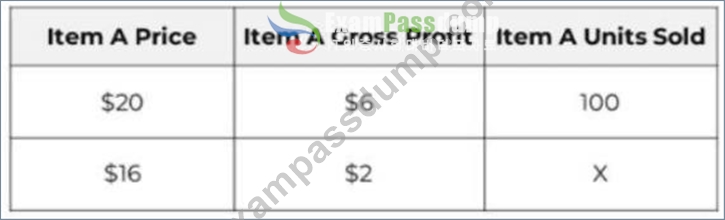
정답:A
설명:
The correct answer is A .
The original gross profit dollars are calculated from the current gross profit per unit multiplied by units sold:
$6 gross profit × 100 units = $600 total gross profit
At the lower $16 price, the gross profit per unit drops to $2 . To break even on total gross profit, the item must still generate $600 in gross profit dollars.
Calculation:
$600 ÷ $2 gross profit per unit = 300 units
So the item must sell 300 units at the $16 price to break even on gross profit.
This aligns with CPCM pricing analytics because CMKG identifies breakeven analysis as a pricing measure and explains that break-even is where total costs and total sales meet. CMKG also states that pricing analytics must be understood for both calculation and strategic implication.
Option B is wrong because selling 100 units at $2 gross profit only generates $200, which is far below the original $600. Option C gives $250 gross profit, still too low. Option D would generate $1,200 gross profit, which exceeds break-even.
질문 # 35
What are the primary data sources for shopper insights?
정답:C
설명:
The correct answer is B because shopper insights in category management are developed from multiple shopper and sales-data sources, not from loyalty data alone. The CPCM/CMKG material describes the intermediate CPCM program as focused on "in-depth data and analytics across key data sources and category tactics," and its curriculum includes both Panel Data and POS Data as formal data competency areas.
The supporting extract states that standard category management data includes "retail POS, retail measurement data, consumer panel data and 'other' data," and that learners must understand the best data sources for different business issues and key questions.
So the complete set in the answer choices is Retailer Loyalty Data, Syndicated Panel Data, and Syndicated POS Data . Loyalty data helps identify known shopper/household purchasing behavior. Panel data gives a broader consumer/household behavior view. Syndicated POS data provides scanned sales and market-level performance context.
Option A is wrong because it repeats Retailer Loyalty Data and is poorly constructed. Option C is too narrow because it excludes Syndicated POS Data. Option D is incomplete because retailer loyalty data alone cannot provide a full shopper insight picture.
질문 # 36
Why is it important for Category Managers to align promotional planning with supply chain capabilities?
정답:A
설명:
The correct answer is C .
Promotions create demand spikes. If the supply chain is not prepared, the promotion can fail because stores run out of product, shoppers cannot buy, and the retailer loses sales. The CPCM course treats promotion as a driver of incremental sales, while CMKG's supply-chain material emphasizes that supply chain affects inventory, forecasting, availability, service levels, and the shopper experience.
That is why category managers must align promotional planning with supply-chain capability. The promotional plan must be supported by forecasted demand, inventory, replenishment, supplier readiness, store execution, and lead times.
Option A is wrong because promotions usually require more collaboration, not less. Option B may happen in some promotions, but variety is not the main reason for supply-chain alignment. Option D is dangerous because ignoring supply-chain constraints creates out-of-stocks and failed promotions. The correct answer is C
protect availability during high-demand periods and minimize stockouts.
질문 # 37
Which phase of analytics uses past data and models to estimate what's likely to happen next?
정답:B
설명:
The correct answer is A .
Predictive analytics is the analytics phase that uses historical data and models to estimate future outcomes.
The CPCM course explicitly includes predictive analytics as part of advanced category analytics, including regression models, clustering algorithms, collaborative filtering, and time-to-event models. IBM defines predictive analytics as a branch of advanced analytics that makes predictions about future outcomes using historical data, statistical modeling, data mining, and machine learning.
Option C, descriptive analytics, explains what happened in the past. Option D, prescriptive analytics, recommends what action should be taken. Option B, generative, refers to creating new content or outputs and is not the correct analytics phase here. The phrase "what's likely to happen next" is the giveaway: that is predictive analytics.
질문 # 38
......
많은 시간과 정신력을 투자하고 모험으로CMA인증Category-Manager시험에 도전하시겠습니까? 아니면 우리ExamPassdump 의 도움으로 시간을 절약하시겠습니까? 요즘 같은 시간인 즉 모든 것인 시대에 여러분은 당연히 ExamPassdump의 제품이 딱 이라고 생각합니다. 그리고 우리 또한 그 많은 덤프판매사이트 중에서도 단연 일등이고 생각합니다. 우리 ExamPassdump선택함으로 여러분은 성공을 선택한 것입니다.
Category-Manager최신버전 덤프공부문제: https://www.exampassdump.com/Category-Manager_valid-braindumps.html