P.S. Free & New Mule-Arch-201 dumps are available on Google Drive shared by PassLeaderVCE: https://drive.google.com/open?id=14BXkLu9YdRHQmkq80BwKOPCFp3eD9J7m
We try to meet different requirements by setting different versions of our Mule-Arch-201 question dumps. The first one is online Mule-Arch-201 engine version. As an online tool, it is convenient and easy to study, supports all Web Browsers and system including Windows, Mac, Android, iOS and so on. You can practice online anytime and check your test history and performance review, which will do help to your study. The second is Mule-Arch-201 Desktop Test Engine. As an installable Mule-Arch-201 software application, it simulated the real Mule-Arch-201 exam environment, and builds 200-125 exam confidence. The third one is Practice PDF version. PDF Version is easy to read and print. So you can study anywhere, anytime.
| Section | Objectives |
|---|---|
| API Management and Governance | - API lifecycle management - Governance frameworks and best practices - API security policies and enforcement |
| Anypoint Platform Architecture | - Anypoint Platform components and capabilities - Deployment models (CloudHub, hybrid, on-premises) - Runtime Fabric architecture overview |
| Data Integration and Transformation | - Data mapping and transformation strategies - Batch vs real-time integration patterns |
| Security and Compliance | - Secure API exposure and threat protection - Authentication and authorization mechanisms |
| Integration Architecture Strategy | - API-led connectivity principles - System, process, and experience APIs - Designing enterprise integration architecture |
| Performance and Scalability | - Scaling Mule applications - High availability design patterns |
>> Mule-Arch-201 Reliable Exam Preparation <<
Mule-Arch-201 guide torrent is authoritative. Over the years, our study materials have helped tens of thousands of candidates successfully pass the exam. Mule-Arch-201 certification training is prepared by industry experts based on years of research on the syllabus. These experts are certificate holders who have already passed the certification. They have a keen sense of smell for the test. Therefore, Mule-Arch-201 certification training is the closest material to the real exam questions. With our study materials, you don't have to worry about learning materials that don't match the exam content. With Mule-Arch-201 Study Guide, you only need to spend 20 to 30 hours practicing to take the exam. In addition, Mule-Arch-201 certification training has a dedicated expert who updates all data content on a daily basis and sends the updated content to the customer at the first time. Therefore, using Mule-Arch-201 guide torrent, you don't need to worry about missing any exam focus.
NEW QUESTION # 50
Version 3.0.1 of a REST API implementation represents time values in PST time using ISO 8601 hh:mm:ss format. The API implementation needs to be changed to instead represent time values in CEST time using ISO 8601 hh:mm:ss format. When following the semver.org semantic versioning specification, what version should be assigned to the updated API implementation?
Answer: B
Explanation:
Correct Answe r: 4.0.0
*****************************************
As per semver.org semantic versioning specification:
Given a version number MAJOR.MINOR.PATCH, increment the:
- MAJOR version when you make incompatible API changes.
- MINOR version when you add functionality in a backwards compatible manner.
- PATCH version when you make backwards compatible bug fixes.
As per the scenario given in the question, the API implementation is completely changing its behavior. Although the format of the time is still being maintained as hh:mm:ss and there is no change in schema w.r.t format, the API will start functioning different after this change as the times are going to come completely different.
Example: Before the change, say, time is going as 09:00:00 representing the PST. Now on, after the change, the same time will go as 18:00:00 as Central European Summer Time is 9 hours ahead of Pacific Time.
>> This may lead to some uncertain behavior on API clients depending on how they are handling the times in the API response. All the API clients need to be informed that the API functionality is going to change and will return in CEST format. So, this considered as a MAJOR change and the version of API for this new change would be 4.0.0
NEW QUESTION # 51
4A developer for a transportation organization is implementing exactly one processing functionality in a Reservation Mule application to process and store passenger records. This Reservation application will be deployed to multiple CloudHub workers/replicas. It is possible that several external systems could send duplicate passenger records to the Reservation application.
An appropriate storage mechanism must be selected to help the Reservation application process each passenger record exactly once as much as possible. The selected storage mechanism must be shared by all the CloudHub workers/replicas in order to synchronize the state information to assist attempting exactly once processing of each passenger record by the deployed Reservation Mule application.
Which type of simple storage mechanism in Anypoint Platform allows the Reservation Mule application to update and share data between the CloudHub workers/replicas exactly once, with minimal development effort?
Answer: B
Explanation:
Processing Requirements and Storage Mechanism:
The Reservation Mule application will be deployed to multiple CloudHub workers/replicas, meaning that each worker must share state information to handle records exactly once. This requires a shared storage mechanism where state can be stored and accessed by multiple instances to avoid duplicate processing of the same records.
A Persistent Object Store in Anypoint Platform can be used to store records in a way that is accessible across multiple workers, providing a reliable mechanism for "exactly once" processing.
Evaluating the Options:
Option A (Correct Answer): A Persistent Object Store is designed to retain data across different application instances and can be shared by all workers on CloudHub. It helps achieve idempotency by ensuring that a record is processed exactly once.
Option B: Runtime Fabric Object Store is used for applications deployed in Anypoint Runtime Fabric, not CloudHub. This option would not be compatible with the CloudHub deployment.
Option C: A Non-persistent Object Store does not retain data across application restarts or different instances, making it unsuitable for the requirement of synchronized storage for exactly-once processing.
Option D: An In-memory Mule Object Store is local to each worker and is not shared across instances, so it does not meet the requirement for a shared storage mechanism accessible to all CloudHub workers.
Conclusion:
Option A is the correct answer, as a Persistent Object Store allows data sharing across multiple CloudHub workers, enabling them to synchronize and achieve "exactly once" processing of passenger records with minimal development effort.
Refer to MuleSoft's documentation on Object Store configurations and usage for best practices on handling state across distributed instances.
NEW QUESTION # 52
An API implementation is deployed on a single worker on CloudHub and invoked by external API clients (outside of CloudHub). How can an alert be set up that is guaranteed to trigger AS SOON AS that API implementation stops responding to API invocations?
Answer: A
Explanation:
Correct Answe r: Configure a "Worker not responding" alert in Anypoint Runtime Manager.
*****************************************
>> All the options eventually helps to generate the alert required when the application stops responding.
>> However, handling exceptions within calling API and then raising alert from API client is inappropriate and silly. There could be many API clients invoking the API implementation and it is not ideal to have this setup consistently in all of them. Not a realistic way to do.
>> Implementing a health check/ heartbeat with in the API and calling from outside to detmine the health sounds OK but needs extra setup for it and same time there are very good chances of generating false alarms when there are any intermittent network issues between external tool calling the health check API on API implementation. The API implementation itself may not have any issues but due to some other factors some false alarms may go out.
>> Creating an alert in API Manager when the API receives no requests within a specified time period would actually generate realistic alerts but even here some false alarms may go out when there are genuinely no requests from API clients.
The best and right way to achieve this requirement is to setup an alert on Runtime Manager with a condition "Worker not responding". This would generate an alert AS SOON AS the workers become unresponsive.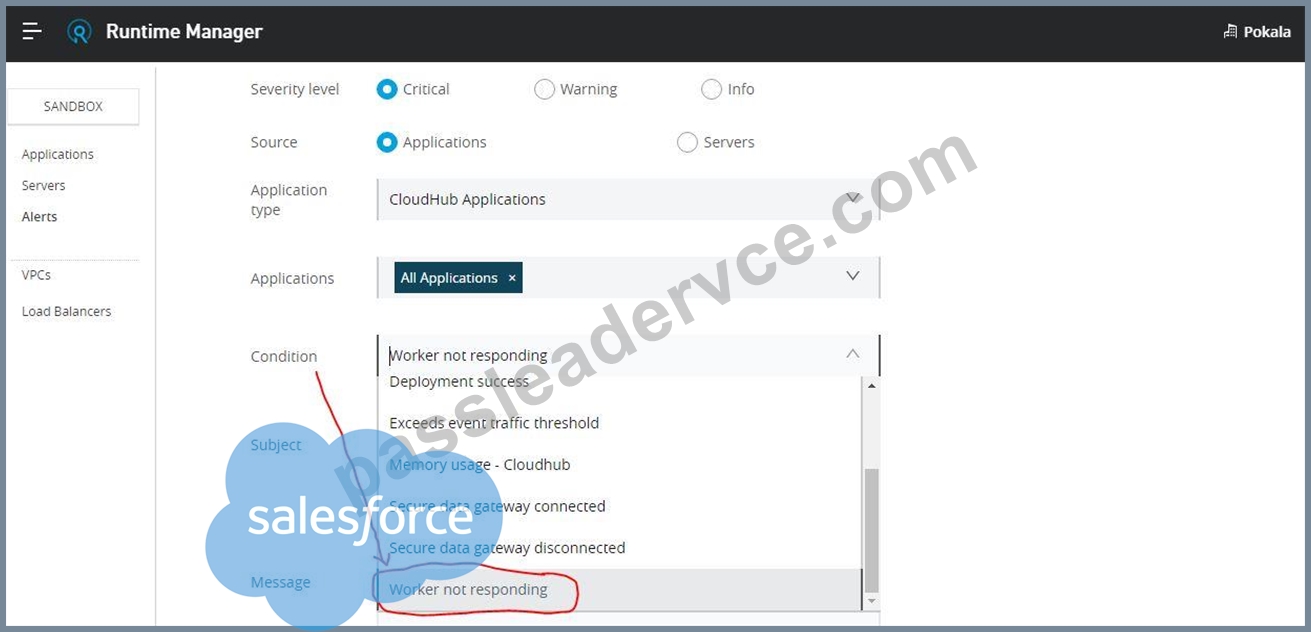
Bottom of Form
Top of Form
NEW QUESTION # 53
A business process is being implemented within an organization's application network. The architecture group proposes using a more coarse-grained application network design with relatively fewer APIs deployed to the application network compared to a more fine-grained design.
Overall, which factor typically increases with a more coarse-grained design for this business process implementation and deployment compared with using a more fine-grained design?
Answer: C
Explanation:
Understanding Coarse-Grained vs. Fine-Grained API Design:
A coarse-grained design consolidates multiple operations within a single API, leading to fewer APIs but with more complex implementations. Conversely, a fine-grained design breaks down functionalities into smaller, more specific APIs, resulting in simpler implementations but a larger number of APIs.
Evaluating the Options:
Option A (Correct Answer): With a coarse-grained design, each API handles more functionalities, increasing the complexity of each API implementation as it needs to manage more use cases and logic.
Option B: A coarse-grained design typically reduces the number of APIs, so fewer discoverable assets are available.
Option C: Fewer APIs generally mean fewer connections between them in the application network.
Option D: Network infrastructure usage may actually decrease with fewer APIs, as there are fewer calls between APIs.
Conclusion:
Option A is the correct answer, as the complexity of each API implementation increases in a coarse-grained design due to the consolidation of multiple functionalities into single APIs.
Refer to MuleSoft's documentation on API design principles and best practices for coarse-grained vs. fine-grained API implementation.
NEW QUESTION # 54
Which APIs can be used with DataGraph to create a unified schema?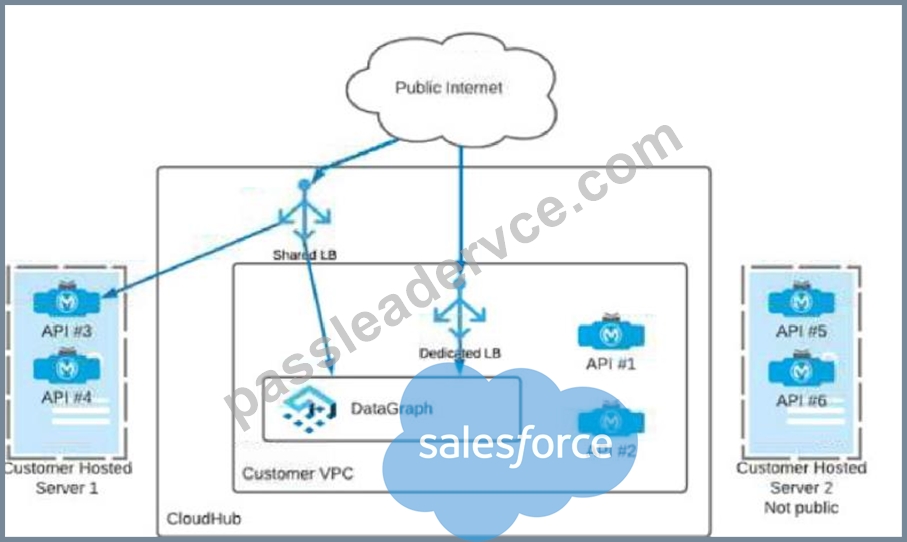
Answer: B
Explanation:
To create a unified schema in MuleSoft's DataGraph, APIs must be exposed in a way that allows DataGraph to pull and consolidate data from these APIs into a single schema accessible to consumers. DataGraph provides a federated approach, combining multiple APIs to form a single, unified API endpoint.
In this setup:
APIs 1, 2, 3, and 4 are suitable candidates for DataGraph because they are hosted within the Customer VPC on CloudHub and are accessible either through a Shared Load Balancer (LB) or a Dedicated Load Balancer (DLB). Both of these load balancers provide public access, which is a necessary condition for DataGraph as it must access the APIs to aggregate data.
APIs 5 and 6 are hosted on Customer Hosted Server 2, which is explicitly marked as "Not public". Since DataGraph requires API access through a publicly reachable endpoint to aggregate them into a unified schema, APIs 5 and 6 cannot be used with DataGraph in this configuration.
APIs 3 and 4 on Customer Hosted Server 1 appear accessible through a Shared LB, implying public accessibility that meets DataGraph's requirements.
By combining APIs 1, 2, 3, and 4 within DataGraph, you can create a unified schema that enables clients to query data seamlessly from all these APIs as if it were from a single source.
This setup allows for efficient data retrieval and can simplify API consumption by reducing the need to call multiple APIs individually, thus optimizing performance and developer experience.
Reference
For more detailed information on setting up and managing unified schemas in DataGraph, refer to the DataWeave documentation and MuleSoft DataGraph resources which provide in-depth guidelines on schema aggregation and API federation.
NEW QUESTION # 55
......
Several advantages we now offer for your reference. On the one hand, our Mule-Arch-201 learning questions engage our working staff in understanding customers’ diverse and evolving expectations and incorporate that understanding into our strategies, thus you can 100% trust our Mule-Arch-201 Exam Engine. On the other hand, the professional Mule-Arch-201 study materials determine the high pass rate. According to the research statistics, we can confidently tell that 99% candidates have passed the Mule-Arch-201 exam.
Mule-Arch-201 Book Free: https://www.passleadervce.com/Salesforce-MuleSoft/reliable-Mule-Arch-201-exam-learning-guide.html
2026 Latest PassLeaderVCE Mule-Arch-201 PDF Dumps and Mule-Arch-201 Exam Engine Free Share: https://drive.google.com/open?id=14BXkLu9YdRHQmkq80BwKOPCFp3eD9J7m