BONUS!!! Download part of Dumps4PDF NCP-BC-7.5 dumps for free: https://drive.google.com/open?id=1r-VZzrhomkrA8Z9F8kdqnLr7kdmsXJXk
Dumps4PDF NCP-BC-7.5 exam braindumps are authorized legal products which is famous for its high passing rate. Our dumps can cover nearly 95% questions of the real test, our answers and explanations are edited by many experienced experts and the correct rate is 100%. Our Nutanix NCP-BC-7.5 Exam Braindumps provide three versions to satisfy different kinds of customers' habits: PDF version, Soft test engine and APP test engine.
| Section | Objectives |
|---|---|
| Nutanix Disaster Recovery Architecture | - Nutanix Leap Overview - Replication Types (Sync/Async) - Protection Domains |
| Data Protection and Backup Integration | - Backup Solutions Integration - Snapshot Management |
| Recovery Operations | - Test Recovery Workflows - Recovery Plans and Orchestration - Failover and Failback Procedures |
| Prism Central Management | - DR Monitoring and Operations - Cluster and Site Management |
| Disaster Recovery Fundamentals | - Business Continuity Principles - DR Concepts (RPO, RTO, SLAs) |
>> NCP-BC-7.5 Latest Test Dumps <<
We can offer further help related with our NCP-BC-7.5 study engine which win us high admiration. By devoting in this area so many years, we are omnipotent to solve the problems about the NCP-BC-7.5 practice questions with stalwart confidence. Providing services 24/7 with patient and enthusiastic staff, they are willing to make your process more convenient. So, if I can be of any help to you in the future, please feel free to contact us at any time on our NCP-BC-7.5 Exam Braindumps.
NEW QUESTION # 14
An administrator recently expanded a Nutanix cluster by adding several new nodes. Shortly after, multiple backup jobs began failing. The following error is consistently reported: " Failed to perform backup: Cannot complete process ' iscsiadm --mode discovery --type sendtargets --portal X.X.X.X ' within timeout " . What is the most likely cause of the failure?
Answer: C
Explanation:
Nutanix storage is often accessed by external backup solutions (like Veeam, Commvault, or HYCU) using the iSCSI protocol. This allows the backup server to mount snapshots and read data directly from the storage tier.
The error message " iscsiadm... discovery... timeout " specifically indicates that the backup server ' s iSCSI initiator is unable to communicate with the Nutanix Data Services IP or the Controller VMs (CVMs) over the network.
When a Nutanix cluster is expanded, it is essential that all networking and firewall configurations applied to the existing nodes are also applied to the new nodes. The iSCSI protocol relies on specific TCP ports: port
3260 is the standard port for iSCSI traffic, and port 3205 is often used for iSCSI discovery and metadata operations within Nutanix. If these ports are not open in the physical firewall or the host-based security rules for the newly added nodes, the backup server will be unable to discover the targets on those specific nodes, leading to the timeout errors . This highlights a common " Day 2 " operational trap: cluster expansion requires careful auditing of network security groups and firewall whitelists to ensure that external integrations- especially BCDR and backup services-continue to have uninterrupted access to the expanded storage fabric.
Verifying and opening ports 3205 and 3260 for the new node IPs is the first step to resolving this timeout issue.
NEW QUESTION # 15
A VM is protected in an Async Protection Policy and added to a Recovery Plan. An administrator is attempting to perform a planned failover of the VM. How many recovery points are created and replicated during the planned failover process?
Answer: C
Explanation:
A Planned Failover in Nutanix Disaster Recovery is an orchestrated workflow designed to migrate workloads with zero data loss. However, the behavior of recovery point creation depends on the current state of synchronization and the type of replication policy. For standard Asynchronous (Async) Protection Policies, the system typically relies on the established schedule to maintain recovery point consistency. In many automated workflows, especially during a test or a specific " planned " trigger, the administrator might assume a new snapshot is generated; however, if the system is designed to use the most recent " consistent " state, it may rely on the last successfully replicated recovery point to initiate the restore.
Technically, if a new point were to be created, it would require the VM to be shut down at the source to ensure application consistency-a process that is part of the planned failover sequence. If the policy is configured to use existing data for speed, it bypasses new creation to minimize the maintenance window. This emphasizes the importance of verifying that replication is " In-Sync " or " Healthy " before starting a planned failover. If the last recovery point is several hours old, the " planned " move could result in a significant rollback unless the administrator manually triggers a synchronization task prior to the failover event.
Understanding this behavior ensures that BCDR administrators can accurately predict data states following a controlled migration between sites.
NEW QUESTION # 16
Which ports must remain open to support replication between two Prism Element clusters?
Answer: B
Explanation:
Replication between Nutanix clusters involves the transfer of both actual data blocks and the metadata required to manage the consistency and scheduling of those snapshots. Two specific services running on the Controller VMs (CVMs) are responsible for these tasks: Stargate and Cerebro.
Port TCP 2009 is used by the Stargate service. Stargate is the primary I/O manager for the Nutanix cluster, and in a BCDR context, it handles the " Snapshot-on-wire " data transfer. This is the port where the actual bits of the virtual disks are sent from the source cluster to the destination cluster. Port TCP 2020 is used by the Cerebro service. Cerebro is the replication engine that handles protection domain orchestration, snapshot scheduling, and cross-site handshake operations. Without port 2020, the clusters cannot synchronize their schedules or confirm that a recovery point has been successfully stored at the remote site. While other ports like 9440 (Prism management) and 22 (SSH) are used for administrative tasks, ports 2009 and 2020 are the mandatory " data path " and " control path " ports required for the continuous and successful replication of workloads between availability zones.
NEW QUESTION # 17
Exhibit: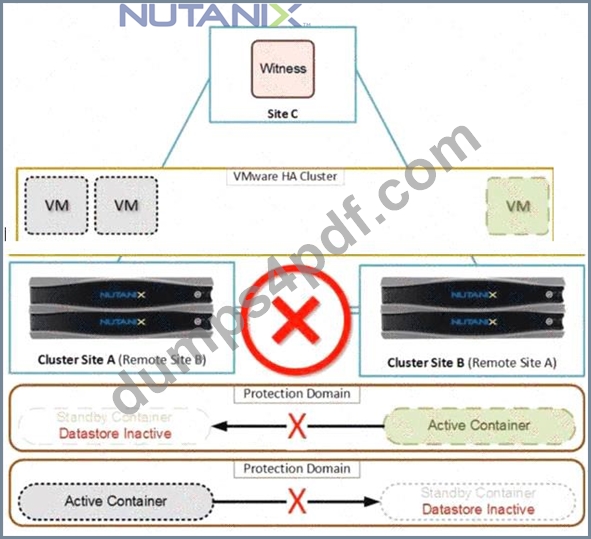
An administrator wants to protect the snapshots created on the cluster. Only authorized users should be allowed to modify or delete the snapshots on the cluster. How can the administrator harden the security of the snapshots?
Answer: D
Explanation:
Security hardening for BCDR is focused on protecting the integrity of recovery points against accidental deletion, administrative errors, or malicious intent such as ransomware. While infrastructure-level hardening like SSH keys (Option C) or host-level security (Option A) is important, they do not prevent a user with valid administrative credentials in Prism from deleting a snapshot. To address the specific requirement of ensuring only " authorized " and verified actions can modify or delete snapshots, the administrator should implement an " Approval Policy " .
An Approval Policy introduces a " four-eyes " principle for critical management tasks. When this policy is active, any attempt to delete or modify a recovery point does not execute immediately. Instead, it triggers a request in the Prism Central " Task " console and enters a " Pending Approval " state. A separate authorized user-an " Approver " -must then review the request and explicitly grant permission before the deletion can occur. This creates a vital procedural safeguard, ensuring that no single individual has the unilateral power to destroy the organization ' s backup data. By configuring this policy, the administrator hardens the DR environment against both internal threats and external actors who might gain access to a single set of admin credentials, providing a robust layer of defense for critical data assets.
NEW QUESTION # 18
An administrator is evaluating Nearsync for critical VMs in a Nutanix Disaster Recovery environment. What is the minimum RPO, in minutes, supported by Nearsync replication?
Answer: B
Explanation:
Nutanix Disaster Recovery offers several replication tiers to meet varying business Recovery Point Objectives (RPOs). NearSync replication is a specific technology designed to fill the gap between traditional Asynchronous replication and zero-RPO Synchronous replication.
NearSync replication supports a minimum RPO of 1 minute. It achieves this by using Lightweight Snapshots (LWS), which are highly efficient and can be taken much more frequently than standard full snapshots without causing significant I/O overhead on the system. While some versions of Nutanix software allow NearSync to reach RPOs as low as 20 seconds, the standard minimum RPO recognized in the context of the NCP-BC 7.5 evaluation for minutes-based intervals is 1 minute. Option A (0 RPO) is only achievable through Synchronous replication. Option C (15 minutes) is the typical maximum RPO for NearSync before it transitions to Async, and Option D (60 minutes) is the standard interval for Asynchronous replication.
Understanding these thresholds is essential for administrators when designing protection policies for mission- critical workloads.
NEW QUESTION # 19
......
To make preparation easier for you, Dumps4PDF has created an NCP-BC-7.5 PDF format. This format follows the current content of the Nutanix NCP-BC-7.5 real certification exam. The NCP-BC-7.5 dumps PDF is suitable for all smart devices making it portable. As a result, there are no place and time limits on your ability to go through Nutanix NCP-BC-7.5 Real Exam Questions pdf.
NCP-BC-7.5 Cost Effective Dumps: https://www.dumps4pdf.com/NCP-BC-7.5-valid-braindumps.html
P.S. Free 2026 Nutanix NCP-BC-7.5 dumps are available on Google Drive shared by Dumps4PDF: https://drive.google.com/open?id=1r-VZzrhomkrA8Z9F8kdqnLr7kdmsXJXk