無料でクラウドストレージから最新のJpshiken DP-100 PDFダンプをダウンロードする:https://drive.google.com/open?id=1pGe14x5IM7mBeYCihagGIl-j5pI430od
すべての人々がDP-100試験に合格し、関連する認定を短時間で取得できるように、3つの異なるバージョンのDP-100学習教材を設計しました。製品は、すべての人が同時に学習とテストを行うための実際の試験をシミュレートすることを試みることができ、学習コースでの学習不足に適した環境を提供することができます。当社からDP-100学習教材を購入して使用すると、実際の試験のようにDP-100学習テストを練習し、DP-100試験に簡単に合格できます。
| Section | Weight | Objectives |
|---|---|---|
| Deploy and retrain models | 10-15% | - Implement retraining pipelines
|
| Prepare a model for deployment | 20-25% | - Deploy machine learning models
|
| Explore data and train models | 35-40% | - Prepare data for modeling
|
| Design and prepare a machine learning solution | 20-25% | - Design an Azure Machine Learning workspace
|
Jpshikenは、Designing and Implementing a Data Science Solution on Azure試験に必要な人向けの安定した信頼できる試験問題プロバイダーです。 私たちは長い間市場に滞在し、成長してきました。DP-100試験問題の優れた品質と高い合格率のため、私たちは常にここにいます。 安全な環境と効果的な製品については、数千人の候補者が私たちの研究の質問を選んでいます。なぜあなたは私たちJpshikenの研究の質問に挑戦してみてください。
質問 # 453
You need to select a feature extraction method.
Which method should you use?
正解:C
解説:
In statistics, the Kendall rank correlation coefficient, commonly referred to as Kendall's tau coefficient (after the Greek letter τ), is a statistic used to measure the ordinal association between two measured quantities.
It is a supported method of the Azure Machine Learning Feature selection.
Scenario: When you train a Linear Regression module using a property dataset that shows data for property prices for a large city, you need to determine the best features to use in a model. You can choose standard metrics provided to measure performance before and after the feature importance process completes. You must ensure that the distribution of the features across multiple training models is consistent.
References:
https://docs.microsoft.com/en-us/azure/machine-learning/studio-module-reference/feature-selection-modules Perform Feature Engineering Question Set 3
質問 # 454
You create a training pipeline using the Azure Machine Learning designer. You upload a CSV file that contains the data from which you want to train your model.
You need to use the designer to create a pipeline that includes steps to perform the following tasks:
Select the training features using the pandas filter method.
Train a model based on the naive_bayes.GaussianNB algorithm.
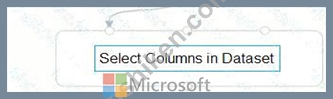
Return only the Scored Labels column by using the query SELECT [Scored Labels] FROM t1; Which modules should you use? To answer, drag the appropriate modules to the appropriate locations. Each module name may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.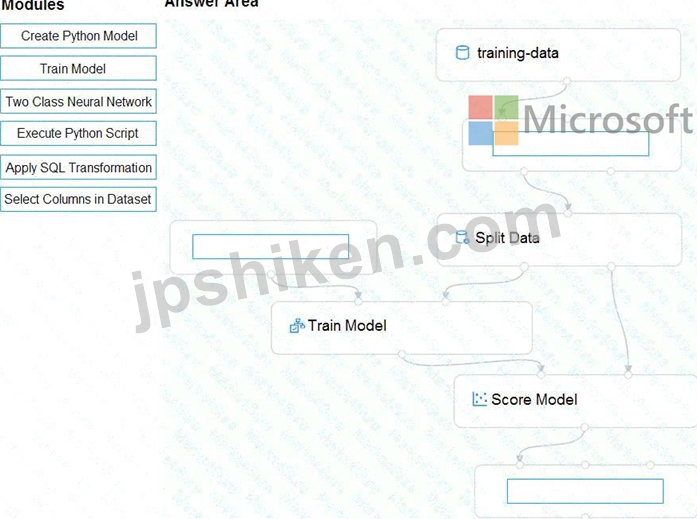
正解:
解説: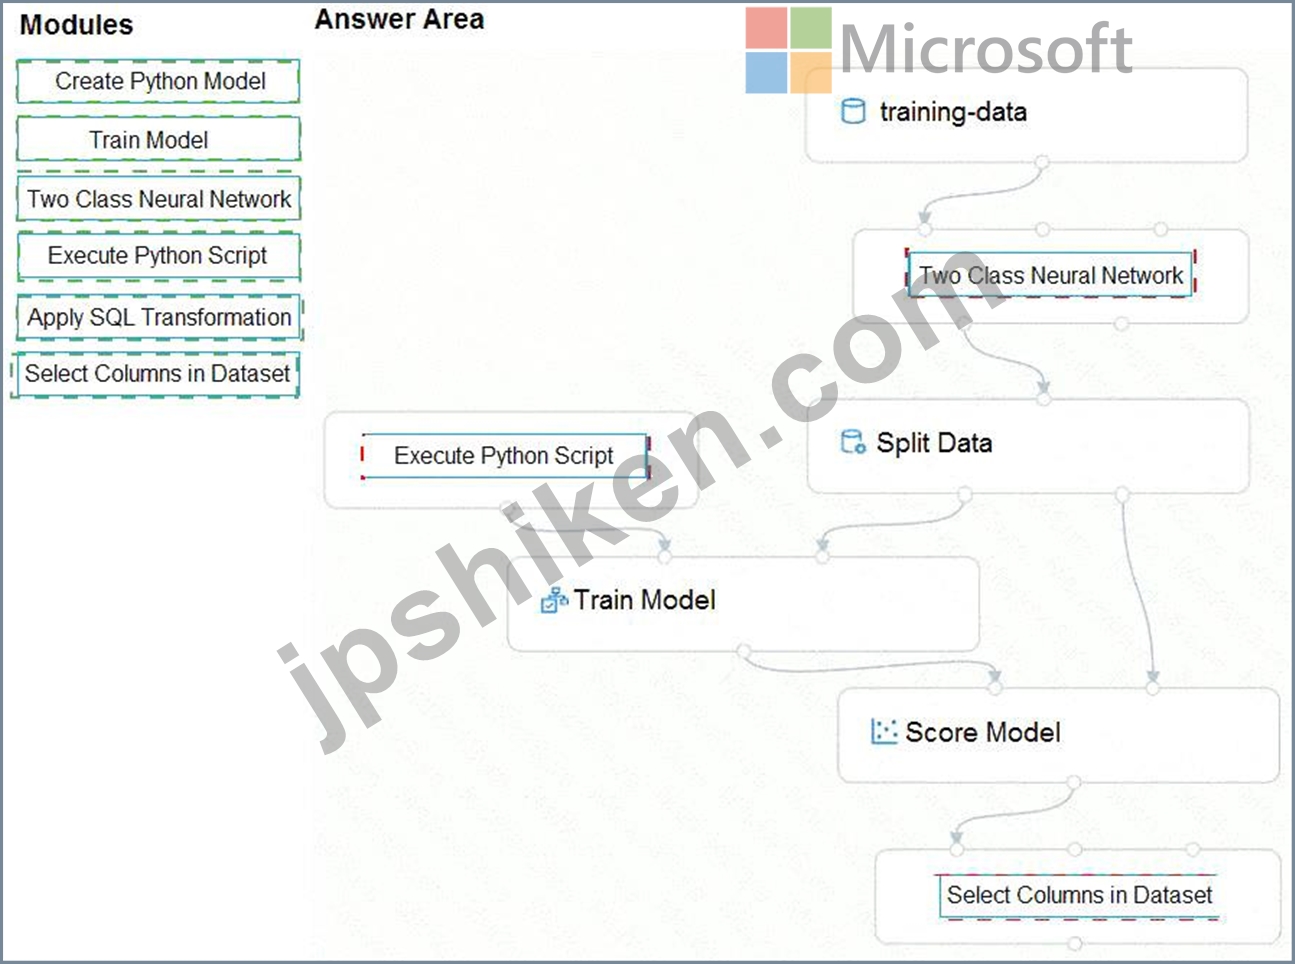
Explanation: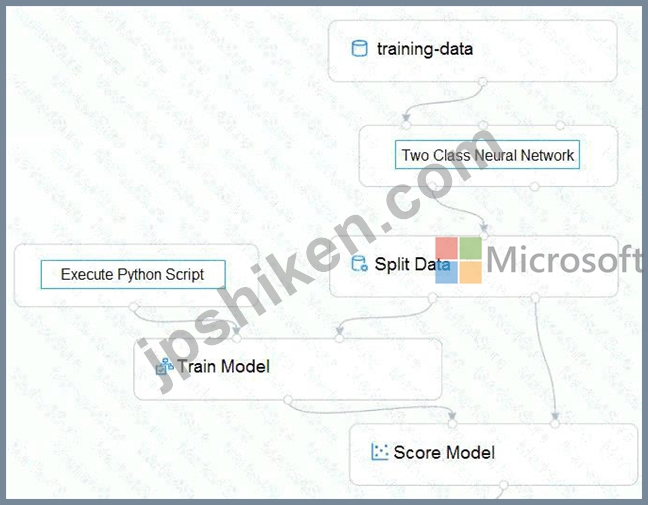
質問 # 455
You have a Python script that executes a pipeline. The script includes the following code:
from azureml.core import Experiment
pipeline_run = Experiment(ws, 'pipeline_test').submit(pipeline)
You want to test the pipeline before deploying the script.
You need to display the pipeline run details written to the STDOUT output when the pipeline completes.
Which code segment should you add to the test script?
正解:C
解説:
wait_for_completion: Wait for the completion of this run. Returns the status object after the wait.
Syntax: wait_for_completion(show_output=False, wait_post_processing=False, raise_on_error=True) Parameter: show_output Indicates whether to show the run output on sys.stdout.
質問 # 456
An organization uses Azure Machine Learning service and wants to expand their use of machine learning.
You have the following compute environments. The organization does not want to create another compute environment.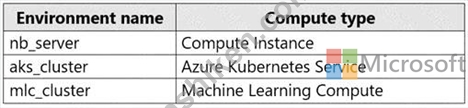
You need to determine which compute environment to use for the following scenarios.
Which compute types should you use? To answer, drag the appropriate compute environments to the correct scenarios. Each compute environment may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.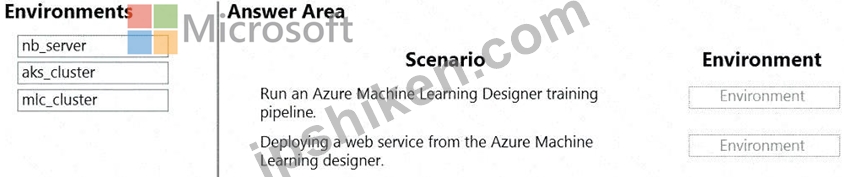
正解:
解説: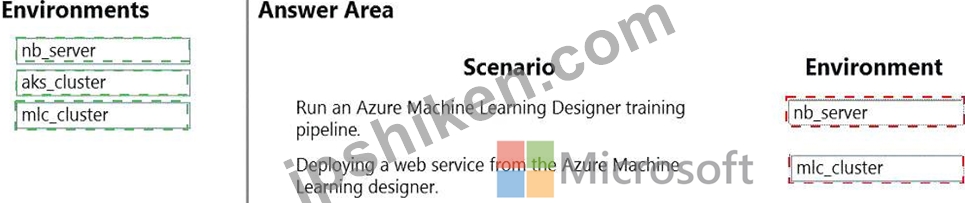
Explanation: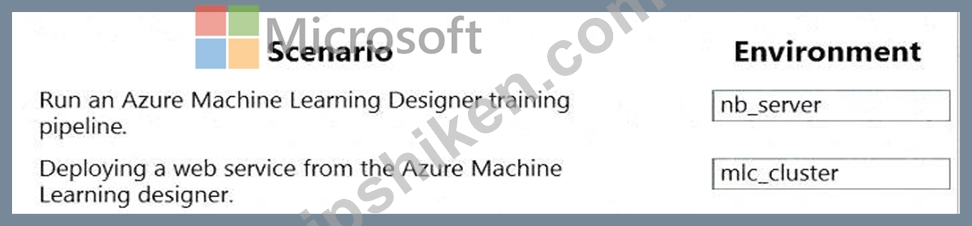
Box 1: nb_server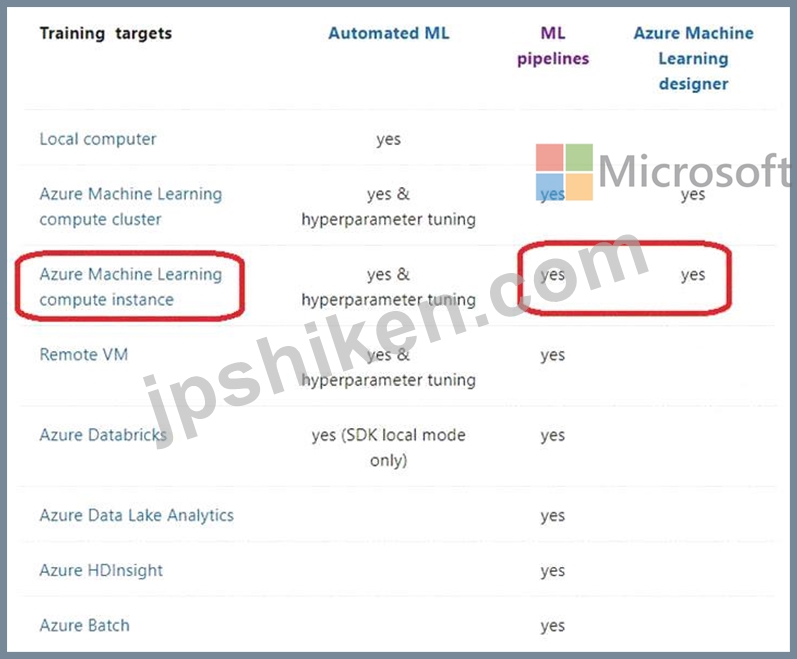
Box 2: mlc_cluster
With Azure Machine Learning, you can train your model on a variety of resources or environments, collectively referred to as compute targets. A compute target can be a local machine or a cloud resource, such as an Azure Machine Learning Compute, Azure HDInsight or a remote virtual machine.
Reference:
https://docs.microsoft.com/en-us/azure/machine-learning/concept-compute-target
https://docs.microsoft.com/en-us/azure/machine-learning/how-to-set-up-training-targets
質問 # 457
You create a multi-class image classification deep learning model.
You train the model by using PyTorch version 1.2.
You need to ensure that the correct version of PyTorch can be identified for the inferencing environment when the model is deployed.
What should you do?
正解:B
解説:
framework_version: The PyTorch version to be used for executing training code.
Reference:
https://docs.microsoft.com/en-us/python/api/azureml-train-
core/azureml.train.dnn.pytorch?view=azure-ml-py
質問 # 458
......
あなたはいい仕事を見つけたい場合、DP-100参考資料を選択してください。多くのお客様はDP-100試験参考書を選択したら、DP-100認定試験資格証明書を取得しました。また、Microsoftのサービスもいいし、24時間のサービスを提供できます。だから、それは最もいい資料です。
DP-100関連受験参考書: https://www.jpshiken.com/DP-100_shiken.html
P.S. JpshikenがGoogle Driveで共有している無料かつ新しいDP-100ダンプ:https://drive.google.com/open?id=1pGe14x5IM7mBeYCihagGIl-j5pI430od