P.S. Free & New Databricks-Certified-Data-Engineer-Professional dumps are available on Google Drive shared by FreeCram: https://drive.google.com/open?id=1ZWps01O8FTbx8kQcPkQV5ZSUZQ8A4cXh
The one badge of Databricks-Certified-Data-Engineer-Professional certificate will increase your earnings and push you forward to achieve your career objectives. Are you ready to accept this challenge? Looking for the simple and easiest way to pass the Databricks-Certified-Data-Engineer-Professional certification exam? If your answer is yes then you do not need to get worried. Just visit the Databricks Databricks-Certified-Data-Engineer-Professional Pdf Dumps and explore the top features of Databricks-Certified-Data-Engineer-Professional test questions. If you feel that Databricks Certified Data Engineer Professional Exam Databricks-Certified-Data-Engineer-Professional exam questions can be helpful in exam preparation then download Databricks Certified Data Engineer Professional Exam Databricks-Certified-Data-Engineer-Professional updated questions and start preparation right now.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Monitoring and Troubleshooting | 16% | - Monitoring - Performance Optimization - Troubleshooting |
| Topic 2: Data Modeling and Storage | 20% | - Data Modeling - File Formats - Storage Optimization |
| Topic 3: Data Quality and Governance | 12% | - Governance - Data Lineage - Data Quality |
| Topic 4: Databricks Lakehouse Platform | 24% | - Data Management - Lakehouse Architecture - Unity Catalog - Delta Lake |
| Topic 5: Data Processing | 28% | - ETL Pipelines - Structured Streaming - Spark SQL - Data Transformation |
>> Current Databricks-Certified-Data-Engineer-Professional Exam Content <<
As a member of the people working in the Databricks-Certified-Data-Engineer-Professional industry, do you have a headache for passing some Databricks certification exams? Generally, Databricks-Certified-Data-Engineer-Professional certification exams are used to test the examinee's related Databricks-Certified-Data-Engineer-Professional professional knowledge and experience and it is not easy pass these exams. For the examinees who are the first time to participate Databricks-Certified-Data-Engineer-Professional certification exam, choosing a good pertinent training program is very necessary. FreeCram can offer a specific training program for many examinees participating in Databricks certification exams. Our training program includes simulation test before the formal examination, specific training course and the current exam which has 95% similarity with the real exam. Please add FreeCram to you shopping car quickly.
NEW QUESTION # 30
A Delta Lake table in the Lakehouse named customer_parsams is used in churn prediction by the machine learning team. The table contains information about customers derived from a number of upstream sources. Currently, the data engineering team populates this table nightly by overwriting the table with the current valid values derived from upstream data sources.
Immediately after each update succeeds, the data engineer team would like to determine the difference between the new version and the previous of the table. Given the current implementation, which method can be used?
Answer: A
Explanation:
Delta Lake provides built-in versioning and time travel capabilities, allowing users to query previous snapshots of a table. This feature is particularly useful for understanding changes between different versions of the table. In this scenario, where the table is overwritten nightly, you can use Delta Lake's time travel feature to execute a query comparing the latest version of the table (the current state) with its previous version. This approach effectively identifies the differences (such as new, updated, or deleted records) between the two versions. The other options do not provide a straightforward or efficient way to directly compare different versions of a Delta Lake table.
NEW QUESTION # 31
A data engineer is developing a Lakeflow Declarative Pipeline (LDP) using a Databricks notebook directly connected to their pipeline. After adding new table definitions and transformation logic in their notebook, they want to check for any syntax errors in the pipeline code without actually processing data or running the pipeline. How should the data engineer perform this syntax check?
Answer: B
Explanation:
Databricks provides a "Validate" option within the Lakeflow Declarative Pipeline development interface that checks pipeline configurations, transformations, and syntax errors before actual execution.
This feature parses and validates the pipeline logic defined in notebooks or workspace files to ensure correctness and consistency of table dependencies, DLT (Delta Live Table) syntax, and schema references.
The validation process does not process or move any data, making it ideal for testing new configurations before deployment.
Using the shell terminal (B) or workspace files (D) does not perform integrated pipeline-level validation, while reconnecting to compute clusters (C) is unrelated to syntax checks. Therefore, the verified and correct approach is A.
NEW QUESTION # 32
A Delta Lake table representing metadata about content from user has the following schema:
user_id LONG, post_text STRING, post_id STRING, longitude FLOAT, latitude FLOAT, post_time TIMESTAMP, date DATE Based on the above schema, which column is a good candidate for partitioning the Delta Table?
Answer: E
Explanation:
Partitioning a Delta Lake table improves query performance by organizing data into partitions based on the values of a column. In the given schema, the date column is a good candidate for partitioning for several reasons:
Time-Based Queries: If queries frequently filter or group by date, partitioning by the date column can significantly improve performance by limiting the amount of data scanned. Granularity: The date column likely has a granularity that leads to a reasonable number of partitions (not too many and not too few). This balance is important for optimizing both read and write performance.
Data Skew: Other columns like post_id or user_id might lead to uneven partition sizes (data skew), which can negatively impact performance.
Partitioning by post_time could also be considered, but typically date is preferred due to its more manageable granularity.
NEW QUESTION # 33
A table in the Lakehouse named customer_churn_params is used in churn prediction by the machine learning team. The table contains information about customers derived from a number of upstream sources. Currently, the data engineering team populates this table nightly by overwriting the table with the current valid values derived from upstream data sources.
The churn prediction model used by the ML team is fairly stable in production. The team is only interested in making predictions on records that have changed in the past 24 hours.
Which approach would simplify the identification of these changed records?
Answer: E
Explanation:
The approach that would simplify the identification of the changed records is to replace the current overwrite logic with a merge statement to modify only those records that have changed, and write logic to make predictions on the changed records identified by the change data feed.
This approach leverages the Delta Lake features of merge and change data feed, which are designed to handle upserts and track row-level changes in a Delta table. By using merge, the data engineering team can avoid overwriting the entire table every night, and only update or insert the records that have changed in the source data. By using change data feed, the ML team can easily access the change events that have occurred in the customer_churn_params table, and filter them by operation type (update or insert) and timestamp. This way, they can only make predictions on the records that have changed in the past 24 hours, and avoid re-processing the unchanged records.
NEW QUESTION # 34
A data engineer wants to join a stream of advertisement impressions (when an ad was shown) with another stream of user clicks on advertisements to correlate when impressions led to monetizable clicks.
In the code below, Impressions is a streaming DataFrame with a watermark ("event_time", "10 minutes")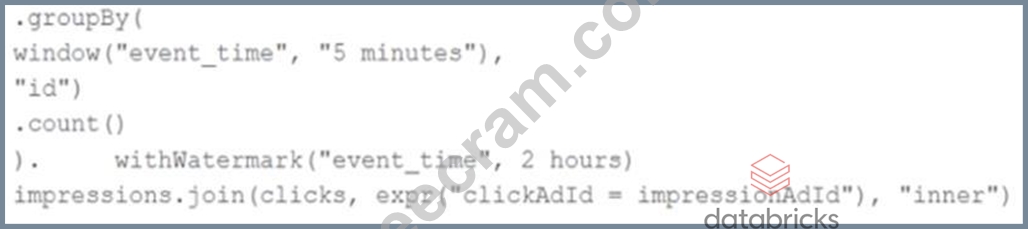
The data engineer notices the query slowing down significantly.
Which solution would improve the performance?
Answer: B
NEW QUESTION # 35
......
FreeCram Databricks-Certified-Data-Engineer-Professional practice test has real Databricks-Certified-Data-Engineer-Professional exam questions. You can change the difficulty of these questions, which will help you determine what areas appertain to more study before taking your Databricks Databricks-Certified-Data-Engineer-Professional Exam Dumps. Here we listed some of the most important benefits you can get from using our Databricks Databricks-Certified-Data-Engineer-Professional practice questions.
Reliable Databricks-Certified-Data-Engineer-Professional Test Guide: https://www.freecram.com/Databricks-certification/Databricks-Certified-Data-Engineer-Professional-exam-dumps.html
BTW, DOWNLOAD part of FreeCram Databricks-Certified-Data-Engineer-Professional dumps from Cloud Storage: https://drive.google.com/open?id=1ZWps01O8FTbx8kQcPkQV5ZSUZQ8A4cXh