Without doubt, our AI-103 practice dumps keep up with the latest information and contain the most valued key points that will show up in the real AI-103 exam. Meanwhile, we can give you accurate and instant suggestion for our customer services know every detail of our AI-103 Exam Questions. And they are pleased to give guide for 24 hours online. You can get assistant by them as long as you made your inquire.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Implement generative AI solutions | 25-30% | - Optimize and evaluate models
|
| Topic 2: Implement agentic solutions | 20-25% | - Build AI agents
|
| Topic 3: Implement computer vision solutions | 10-15% | - Analyze visual content
|
| Topic 4: Plan and manage Azure AI solutions | 25-30% | - Plan Azure AI resources
|
| Topic 5: Implement text analysis and information extraction solutions | 10-15% | - Analyze and extract information
|
We provide free PDF demo for each exam. This free demo is a small part of the official complete Microsoft AI-103 training dumps. The free demo can show you the quality of our exam materials. You can download any time before purchasing. You can tell if our products and service have advantage over others. I believe our Microsoft AI-103 training dumps will be the highest value with competitive price comparing other providers.
NEW QUESTION # 101
You are building a text-to-speech solution that uses Azure Speech in Foundry Tools to read instructions from the script in a text file.
You discover that the solution often pronounces technical terms incorrectly.
You need to prevent the incorrect pronunciations. The solution must minimize development effort.
What should you do?
Answer: A
Explanation:
Using Speech Synthesis Markup Language (SSML) with the <phoneme> element is the ideal way to fix mispronunciations for technical terms.
The <phoneme> tag lets you override the default text-to-speech model by explicitly defining the sounds using the International Phonetic Alphabet (IPA).
Reference:
https://learn.microsoft.com/en-us/answers/questions/5729867/pronunciation-issue-when-generating-audio-from-ssm
NEW QUESTION # 102
You have a Microsoft Foundry project that contains an agent. The agent has a Model Context Protocol (MCP) tool that queries a knowledge base stored in Azure AI Search.
Some agent runs return answers from the base model without invoking the knowledge base, which results in responses without grounded citations.
You are provided with the following code snippet that runs the agent.
run = project_client.agents.runs.create_and_process(
thread_id=thread.id,
agent_id=agent.id,
)
You need to add the correct tool_choice parameter to the code to deterministically force the agent to invoke the MCP tool on each run.
What should you add?
Answer: C
Explanation:
The correct selection is D . In Microsoft Foundry Agent Service, tool_choice is the runtime control used to influence whether the model may answer directly or must invoke a tool. Microsoft's tool best-practice guidance states that auto lets the model decide whether to call tools, none prevents tool calls, and required means the model must call one or more tools. This directly addresses the issue where some runs answer from the base model and skip the knowledge base.
For an agentic retrieval solution backed by Azure AI Search through an MCP tool, Microsoft's tutorial states that setting tool_choice= " required " ensures the agent always uses the knowledge base tool when processing queries. This produces grounded answers because the run is forced into tool invocation before responding.
auto is incorrect because it preserves the nondeterministic behavior already causing missing citations. { " type
" : " knowledge_base " } is not a valid Foundry tool-choice type. { " type " : " mcp " } describes an MCP tool type in some Responses API schemas, but the deterministic guarantee for this agent run scenario is the required tool-call mode. Reference topics: Microsoft Foundry Agent Service, MCP tools, Azure AI Search agentic retrieval, tool_choice, and grounded citations.
NEW QUESTION # 103
You need to configure the model deployment for Agent1 to meet the technical requirements.
What should you configure? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.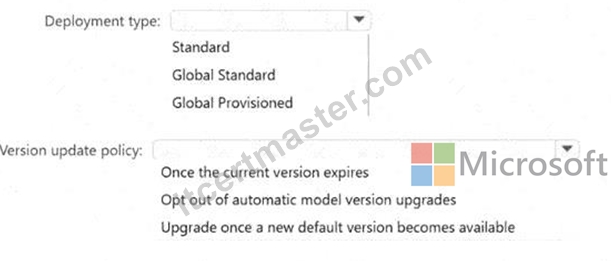
Answer:
Explanation: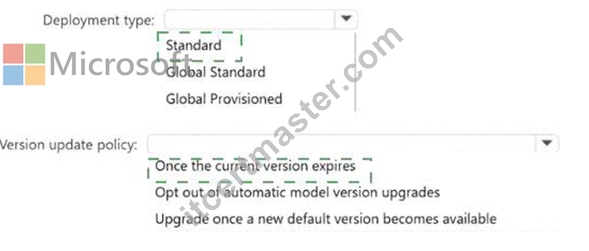
Explanation:
Deployment type: Standard
Version update policy: Once the current version expires
The correct deployment type is Standard . The case study specifies that Project1 is deployed in an EU Azure region and that model-processed data must remain within the EU. It also requires scalable, high-throughput generative AI workloads that dynamically handle variable customer support traffic without reserved throughput capacity. In Microsoft Foundry Models, Standard is a pay-per-token deployment type that processes data in a single Azure region, while Global Standard can process requests across regions and Global Provisioned uses reserved provisioned throughput. Microsoft's deployment-type guidance identifies Standard as single-region, pay-per-token, whereas Global Provisioned is cross-region with reserved capacity.
The correct version update policy is Once the current version expires . This keeps Agent1 on the selected model version during its supported lifecycle, which supports stable and consistent responses, but still preserves continuity by automatically moving to a supported replacement when the current version is retired.
Microsoft's model versioning guidance states that this policy updates only when the current model version expires, while upgrading when a new default is available changes the deployment sooner and opting out can cause the deployment to stop working after retirement. Reference topics: deployment types, regional data processing, model versioning, throughput capacity, and stable production deployments.
NEW QUESTION # 104
You have an invoice-processing application named App1 that uses Azure Content Understanding in Foundry Tools. You are building a new Content Understanding pipeline named Pipeline1 that must meet the following requirements:
* Compare an invoice to its related purchase order.
* Validate the invoice against static vendor contract documents.
* Return a single structured output that includes discrepancy findings.
You need to configure Pipeline1 and expose the pipeline as a single analyzer endpoint. What should you configure?
Answer: C
Explanation:
Configure a multi-file task in pro mode . At analysis time, provide the invoice and its related purchase order as the input documents. During analyzer creation, add the static vendor contracts as reference data . Pro mode can reason across multiple input documents and use reference documents as contextual knowledge for validation, enrichment, and discrepancy detection. Microsoft specifically documents the scenario of supplying an invoice and purchase order as inputs while using contract files as reference data to identify inconsistencies.
Define a field schema containing the required invoice information and generated discrepancy findings.
Building the task creates an analyzer ID that applications invoke through one analyzer API endpoint, producing a unified structured result governed by that schema.
Standard mode is optimized for straightforward processing of individual files. It does not support cross-file analysis, reference-dataset integration, or the multi-step reasoning required to compare invoices, purchase orders, and contractual conditions. A "multi-file task in standard mode" is therefore not a supported configuration. Confidence scores do not address document comparison and, notably, are not available in pro mode.
Study Guide alignment: configure Content Understanding analyzers, design structured schemas, process multiple documents, integrate reference data, and implement document validation workflows .
NEW QUESTION # 105
You have a Microsoft Foundry project that contains an agent and an image generation model deployment.
The agent generates original images from user-supplied product photos.
You need to ensure that the generated images maintain the product identity and visual characteristics of the provided photo.
What should you do?
Answer: C
Explanation:
You should set the input_fidelity parameter to "high" in this scenario.
In Microsoft Foundry (built on Azure AI Foundry), the input_fidelity parameter specifically dictates how strictly the image generation model adheres to the visual features, layout, and style of the source image.
Why "high" is the Correct Choice
Preserves Product Identity: Setting input_fidelity="high" ensures that critical branding details, logos, structures, and product contours are preserved exactly as they appear in the original photo.
Designed for E-commerce: Microsoft explicitly designed this setting for e-commerce, commercial marketing assets, and product photography to prevent the model from hallucinating or altering key product characteristics.
Model Support: This parameter is natively supported when configuring agent image generation tools (such as the ImageGenerationTool or ImageGenTool classes in the Foundry Agent Service) leveraging advanced models like GPT-image-1 or GPT-image-2.
Reference:
https://developers.openai.com/cookbook/examples/generate_images_with_high_input_fidelity
NEW QUESTION # 106
......
Once you have any questions about our AI-103 actual exam, you can contact our staff online or send us an email. We have a dedicated all-day online service to help you solve problems. Before purchasing, you may be confused about what kind of AI-103 Guide questions you need. You can consult our staff online. After the consultation, your doubts will be solved and you will choose the AI-103 learning materials that suit you.
Test AI-103 Pass4sure: https://www.itcertmaster.com/AI-103.html