What's more, part of that PracticeTorrent Certified-Data-Engineer-Professional dumps now are free: https://drive.google.com/open?id=1Szv-WKIbZ5aeI3KDCkJOWmqloAx5yaQv
Everyone has the right to pursue happiness and wealth. You can rely on the Certified-Data-Engineer-Professional certificate to support yourself. If you do not own one or two kinds of skills, it is difficult for you to make ends meet in the modern society. After all, you can rely on no one but yourself. At present, our Certified-Data-Engineer-Professionalstudy materials can give you a ray of hope. You can get the Certified-Data-Engineer-Professional certification easily with our Certified-Data-Engineer-Professional learning questions and have a better future.
| Section | Weight | Objectives |
|---|---|---|
| Data Sharing and Federation | ~8% | - Configure Delta Sharing and Lakehouse Federation |
| Streaming Workloads and Change Data Capture | ~11% | - Implement reliable streaming pipelines - Apply AUTO CDC APIs and exactly-once semantics |
| Data Modeling | ~10% | - Design scalable Delta Lake schemas and clustering - Apply dimensional modeling techniques |
| Security and Governance | ~10% | - Manage Unity Catalog permissions and ACLs - Implement row-level security, column masking, and compliance |
| CI/CD, Testing, and Deployment | ~6% | - Implement testing and deployment pipelines - Deploy with Declarative Automation Bundles, CLI, and REST API |
| Data Transformation, Cleansing, and Quality | ~12% | - Enforce data quality and quarantine bad data - Apply advanced Spark transformations |
| Cost and Performance Optimization | ~13% | - Leverage system tables and observability tools - Optimize queries, clusters, and storage |
| Developing Code for Data Processing using Python and SQL | ~22% | - Build pipelines with Lakeflow Spark Declarative Pipelines and Auto Loader - Manage dependencies, libraries, and UDFs - Implement scalable Python/SQL code and project structures |
| Monitoring, Logging, and Troubleshooting | ~8% | - Diagnose common pipeline and job failures - Use Spark UI, Query Profiler, and system tables |
>> Databricks Certified-Data-Engineer-Professional Free Dumps <<
Yes, as a lot of our loyal customers who have passed the Certified-Data-Engineer-Professional exam and got the certification said that more than the Certified-Data-Engineer-Professional certification, they felt they had been benifited more for they had obtained the knowledge and apply it in the daily work, which can help them finish all tasks efficiently. Then they do not need to work overtime. It is necessary to learn our Certified-Data-Engineer-Professional Guide materials if you want to own a bright career development.
NEW QUESTION # 76
A data engineer has a Delta table orders with deletion vectors enabled. The engineer executes the following command:
DELETE FROM orders WHERE status = 'cancelled';
What should be the behavior of deletion vectors when the command is executed?
Answer: D
Explanation:
Deletion vectors (DVs) in Delta Lake optimize delete operations by marking deleted rows logically in metadata rather than rewriting Parquet files. When a DELETE statement is executed, affected rows are tracked by DVs in the transaction log. The data remains in the underlying files but is filtered out during query reads. This improves performance for frequent deletes and updates since file rewrites are deferred. Physical data removal only occurs when a VACUUM command is later executed. The Databricks documentation confirms: "With deletion vectors, deleted rows are marked in metadata and skipped at read time, avoiding file rewrites." Thus, rows are marked as deleted in metadata--not in files.
NEW QUESTION # 77
A data engineer wants to join a stream of advertisement impressions (when an ad was shown) with another stream of user clicks on advertisements to correlate when impression led to monitizable clicks.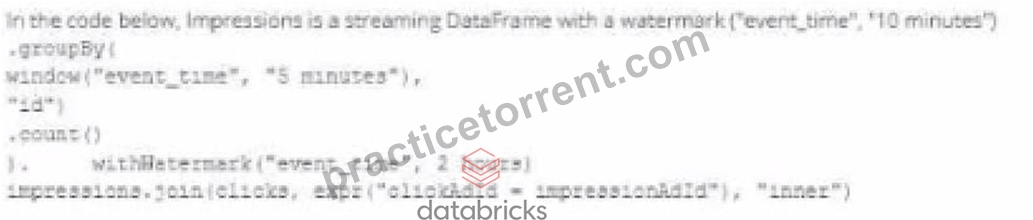
Which solution would improve the performance?




Answer: D
Explanation:
When joining a stream of advertisement impressions with a stream of user clicks, you want to minimize the state that you need to maintain for the join. Option A suggests using a left outer join with the condition that clickTime == impressionTime, which is suitable for correlating events that occur at the exact same time. However, in a real-world scenario, you would likely need some leeway to account for the delay between an impression and a possible click. It's important to design the join condition and the window of time considered to optimize performance while still capturing the relevant user interactions. In this case, having the watermark can help with state management and avoid state growing unbounded by discarding old state data that's unlikely to match with new data.
NEW QUESTION # 78
A data engineer is designing an append-only pipeline that needs to handle both batch and streaming data in Delta Lake. The team wants to ensure that the streaming component can efficiently track which data has already been processed. Which configuration should be set to enable this?
Answer: B
Explanation:
When working with Delta Lake streaming ingestion, checkpointing is critical for maintaining fault tolerance and ensuring exactly-once data processing semantics.
The checkpointLocation parameter defines the directory where Spark Structured Streaming stores progress information, offsets, and metadata. This allows the engine to resume processing from the last committed offset without reprocessing previously ingested data.
Without checkpointing, each stream restart would reprocess all data, leading to duplicates.
Parameters like partitionBy or schema options (mergeSchema / overwriteSchema) affect table structure, not data lineage tracking. Therefore, the correct and required configuration for efficient streaming state management is checkpointLocation.
NEW QUESTION # 79
Spill occurs as a result of executing various wide transformations. However, diagnosing spill requires one to proactively look for key indicators.
Where in the Spark UI are two of the primary indicators that a partition is spilling to disk?
Answer: D
Explanation:
In the Spark UI, the Stage's detail screen provides key metrics about each stage of a job, including the amount of data that has been spilled to disk. If you see a high number in the "Spill (Memory)" or "Spill (Disk)" columns, it's an indication that a partition is spilling to disk.
The Executor's log files can also provide valuable information about spill. If a task is spilling a lot of data, you'll see messages in the logs like "Spilling UnsafeExternalSorter to disk" or "Task memory spill". These messages indicate that the task ran out of memory and had to spill data to disk.
NEW QUESTION # 80
A data company uses Databricks Unity Catalog and has multiple enterprise data sources, including PostgreSQL, Snowflake, and SQL Server. The central data platform team wants to configure Lakehouse Federation so analysts can query external tables directly in Databricks using Databricks SQL, without duplicating data. Which steps are necessary to configure Lakehouse Federation in a secure and governed manner?
Answer: A
Explanation:
Lakehouse Federation is configured by defining secure connections to external data sources and registering them as foreign catalogs in Unity Catalog. Access is then governed using Unity Catalog permissions at the catalog, schema, and table levels, enabling analysts to query external tables securely without data duplication.
NEW QUESTION # 81
......
We have installed the most advanced operation system in our company which can assure you the fastest delivery speed, to be specific, you can get immediately our Certified-Data-Engineer-Professional training materials only within five to ten minutes after purchase after payment. At the same time, your personal information on our Certified-Data-Engineer-Professional Exam Questions will be encrypted automatically by our operation system as soon as you pressed the payment button, that is to say, there is really no need for you to worry about your personal information if you choose to buy the Certified-Data-Engineer-Professional exam practice from our company.
Valid Braindumps Certified-Data-Engineer-Professional Pdf: https://www.practicetorrent.com/Certified-Data-Engineer-Professional-practice-exam-torrent.html
BONUS!!! Download part of PracticeTorrent Certified-Data-Engineer-Professional dumps for free: https://drive.google.com/open?id=1Szv-WKIbZ5aeI3KDCkJOWmqloAx5yaQv