Sie brauchen nicht die komplizierte Ordnungsarbeit machen. Sie brauchen nicht für eine lange Zeit warten. Auf unserer Webseite können Sie die neueste und zuverlässigste Prüfungsunterlagen für Microsoft DP-800 erhalten. Unterschiedliche Versionen bieten Ihnen unterschiedliche Emfindungen. Was zweifellos ist, dass alle Versionen von Microsoft DP-800 sind effektiv. Bezahlen Sie mit gesichertem Zahlungsmittel Paypal! Dann können Sie gleich die Microsoft DP-800 Prüfungsunterlagen herunterlagen und benutzen!
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Design and develop database solutions | 35-40% | - Design database solutions
|
| Topic 2: Implement AI capabilities in database solutions | 25-30% | - Build intelligent search and retrieval
|
| Topic 3: Secure, optimize, and deploy database solutions | 35-40% | - Deploy and maintain solutions
|
Die Prüfungsfragen und Antworten zur Microsoft DP-800 Zertifizierungsprüfung von DeutschPrüfung wird von unserem Expertenteam nach ihren umfangreichen Kenntnissen und Erfahrungen berarbeitet. Sie können die Bedürfnisse der Kandidaten abdecken. Sie finden vielleicht in anderen Büchern oder auf anderen Websites auch die Microsoft DP-800 Schulungsunterlagen. Aber die Schulungsunterlagen von DeutschPrüfung sind die umfassendste unter ihnen und zugleich kann Ihnen die beste Garantie geben. Bitte wählen Sie die Microsoft DP-800 Prüfungsfragen und Antworten von DeutschPrüfung.
28. Frage
You have a database named DB1. The schema is stored in a GitHub repository as an SDK style SQL database project.
You use a feature branch workflow to deploy changes to DB1
You need to update the local feature branch with the latest changes to main, and then create a pull request to merge the feature branch into main for review.
How should you complete the GitHub CLI script? To answer, drag the appropriate values to the correct targets. Each value may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.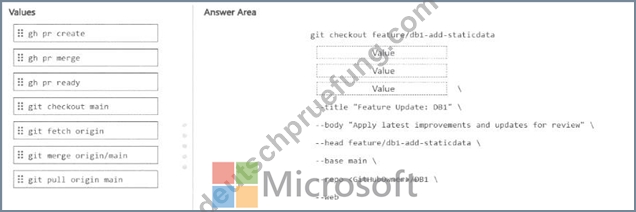
Antwort:
Begründung: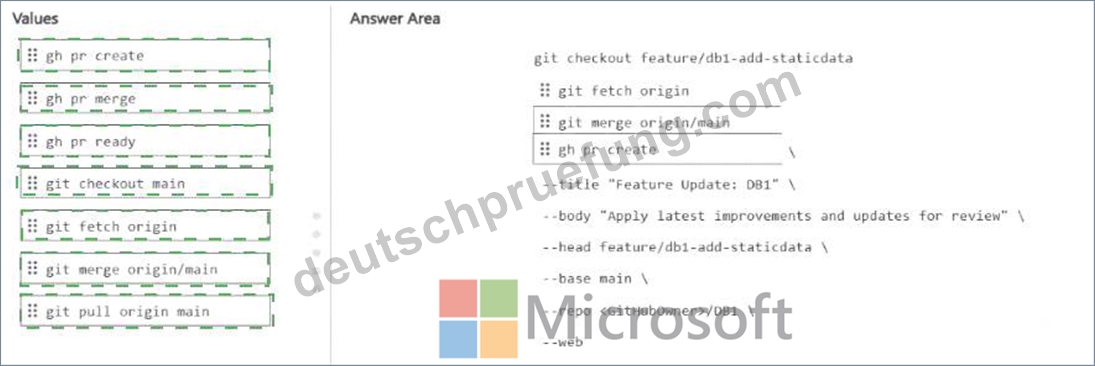
Explanation: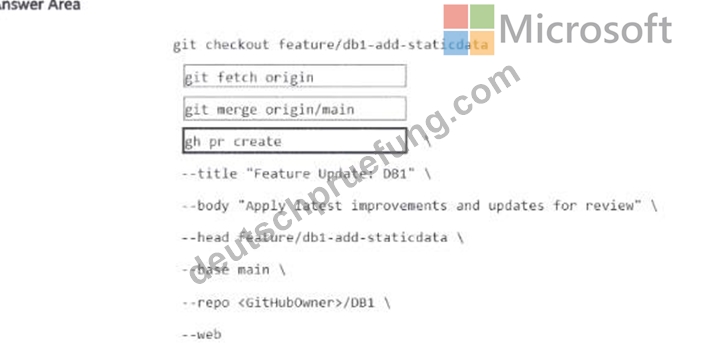
The correct sequence is:
* git fetch origin
* git merge origin/main
* gh pr create
This is the right workflow because the script starts on the local feature branch:
git checkout feature/db1-add-staticdata
To update that local feature branch with the latest changes from main, you first fetch the latest remote refs with git fetch origin , then merge the updated remote main branch into the current feature branch with git merge origin/main . After the feature branch is up to date, the correct GitHub CLI command to open the pull request is gh pr create . GitHub's CLI documentation shows that gh pr create is the command used to create a pull request, and supports flags such as --title, --body, --head, --base, --repo, and --web, which match the script shown in the question.
The other commands are not the best fit here:
* git checkout main would move you off the feature branch, which is not what you want before merging main into the feature branch.
* git pull origin main could update from remote main, but the script pattern here clearly separates fetching and then merging.
* gh pr merge merges an existing pull request, not create one.
* gh pr ready marks a draft PR as ready for review, but does not create the PR.
29. Frage
Case Study 1 - Contoso
Existing Environment
Azure Environment
Contoso has an Azure subscription in North Europe that contains the corporate infrastructure.
The current infrastructure contains a Microsoft SQL Server 2017 database. The database contains the following tables.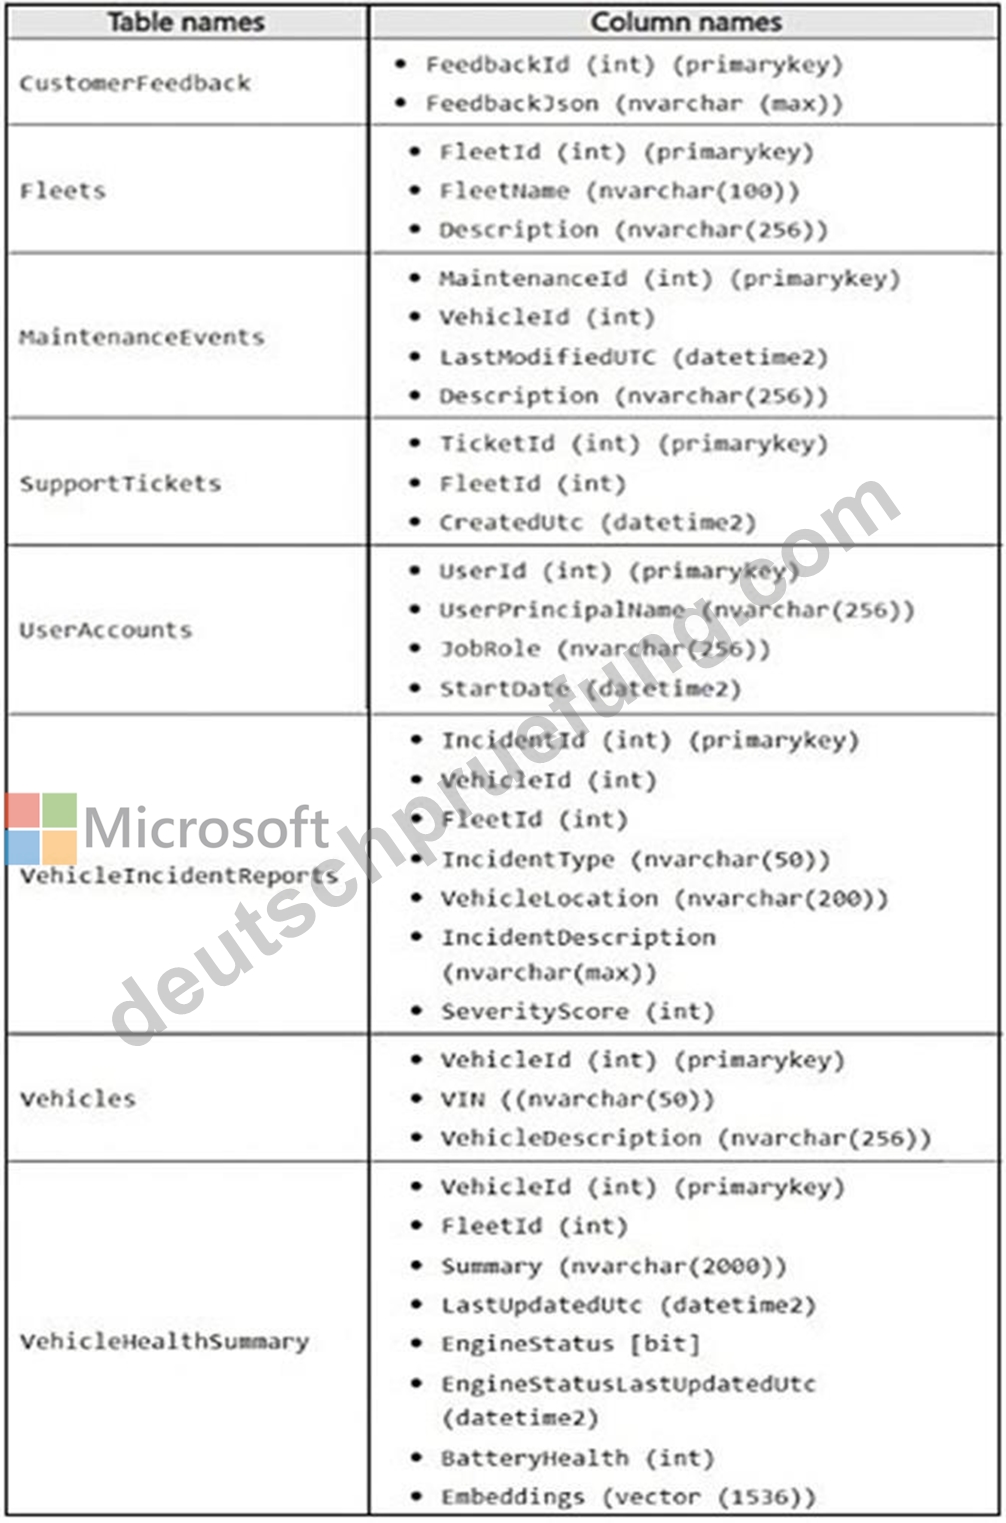
The FeedbackJsoncolumn has a full-text index and stores JSON documents in the following format.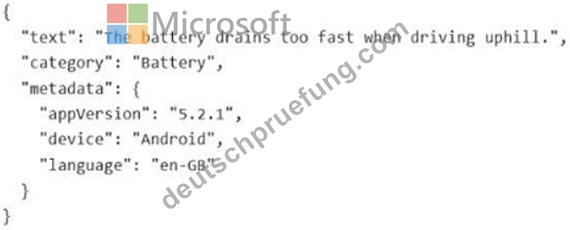
The support staff at Contoso never has the UNMASKpermission.
Problem Statements
Contoso is deploying a new Azure SQL database that will become the authoritative data store for the following:
* AI workloads
* Vector search
* Modernized API access
* Retrieval Augmented Generation (RAG) pipelines
Sometimes the ingestion pipeline fails due to malformed JSON and duplicate payloads.
The engineers at Contoso report that the following dashboard query runs slowly.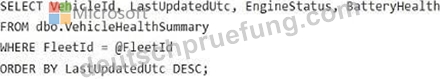
You review the execution plan and discover that the plan shows a clustered index scan.
VehicleIncidentReportsoften contains details about the weather, traffic conditions, and location. Analysts report that it is difficult to find similar incidents based on these details.
Requirements
Planned Changes
Contoso wants to modernize Fleet Intelligence Platform to support AI-powered semantic search over incident reports.
Security Requirements
Contoso identifies the following security requirements:
* Restrict the support staff from viewing Personally Identifiable Information (PII) data, which is full email addresses and phone numbers.
* Enforce row-level filtering so that analysts see only incidents for the fleets to which they are assigned. The analysts can be assigned to multiple fleets.
Database Performance and Requirements
Contoso identifies the following telemetry requirements:
* Telemetry data must be stored in a partitioned table.
* Telemetry data must provide predictable performance for ingestion and retention operations.
* latitude, longitude, and accuracyJSON properties must be filtered by using an index seek.
Contoso identifies the following maintenance data requirements:
* Ensure that any changes to a row in the MaintenanceEventstable updates the corresponding value in the LastModifiedUtccolumn to the time of the change.
* Avoid recursive updates.
AI Search, Embeddings, and Vector Indexing
Contoso plans to implement semantic search over incident data to meet the following requirements:
* Embeddings must be stored in dedicated Azure SQL Database tables.
* Embeddings must be generated from rich natural language fields.
* Chunking must preserve semantic coherence.
* Hybrid search must combine the following:
- Vector similarity
- Keyword filtering or boosting
Development Requirements
The development team at Contoso will use Microsoft Visual Studio Code and GitHub Copilot and will retrieve live metadata from the databases.
Contoso identifies the following requirements for querying data in the FeedbackJsoncolumn of the CustomerFeedbacktable:
* Extract the customer feedback text from the JSON document.
* Filter rows where the JSON text contains a keyword.
* Calculate a fuzzy similarity score between the feedback text and a known issue description.
* Order the results by similarity score, with the highest score first.
Hotspot Question
You need to meet the development requirements for the FeedbackJson column.
How should you complete the Transact-SQL query? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.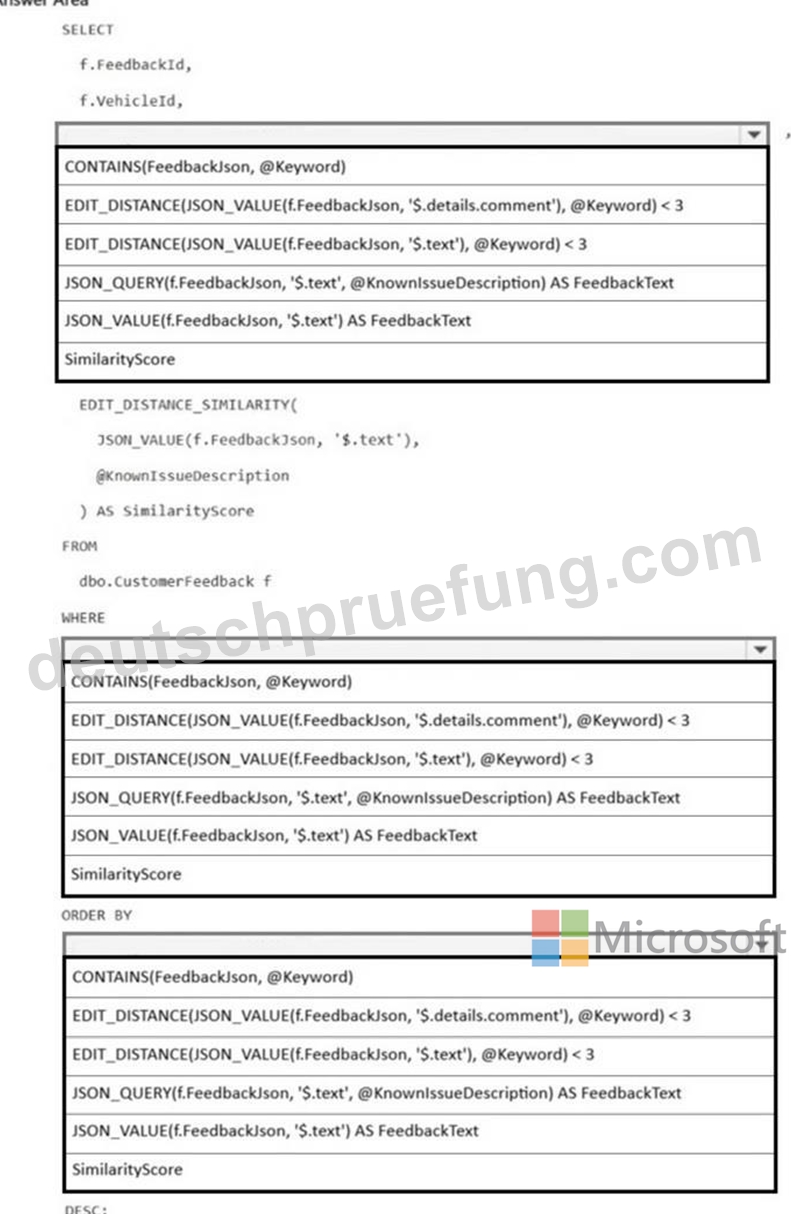
Antwort:
Begründung: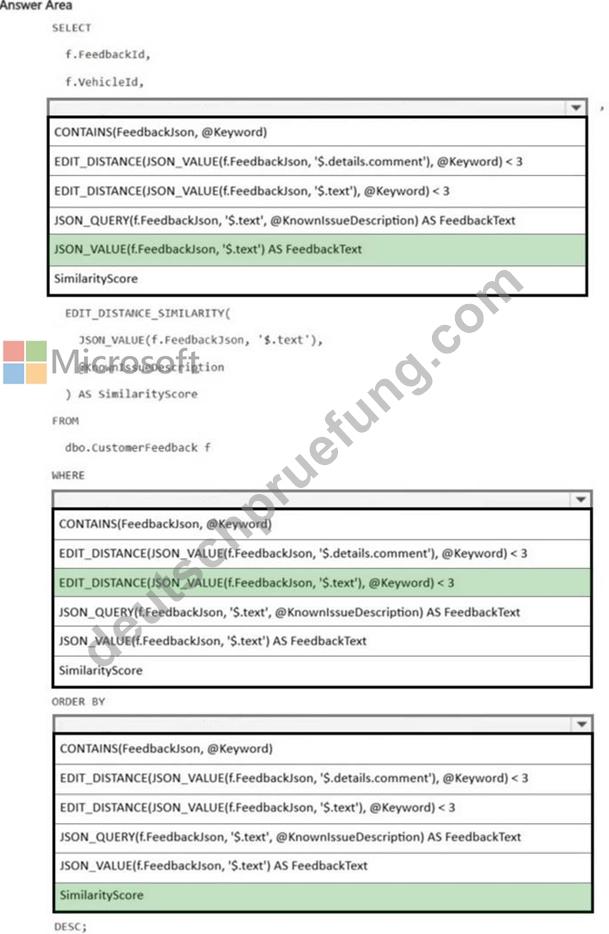
30. Frage
You have an Azure SQL database that contains a table named stores, stores contains a column named description and a vector column named embedding.
You need to implement a hybrid search query that meets the following requirements:
* Uses full-text search on description for the keyword portion
* Returns the top 20 results based on a combined score that uses a weighted formula of 60% vector distance and 40% full-text rank How should you configure the query components? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.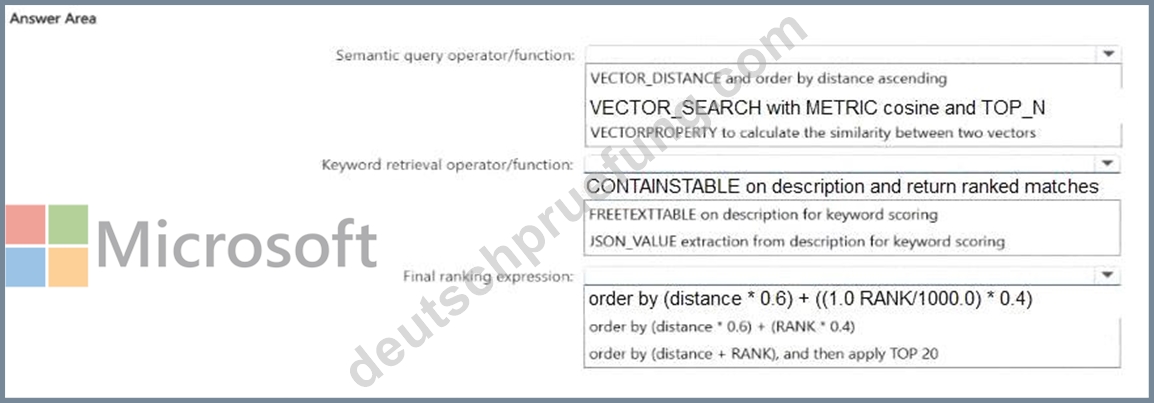
Antwort:
Begründung: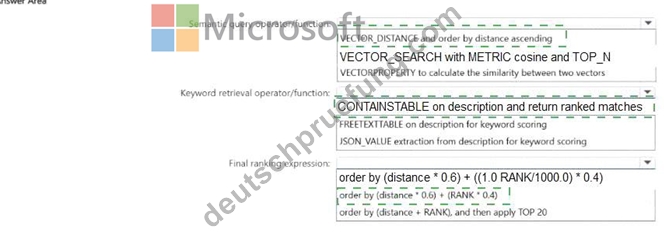
Explanation: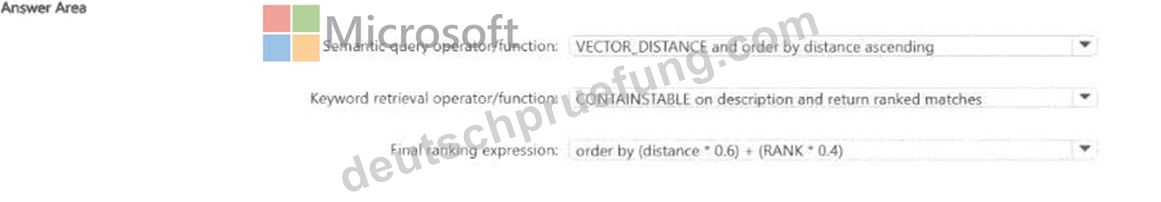
For the vector portion, the correct choice is VECTOR_DISTANCE and order by distance ascending . The requirement is to build a combined weighted formula using the actual vector distance. Microsoft documents that VECTOR_DISTANCE returns the exact distance between two vectors. Since lower distance means greater similarity, ascending distance is the right direction for ranking. VECTOR_SEARCH is for ANN retrieval, but this hotspot specifically asks for a weighted formula based on distance , so VECTOR_DISTANCE is the appropriate operator.
For the keyword portion, the correct choice is CONTAINSTABLE on description and return ranked matches . Microsoft documents that CONTAINSTABLE returns a RANK column from 0 through 1000 , which is exactly what is needed for weighted scoring in a hybrid formula.
For the final ranking expression, the best choice is order by (distance * 0.6) + ((1.0 - RANK/1000.0) * 0.4) .
This works because vector distance is a lower-is-better metric, while full-text RANK is a higher-is-better metric. Dividing RANK by 1000 normalizes it to the documented range, and subtracting from 1.0 converts it into a lower-is-better term so both components can be combined consistently in one ascending score. This final step is a sound inference based on Microsoft's documented distance semantics and full-text rank range.
31. Frage
You have an Azure SQL database that supports an AI-enabled product catalog API. The database contains a table named Sales.Orders. Sales.Orders contains 20 million rows and has a nonclustered index on a column named CreateDate.
The API passes a date parameter named @OrderDate.
You have a stored procedure named get_latest_day_orders that filters by running the following query.
WHERE CAST(CreateDate AS date) = @0rderDate.
A review of the query execution reveals that the query causes an index scan.
You need to modify the predicate to ensure that Microsoft SQL Server can use an index seek on CreateDate for a single day.
Which WHERE clause should you use?
Antwort: B
Begründung:
To achieve an Index Seek on your CreateDate column, you must remove the CAST function from the column side of the equation. Wrapping a column in a function makes the expression non- SARGable (Searchable Argument), forcing SQL Server to scan the entire index rather than jumping to a specific range.
The Recommended WHERE Clause
To capture all rows for a single day while remaining SARGable, use a range comparison:
WHERE CreateDate >= @OrderDate
AND CreateDate < DATEADD(day, 1, @OrderDate)
Why This Works
Eliminates Functions on Columns: By keeping CreateDate "naked," the query optimizer can use the nonclustered index to find the exact starting point.
Handles Time Components: Since CreatedDate likely contains time data (DATETIME or DATETIME2), this logic captures everything from 00:00:00.000 up to (but not including) midnight of the following day.
Single Day Precision: It creates a "half-open" interval that is the standard best practice for date filtering in SQL Server.
Reference:
https://medium.com/@c.charalambos1998/how-to-design-indexes-in-sql-server-for-faster-query- performance-4a2279a9b512
32. Frage
You have an Azure SQL database that has Query Store enabled
Query Performance Insight shows that one stored procedure has the longest runtime. The procedure runs the following parameterized query.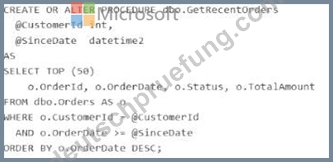
The dbo.orders table has approximately 120 million rows. Customer-id is highly selective, and orderOate is used for range filtering and sorting.
Vou have the following indexes:
* Clustered index: PK_Orders on (Orderld)
* Nonclustered index: lx_0rders_order-Date on (OrderDate) with no included columns An actual execution plan captured from Query Store for slow runs shows the following:
* An index seek on ixordersorderDate followed by a Key Lookup (Clustered) on PKOrders for customerid, status, and TotalAnount
* A sort operator before top (50), because the results are ordered by orderDate DESC For each of the following statements, select Yes if the statement is true. Otherwise, select No. NOTE: Each correct selection is worth one point.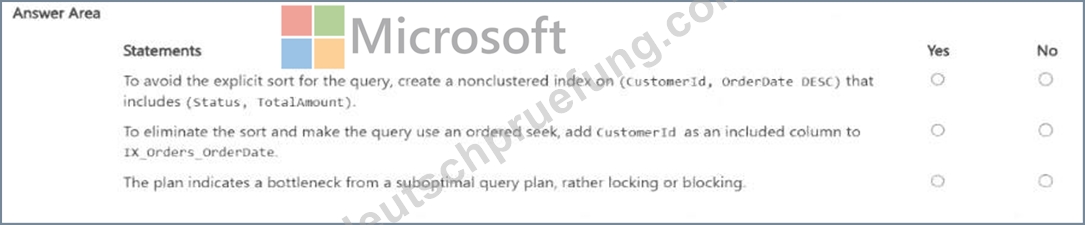
Antwort:
Begründung: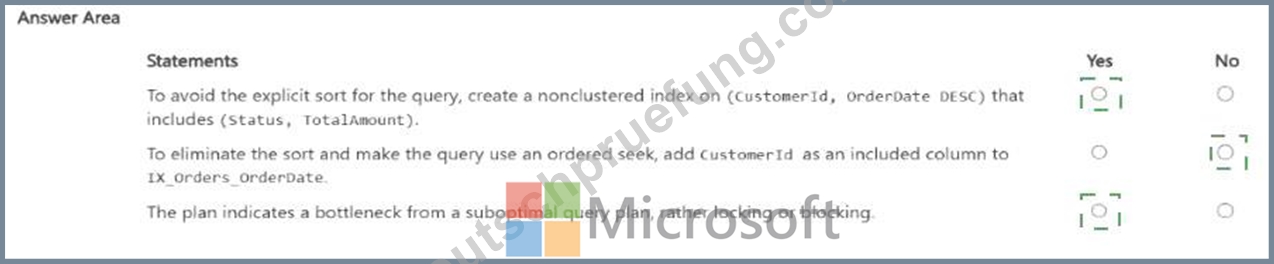
Explanation: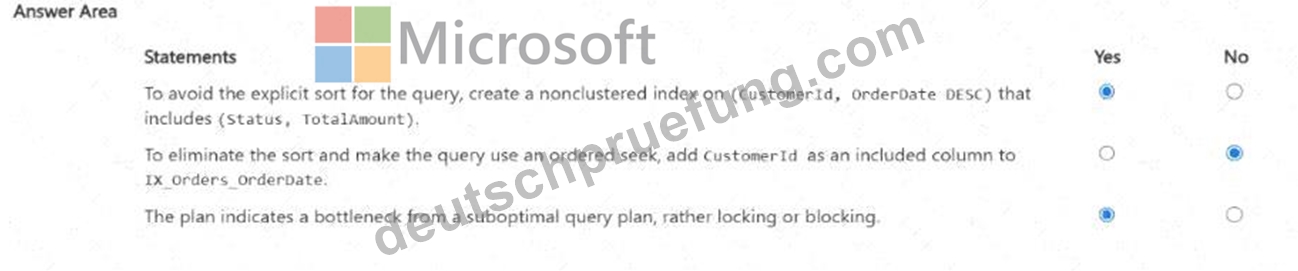
The first statement is Yes . The query filters on CustomerId, applies a range predicate on OrderDate, and sorts by OrderDate DESC. Microsoft's index design guidance recommends putting equality predicates first in the key, followed by columns used for ordering/range access, because the order of key columns determines seek and sort support. A nonclustered index on (CustomerId, OrderDate DESC) can support an ordered seek for this query and avoid the explicit sort. Including Status and TotalAmount helps cover the query, and OrderId is already available because the clustered key is stored with nonclustered index rows.
The second statement is No . Adding CustomerId as an included column to IX_Orders_OrderDate does not make it part of the index's navigational structure. Microsoft states that included columns are nonkey columns used to cover queries; they do not provide the seek and ordering characteristics that key columns do. So an index keyed only on OrderDate still is not the right ordered access path for WHERE CustomerId =
@CustomerId ... ORDER BY OrderDate DESC.
The third statement is Yes . The described actual plan shows an index seek on the wrong access path for the workload, followed by clustered key lookups and an explicit sort before TOP (50). That is characteristic of a suboptimal query/index plan . Query Store and Query Performance Insight are designed to surface plan- related performance regressions, while locking/blocking problems are typically identified through waits
/DMVs and blocking-session indicators, not from a plan shape like seek + lookup + sort alone.
33. Frage
......
Vielleicht haben Sie auch andere ähnliche Trainingsinstrumente für die Microsoft DP-800 Zertifizierungsprüfung auf anderen Websites gesehen. Aber unser DeutschPrüfung stellt eine wichtige Position im Bereich der IT-Zertifizierungsprüfung dar. Mit den wissenschaftlichen Materialien von DeutschPrüfung garantieren wir Ihnen , die DP-800 Prüfung 100% zu bestehen. Mit DeutschPrüfung wird sich Ihre Karriere ändern. Sie können sich erfolgreich in der IT-Branche befördert werden. Wenn Sie DeutschPrüfung wählen, wissen Sie schon, dass Sie sich schon gut auf die Microsoft DP-800 Zertifizierungsprüfung vorbereitet haben. Wir werden Ihnen nicht nur dabei helfen, die Prüfung erfolgreich zu bestehen, sondern auch Ihnen einen einjährigen Update-Service kostenlos bieten.
DP-800 Online Praxisprüfung: https://www.deutschpruefung.com/DP-800-deutsch-pruefungsfragen.html