The language of our DP-750 qualification test guide is simple. The learners may come from many social positions and their abilities to master our DP-750 test materials are varied. Based on this consideration we apply the most simple and easy-to-be-understood language to help the learners no matter he or she is the students or the in-service staff, the novice or the experienced employee which have worked for many years. DP-750 Certification guide use the simple language to explain the answers and detailed knowledge points to help pass the DP-750 exam.
| Section | Weight | Objectives |
|---|---|---|
| Set up and configure an Azure Databricks environment | 15-20% | - Create and configure Azure Databricks workspaces
|
| Secure and govern Unity Catalog objects | 15-20% | - Implement governance and security
|
| Deploy and maintain data pipelines and workloads | 30-35% | - Manage production workloads
|
| Prepare and process data | 30-35% | - Ingest and transform data
|
>> Reliable DP-750 Braindumps Sheet <<
If you want to ace the Implementing Data Engineering Solutions Using Azure Databricks (DP-750) test, the main problem you may face is not finding updated DP-750 practice questions to crack this test quickly. After examining the situation, the ValidBraindumps has come with the idea to provide you with updated and actual Microsoft DP-750 Exam Dumps so you can Pass DP-750 Test on the first attempt. The product of ValidBraindumps has many different premium features that help you use this product with ease. The study material has been made and updated after consulting with a lot of professionals and getting customers' reviews.
NEW QUESTION # 17
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains:
* A catalog named Corpdb
* A schema named Finance in the Corpdb catalog
* A table named Sales in the Finance schema
You have a group named Analysts.
You assign the following permissions to Analysts:
* USE CATALOG on the Corpdb catalog
* USE SCHEMA on the Finance schema
* SELECT on the Sales table
For each of the following statements, select Yes if the statement is true. Otherwise, select No.
NOTE: Each correct selection is worth one point.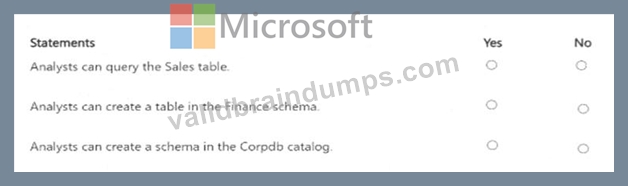
Answer:
Explanation: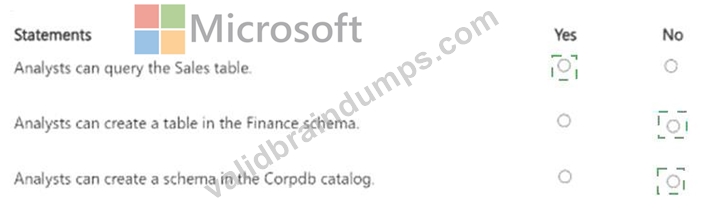
Explanation: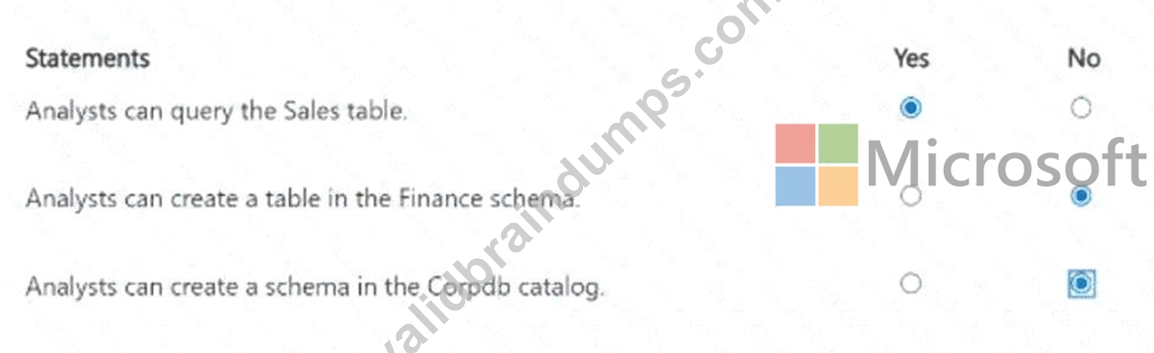
The Analysts group can query the Sales table because it has all three privileges required by the Unity Catalog hierarchy: USE CATALOG on Corpdb, USE SCHEMA on Finance, and SELECT on Sales. These permissions allow the group to navigate through the catalog and schema and read the table. However, USE SCHEMA does not grant permission to create tables. Creating a table in Finance would additionally require CREATE TABLE on that schema. Similarly, USE CATALOG only permits access to the catalog; it does not permit schema creation. Creating a schema in Corpdb would require the CREATE SCHEMA privilege on the catalog. Therefore, only the first statement is true.
NEW QUESTION # 18
You have an Azure Databricks workspace.
You have an Azure key vault named kv-secure that stores a secret named storageKey. The value of storageKey is managed and updated by the cloud security team at your company.
You need to enable a Databricks notebook named Notebook 1 to retrieve the value of storageKey securely at runtime. The solution must follow the principle of least privilege and always retrieve the latest value.
What should you do? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.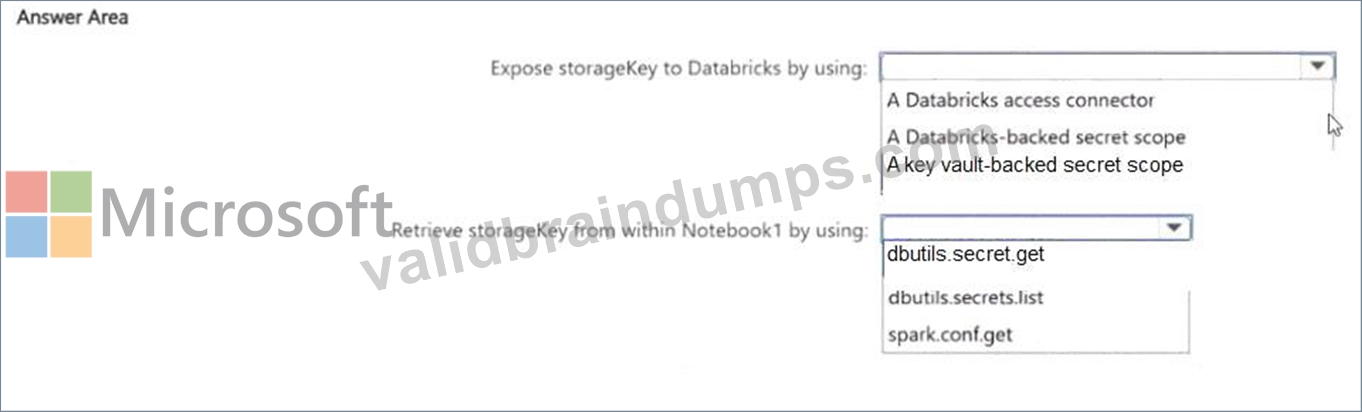
Answer:
Explanation: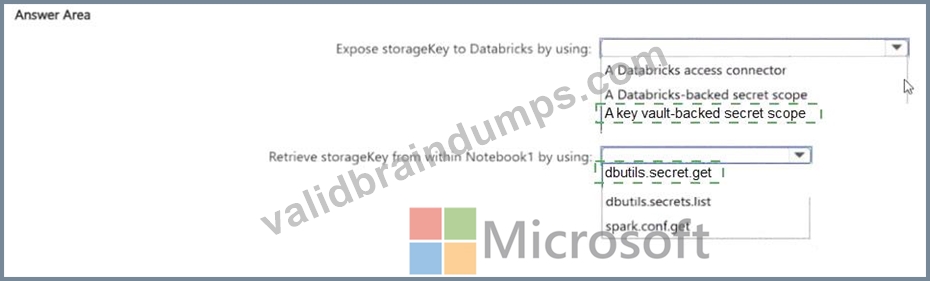
Explanation:
The solution is a Key Vault-backed secret scope combined with dbutils.secrets.get() in the notebook.
An Azure Key Vault-backed secret scope does not copy the secret value into Databricks. Every call to dbutils.
secrets.get() fetches the live current value directly from Key Vault at runtime. This means when the cloud security team rotates storageKey in Key Vault, the notebook automatically picks up the new value on its next run - no Databricks configuration changes needed. That satisfies 'always retrieve the latest value.' The principle of least privilege is upheld because only the secret scope has read access to Key Vault through a service principal or managed identity, and individual users never see the raw secret value - Databricks redacts it in logs automatically.
A Databricks-backed scope stores a copy of the secret inside Databricks, so it wouldn't automatically reflect Key Vault updates. Hardcoding or using environment variables would expose the secret in plain text.
Reference: https://learn.microsoft.com/en-us/azure/databricks/security/secrets/secret-scopes
NEW QUESTION # 19
You have an Azure Databricks workspace that contains an all-purpose cluster named Cluster1.
You discover that out of- memory (OOM) errors intermittently cause jobs running on Cluster1 to fail.
You need to identify the root cause of the failures by analyzing the runtime execution behavior. What should you do? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.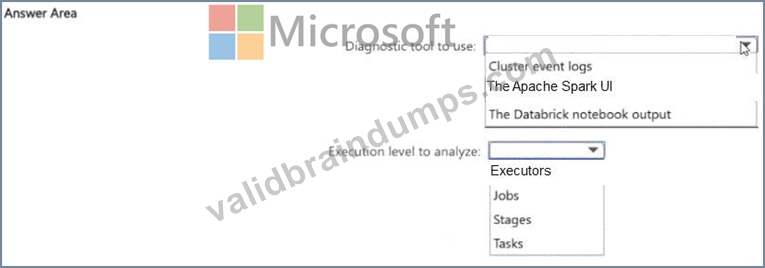
Answer:
Explanation: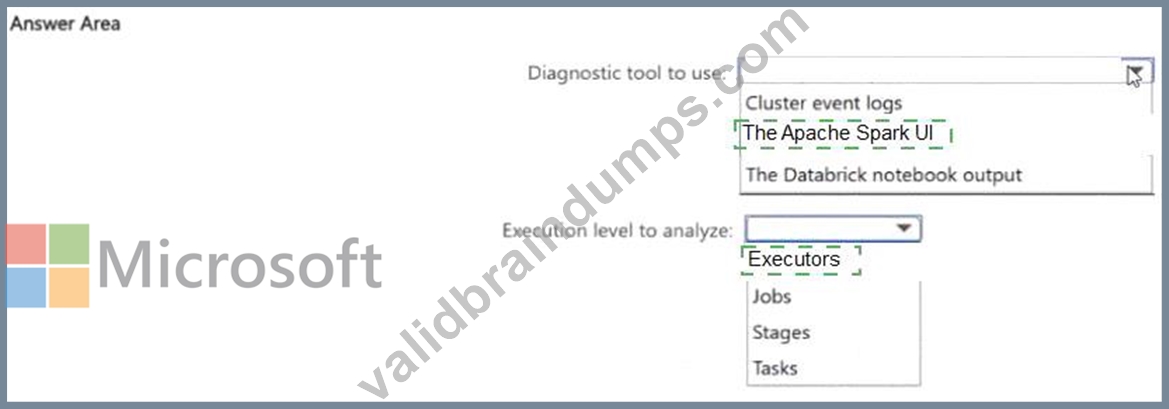
Explanation:
Diagnosing OOM errors requires analysing actual runtime execution behaviour. The Spark UI is the primary tool - it ' s accessible from the cluster detail page and captures rich per-stage and per-task metrics without any extra setup.
In the Executors tab, look at storage memory used, execution memory used, memory spill to disk, and GC time per executor. An executor showing high memory spill is a strong indicator that it ' s processing more data than it can hold in memory - often caused by data skew, where one partition is far larger than the others.
The Stages tab shows task distribution - if one task in a stage is processing 10x more data than its peers, that
' s data skew causing memory pressure on that specific executor. Ganglia (available on older runtimes) provides node-level OS metrics like heap usage over time, which can confirm whether memory pressure is sustained or spiky.
These built-in tools give a complete picture of the root cause before making any configuration changes.
Reference: https://learn.microsoft.com/en-us/azure/databricks/compute/monitor-cluster
NEW QUESTION # 20
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a Delta table named Orders You load the Orders table into an Apache Spark DataFrame named df.
You need to create a DataFrame that excludes rows where the order amount is null.
Solution: You run the following expression.
df-fillna(0, subset=['order_amount'])
Does this meet the goal?
Answer: B
Explanation:
The correct answer is B - No.
df.fillna(0, subset=['order_amount']) does not remove null rows. It replaces null values in order_amount with the integer 0, leaving those rows in the DataFrame with 0 as their order_amount value. The row count is unchanged - nulls are imputed, not dropped.
The requirement is to exclude rows where order_amount is null, meaning those rows should not appear in the result at all. fillna is a data imputation function - it fills gaps with default values, which is a different operation entirely from filtering. After fillna, a downstream process would see order_amount = 0 and might treat it as a valid zero-value order rather than recognising it was originally null.
The correct approach is df.dropna(subset=['order_amount']) or df.filter(df.order_amount.isNotNull()), both of which physically remove null rows from the resulting DataFrame.
Reference: https://learn.microsoft.com/en-us/azure/databricks/pyspark/basics
NEW QUESTION # 21
Note: This section contains one or more sets of questions with the same scenario and problem. Each question presents a unique solution to the problem. You must determine whether the solution meets the stated goals. More than one solution in the set might solve the problem. It is also possible that none of the solutions in the set solve the problem.
After you answer a question in this section, you will NOT be able to return. As a result, these questions do not appear on the Review Screen.
You have an Azure Databricks workspace named Workspace1 that contains a lakehouse and is enabled for Unity Catalog.
You have a connection to a Microsoft SQL Server database named DB1.
You need to expose the schemas and tables of DB1 to meet the following requirements:
- The schemas and tables can be queried in Databricks.
- The schemas and tables appear alongside other Unity Catalog objects.
- The data is NOT copied into Databricks-managed storage.
Solution: You create a Databricks access connector.
Does this meet the goal?
Answer: B
Explanation:
Correct:
* You create a foreign catalog in Catalog Explorer.
You should create a Foreign Catalog using Lakehouse Federation.
Data Copying: Lakehouse Federation queries data directly in the source SQL Server without moving or copying it.
Seamless Integration: The database schemas and tables appear right inside Unity Catalog alongside your other data objects.Real-time Access: It provides immediate access to live SQL Server data.
Incorrect:
* You create a Databricks access connector.
* You create a Lakeflow Connect pipeline and connect it to DB1.
Data Copying: Lakeflow Connect is an ingestion tool that physically replicates and copies data into Databricks-managed storage (Delta tables).
Storage Costs: It violates your requirement to keep data out of Databricks storage.
* You create a new native catalog in Unity Catalog.
Note:
To expose the external SQL Server database in Unity Catalog without copying the data, you must use Lakehouse Federation.
Here are the step-by-step actions you need to take:
1. Create a Connection
Create a securable object in Unity Catalog that specifies the path and credentials to access the SQL Server database.
Go to Catalog Explorer or use SQL.
Select External Data > Connections.
Create a connection using the SQL Server connection details (URL, host, port, and database credentials).
*-> 2. Create a Foreign Catalog
Create a specific type of catalog in Unity Catalog that mirrors the external database.
Use the CREATE FOREIGN CATALOG SQL command or the Catalog Explorer UI.
Link this foreign catalog directly to the connection you created in step 1.
3. Query the DataOnce the foreign catalog is created, Unity Catalog automatically syncs the schemas and tables from SQL Server.
Reference:
https://docs.databricks.com/gcp/en/database-objects/
NEW QUESTION # 22
......
All DP-750 practice questions you should know are written in them with three versions to choose from: the PDF, the Software and the APP online. At the same time, the experts who compiled the DP-750 learning engine are assiduously over so many years in this filed. I can say that our experts have became the authority in this career. And they are good at simplifying the content of the DP-750 Exam Braindumps to be understood by our customers all over the world.
DP-750 New Practice Questions: https://www.validbraindumps.com/DP-750-exam-prep.html