BONUS!!! Download part of VCEEngine DP-600 dumps for free: https://drive.google.com/open?id=1OGByvczMqDA_tTCqeIK4LWxsxg15ZY7W
You can access our web-based Implementing Analytics Solutions Using Microsoft Fabric (DP-600) practice exam from anywhere with an internet connection, and fit your studying into your busy schedule. No more traveling to a physical classroom, wasting time and money on gas or public transportation. With the web-based Microsoft DP-600 Practice Test, you can evaluate and enhance your progress. Customizable web-based mock exam creates a real Implementing Analytics Solutions Using Microsoft Fabric (DP-600) exam environment and works on all operating systems.
| Section | Objectives |
|---|---|
| Topic 1: Get data into Microsoft Fabric | - Data ingestion and integration
|
| Topic 2: Implement data engineering solutions | - Lakehouse architecture
|
| Topic 3: Manage and secure Microsoft Fabric | - Governance and administration
|
| Topic 4: Real-time analytics | - Streaming and event processing
|
| Topic 5: Implement analytics solutions | - Data warehousing and modeling
|
>> Practice DP-600 Test Online <<
In recruiting employees as IT engineers many companies look for evidence of all-round ability especially constantly studying ability more their education background. DP-600 dumps torrent can help you fight for Microsoft certification and achieve your dream in the shortest time. If you want to stand out from the crowd, purchasing a valid DP-600 Dumps Torrent will be a shortcut to success. It will be useful for you to avoid detours and save your money & time.
NEW QUESTION # 61
You have a Fabric eventhouse named Eventhousel that contains a table named Weatherdata. A sample of the data in Weatherdata is shown in the following table.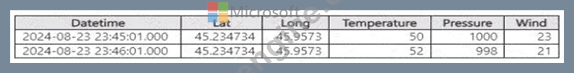
You plan to use a KQL queryset to manipulate the data in Eventhouse1. The result set must have the following columns.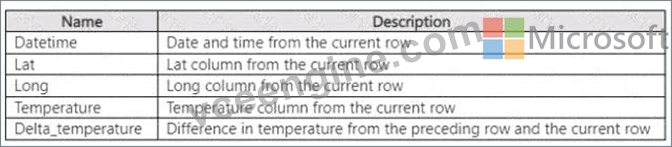
You need to build the query.
Which four KQL statements should you use in sequence? To answer, move the appropriate statements from the list of statements to the answer area and arrange them in the correct order.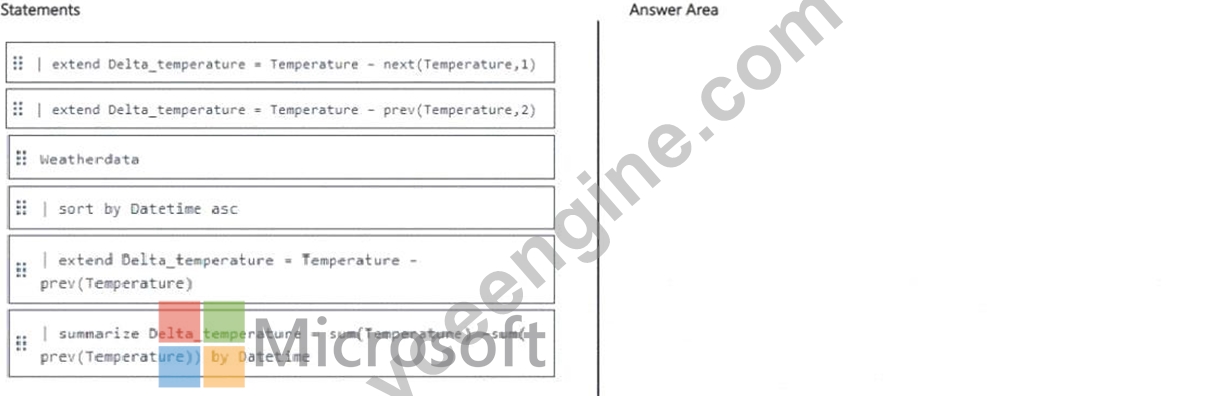
Answer:
Explanation: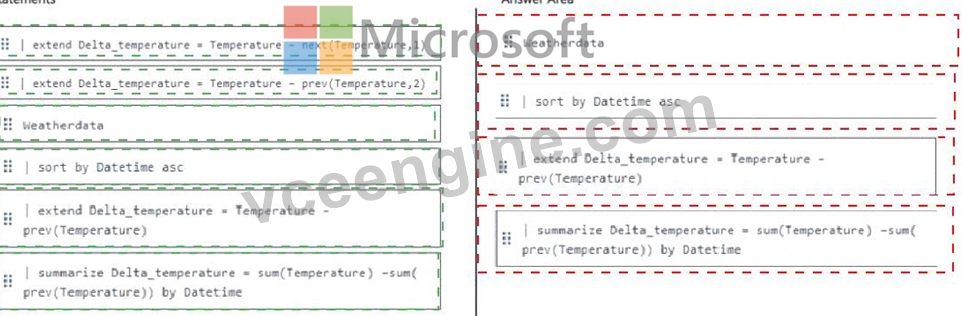
Explanation: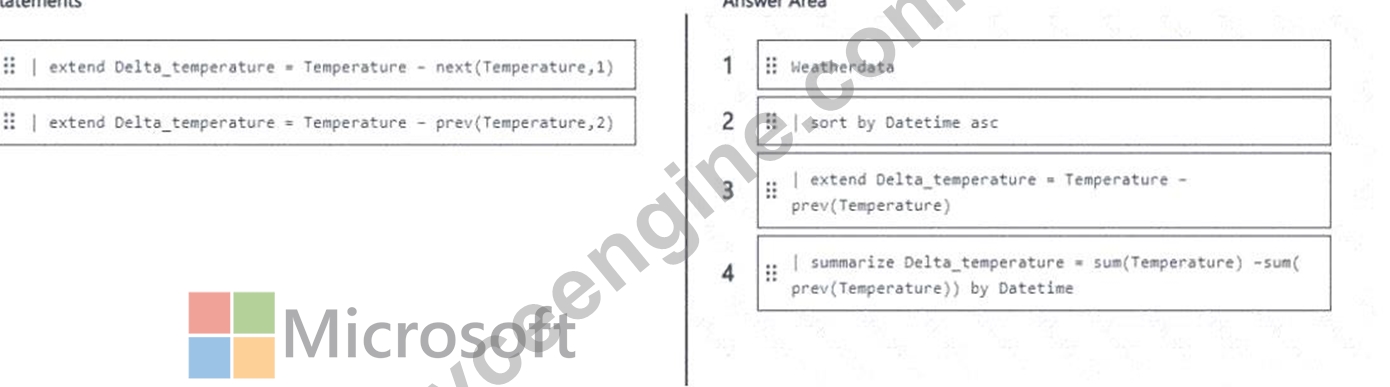
Comprehensive Detailed Explanation
Step 1: Understanding the requirement
We need a KQL query that:
Reads data from Weatherdata.
Orders by Datetime.
Calculates Delta_temperature as the difference between the current row and the preceding row.
Returns the final columns: Datetime, Lat, Long, Temperature, Delta_temperature.
Step 2: Evaluate the provided statements
Weatherdata # Starts the query with the source table.
| sort by Datetime asc # Ensures chronological order, required for prev() to work correctly.
| extend Delta_temperature = Temperature - prev(Temperature) # Computes difference between the current row and the previous row's temperature.
| project Datetime, Lat, Long, Temperature, Delta_temperature # Selects the required output columns.
Step 3: Incorrect choices (to avoid)
next(Temperature,1) # Would calculate the difference with the next row, not the previous.
prev(Temperature,2) # Would skip one row, giving the difference with two rows back, which is not needed.
summarize ... by Datetime # Aggregates the data; not required here since we just need row-level differences.
Step 4: Final Correct Sequence
Weatherdata
| sort by Datetime asc
| extend Delta_temperature = Temperature - prev(Temperature)
| project Datetime, Lat, Long, Temperature, Delta_temperature
References
prev() function in KQL
extend operator in KQL
project operator in KQL
NEW QUESTION # 62
You have a Fabric warehouse that contains a table named Sales.Orders. Sales.Orders contains the following columns.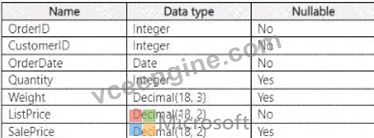
You need to write a T-SQL query that will return the following columns.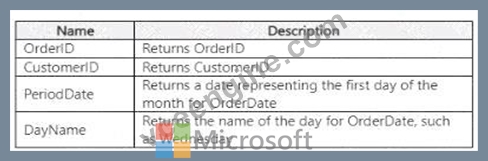
How should you complete the code? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.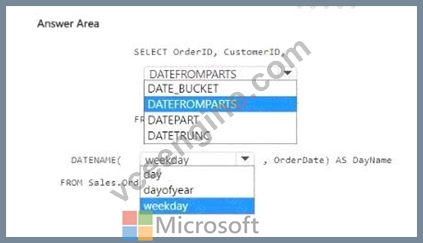
Answer:
Explanation: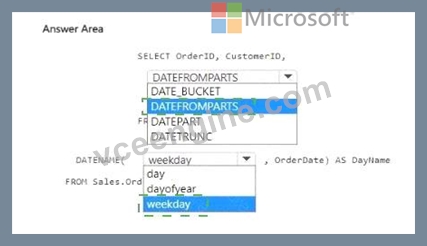
Explanation: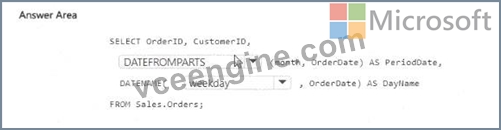
For the PeriodDate that returns the first day of the month for OrderDate, you should use DATEFROMPARTS as it allows you to construct a date from its individual components (year, month, day).
For the DayName that returns the name of the day for OrderDate, you should use DATENAME with the weekday date part to get the full name of the weekday.
The complete SQL query should look like this:
SELECT OrderID, CustomerID,
DATEFROMPARTS(YEAR(OrderDate), MONTH(OrderDate), 1) AS PeriodDate,
DATENAME(weekday, OrderDate) AS DayName
FROM Sales.Orders
Select DATEFROMPARTS for the PeriodDate and weekday for the DayName in the answer area.
NEW QUESTION # 63
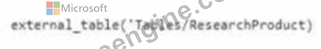
Which syntax should you use in a notebook to access the Research division data for Productlinel?



Answer: D
NEW QUESTION # 64
You have a Fabric tenant that contains a semantic model named Model1.
Modell contains a table named TemperatureUnit. TempetatuieUnit contains a column named Unit. Unit contains manually added options for Celsius and Fahrenheit.
Model1 contains the following measures: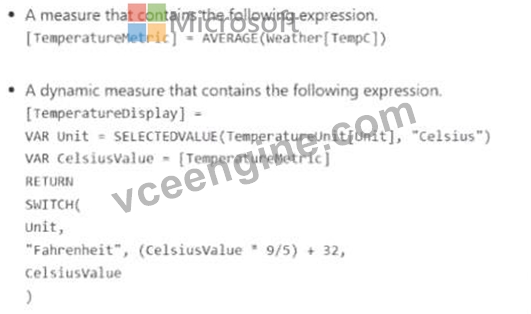
You need to add a dynamic format string to the [TemperatureDisplay] measure to enable users to switch display values between metric (Celsius) and imperial (Fahrenheit).
How should you complete the DAX expression? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.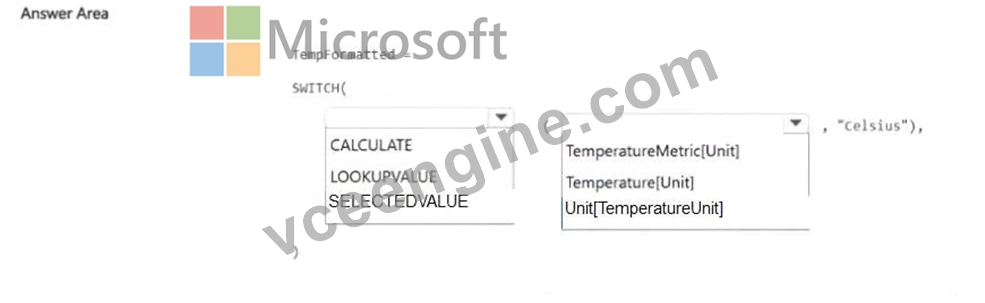
Answer:
Explanation: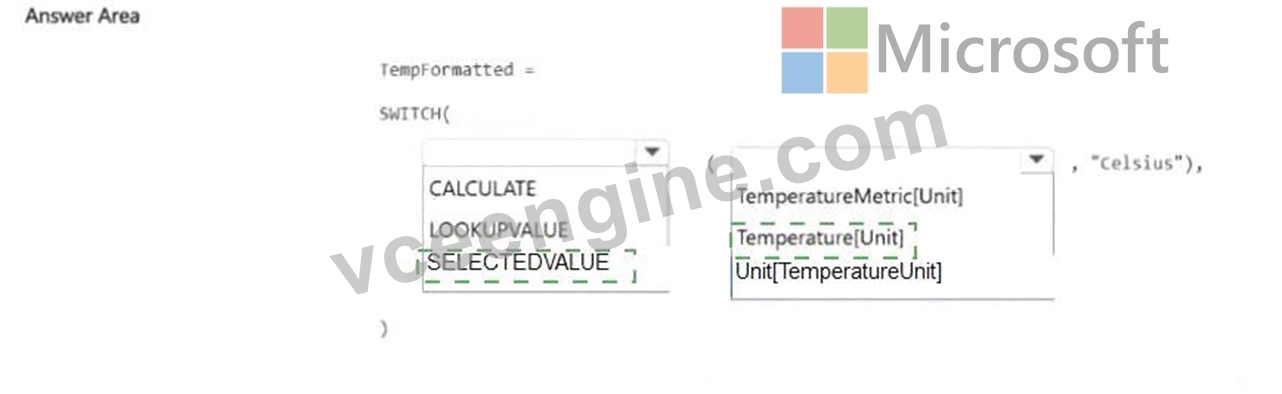
Explanation: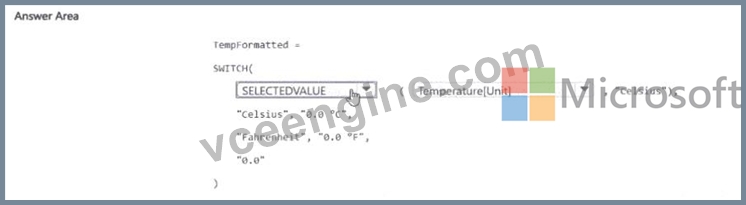
NEW QUESTION # 65
Case Study 2 - Litware, Inc
Overview
Litware, Inc. is a manufacturing company that has offices throughout North America. The analytics team at Litware contains data engineers, analytics engineers, data analysts, and data scientists.
Existing Environment
Fabric Environment
Litware has been using a Microsoft Power BI tenant for three years. Litware has NOT enabled any Fabric capacities and features.
Available Data
Litware has data that must be analyzed as shown in the following table.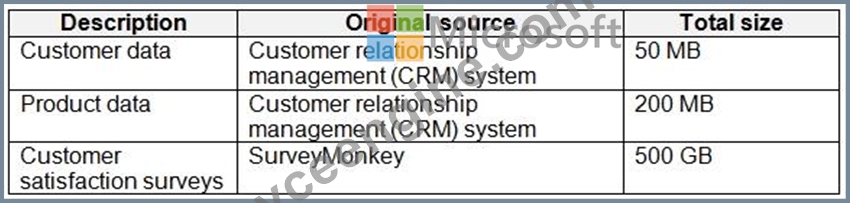
The Product data contains a single table and the following columns.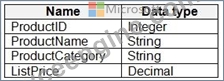
The customer satisfaction data contains the following tables:
- Survey
- Question
- Response
For each survey submitted, the following occurs:
- One row is added to the Survey table.
- One row is added to the Response table for each question in the survey.
- The Question table contains the text of each survey question. The third question in each survey response is an overall satisfaction score. Customers can submit a survey after each purchase.
User Problems
The analytics team has large volumes of data, some of which is semi-structured. The team wants to use Fabric to create a new data store.
Product data is often classified into three pricing groups: high, medium, and low. This logic is implemented in several databases and semantic models, but the logic does NOT always match across implementations.
Requirements
Planned Changes
Litware plans to enable Fabric features in the existing tenant. The analytics team will create a new data store as a proof of concept (PoC). The remaining Liware users will only get access to the Fabric features once the PoC is complete. The PoC will be completed by using a Fabric trial capacity The following three workspaces will be created:
- AnalyticsPOC: Will contain the data store, semantic models, reports pipelines, dataflow, and notebooks used to populate the data store
- DataEngPOC: Will contain all the pipelines, dataflows, and notebooks used to populate OneLake
- DataSciPOC: Will contain all the notebooks and reports created by the data scientists The following will be created in the AnalyticsPOC workspace:
- A data store (type to be decided)
- A custom semantic model
- A default semantic model
Interactive reports
The data engineers will create data pipelines to load data to OneLake either hourly or daily depending on the data source. The analytics engineers will create processes to ingest, transform, and load the data to the data store in the AnalyticsPOC workspace daily. Whenever possible, the data engineers will use low-code tools for data ingestion. The choice of which data cleansing and transformation tools to use will be at the data engineers' discretion.
All the semantic models and reports in the Analytics POC workspace will use the data store as the sole data source.
Technical Requirements
The data store must support the following:
- Read access by using T-SQL or Python
- Semi-structured and unstructured data
- Row-level security (RLS) for users executing T-SQL queries
Files loaded by the data engineers to OneLake will be stored in the Parquet format and will meet Delta Lake specifications.
Data will be loaded without transformation in one area of the AnalyticsPOC data store. The data will then be cleansed, merged, and transformed into a dimensional model The data load process must ensure that the raw and cleansed data is updated completely before populating the dimensional model The dimensional model must contain a date dimension. There is no existing data source for the date dimension. The Litware fiscal year matches the calendar year. The date dimension must always contain dates from 2010 through the end of the current year.
The product pricing group logic must be maintained by the analytics engineers in a single location. The pricing group data must be made available in the data store for T-SOL. queries and in the default semantic model. The following logic must be used:
- List prices that are less than or equal to 50 are in the low pricing group.
- List prices that are greater than 50 and less than or equal to 1,000 are in the medium pricing group.
- List prices that are greater than 1,000 are in the high pricing group.
Security Requirements
Only Fabric administrators and the analytics team must be able to see the Fabric items created as part of the PoC.
Litware identifies the following security requirements for the Fabric items in the AnalyticsPOC workspace:
- Fabric administrators will be the workspace administrators.
- The data engineers must be able to read from and write to the data store. No access must be granted to datasets or reports.
- The analytics engineers must be able to read from, write to, and create schemas in the data store. They also must be able to create and share semantic models with the data analysts and view and modify all reports in the workspace.
- The data scientists must be able to read from the data store, but not write to it. They will access the data by using a Spark notebook
- The data analysts must have read access to only the dimensional model objects in the data store. They also must have access to create Power BI reports by using the semantic models created by the analytics engineers.
- The date dimension must be available to all users of the data store.
- The principle of least privilege must be followed.
Both the default and custom semantic models must include only tables or views from the dimensional model in the data store. Litware already has the following Microsoft Entra security groups:
FabricAdmins: Fabric administrators
- AnalyticsTeam: All the members of the analytics team
- DataAnalysts: The data analysts on the analytics team
- DataScientists: The data scientists on the analytics team
- DataEngineers: The data engineers on the analytics team
- AnalyticsEngineers: The analytics engineers on the analytics team
Report Requirements
The data analysts must create a customer satisfaction report that meets the following requirements:
- Enables a user to select a product to filter customer survey responses to only those who have purchased that product.
- Displays the average overall satisfaction score of all the surveys submitted during the last 12 months up to a selected dat.
- Shows data as soon as the data is updated in the data store.
- Ensures that the report and the semantic model only contain data from the current and previous year.
- Ensures that the report respects any table-level security specified in the source data store.
- Minimizes the execution time of report queries.
What should you recommend using to ingest the customer data into the data store in the AnalyticsPOC workspace?
Answer: B
Explanation:
Even though the text reads "Data will be loaded without transformation in one area of the AnalyticsPOC data store": in general, dataflows are used when data transformations are involved after ingestion. As suggested by user BHARAT, the Copy Activity should be the optimal solution.
NEW QUESTION # 66
......
One of the great features of our DP-600 training material is our DP-600 pdf questions. DP-600 exam questions allow you to prepare for the real DP-600 exam and will help you with the self-assessment. You can easily pass the Microsoft DP-600 exam by using DP-600 dumps pdf. Moreover, you will get all the updated DP-600 Questions with verified answers. If you want to prepare yourself for the real Implementing Analytics Solutions Using Microsoft Fabric exam, then it is one of the most important ways to improve your DP-600 preparation level. We provide 100% money back guarantee on all DP-600 braindumps products.
DP-600 Authorized Exam Dumps: https://www.vceengine.com/DP-600-vce-test-engine.html
DOWNLOAD the newest VCEEngine DP-600 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1OGByvczMqDA_tTCqeIK4LWxsxg15ZY7W