弊社PassTestのDP-800練習資料は、さまざまな学位の受験者に適しています。これらの受験者は、この分野の知識のレベルに関係ありません。これらのDP-800トレーニング資料は当社にとって名誉あるものであり、お客様の目標達成を支援するための最大限の特権として扱っています。私たちの知る限り、DP-800試験準備は何百万人もの受験者に夢を追いかけ、より効率的に学習するように動機付けました。 DP-800の練習資料は、あなたを失望させません。
| Certification Vendor: | Microsoft |
|---|---|
| Exam Name: | Developing AI-Enabled Database Solutions |
| Exam Number: | DP-800 |
| Available Languages: | English, Korean, Portuguese (Brazil), French, German, Chinese (Simplified), Japanese, Spanish |
| Exam Duration: | 100 minutes |
| Exam Format: | Multiple choice, Drag and drop, Multiple select, Case studies, Active screen |
| Passing Score: | 700 (on a scale of 1-1000) |
| Real Exam Qty: | 40-60 |
| Exam Price: | $165 USD |
| Certificate Validity Period: | 1 year (renewable annually via free online assessment) |
| Recommended Training: | Microsoft Learn DP-800 Learning Path |
| Exam Registration: | Pearson VUE Registration |
| Sample Questions: | Microsoft DP-800 Sample Questions |
| Exam Way: | Online proctored or onsite at Pearson VUE test centers |
| Pre Condition: | No mandatory prerequisites; recommended experience: T-SQL development, SQL Server/Azure SQL, CI/CD practices, basic AI concepts |
| Official Syllabus URL: | https://learn.microsoft.com/en-us/credentials/certifications/resources/study-guides/dp-800 |
試験に合格し、マネージャーから認定を取得する必要がある場合は、DP-800の元の質問をお勧めします。 当社の製品は、最初の試験で試験をクリアするのに役立ちます。 最高品質のDP-800元の質問と競争力のある価格を提供することをお約束します。 優れたサービスを提供する100%パス製品を提供しています。 1年間の学習支援サービスと、Microsoft DP-800試験問題の1年間の無料更新ダウンロードを提供しています。 試験に不合格の場合は、問題集の交換と全額返金をサポートします。
| トピック | 出題範囲 |
|---|---|
| トピック 1 |
|
| トピック 2 |
|
| トピック 3 |
|
質問 # 62
You need to enable similarity search to provide the analysts with the ability to retrieve the most relevant health summary reports. The solution must minimize latency.
What should you include in the solution?
正解:C
解説:
The correct answer is D because the requirement is to enable similarity search over embedding vectors and to minimize latency . Microsoft documents that CREATE VECTOR INDEX is specifically used to create an index on vector data for approximate nearest neighbor (ANN) search , which is designed to accelerate vector similarity queries compared to exact k-nearest-neighbor scans.
This matches the scenario exactly. The VehicleHealthSummary table already includes an Embeddings (vector (1536)) column. In Microsoft SQL platforms, embeddings are stored in vector columns and queried for semantic similarity. To improve performance and reduce response time, Microsoft recommends a vector index , not a regular B-tree nonclustered index and not a full-text index. A vector index is purpose-built for finding the most similar vectors efficiently.
The other options are not appropriate:
* A would require manual comparison logic and would increase latency rather than minimize it.
* B is incorrect because a standard nonclustered index is not the index type used for vector similarity operations.
* C is incorrect because full-text indexes are for textual token-based search, not numeric vector embeddings.
Microsoft's current documentation is explicit that vector indexes support approximate nearest neighbor search , and that the optimizer can use the ANN index automatically for vector queries. That is the exam- aligned design choice when the goal is fast retrieval of the most relevant health summary reports from an embeddings column.
Topic 2, Fabrikam Case
- To display the first question in this case study, click the Next button. Use the buttons in the left pane to explore the content of the case study before you answer the questions. Clicking these buttons displays information such as business requirements, existing environment and problem statements. If the case study has an All Information tab, note that the information displayed is identical to the information displayed on the subsequent tabs. When you are ready to answer a question, click the Question button to return to the question.
Existing Environment - Azure Environment - Fabrikam has a single Azure subscription in the East US 2 Azure region. The subscription contains an Azure SQL database named DB1. DB1 contains the following tables: * Patients * Employees * Procedures * Transactions * UsefulPrompts * ProcedureDocuments You store a column master key as a secret in Azure Key Vault. You have an on-premises application named TransactionProcessing that uses a hard-coded username and password in a connection string to access DB1.
Problem Statements - Users report that after executing a long-running stored procedure named sp_UpdateProcedureForPatient, updates to the underlying data are sometimes inconsistent. Requirements - Planned Changes - Fabrikam plans to manage all changes to Azure SQL Database objects by using source control in GitHub. Every pull request submitted to production will be validated before it can be merged.
Deployments must use the Release configuration. Security Requirements - Fabrikam identifies the following security requirements: * The TransactionProcessing application must use a passwordless connection to DB1. * The Employees table contains two columns named TaxID and Salary that must be encrypted at rest. * Auditors must have a tamper-evident history of transactions with cryptographic proof of changes to the employee data. Database Performance Requirements Records accessed by using sp_UpdateProcedureForPatient must NOT be changed by other transactions while the stored procedure runs.
AI Search, Embeddings, and Vector Indexing Fabrikam identifies the following AI-related requirements: * Queries to the ProcedureDocuments table must use Reciprocal Rank Fusion (RRF). * Users must be able to query the data in DB1 by using prompts in Copilot in Microsoft Fabric. * The UsefulPrompts table will store prompts that doctors can use to help diagnose patient illness by connecting to an Azure OpenAI endpoint.
Development Requirements - Fabrikam identifies the following development requirements: * Provide the functionality to retrieve all the transactions of a given patient between two dates, showing a running total. * Expose a Data API builder (DAB) configuration file to enable Azure services to perform the following operations over a REST API: o Read data from the procedures table without authentication. o Read and insert data into the Transactions table once authenticated. o Execute the sp_UpdateProcedurePatient stored procedure. * Provide the functionality to retrieve a list of the names of patients who underwent medical procedures during the last 30 days. * Information for each medical procedure will be stored in a table. The table will be used with a large language model (LLM) for user querying and will have the following structure.
DAB
You create a DAB configuration file that meets the development requirements for DB1 and includes the following entities.
質問 # 63
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear in the review screen.
You have a SQL database in Microsoft Fabric that contains a table named dbo.Orders.
dbo.Orders has a clustered index, contains three years of data, and is partitioned by a column named OrderDate by month.
You need to remove all the rows for the oldest month. The solution must minimize the impact on other queries that access the data in dbo.Orders.
Solution: Run the following Transact-SQL statement.
DELETE FROM dbo.Orders
WHERE OrderDate < DATEADD(month, -36, SYSUTCDATETIME());
Does this meet the goal?
正解:B
解説:
Correct:
* Identify the partition number for the oldest month, and then run the following Transact-SQL statement.
TRUNCATE TABLE dbo.Orders
WITH (PARTITIONS (partition number));
The best Transact-SQL statement to remove all rows for the oldest month while minimizing the impact on other queries is TRUNCATE TABLE with a WITH (PARTITIONS (...)) clause.
Why TRUNCATE TABLE ... WITH (PARTITIONS (...)) is Best
Efficiency: TRUNCATE TABLE is a Data Definition Language (DDL) operation that removes data by deallocating the data pages, which is a metadata operation and is very fast, regardless of the amount of data in the partition.
Minimal Logging: It uses less transaction log space compared to a DELETE statement, which logs each row deletion individually.
Low Impact on Concurrency: It performs a quick, partition-specific operation. A row-by-row DELETE would be a long-running transaction and could cause locking and blocking issues for other queries accessing the table.
Data Integrity: Because the table has a clustered index and is partitioned by the same column (aligned indexes), the TRUNCATE PARTITION operation is a fast, partition-level maintenance operation that targets only that specific data subset.
Incorrect:
* : Identify the partition scheme for the oldest month, and then run the following Transact-SQL statement.
ALTER TABLE dbo.Orders
DROP PARTITION SCHEME (partition_scheme_name);
The DROP PARTITION SCHEME statement removes the partition scheme object from the database but does not remove the data itself or free up the space, and it requires all tables to be moved off the scheme first, which is a complex operation. This does not meet the goal of removing the data efficiently.
* Run the following Transact-SQL statement.
DELETE FROM dbo.Orders
WHERE OrderDate < DATEADD(month, -36, SYSUTCDATETIME());
A standard DELETE statement, even with a WHERE clause that uses the partition column, can be a time-consuming, logged operation that causes locking and blocking on the main table, negatively impacting performance.
Reference:
https://stackoverflow.com/questions/63632963/truncate-partition-vs-drop-partition-performace- wise-which-one-is-efficient-an
質問 # 64
You need to generate embeddings to resolve the issues identified by the analysts. Which column should you use?
正解:A
解説:
The correct column to use for generating embeddings is incidentDescrlption because embeddings are intended to represent the semantic meaning of rich textual content , not simple categorical, numeric, or location-only values. Microsoft's DP-800 study guide explicitly includes skills such as identifying which columns to include in embeddings , generating embeddings , and implementing semantic vector search for scenarios where users need to find similar records based on meaning rather than exact matches.
In this scenario, analysts report that it is difficult to find similar incidents based on details such as weather, traffic conditions, and location . Those are descriptive context elements that are typically captured in a free- text incident description field. An embedding generated from incidentDescrlption can encode the semantic relationships among these narrative details, making it suitable for similarity search , semantic search , and RAG retrieval . Microsoft documentation on vectors and embeddings explains that embeddings are generated from text data and then stored for vector search to find semantically related items.
The other options are weaker choices:
* vehicleLocation is too narrow and usually better handled with geospatial filtering , not embeddings.
* incidentType is likely categorical and too low in semantic richness.
* SeverityScore is numeric and not appropriate as the primary source for semantic embeddings.
Microsoft also notes that when multiple useful attributes exist, you can either embed each text column separately or concatenate relevant text fields into one textual representation before generating the embedding.
But among the options given, the best and most exam-aligned answer is the textual narrative column :
incidentDescrlption .
質問 # 65
Your company has an ecommerce catalog in a Microsoft SQL Server 202b database named SalesDB SalesDB contains a table named products, products contains the following columns:
* product.id (int)
* product_name (nvarchar(200))
* description (nvarchar(max))
* category (nvarchar(50))
* brand (nvarchar(W))
* price (decimal)
* sku (nvarchar(40))
The description fields ate updated dairy by a content pipeline, and price can change multiple times per day.
You want customers to be able to submit natural language queries and apply structured filters for brand and price. You plan to store embeddings in a new VECTOR(1536) column and use VECTOR_SEARCH(...
METRIC=' cosine ' ...).
For each of the following statements, select Yes if the statement is true. Otherwise, select No.
NOTE: Each correct selection is worth one point.
正解:
解説: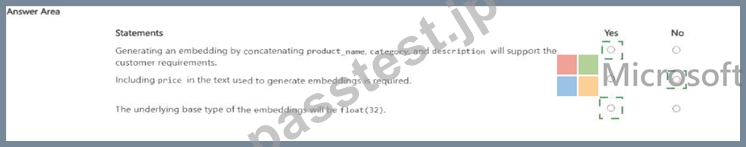
Explanation:
The first statement is Yes. Embeddings are used to represent the semantic meaning of content, and vector search is for conceptually similar matches over that content. Here, the semantically meaningful fields are product_name, category, and description. Using those together supports natural-language search, while brand and price can be handled as structured filters outside the embedding itself. This is an inference from Microsoft's guidance that vector search works over embeddings representing content meaning, while filters remain part of the nonvector query pipeline.
The second statement is No. price changes multiple times per day and is a structured numeric attribute, not stable semantic content. Since the requirement already says customers can apply structured filters for brand and price, price does not need to be embedded into the text. Embedding volatile numeric values would also make embeddings stale faster without improving the semantic-search objective. This is again an inference grounded in Microsoft's distinction between vector similarity over content and filtering/sorting over nonvector fields.
The third statement is Yes. In SQL Server's vector type, the default underlying base type is float32 unless float16 is specified explicitly.
質問 # 66
Case Study 1 - Contoso
Existing Environment
Azure Environment
Contoso has an Azure subscription in North Europe that contains the corporate infrastructure.
The current infrastructure contains a Microsoft SQL Server 2017 database. The database contains the following tables.
The FeedbackJsoncolumn has a full-text index and stores JSON documents in the following format.
The support staff at Contoso never has the UNMASKpermission.
Problem Statements
Contoso is deploying a new Azure SQL database that will become the authoritative data store for the following:
* AI workloads
* Vector search
* Modernized API access
* Retrieval Augmented Generation (RAG) pipelines
Sometimes the ingestion pipeline fails due to malformed JSON and duplicate payloads.
The engineers at Contoso report that the following dashboard query runs slowly.
You review the execution plan and discover that the plan shows a clustered index scan.
VehicleIncidentReportsoften contains details about the weather, traffic conditions, and location. Analysts report that it is difficult to find similar incidents based on these details.
Requirements
Planned Changes
Contoso wants to modernize Fleet Intelligence Platform to support AI-powered semantic search over incident reports.
Security Requirements
Contoso identifies the following security requirements:
* Restrict the support staff from viewing Personally Identifiable Information (PII) data, which is full email addresses and phone numbers.
* Enforce row-level filtering so that analysts see only incidents for the fleets to which they are assigned. The analysts can be assigned to multiple fleets.
Database Performance and Requirements
Contoso identifies the following telemetry requirements:
* Telemetry data must be stored in a partitioned table.
* Telemetry data must provide predictable performance for ingestion and retention operations.
* latitude, longitude, and accuracyJSON properties must be filtered by using an index seek.
Contoso identifies the following maintenance data requirements:
* Ensure that any changes to a row in the MaintenanceEventstable updates the corresponding value in the LastModifiedUtccolumn to the time of the change.
* Avoid recursive updates.
AI Search, Embeddings, and Vector Indexing
Contoso plans to implement semantic search over incident data to meet the following requirements:
* Embeddings must be stored in dedicated Azure SQL Database tables.
* Embeddings must be generated from rich natural language fields.
* Chunking must preserve semantic coherence.
* Hybrid search must combine the following:
- Vector similarity
- Keyword filtering or boosting
Development Requirements
The development team at Contoso will use Microsoft Visual Studio Code and GitHub Copilot and will retrieve live metadata from the databases.
Contoso identifies the following requirements for querying data in the FeedbackJsoncolumn of the CustomerFeedbacktable:
* Extract the customer feedback text from the JSON document.
* Filter rows where the JSON text contains a keyword.
* Calculate a fuzzy similarity score between the feedback text and a known issue description.
* Order the results by similarity score, with the highest score first.
You need to enable similarity search to provide the analysts with the ability to retrieve the most relevant health summary reports. The solution must minimize latency. What should you include in the solution?
正解:B
解説:
Scenario: There is a VehicleHealthSummary table.
To enable similarity search on your health summary data while minimizing latency, you should use the native VECTOR data type and a DiskANN vector index, which are now available in public preview for Azure SQL Database.
Solution Implementation
1. Define the Vector Column: Ensure your embeddings are stored using the native VECTOR(1536) type rather than NVARCHAR or VARBINARY. This format is optimized for high- dimensional data and mathematical operations.
ALTER TABLE HealthSummaries
ADD SummaryVector VECTOR(1536);
2. Create the Vector Index: Use the CREATE VECTOR INDEX statement. In Azure SQL, this uses the DiskANN algorithm, which is specifically designed to provide high-speed Approximate Nearest Neighbor (ANN) searches for large datasets.
CREATE VECTOR INDEX idx_health_summary_vector
ON HealthSummaries (SummaryVector)
WITH ( METRIC = 'COSINE', TYPE = 'DISKANN' );
3. Perform the Similarity Search: To leverage the index for low-latency retrieval, use the VECTOR_SEARCH function rather than VECTOR_DISTANCE. While VECTOR_DISTANCE calculates exact values (resulting in a full table scan), VECTOR_SEARCH utilizes the DiskANN index to find the most relevant reports quickly.
SELECT TOP(10) *
FROM HealthSummaries
ORDER BY VECTOR_DISTANCE('cosine', SummaryVector, @query_vector);
Reference:
https://learn.microsoft.com/en-us/samples/azure-samples/azure-sql-db-openai/azure-sql-db- openai/
質問 # 67
......
DP-800模擬対策問題: https://www.passtest.jp/Microsoft/DP-800-shiken.html