Our DP-750 question materials are designed to help ambitious people. The nature of human being is pursuing wealth and happiness. Perhaps you still cannot make specific decisions. It doesn’t matter. We have the free trials of the DP-750 study materials for you. The initiative is in your own hands. Our DP-750 Exam Questions are very outstanding. People who have bought our products praise our company highly. In addition, we have strong research competence. So you can always study the newest version of the DP-750 exam questions.
| Section | Weight | Objectives |
|---|---|---|
| Set up and configure an Azure Databricks environment | 15-20% | - Create and configure Azure Databricks workspaces
|
| Secure and govern Unity Catalog objects | 15-20% | - Implement governance and security
|
| Prepare and process data | 30-35% | - Ingest and transform data
|
| Deploy and maintain data pipelines and workloads | 30-35% | - Manage production workloads
|
We are so popular for that we have a detailed and perfect customer service system. Firstly, only 5 to 10 minutes after the customer's online payment of DP-750 actual exam is successful, you can receive an email from the customer service and immediately start learning. We also have dedicated staff to check and update DP-750 Exam Questions every day, so you can get the latest information of DP-750 exam materials whenever you buy it. Secondly, we provide 24-hour round-the-clock service to customers. We can solve any problems about DP-750 study materials for you whenever and wherever you need it.
NEW QUESTION # 45
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a Delta table named Orders.
You load the Orders table into an Apache Spark DataFrame named df.
You need to create a DataFrame that excludes rows where the order amount is null.
Solution: You run the following expression.
df.dropna(subset=["order_amount"])
Does this meet the goal?
Answer: A
Explanation:
The correct answer is A - Yes.
df.dropna(subset=['order_amount']) is the idiomatic PySpark way to remove rows where a specific column contains a null. It inspects only the columns listed in subset and drops any row where those columns are null.
The resulting DataFrame contains only rows where order_amount is not null - exactly what the requirement asks for.
The subset parameter is important: without it, dropna() would drop rows where ANY column is null, which could incorrectly exclude rows that have nulls in other columns but a valid order_amount. By specifying subset=['order_amount'], the filter is applied precisely and only to the column in question.
This method is semantically equivalent to df.filter(df.order_amount.isNotNull()) and to the SQL clause WHERE order_amount IS NOT NULL. Both are correct - dropna with a subset is arguably the more readable Pythonic approach.
Reference: https://learn.microsoft.com/en-us/azure/databricks/pyspark/basics
NEW QUESTION # 46
You have an Azure Databricks workspace that is enabled for Unity Catalog.
You need to profile a table to meet the following requirements:
* The count of null values per column must be evaluated repeatedly as new records are added to the table.
* Changes in the count of null values must be observable over the progression of the dataset.
Which type of profile should you create?
Answer: A
Explanation:
A time series profile repeatedly calculates data-quality metrics as a table changes and preserves those measurements over time. This makes it possible to observe whether the number of null values in each column is increasing, decreasing, or remaining stable as new records are added. A snapshot profile evaluates the table at a particular point in time and is therefore insufficient when the requirement is to analyze metric progression across multiple updates. Inference is associated with deriving information such as a schema or statistical characteristics; it is not the profile type used to maintain a historical sequence of monitoring measurements.
Because the question requires repeated evaluation and the ability to observe changes throughout the dataset's progression, the time series profile satisfies both requirements.
NEW QUESTION # 47
Hotspot Question
You have an Azure Databricks workspace.
You need to ingest streaming data from Azure Event Hubs by using Apache Spark Structured Streaming. The solution must authenticate to Event Hubs and read the event payload.
How should you complete the PySpark code segment? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.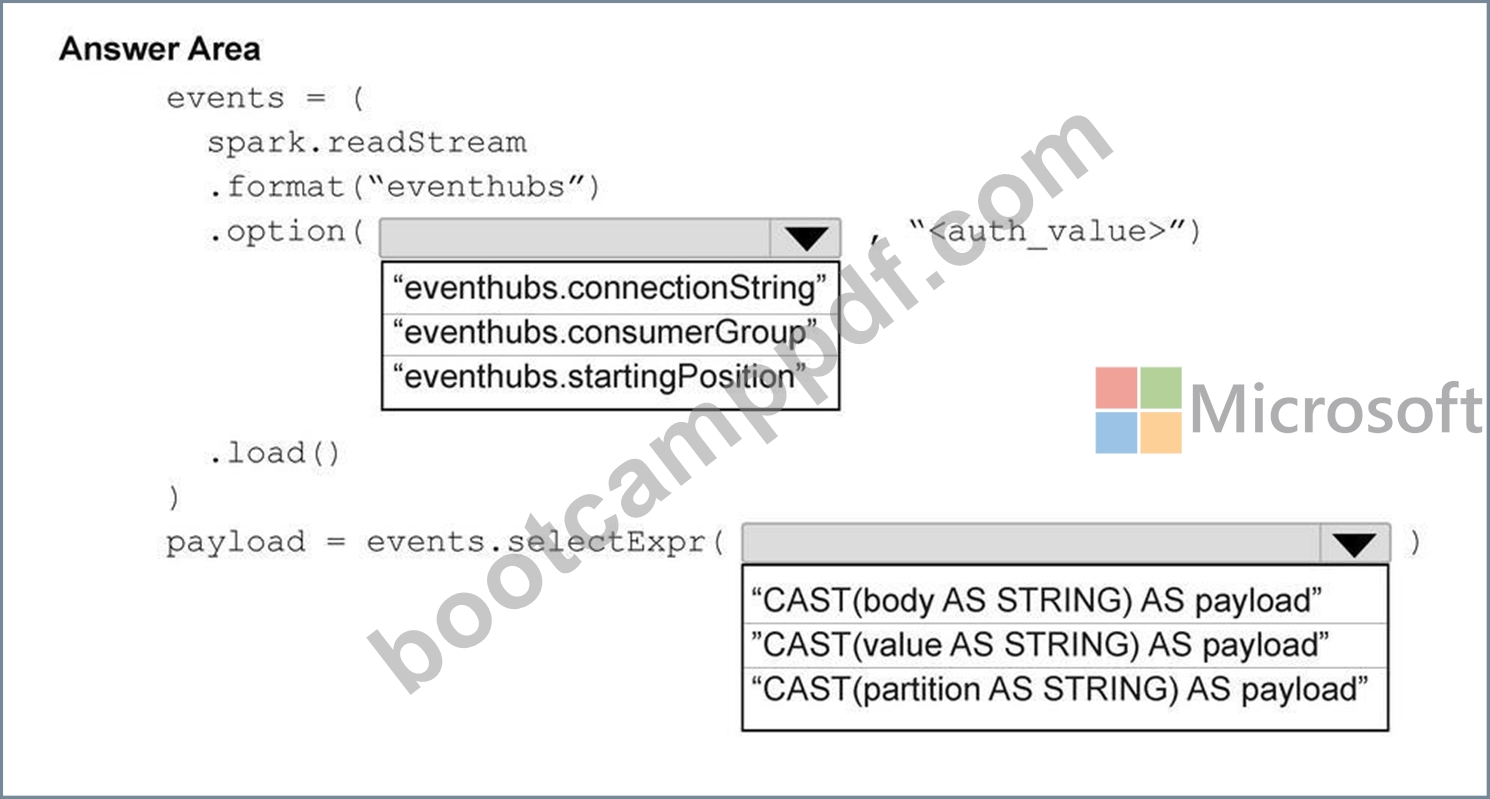
Answer:
Explanation: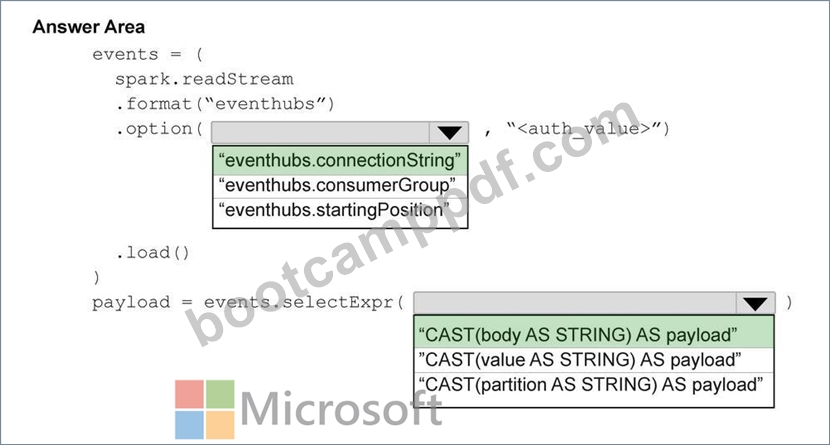
NEW QUESTION # 48
You have an Azure Databricks account that contains a single workspace named Workspace1. Workspace1 is enabled for Unity Catalog.
You discover that data access events for Unity Catalog tables fail to appear in the logs.
You need to ensure that all the data access events are captured centrally for auditing purposes. The log data must be available for analysis as quickly as possible.
What should you do? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.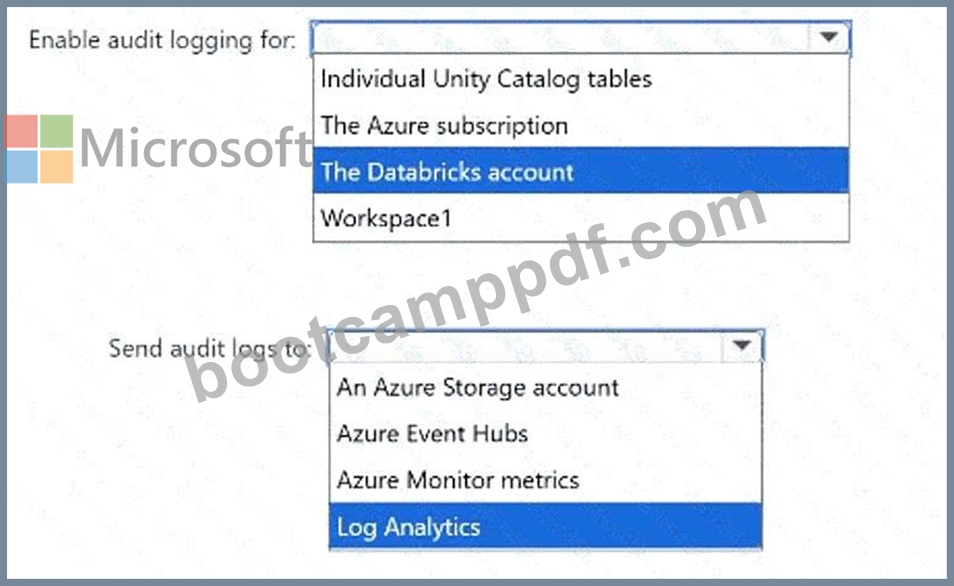
Answer:
Explanation: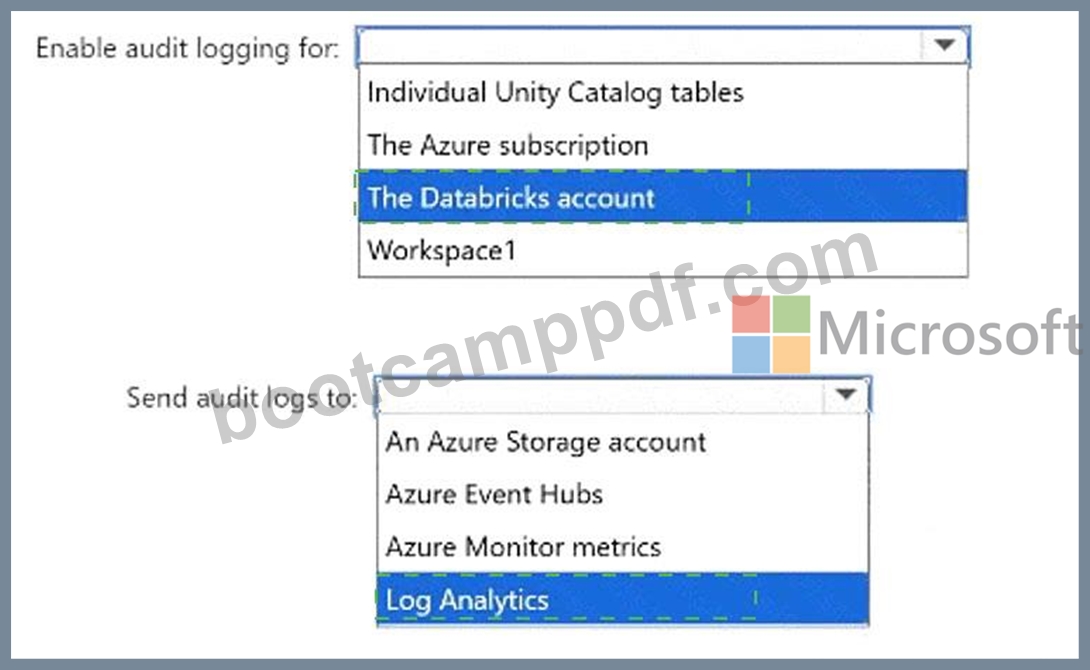
Explanation:
Enable audit logging for: The Databricks account
Send audit logs to: Log Analytics
Enabling audit logging at the Databricks account level provides centralized coverage of account and workspace activities, including Unity Catalog data-access events. Enabling logging only for Workspace1 would provide a narrower configuration and would not offer the same centralized account-level auditing model. Individual Unity Catalog tables and the Azure subscription are not the appropriate Databricks audit- log scope selections. Log Analytics is the suitable destination because it supports rapid ingestion and immediate querying of log records through Azure Monitor Logs. Auditors can search, filter, correlate, and analyze the captured events without first developing a separate data-processing solution. An Azure Storage account is more suitable for inexpensive archival, while Event Hubs is primarily a streaming transport that normally requires an additional consumer before investigators can analyze the records.
NEW QUESTION # 49
You need to deploy Declarative Automation Bundles to a development environment. The solution must support automated and repeatable deployments across environments.
What should you use?
Answer: A
Explanation:
The Databricks CLI contains the bundle command group for validating, deploying, and running Declarative Automation Bundles. CLI commands can be executed consistently from developer terminals or CI/CD pipelines, making deployments automated, repeatable, and suitable for multiple target environments. The Databricks SDK for Python can manage workspace APIs programmatically, but it is not the standard bundle deployment interface required here. Git folders provide source-control integration inside the workspace but do not deploy bundle-defined resources. The Jobs UI supports interactive creation and management of jobs, which introduces manual steps and does not provide the same infrastructure-as-code workflow. Using commands such as databricks bundle validate and databricks bundle deploy -t dev directly satisfies the automated development deployment requirement. Microsoft Learn
NEW QUESTION # 50
......
Preparing with BootcampPDF Implementing Data Engineering Solutions Using Azure Databricks (DP-750) practice exam would be the most effective way to get success. BootcampPDF would give you access to Implementing Data Engineering Solutions Using Azure Databricks (DP-750) exam questions that are factual and unambiguous, as well as information that is important for the preparation of the DP-750 DP-750 exam.
Braindumps DP-750 Torrent: https://www.bootcamppdf.com/DP-750_exam-dumps.html